 Jack Chen
a87f6c17fd
* docs(readme): retire 3-deps headline; sync zh Consensus

- Drop "Three runtime dependencies" from tagline / badge / intro across 4 READMEs (mechanism + category kept, deps-count headline retired)
- Remove runtime_deps-3 badge; refresh npm description
- Add missing Consensus section + doc links to the zh READMEs

* docs(readme): sharpen vs. Mastra comparison

Recast on goal-driven vs. hand-wired orchestration: drop the "lightweight" framing (OMA edge is goal-driven auto-decomposition, not doing less) and fix the mislabel (Mastra is a full-stack platform, not a "Supervisor pattern"). Sync all 4 READMEs (en/zh root + core).
35 KiB
Open Multi-Agent
From a goal to a task DAG, automatically.
TypeScript-native multi-agent orchestration.


English · 中文
open-multi-agent is a multi-agent orchestration framework for TypeScript backends. Give it a goal; a coordinator agent decomposes it into a task DAG, parallelizes independents, and synthesizes the result. Drops into any Node.js backend.
Your engineers describe the goal, not the graph.
Graph-first frameworks make you enumerate every node and edge up front. open-multi-agent is goal-first: you describe the outcome and the coordinator builds the task DAG at runtime, so the orchestration adapts to the goal instead of being hand-wired for one.
Contents
Quick Start · Three Ways to Run · Features · Orchestration Controls · Ecosystem · Examples · How Is This Different? · Architecture · Supported Providers · Production Checklist · Documentation · Contributing
Quick Start
Requires Node.js >= 18.
The fastest way to see a multi-agent run — scaffold a project and start it in one command:
npm create oma-app@latest
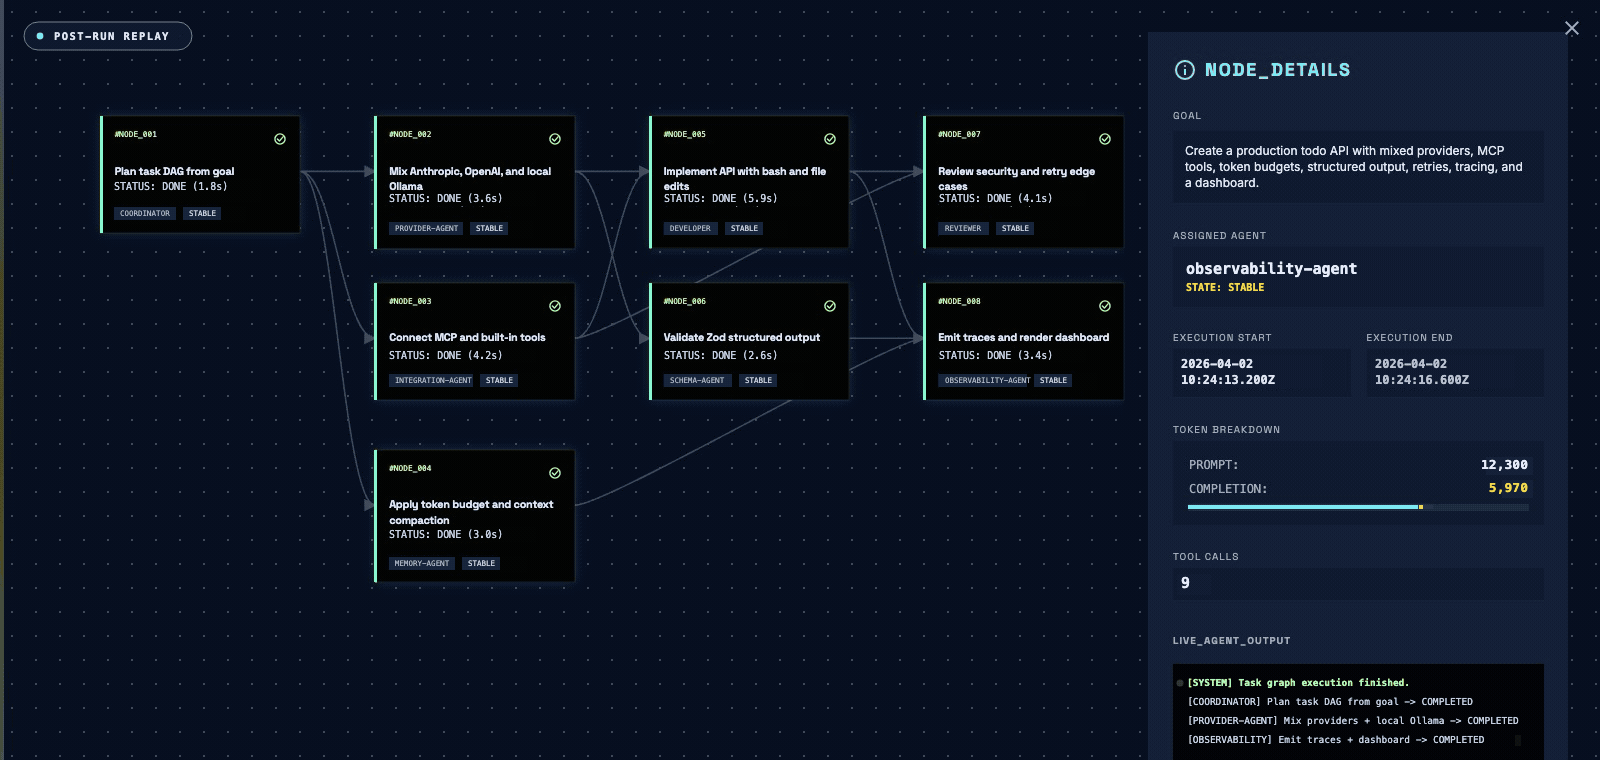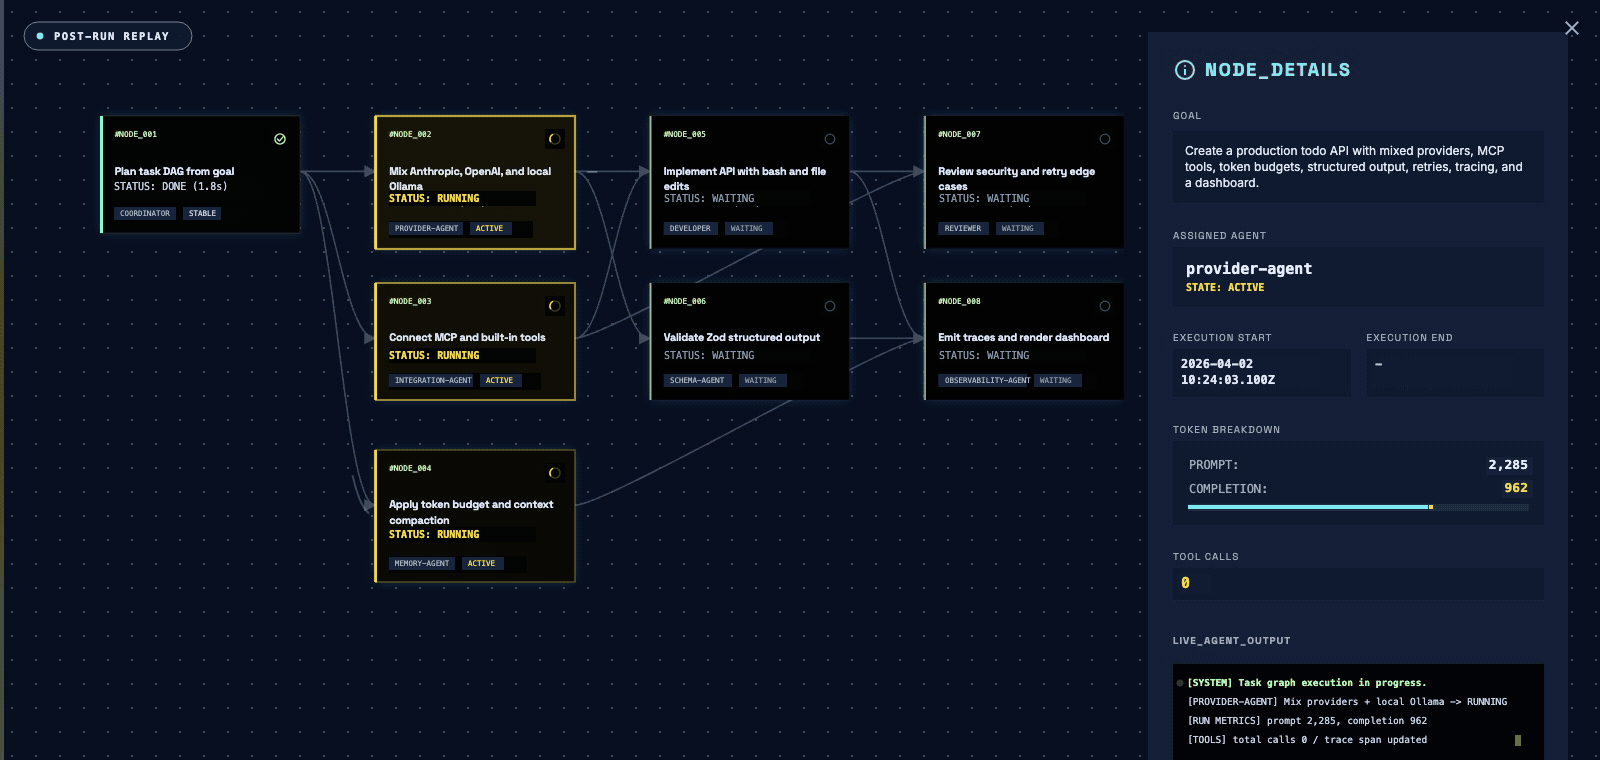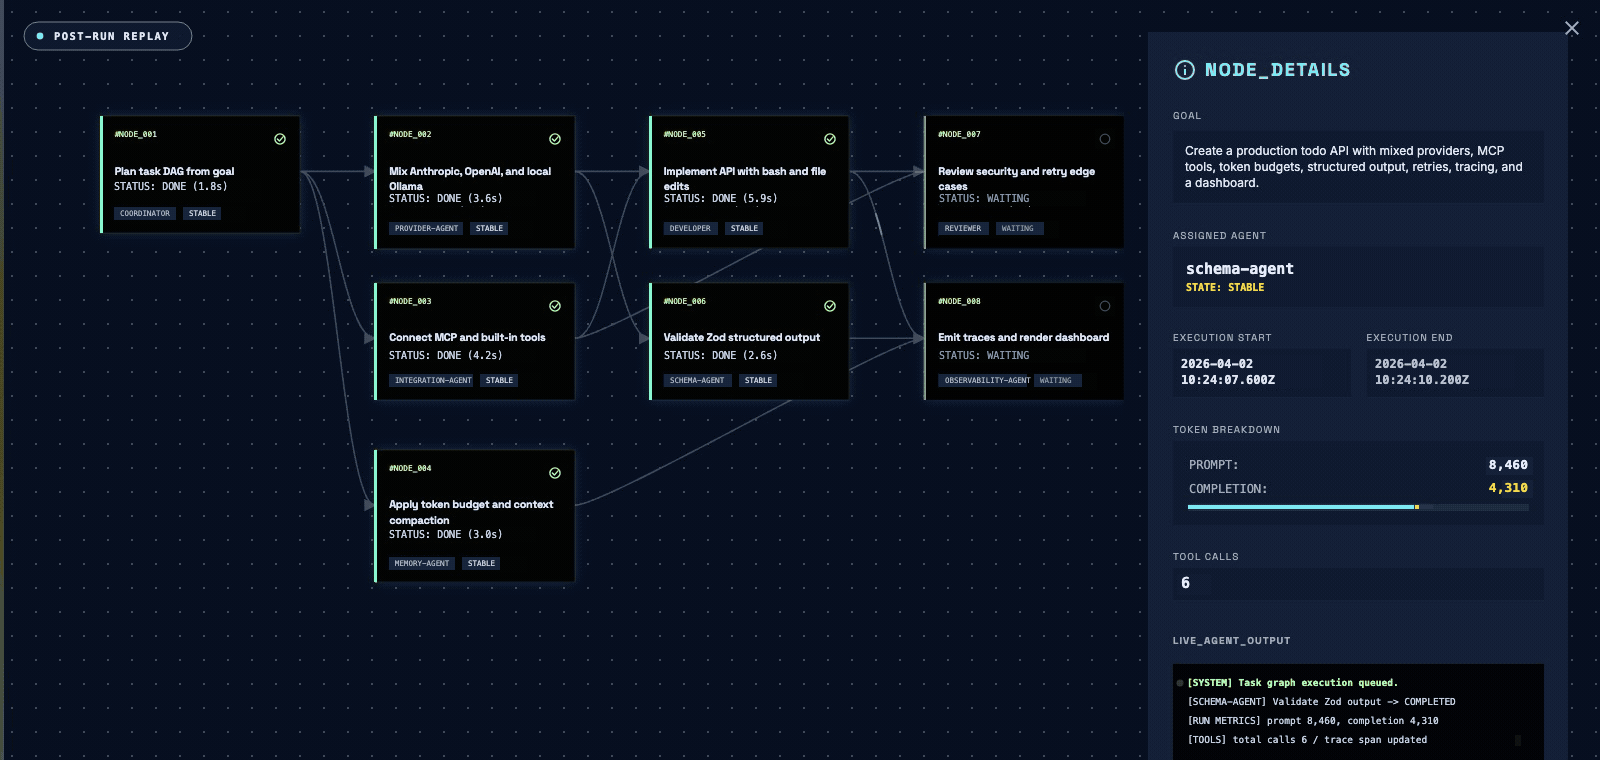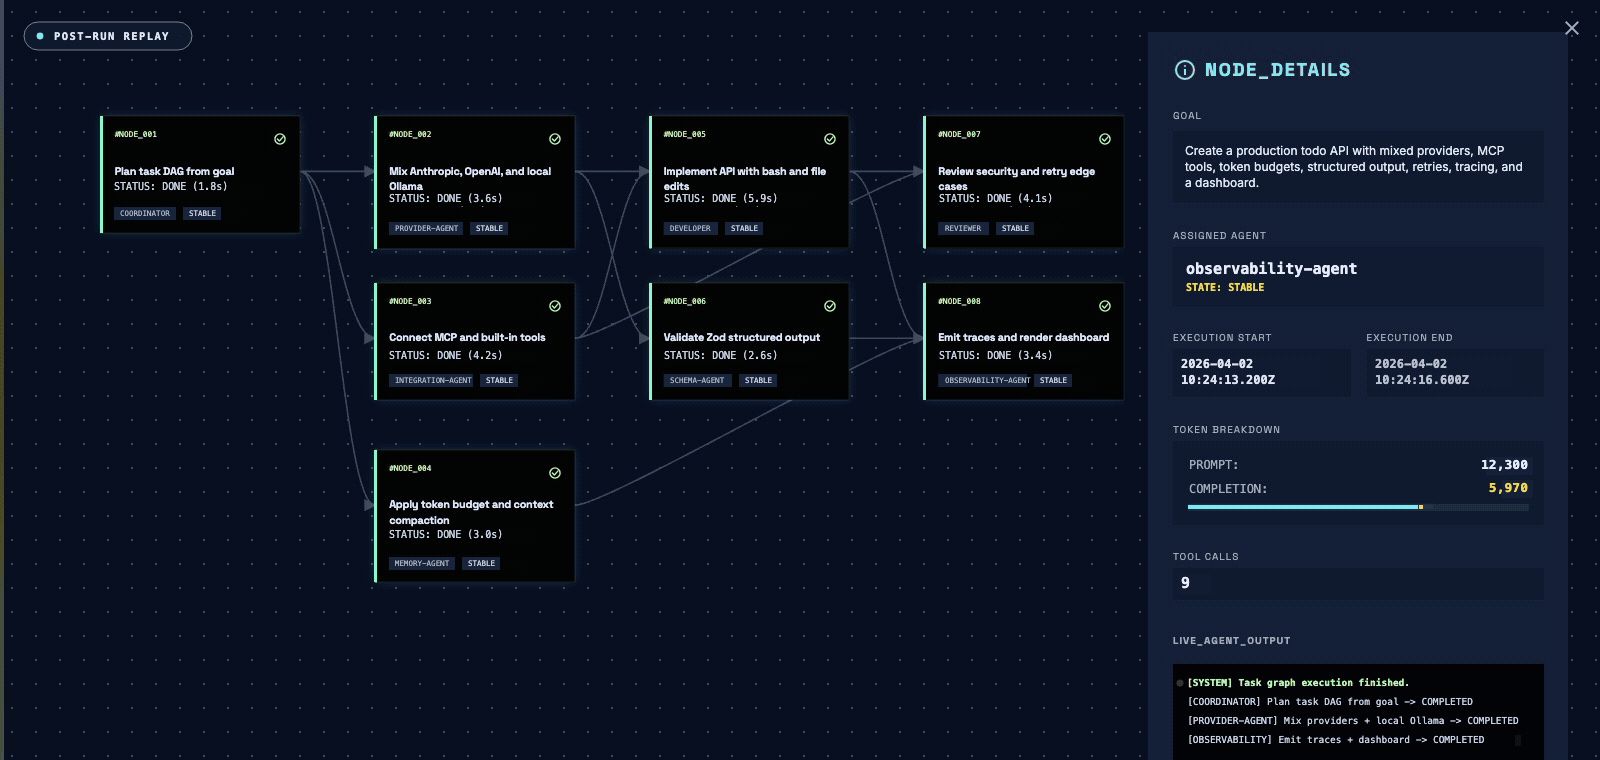
The first run shows the coordinator decompose one goal into a multi-agent DAG, then opens a dashboard of the run. To add the library to an existing project instead:
npm install @open-multi-agent/core
Migrating from @jackchen_me/open-multi-agent? That package is deprecated; install @open-multi-agent/core instead.
import { OpenMultiAgent, type AgentConfig } from '@open-multi-agent/core'

// Works with any OpenAI-compatible provider. Set OPENAI_API_KEY for OpenAI, or
// set OPENAI_BASE_URL + OMA_MODEL for Groq, DeepSeek, Ollama, etc.
const model = process.env.OMA_MODEL ?? 'gpt-5.4'

// Built-in tools are opt-in (default-deny): each agent gets only the tools it
// lists in `tools` (or a `toolPreset`). List neither and the agent gets none.
const agents: AgentConfig[] = [
  { name: 'architect', model, systemPrompt: 'Design clean API contracts.', tools: ['file_write'] },
  { name: 'developer', model, systemPrompt: 'Implement runnable TypeScript.', tools: ['bash', 'file_read', 'file_write', 'file_edit'] },
  { name: 'reviewer', model, systemPrompt: 'Review correctness and security.', tools: ['file_read', 'grep'] },
]

const orchestrator = new OpenMultiAgent({
  defaultProvider: 'openai',
  defaultModel: model,
  defaultBaseURL: process.env.OPENAI_BASE_URL, // unset = OpenAI
  onProgress: (event) => console.log(event.type, event.task ?? event.agent ?? ''),
})

const team = orchestrator.createTeam('api-team', { name: 'api-team', agents, sharedMemory: true })

// Built-in filesystem tools default to a `<cwd>/.agent-workspace` sandbox.
const result = await orchestrator.runTeam(
  team,
  `Create a REST API for a todo list in ${process.cwd()}/.agent-workspace/todo-api/`,
)

console.log(result.success, result.totalTokenUsage.output_tokens)
Run an example locally
git clone https://github.com/open-multi-agent/open-multi-agent && cd open-multi-agent
npm install
export OPENAI_API_KEY=sk-...
npx tsx packages/core/examples/basics/team-collaboration.ts
Three agents collaborate on a REST API while onProgress streams the coordinator's task DAG:
agent_start coordinator
task_start design-api
task_complete design-api
task_start implement-handlers
task_start scaffold-tests         // independent tasks run in parallel
task_complete scaffold-tests
task_complete implement-handlers
task_start review-code            // unblocked after implementation
task_complete review-code
agent_complete coordinator        // synthesizes final result
Success: true
Tokens: 12847 output tokens
Local models via Ollama need no API key, see providers/ollama. For hosted providers (OPENAI_API_KEY, GEMINI_API_KEY, etc.), see Supported Providers.
Three Ways to Run
| Mode | Method | When to use | Example |
|---|---|---|---|
| Single agent | runAgent() |
One agent, one prompt | basics/single-agent |
| Auto-orchestrated team | runTeam() |
Give a goal, let the coordinator plan and execute | basics/team-collaboration |
| Explicit pipeline | runTasks() |
You define the task graph and assignments | basics/task-pipeline |
For answers that need scrutiny, runConsensus() runs a proposer→judge verification loop (with an opt-in per-task verify hook). See Consensus.
Preview the coordinator's task DAG without executing it, or pin that plan and replay the same graph later without another coordinator call:
// Decompose once and review the plan
const preview = await orchestrator.runTeam(team, goal, { planOnly: true })

// Turn it into a diffable, version-controllable artifact (plain JSON)
const plan = orchestrator.createPlanArtifact(preview)

// Later: replay the exact graph (same task ids, deps, assignees), no coordinator
const result = await orchestrator.runFromPlan(team, plan)
Route orchestration phases to different models with an opt-in modelRouting policy: a flagship model plans, a cheap model runs the leaf tasks. Match by phase, agent, task role/priority, or leaf status; first match wins, and omitting it leaves model selection unchanged. See Model routing.
Features
| Capability | What you get |
|---|---|
| Goal-driven coordinator | One runTeam(team, goal) call decomposes the goal into a task DAG, parallelizes independents, and synthesizes the result. Unassigned tasks are auto-scheduled — dependency-first (default), round-robin, least-busy, or capability-match. |
| Mix providers in one team | 13 built-in providers plus any OpenAI-compatible endpoint (Ollama, vLLM, LM Studio, OpenRouter, Groq), mixed freely in one team. Local servers that emit tool calls as plain text are recovered by a fallback parser. (full list · setup) |
| Extended thinking / reasoning | One thinking config maps to Anthropic thinking, Gemini thinkingConfig, and OpenAI reasoning_effort; reasoning is streamed as events, with opt-in preservation across a provider switch. (cross-provider-reasoning) |
| Tools + MCP | 6 built-in (bash, file_*, grep, glob), all opt-in (default-deny — grant via tools / toolPreset), plus delegate_to_agent handoff (cycle + depth guards), custom tools via defineTool() + Zod, stdio MCP servers via connectMCPTools(). (tool config) |
| Streaming + structured output | Token-by-token streaming on every adapter (per-agent during team runs via onAgentStream); Zod-validated final answer with auto-retry on parse failure. (structured-output) |
| Human-in-the-loop | Gate execution with onPlanReady (approve the plan before any agent runs) and onApproval (approve between task rounds), or inspect first with planOnly. |
| Pin and replay plans | Serialize a planOnly decomposition with createPlanArtifact, then runFromPlan replays the exact task graph without re-invoking the coordinator. (patterns/plan-replay) |
| Lifecycle hooks + cancellation | beforeRun rewrites the prompt, afterRun post-processes or rejects the result; pass an AbortSignal to cancel a run in flight. |
| Configurable coordinator | Override the coordinator's model, provider, adapter, system prompt, or tools via runTeam(team, goal, { coordinator }). |
| Observability | onProgress events, onTrace spans, post-run HTML dashboard rendering the executed task DAG. API keys and tokens are redacted from traces, bash output, and the dashboard. (observability guide) |
| Pluggable shared memory | Default in-process KV; swap in Redis / Postgres / your own backend by implementing MemoryStore. (shared memory) |
| Checkpoint & resume | Opt-in per-run checkpointing over any MemoryStore: snapshot on each completed task, then restore() skips finished tasks to continue after a crash or restart. Best-effort saves never take the run down. (checkpoint & resume) |
| Sandboxed filesystem workspace | Built-in filesystem tools are sandboxed to <cwd>/.agent-workspace by default; agents sharing the default configuration share this root. For per-agent isolation, set AgentConfig.cwd; for a different shared root, set OrchestratorConfig.defaultCwd; pass null to disable. (sandbox config) |
Production controls (context strategies, task retry with backoff, loop detection, tool output truncation/compression) are covered in the Production Checklist.
Orchestration Controls
Fine-grained control over a runTeam run. All optional; defaults keep behavior unchanged.
Inject team context. Prepend the goal, roster, and this worker's role to every worker prompt — helps workers stay aligned and makes multi-step runs easier to debug. Off by default; worker prompts stay byte-identical when omitted.
await orchestrator.runTeam(team, goal, { revealCoordinator: true })
Approve before running. Inspect the coordinator's plan before any agent executes, and again between task rounds. These live on the orchestrator. Returning false aborts; remaining tasks are marked skipped.
const orchestrator = new OpenMultiAgent({
  onPlanReady: async (tasks) => tasks.length <= 10,        // gate the whole plan
  onApproval:  async (completed, next) => next.length > 0, // gate each round
})
Cancel a run. Pass an AbortSignal; aborting stops the run in flight.
const controller = new AbortController()
const run = orchestrator.runTeam(team, goal, { abortSignal: controller.signal })
// controller.abort() from elsewhere to cancel
Configure the coordinator. Give the planner its own model, adapter, or extra instructions without touching the worker agents.
await orchestrator.runTeam(team, goal, {
  coordinator: { model: 'claude-opus-4-6', instructions: 'Prefer fewer, larger tasks.' },
})
Fan-out without dependencies. For MapReduce-style parallelism, use AgentPool.runParallel() directly. See patterns/fan-out-aggregate.
Shell & CI. Use the JSON-first oma binary. See docs/cli.md.
Ecosystem
open-multi-agent launched 2026-04-01 under MIT. Known users and integrations to date:
Built with OMA
- temodar-agent (~60 stars). WordPress security analysis platform by Ali Sünbül. Uses our built-in tools (
bash,file_*,grep) directly inside a Docker runtime. Confirmed production use. - PR-Copilot. AI pull-request review assistant by kidoom. Runs an OMA review team (coordinator + scoped reviewer agents), defines repo-context tools with
defineTool, and adds a customContextStrategyfor token-aware PR-diff compression. Public code on@open-multi-agent/core.
Using open-multi-agent in production or a side project? Open a discussion and we will list it here.
Integrations
- Engram — "Git for AI memory." Syncs knowledge across agents instantly and flags conflicts. (repo)
- @agentsonar/oma — Sidecar detecting cross-run delegation cycles, repetition, and rate bursts.
Built an integration? See the integration guide for how to submit a reference or vendor example and get your product listed.
Provider community offers
Limited-time provider offers for open-multi-agent users. Listings are not paid endorsements.
- MiniMax — Use MiniMax M3 in OMA's TypeScript multi-agent workflows. OMA users get 12% off the MiniMax Token Plan until 2026-06-30. See the MiniMax setup guide.
Featured partner
For products and platforms with a deep open-multi-agent integration. See the Featured partner program for terms and how to apply.
Examples
examples/ is organized by category: basics, cookbook, patterns, providers, and integrations. See examples/README.md for the full index. (production/ is open for contributions — see the acceptance criteria.)
Real-world workflows (cookbook/)
End-to-end scenarios you can run today. Each one is a complete, opinionated workflow.
contract-review-dag: four-task DAG for contract review with parallel branches and step-level retry on failure.meeting-summarizer: three specialised agents fan out on a transcript, an aggregator merges them into one Markdown report with action items and sentiment.competitive-monitoring: three parallel source agents extract claims from feeds; an aggregator cross-checks them and flags contradictions.translation-backtranslation: translate EN to target with one provider, back-translate with another, flag semantic drift.incident-postmortem-dag: three independent root tasks fan out at t=0, then a root-cause hypothesizer and postmortem writer synthesize them into one document.personalized-interview-simulator: a stateful interviewer (Agent.prompt()across turns) plus a transcript-reading observer, withreadlinehuman input and a Zod-validated debrief.
Patterns and integrations
basics/team-collaboration:runTeam()coordinator pattern.patterns/structured-output: any agent returns Zod-validated JSON.patterns/multi-perspective-code-review: a generator feeds security, performance, and style reviewers running in parallel, then a synthesizer returns Zod-validated findings.patterns/cross-provider-reasoning: preserve a reasoning model's thought stream across a provider switch viapreserveReasoningAsText.patterns/cost-tiered-pipeline: assign a different model per stage and estimate per-model USD cost fromonTracetoken counts.patterns/fan-out-aggregate: MapReduce-style fan-out viaAgentPool.runParallel().patterns/agent-handoff: synchronous sub-agent delegation viadelegate_to_agent.patterns/plan-replay: decompose a goal once withplanOnly, serialize it withcreatePlanArtifact, then replay the same DAG viarunFromPlanwithout re-running the coordinator.integrations/trace-observability:onTracespans for LLM calls, tools, and tasks.integrations/mcp-github: expose an MCP server's tools to an agent viaconnectMCPTools().- Provider examples: scripts under
examples/providers/covering hosted providers, OpenAI-compatible endpoints, and local models.
Full applications
Clone-and-run apps with their own package.json, not npx tsx scripts. Each embeds OMA in a real backend.
integrations/express-customer-support: Express REST API.runTasks()behindPOST /ticketswith per-agent Zod schemas, swappable provider env vars, and HTTP error mapping. Runs on one DeepSeek key (npm install && npm start).integrations/with-vercel-ai-sdk: Next.js app. OMArunTeam()plus AI SDKuseChatstreaming (npm install && npm run dev).
Run any script with npx tsx packages/core/examples/<path>.ts; the full applications above use their own npm scripts.
How is this different from X?
A quick router. Mechanism breakdown follows.
| If you need | Pick |
|---|---|
| Fixed production topology with mature checkpointing | LangGraph JS |
| Full-stack platform, workflows wired by hand | Mastra |
| Python stack with mature multi-agent ecosystem | CrewAI |
| AI app toolkit with broad model-provider support | Vercel AI SDK |
| TypeScript, goal to result with auto task decomposition | open-multi-agent |
vs. LangGraph JS. LangGraph compiles a declarative graph (nodes, edges, conditional routing) into an invokable. open-multi-agent runs a Coordinator that decomposes the goal into a task DAG at runtime, then auto-parallelizes independents. Same end (orchestrated execution), opposite directions: LangGraph is graph-first, OMA is goal-first.
vs. Mastra. Both are TypeScript-native; the difference is who drives the orchestration. With Mastra you wire the workflow by hand. OMA is goal-driven: give its Coordinator a goal and it builds the task DAG at runtime, adapting the plan to the goal instead of running a graph you wired step by step. runTeam(team, goal) in one call.
vs. CrewAI. CrewAI is the mature multi-agent option in Python. OMA targets TypeScript backends with three runtime dependencies and direct Node.js embedding. Roughly comparable orchestration surface; the choice is the language stack.
vs. Vercel AI SDK. AI SDK provides the LLM-call layer — provider abstraction, streaming, tool calls, and structured outputs. It does not orchestrate goal-driven multi-agent teams. The two are complementary: AI SDK for app surfaces and single-agent calls, OMA when you need a team.
Architecture
┌─────────────────────────────────────────────────────────────────┐
│  OpenMultiAgent (Orchestrator)                                  │
│                                                                 │
│  createTeam()  runTeam()  runTasks()  runAgent()  getStatus()   │
└──────────────────────┬──────────────────────────────────────────┘
                       │
            ┌──────────▼──────────┐
            │  Team               │
            │  - AgentConfig[]    │
            │  - MessageBus       │
            │  - TaskQueue        │
            │  - SharedMemory     │
            └──────────┬──────────┘
                       │
         ┌─────────────┴─────────────┐
         │                           │
┌────────▼──────────┐    ┌───────────▼───────────┐
│  AgentPool        │    │  TaskQueue             │
│  - Semaphore      │    │  - dependency graph    │
│  - runParallel()  │    │  - auto unblock        │
└────────┬──────────┘    │  - cascade failure     │
         │               └───────────────────────┘
┌────────▼──────────┐
│  Agent            │
│  - run()          │    ┌────────────────────────┐
│  - prompt()       │───►│  LLMAdapter            │
│  - stream()       │    │  - 13 built-in         │
└────────┬──────────┘    │    providers           │
         │               │  - OpenAI-compatible   │
         │               │  - AI SDK bridge       │
         │               └────────────────────────┘
┌────────▼──────────┐
│  AgentRunner      │    ┌──────────────────────┐
│  - conversation   │───►│  ToolRegistry        │
│    loop           │    │  - defineTool()      │
│  - tool dispatch  │    │  - 6 built-in tools  │
└───────────────────┘    │  + delegate (opt-in) │
                         └──────────────────────┘
Supported Providers
Change provider, model, and set the env var. The agent config shape stays the same.
const agent: AgentConfig = {
  name: 'my-agent',
  provider: 'anthropic',
  model: 'claude-sonnet-4-6',
  systemPrompt: 'You are a helpful assistant.',
}
| Kind | How to configure | Services |
|---|---|---|
| Built-in shortcuts | Set provider to anthropic, gemini, openai, azure-openai, copilot, grok, deepseek, doubao, hunyuan, minimax, mimo, qiniu, or bedrock; the framework supplies the endpoint. |
Anthropic, Gemini, OpenAI, Azure OpenAI, GitHub Copilot, xAI Grok, DeepSeek, Doubao (Volcengine), Hunyuan (Tencent MaaS), MiniMax, MiMo, Qiniu, AWS Bedrock |
| OpenAI-compatible endpoints | Set provider: 'openai' plus baseURL and, when needed, apiKey. |
Ollama, vLLM, LM Studio, llama.cpp server, OpenRouter, Groq, Mistral, Moonshot (Kimi), Qwen, Zhipu |
| Vercel AI SDK | Import AISdkAdapter from @open-multi-agent/core/ai-sdk; install optional peer ai plus an @ai-sdk/* provider. |
Any AI SDK provider (60+ models and hosts) |
See docs/providers.md for env vars, model examples, local tool-calling, timeouts, and troubleshooting.
Vercel AI SDK (optional)
Install the optional peer ai plus any @ai-sdk provider you need (for example @ai-sdk/openai). Pass adapter: new AISdkAdapter(model) on AgentConfig to route that agent through the AI SDK instead of the built-in provider factory. provider, apiKey, baseURL, and region are ignored when adapter is set. Mixed teams work as usual: only agents with adapter use the AI SDK.
import { openai } from '@ai-sdk/openai'
import { AISdkAdapter } from '@open-multi-agent/core/ai-sdk'
import { OpenMultiAgent } from '@open-multi-agent/core'

const oma = new OpenMultiAgent()
await oma.runAgent(
  {
    name: 'researcher',
    model: 'gpt-4o',
    adapter: new AISdkAdapter(openai('gpt-4o')),
    systemPrompt: 'You are a researcher.',
  },
  'What are the latest AI trends?',
)
The coordinator accepts the same hook via runTeam(team, goal, { coordinator: { adapter: new AISdkAdapter(...) } }).
Production Checklist
Before going live, wire up the controls that protect token spend, recover from failure, and let you debug.
| Concern | Knob | Where it lives |
|---|---|---|
| Bound the conversation | maxTurns per agent + contextStrategy (sliding-window / summarize / compact / custom) |
AgentConfig |
| Bound wall-clock time | timeoutMs per agent (aborts a run that hangs, common with local models) |
AgentConfig |
| Cap tool output | maxToolOutputChars (or per-tool maxOutputChars) + compressToolResults: true |
AgentConfig and defineTool() |
| Recover from failure | Per-task maxRetries, retryDelayMs, retryBackoff (exponential multiplier) |
Task config used via runTasks() |
| Survive a crash or restart | checkpoint (pass a runId or a durable MemoryStore) + restore() to resume, skipping completed tasks |
OrchestratorConfig / run options |
| Hard-cap spend | maxTokenBudget on the orchestrator |
OrchestratorConfig |
| Catch stuck agents | loopDetection with onLoopDetected: 'terminate' (or a custom handler) |
AgentConfig |
| Trace and audit | onTrace to your tracing backend; persist renderTeamRunDashboard(result) |
OrchestratorConfig |
| Redact secrets | Automatic — API keys, tokens, and Authorization headers stripped from traces, bash output, and dashboard payloads | built-in (on by default) |
| Grant tools deliberately | Built-in tools are opt-in (default-deny): an agent gets only what it lists in tools / toolPreset; list neither and it gets none. bash stays unsandboxed once granted, and every tool result is sent to your model provider — so grant read/exec access on purpose. defaultToolPreset restores the old "all tools" behavior in one line |
AgentConfig / OrchestratorConfig |
| Bound filesystem reach | cwd / defaultCwd (default .agent-workspace subdir; widen with process.cwd(), disable with null) |
AgentConfig / OrchestratorConfig |
Documentation
- Providers — env vars, model examples, local tool-calling, timeouts, troubleshooting.
- Tool configuration — tool presets, custom tools, the filesystem sandbox, and MCP.
- Observability —
onProgressevents,onTracespans, and the post-run dashboard. - Shared memory — the default store and custom
MemoryStorebackends. - Checkpoint & resume — opt-in per-run snapshot/resume over any
MemoryStore; survive crashes and restarts. - Context management — sliding window, summarization, compaction, and custom compressors.
- CLI — the JSON-first
omabinary for shell and CI. - Consensus — the
runConsensusproposer→judge primitive, the per-taskverifyhook, and the budget invariant. - Model routing — the opt-in
modelRoutingpolicy: match by phase / agent / role / priority / leaf, first match wins.
Contributing
Issues, feature requests, and PRs are welcome. Some areas where contributions would be especially valuable:
- Production examples. Real-world end-to-end workflows. See
examples/production/README.mdfor the acceptance criteria and submission format. - Documentation. Guides, tutorials, and API docs.
- Translations. Help translate this README into other languages. Open a PR.
Contributors
Contributor credits by area
Framework features
- @ibrahimkzmv (token budget, context strategy, dependency-scoped context, tool presets, glob, MCP integration, configurable coordinator, CLI, dashboard rendering, trace event types)
- @apollo-mg (context compaction fix, sampling parameters)
- @tizerluo (onPlanReady, onAgentStream)
- @CodingBangboo (planOnly mode)
- @Xin-Mai (output schema validation)
- @JasonOA888 (AbortSignal support)
- @EchoOfZion (coordinator skip for simple goals)
- voidborne-d (OpenAI mixed-content fix, text-tool-extractor depth fix)
- @NamelessNATM (agent delegation base implementation)
- @MyPrototypeWhat (reasoning blocks, reasoning_effort, sampling parity, trace input/output)
- @SiMinus (streaming reasoning events)
- @matthewYang08 (OpenAI reasoning-to-text fallback)
- @dvirarad (OpenAI-family adapter hardening)
- @cat0825 (model routing policy, plan replay, structured shared-memory handoff)
- @mvanhorn (checkpoint & resume)
Provider integrations
- @ibrahimkzmv (Gemini)
- @hkalex (DeepSeek, MiniMax)
- @marceloceccon (Grok)
- @Klarline (Azure OpenAI)
- @Deathwing (GitHub Copilot)
- @JackChiang233 (Qiniu)
- @CodingBangboo (AWS Bedrock)
- @kidoom (MiMo, Doubao)
- @KaitlynFeng (Hunyuan)
- @octo-patch (MiniMax-M3 model upgrade)
Examples & cookbook
- @mvanhorn (research aggregation, code review, meeting summarizer, Groq example, Mistral example)
- @Kinoo0 (code review upgrade)
- @Optimisttt (research aggregation upgrade)
- @Agentscreator (Engram memory integration)
- @fault-segment (contract-review DAG)
- @HuXiangyu123 (cost-tiered example)
- @zouhh22333-beep (translation/backtranslation)
- @pei-pei45 (competitive monitoring)
- @mmjwxbc (interview simulator)
- @binghuaren96 (incident postmortem DAG)
- @DaiMao-UT (paper replication triage)
- @oooooowoooooo (rare disease information triage)
- @CodingBangboo (Express customer support pipeline)
- @nuthalapativarun (Doubao and Zhipu provider examples)
- @goodneamtakenbydogs (Moonshot and Qwen provider examples)
- @suans4746-del (narrative puzzle hint arbitration)
- @gregkonush (Bilig WorkPaper MCP integration)
Docs & tests
- @tmchow (llama.cpp docs)
- @kenrogers (OpenRouter docs)
- @jadegold55 (LLM adapter test coverage)
- @btroops (DeepSeek tool-calling tests)
- @nuthalapativarun (context-management docs)
- @Oxygen56 (errors.ts tests, provider docs for Grok/DeepSeek/Doubao)
- @RheagalFire (LiteLLM gateway docs)
License
MIT