Agents your organization can own, approve, and audit.
OMA (Open Multi-Agent) is a self-hosted TypeScript agent runtime for coordinating agents, adding human approval gates, and inspecting runs offline.
@open-multi-agent/core is the OMA orchestration runtime for TypeScript backends. Give it one agent, an explicit task graph, or a dynamic workflow that the coordinator generates from a goal at runtime.
The runtime schedules dependencies, runs independent work in parallel, shares context across agents, and returns an inspectable result. For product positioning and known users, see the project overview.
Requires Node.js 20 or newer. For production, use a currently maintained
Node.js LTS release. Node.js 20 is upstream-EOL and retained only as a
migration compatibility window; OMA will remove it in the next major release,
no earlier than 2026-10-31. Scaffold and run a starter in one command:
npm create oma-app@latest my-oma
In an interactive terminal, the scaffolder selects a starter and Cloud/Ollama runtime, installs dependencies, then runs a deterministic demo and produces an offline dashboard. The demo uses scripted model responses, needs no API key, and makes no model request; OMA orchestration still runs locally for real. Pass --no-install to generate files only, or --no-run to install without starting the demo.
To add OMA to an existing backend:
npm install @open-multi-agent/core
import{OpenMultiAgent,typeAgentConfig}from'@open-multi-agent/core'constmodel=process.env.OMA_MODEL??'gpt-5.4'constagents: AgentConfig[]=[{name:'researcher',model,systemPrompt:'Find the relevant facts.'},{name:'analyst',model,systemPrompt:'Compare evidence and identify tradeoffs.'},]constorchestrator=newOpenMultiAgent({defaultProvider:'openai',defaultModel: model,})constteam=orchestrator.createTeam('research-team',{name:'research-team',agents,sharedMemory: true,})constresult=awaitorchestrator.runTeam(team,'Compare three approaches and recommend one.')console.log(result.agentResults.get('coordinator')?.output)
Set OPENAI_API_KEY for this example. For other hosted or local models, see Providers.
Use planOnly to inspect a generated task graph before execution, then createPlanArtifact() and runFromPlan() to replay it. runConsensus() adds a proposer→judge verification loop when one answer needs extra scrutiny.
Structured single-agent input
Agent.run(), Agent.stream(), and OpenMultiAgent.runAgent() keep the string form above and also accept a complete LLMMessage[], for caller-owned conversation history or blocks such as base64 images. Structured input is validated and defensively copied, and process and ACP backends stay string-only: they reject structured arguments rather than discarding history or images. See structured agent input for copy, hook, and external-backend semantics, or run basics/structured-input.
Execution routing
runTeam() uses the deterministic router by default and makes no extra model call. executionRouting: { strategy: 'hybrid' } keeps deterministic Team decisions and sends only Single candidates to a one-call, no-tool TaskProfiler; results then expose routingDecision and semanticRoutingAssessment. The Profiler falls back to the Coordinator adapter and then the orchestrator's default provider, so it can make a provider call even when every worker has its own adapter. See execution routing for that provider boundary and the full policy precedence; model routing selects models inside the chosen topology.
Declared governance roles
Use governanceIntent: 'required', requiredRoles, and requiredOrder to declare the roles and execution order a run must follow. Applications must check governanceConclusion separately from success. Configuration and example
Scheduling
Set schedulingStrategy on OpenMultiAgent to choose how unassigned tasks are
mapped to agents. The setting applies to coordinator-generated runTeam()
plans and explicit or restored task queues. Tasks with an explicit assignee
keep that assignment.
Task DAG execution is event-driven: a downstream task starts as soon as its
dependencies are satisfied, without waiting for unrelated tasks from the same
ready set, and dependency outputs reach dependents as task-scoped results and
validated structured handoffs.
Assigns tasks that unblock the most downstream work first, rotating eligible agents
The task graph has meaningful dependencies
round-robin
Distributes tasks in queue order across eligible agents
Agents are interchangeable
least-busy
Chooses the eligible agent with the fewest active or newly assigned tasks
Task duration varies and load balance matters
capability-match
Filters explicit task requirements, then prefers declared capability tags before legacy keyword affinity
Tasks or agents declare differentiated requirements/capabilities
composite
Ranks tasks by blocked dependents, then maximizes fit and available capacity across eligible agents
Criticality, capability fit, and current load should influence one decision
Agents may declare description, capabilities, costTier, and latencyClass, and tasks may add hard requires constraints; every strategy fails before worker execution when they cannot be satisfied. Weight semantics, load normalization, strictAssignees, and the NO_ELIGIBLE_AGENT and INVALID_ASSIGNEE failure modes are covered in task scheduling and dispatch.
Capabilities
Capability
What you get
Dynamic orchestration
Runtime goal decomposition, dependency-aware scheduling, parallel branches, configurable assignment, task-scoped results and handoffs, opt-in team context for workers (revealCoordinator), and final synthesis.
Models and reasoning
Mix built-in, OpenAI-compatible, AI SDK, or local models; map one thinking config to each provider's reasoning setting, route phases separately, and preserve reasoning only when explicitly enabled.
Tools and handoffs
Built-in tools are default-deny; custom tools, MCP, and guarded delegate_to_agent handoffs are opt-in, and consequential tools on undeclared runs are flagged for confirmation.
Controlled outputs
Send text or structured single-agent input, stream per agent, validate results with Zod, approve or durably suspend plans, task rounds, dispatches, and tool calls, rewrite messages/prompts or post-process results with beforeRun / afterRun, and cancel with AbortSignal.
Evaluation
Version EvalSets, run reference scorers, gate CI with offline reports, persist results, or sample production runs on a best-effort path.
Memory and recovery
Shared memory is pluggable; checkpoints resume interrupted runs without repeating completed tasks.
Observability
Stable run identity, traces, execution receipts, redaction, TraceStore, and the offline DAG/Waterfall Viewer are available without a hosted service.
External agents
ACP and process backends let coding CLIs participate while OMA keeps scheduling, memory, and budgets; the per-call tool gate, filesystem sandbox, and LLM egress policy do not cover them.
The coordinator plans once by default; the scheduler owns execution order. Applications can opt into append-only adaptive recovery when task outcomes need to revise the unstarted part of the graph. Agents share results through memory, while checkpoints and traces form separate recovery and observability paths. Evaluation observes completed results and never changes them. Detailed contracts live in the linked subsystem guides below.
Examples
Start with one example that matches the behavior you need:
Gemini (@google/genai) and Bedrock (@aws-sdk/client-bedrock-runtime)
OpenAI-compatible
Set provider: 'openai' + baseURL for Ollama, vLLM, LM Studio, OpenRouter, Groq, Mistral, Kimi, Qwen, or Zhipu
AI SDK
Use AISdkAdapter with ai and your selected @ai-sdk/* provider (AI SDK 7 needs Node.js 22+)
Optional integrations load only when used: core directly installs only @anthropic-ai/sdk, openai, and zod; other SDKs are lazy-loading opt-in peers, and OpenTelemetry lives entirely in @open-multi-agent/otel. Dependency changes are weighed on demonstrated value plus security, size, maintenance, and compatibility cost, not a fixed count.
Image generation and editing use a separate interface: runImage() tries an ordered chain of image models with per-model retries, fallback, output validation, and a record for every provider call, and ships native adapters for the OpenAI Images API, OpenRouter, Seedream on Volcengine Ark, and Black Forest Labs. See image generation.
Paid sponsors supporting open-multi-agent. Sponsorship does not affect technical decisions or model recommendations.
Atlas Cloud: Full-modal AI inference platform giving one API for video, image, and LLM across 300+ curated models. $5 credit vouchers for OMA users, first come first served. See the Atlas Cloud setup guide.
Task retries, checkpointing, restore(), and opt-in adaptive plan repair
Own a run across workers
Opt-in runStore: one execution lease per run, fenced checkpoint writes, durable lifecycle
Review work
planOnly, inline approval callbacks, or durable approval gates; your application owns the approval surface and transport
Observe
Trace sinks, TraceStore, execution receipts, Run Viewer, or the optional OTel adapter
Budget checks run at turn and task boundaries, so a run can overshoot by up to one model turn; they are not a cent-exact stop. estimateCost receives each call's token usage plus the agent, effective model, provider, phase, and taskId, and your application owns the price table. Budgets and limits covers every ceiling, where it is checked, and what happens when one trips.
Built-in tools are default-deny, and every model-visible tool result is sent to
your model provider, so grant read and exec access deliberately. Tools may keep
application-owned data separate while returning text, image, or file content
through modelOutput; see the tool configuration guide.
Filesystem tools stay within the configured cwd; granted bash is not
sandboxed. Its execution target can be replaced through a
ShellExecutor,
while the default LocalShellExecutor preserves host execution and is not a
security boundary. Secrets are redacted from traces, shell output, and Viewer
payloads by default, but result messages and checkpoints have their own
persistence boundary.
Observability
Core already provides run identity, trace sinks, execution receipts, queryable in-memory/file stores, and an offline Run Viewer. These cover local debugging, audit artifacts, and post-run analysis without OpenTelemetry.
@open-multi-agent/otel is an optional integration for teams that already operate a centralized OpenTelemetry stack. It converts OMA traces into standard OTel spans so multi-agent runs can join company-wide monitoring, alerting, and incident workflows. The application owns the provider and its lifecycle; telemetry failures never change the run result.
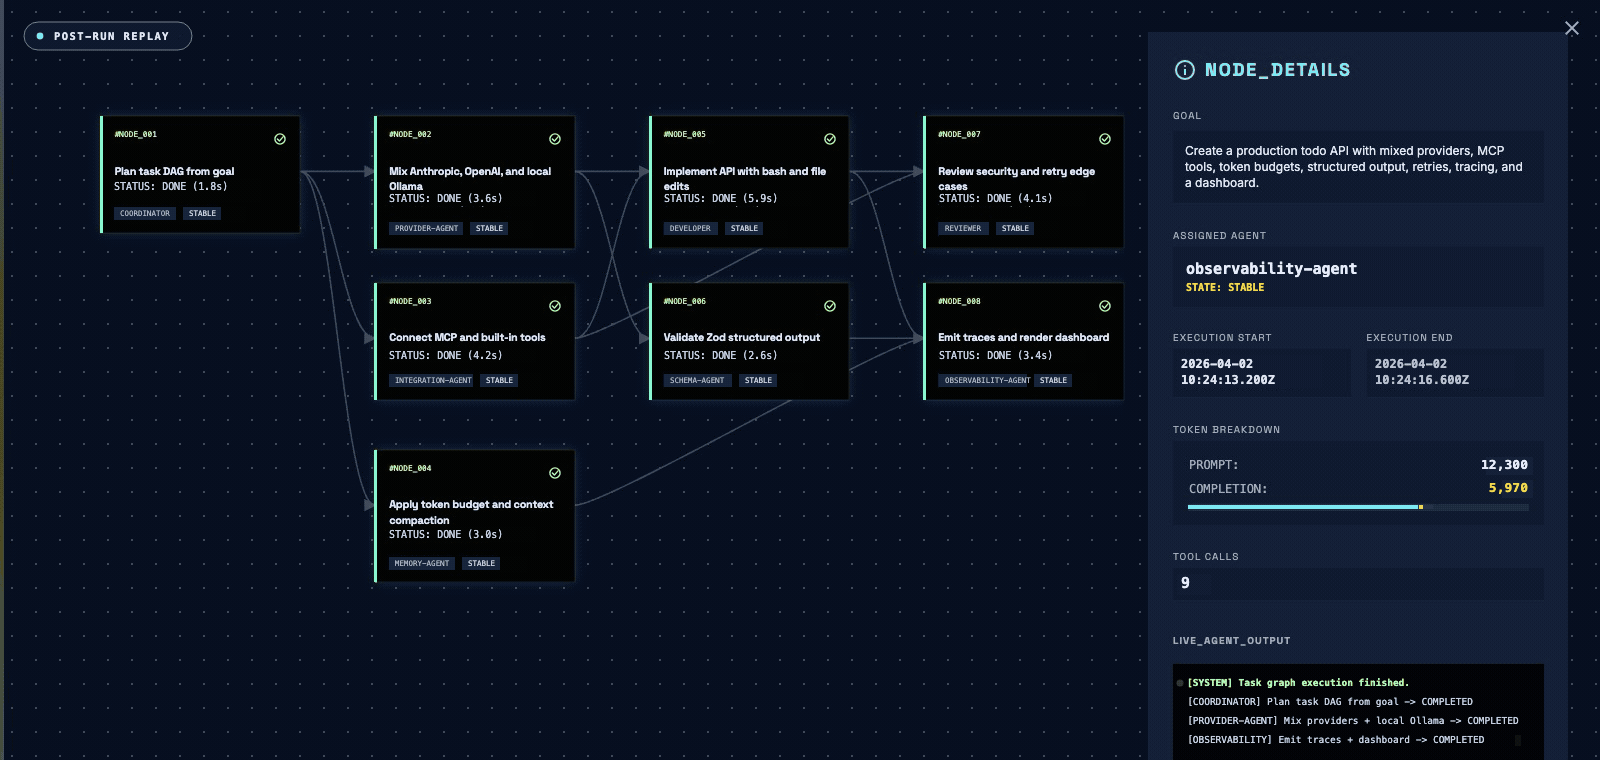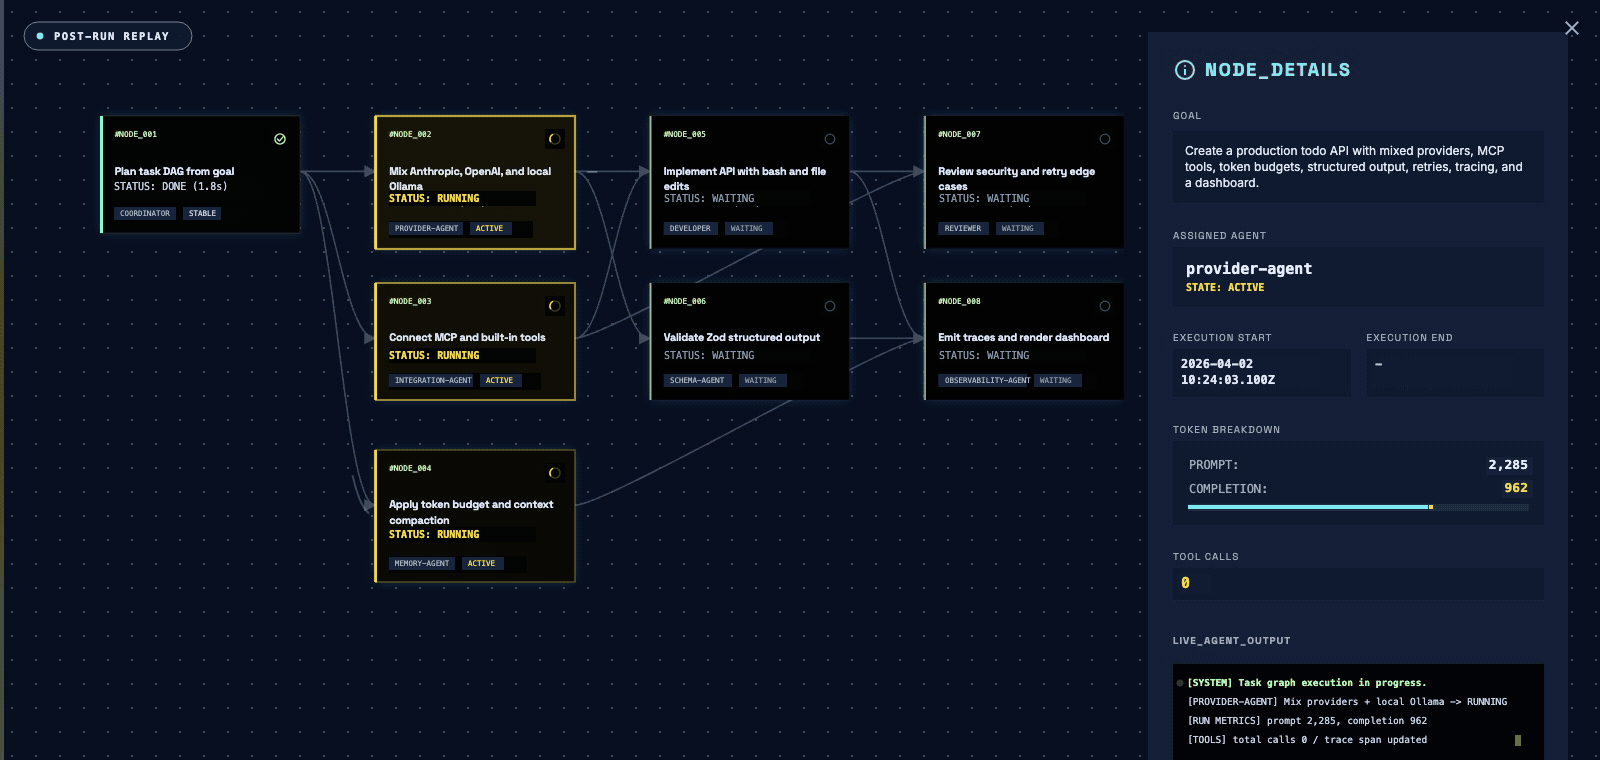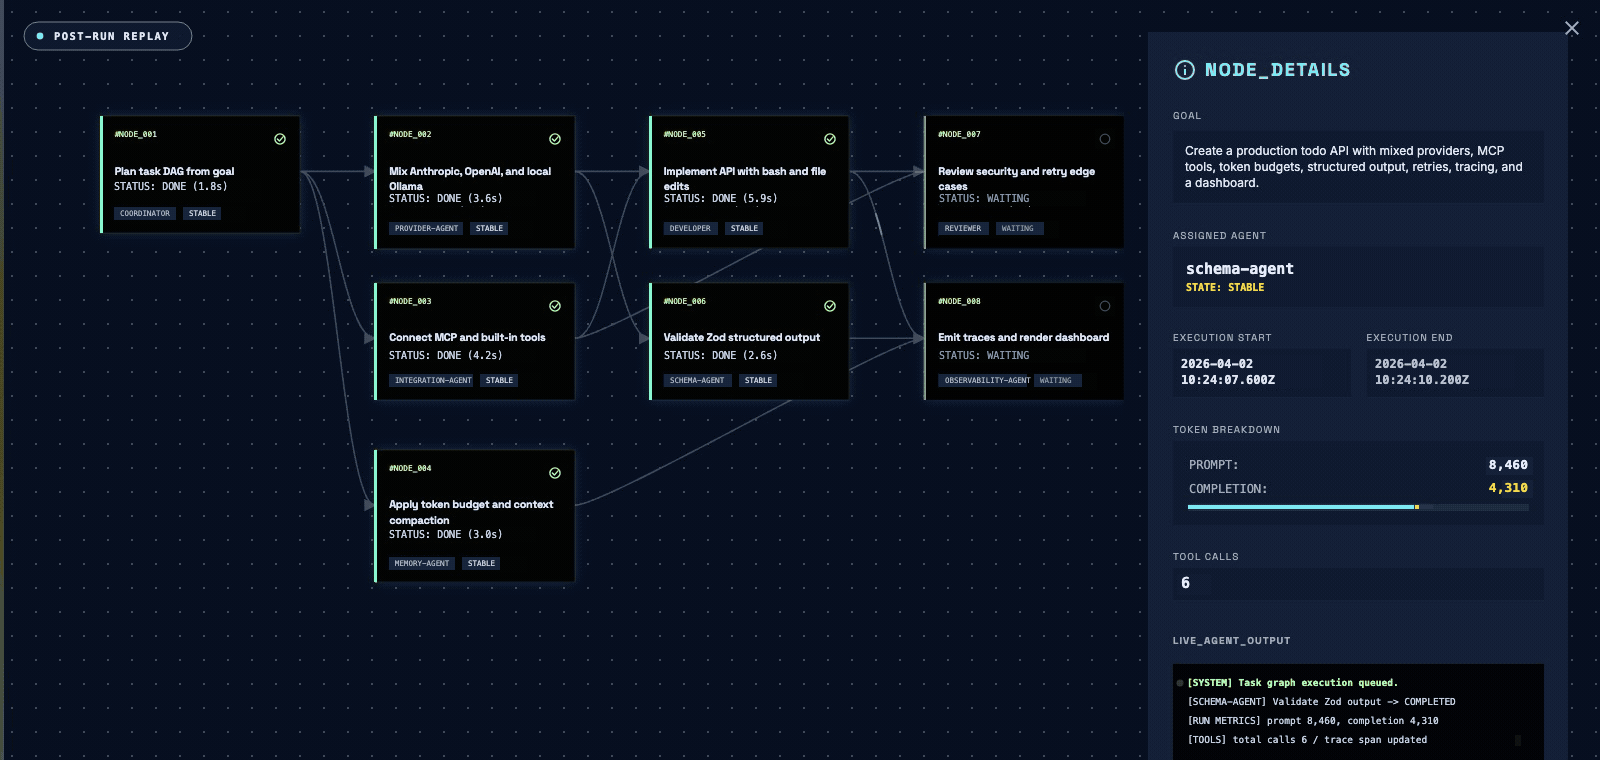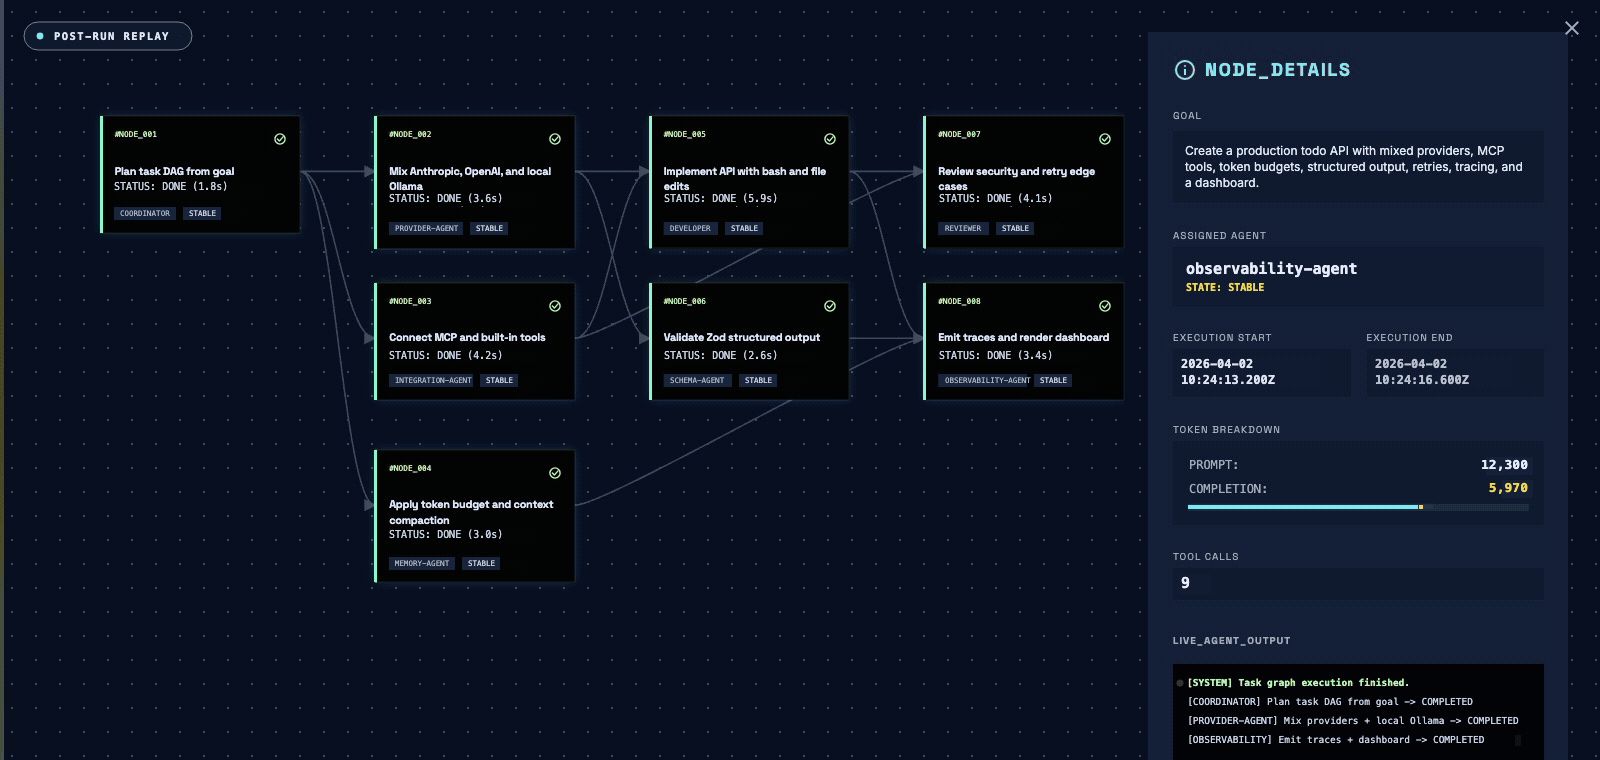
The offline Run Viewer replaying a real run from the trace store: task DAG, span waterfall, and per-task evidence, with no hosted service involved.
Run store and execution leases
Enable runStore when multiple workers may resume the same run. Execution leases and fenced checkpoint writes coordinate ownership, and applications can cancel or resume runs from outside a worker. This feature is off by default. Guide
Run journal
Enable the run journal to retain model inputs, tool results, and context rewrites for debugging long runs. verifyRun() checks source and content consistency offline, and restore can replay compatible events after the checkpoint. The feature is off by default; verification does not prove the journal was never edited. Guide