
Open Multi-Agent
From a goal to a task DAG, automatically.
TypeScript-native multi-agent orchestration.


Website · Docs · npm · Discussions
English · 中文
open-multi-agent is an AI agent orchestration framework for TypeScript backends that drops into any Node.js app.
Your engineers describe the goal, not the graph.
Graph-first frameworks make you wire every node and edge up front. OMA runs a dynamic workflow: a coordinator turns the goal into a task DAG at runtime, parallelizes independent tasks, and synthesizes the result. That plan is emitted as data for a deterministic scheduler to run, so it stays inspectable and replayable. It is the same bet Anthropic made with Claude Code's dynamic workflows; OMA offers it as an open library that runs on any provider, in your own backend.
Lightweight core: the engine plus Anthropic, OpenAI, and any OpenAI-compatible endpoint work out of the box; Gemini, Bedrock, MCP, and the Vercel AI SDK bridge are opt-in peer dependencies. OpenTelemetry is a separately installable integration (@open-multi-agent/otel): OTel APIs, SDKs, semantic-convention mappings, and exporter integrations stay outside the core import, and applications explicitly supply their own provider.
Contents
Quick Start · Three Ways to Run · Features · Orchestration Controls · Ecosystem · Examples · How Is This Different? · Architecture · Supported Providers · Production Checklist · Documentation · Contributing
Quick Start
Requires Node.js >= 18 (the optional Vercel AI SDK 7 bridge needs Node.js >= 22).
The fastest way to see a multi-agent run — scaffold a project and start it in one command:
npm create oma-app@latest
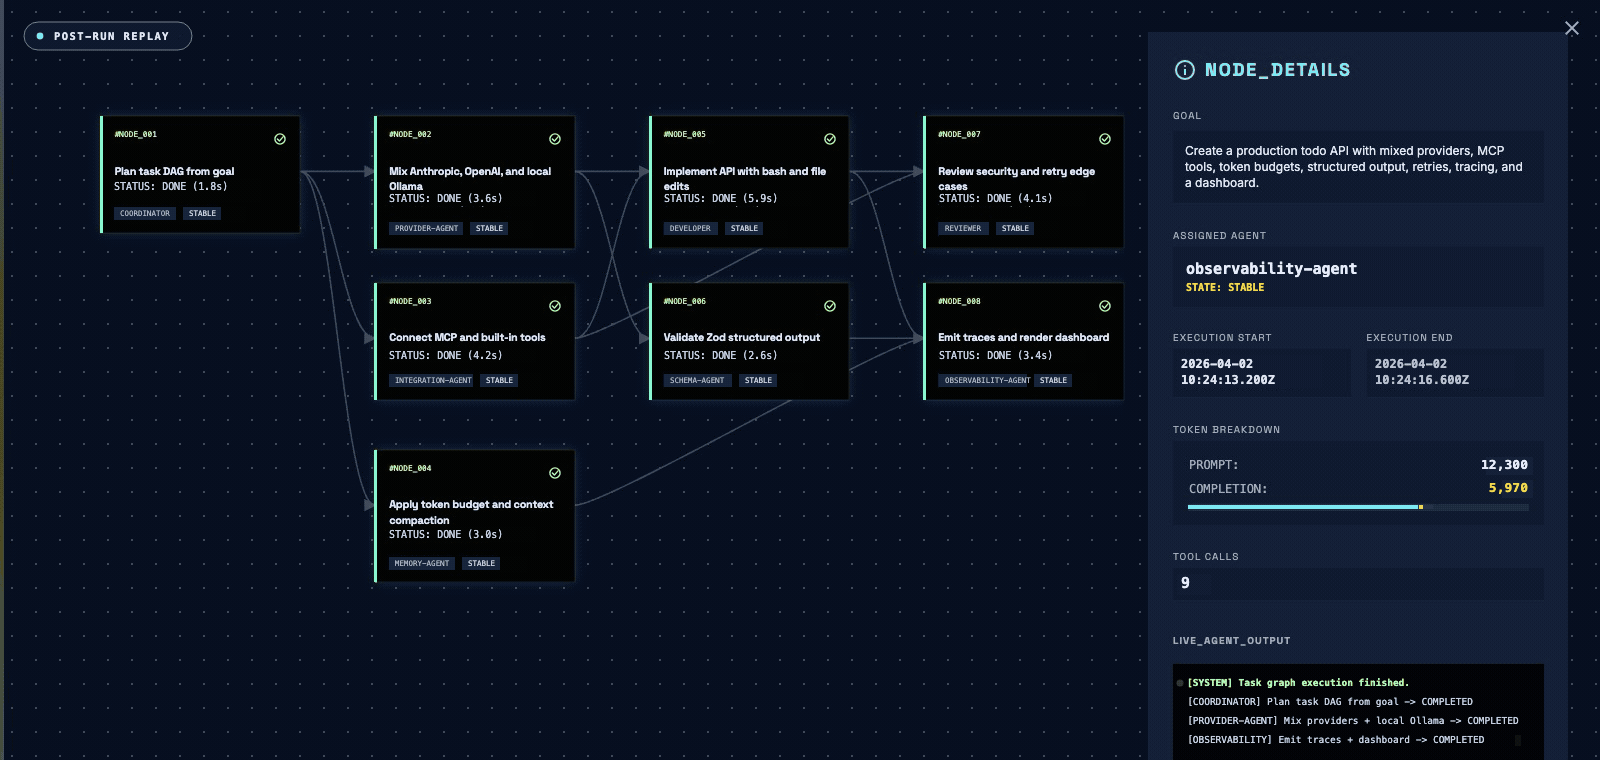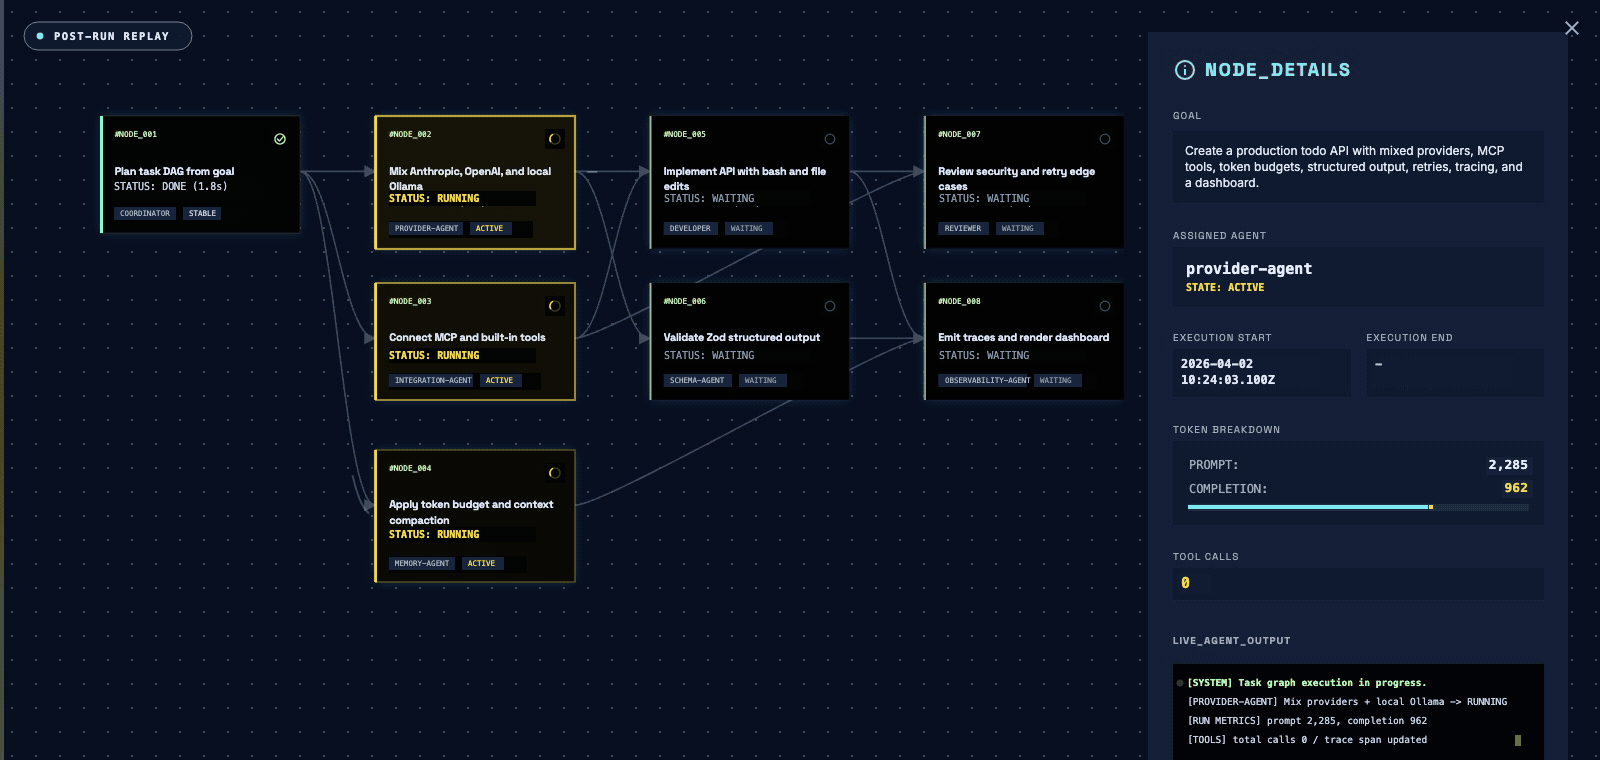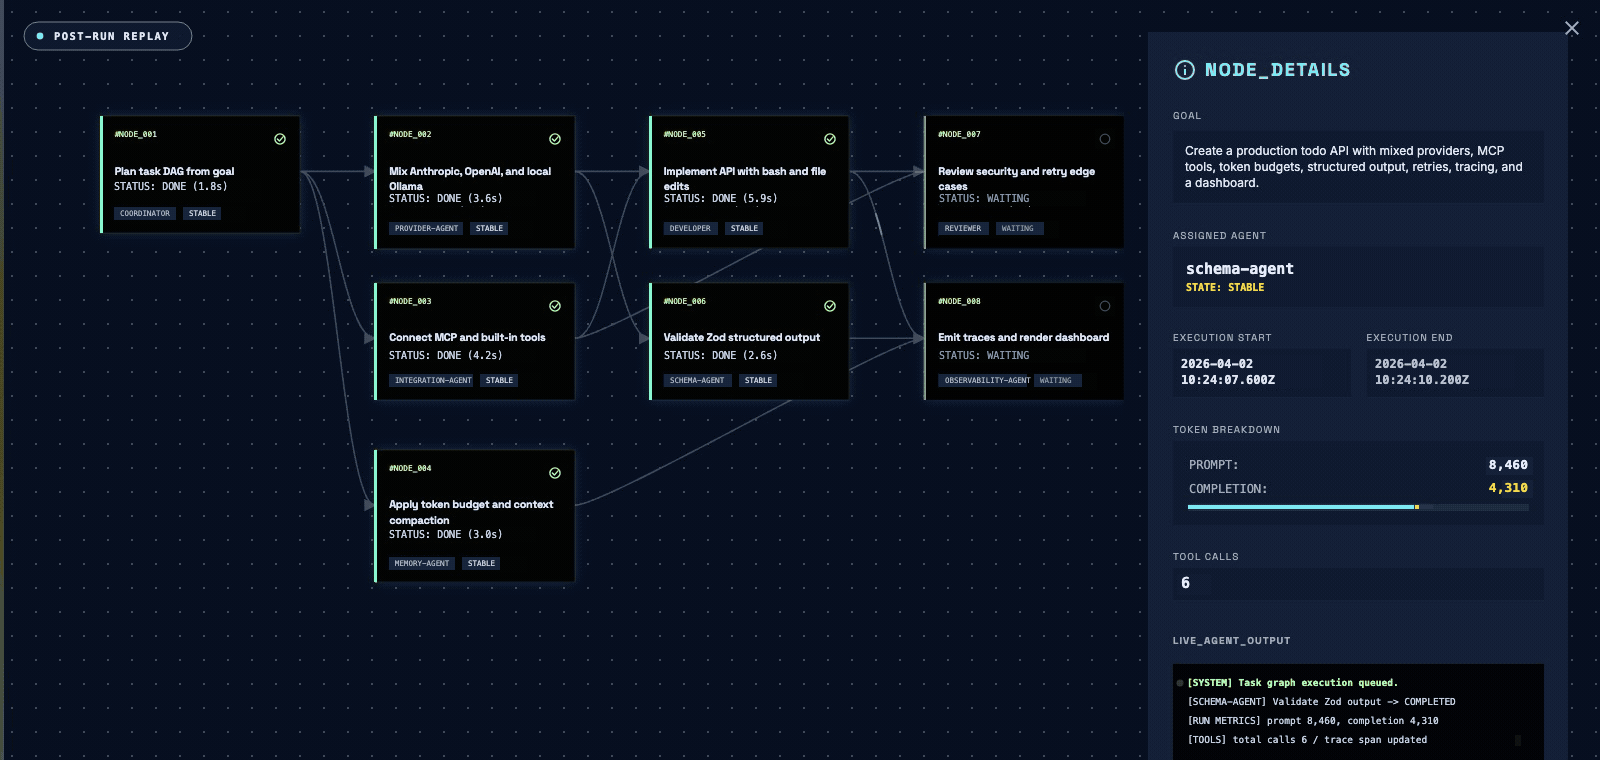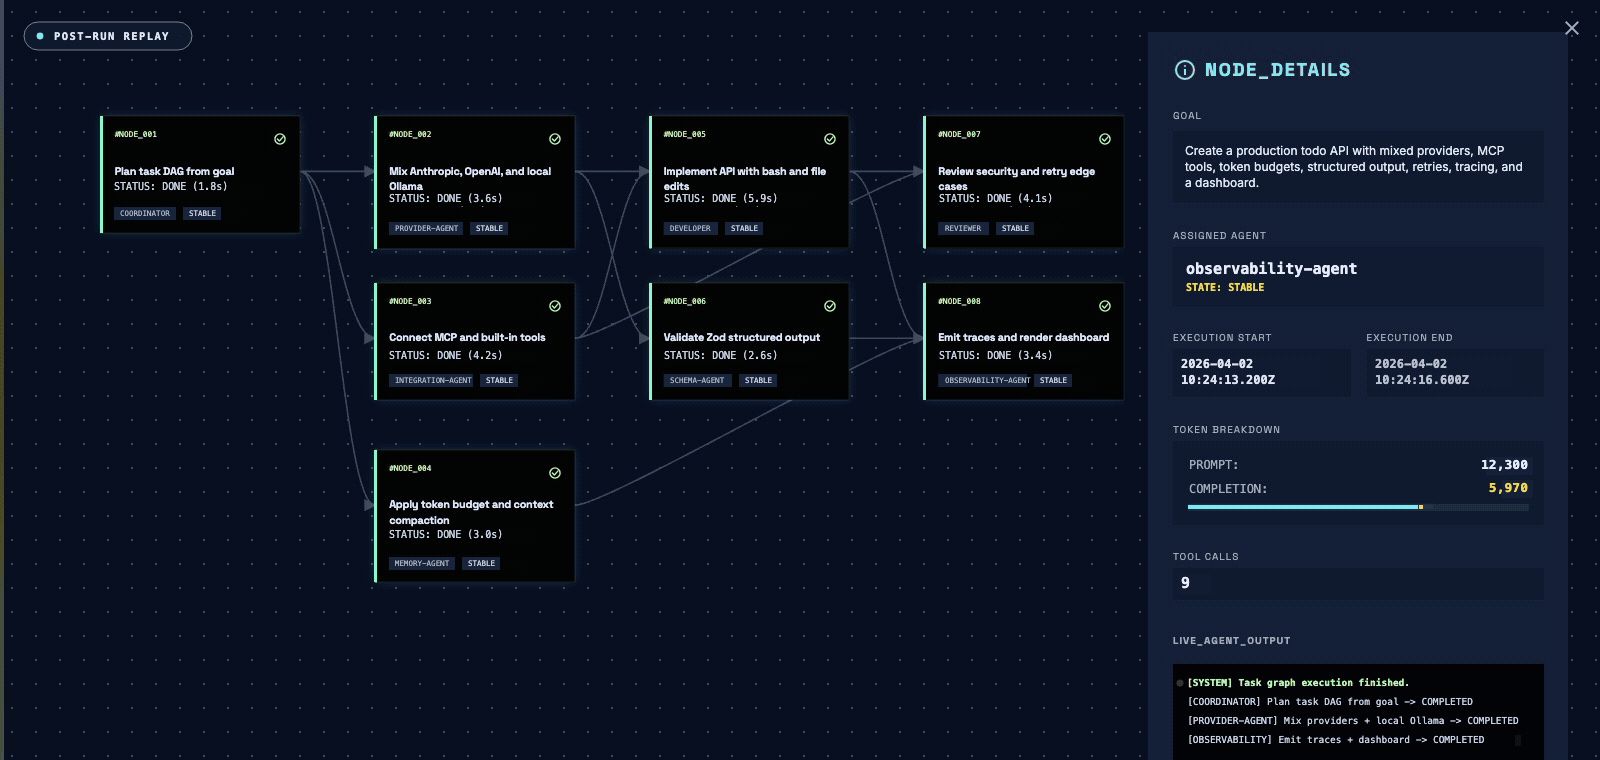
The first run shows the coordinator decompose one goal into a multi-agent DAG, then opens the offline Run Viewer for that run. To add the library to an existing project instead:
npm install @open-multi-agent/core
Migrating from @jackchen_me/open-multi-agent? That package is deprecated; install @open-multi-agent/core instead.
import { OpenMultiAgent, type AgentConfig } from '@open-multi-agent/core'

// Works with any OpenAI-compatible provider. Set OPENAI_API_KEY for OpenAI, or
// set OPENAI_BASE_URL + OMA_MODEL for Groq, DeepSeek, Ollama, etc.
const model = process.env.OMA_MODEL ?? 'gpt-5.4'

// Built-in tools are opt-in (default-deny): each agent gets only the tools it
// lists in `tools` (or a `toolPreset`). List neither and the agent gets none.
const agents: AgentConfig[] = [
  { name: 'architect', model, systemPrompt: 'Design clean API contracts.', tools: ['file_write'] },
  { name: 'developer', model, systemPrompt: 'Implement runnable TypeScript.', tools: ['bash', 'file_read', 'file_write', 'file_edit'] },
  { name: 'reviewer', model, systemPrompt: 'Review correctness and security.', tools: ['file_read', 'grep'] },
]

const orchestrator = new OpenMultiAgent({
  defaultProvider: 'openai',
  defaultModel: model,
  defaultBaseURL: process.env.OPENAI_BASE_URL, // unset = OpenAI
  onProgress: (event) => console.log(event.type, event.task ?? event.agent ?? ''),
})

const team = orchestrator.createTeam('api-team', { name: 'api-team', agents, sharedMemory: true })

// Built-in filesystem tools default to a `<cwd>/.agent-workspace` sandbox.
const result = await orchestrator.runTeam(
  team,
  `Create a REST API for a todo list in ${process.cwd()}/.agent-workspace/todo-api/`,
)

console.log(result.success, result.status?.code, result.identity?.runId)
console.log(result.totalTokenUsage.output_tokens)
Run an example locally
git clone https://github.com/open-multi-agent/open-multi-agent && cd open-multi-agent
npm install
export OPENAI_API_KEY=sk-...
npx tsx packages/core/examples/basics/team-collaboration.ts
Three agents collaborate on a REST API while onProgress streams the coordinator's task DAG:
agent_start coordinator
task_start design-api
task_complete design-api
task_start implement-handlers
task_start scaffold-tests         // independent tasks run in parallel
task_complete scaffold-tests
task_complete implement-handlers
task_start review-code            // unblocked after implementation
task_complete review-code
agent_complete coordinator        // synthesizes final result
Success: true
Tokens: 12847 output tokens
Local models via Ollama need no API key, see providers/ollama. For hosted providers (OPENAI_API_KEY, GEMINI_API_KEY, etc.), see Supported Providers.
Three Ways to Run
| Mode | Method | When to use | Example |
|---|---|---|---|
| Single agent | runAgent() |
One agent, one prompt | basics/single-agent |
| Auto-orchestrated team | runTeam() |
Give a goal, let the coordinator plan and execute | basics/team-collaboration |
| Explicit pipeline | runTasks() |
You define the task graph and assignments | basics/task-pipeline |
For answers that need scrutiny, runConsensus() runs a proposer→judge verification loop (with an opt-in per-task verify hook). See Consensus.
Preview the coordinator's task DAG without executing it, or pin that plan and replay the same graph later without another coordinator call:
// Decompose once and review the plan
const preview = await orchestrator.runTeam(team, goal, { planOnly: true })

// Turn it into a diffable, version-controllable artifact (plain JSON)
const plan = orchestrator.createPlanArtifact(preview)

// Later: replay the exact graph (same task ids, deps, assignees), no coordinator
const result = await orchestrator.runFromPlan(team, plan)
Route orchestration phases to different models with an opt-in modelRouting policy: a flagship model plans, a cheap model runs the leaf tasks. Match by phase, agent, task role/priority, or leaf status; first match wins, and omitting it leaves model selection unchanged. See Model routing.
Features
| Capability | What you get |
|---|---|
| Goal-driven coordinator | One runTeam(team, goal) call decomposes the goal into a task DAG, parallelizes independents, and synthesizes the result. Unassigned tasks are auto-scheduled — dependency-first (default), round-robin, least-busy, or capability-match. |
| Mix providers in one team | 13 built-in providers plus any OpenAI-compatible endpoint (Ollama, vLLM, LM Studio, OpenRouter, Groq), mixed freely in one team. Local servers that emit tool calls as plain text are recovered by a fallback parser. (full list · setup) |
| Extended thinking / reasoning | One thinking config maps to Anthropic thinking, Gemini thinkingConfig, and OpenAI reasoning_effort; reasoning is streamed as events, with opt-in preservation across a provider switch. (cross-provider-reasoning) |
| Tools + MCP | 6 built-in (bash, file_*, grep, glob), all opt-in (default-deny — grant via tools / toolPreset), plus delegate_to_agent handoff (cycle + depth guards), custom tools via defineTool() + Zod, stdio MCP servers via connectMCPTools(). (tool config) |
| Streaming + structured output | Token-by-token streaming on every adapter (per-agent during team runs via onAgentStream); Zod-validated final answer with auto-retry on parse failure. (structured-output) |
| Human-in-the-loop | Gate execution with onPlanReady (approve the plan before any agent runs) and onApproval (approve between task rounds), or inspect first with planOnly. |
| Pin and replay plans | Serialize a planOnly decomposition with createPlanArtifact, then runFromPlan replays the exact task graph without re-invoking the coordinator. (patterns/plan-replay) |
| Lifecycle hooks + cancellation | beforeRun rewrites the prompt, afterRun post-processes or rejects the result; pass an AbortSignal to cancel a run in flight. |
| Configurable coordinator | Override the coordinator's model, provider, adapter, system prompt, or tools via runTeam(team, goal, { coordinator }). |
| External coding agents (ACP) | Swap an agent's LLM loop for an external coding CLI over the Agent Client Protocol: set backend: { kind: 'acp', … } and the subprocess runs its own turns, while the pool, scheduler, queue, shared memory, and budget stay backend-agnostic. (external agents) |
| Observability | Every top-level result carries stable identity (runId, attempt, traceId, rootSpanId) and normalized status, even without onTrace; onProgress events, trace spans, the offline single-run DAG/Waterfall Viewer, and TeamRunResult.metrics remain available. API keys and tokens are redacted from traces, errors, bash output, and Viewer payloads. (observability guide) |
| Pluggable shared memory | Default in-process KV; swap in Redis / Postgres / your own backend by implementing MemoryStore. (shared memory) |
| Checkpoint & resume | Opt-in per-run checkpointing over any MemoryStore: snapshot on each completed task, then restore() skips finished tasks to continue after a crash or restart. Checkpoint v2 preserves runId, increments attempt, and starts a fresh trace; v1 snapshots remain readable. The bundled zero-dependency FileStore makes checkpoints durable out of the box; best-effort saves never take the run down. (checkpoint & resume) |
| Sandboxed filesystem workspace | Built-in filesystem tools are sandboxed to <cwd>/.agent-workspace by default; agents sharing the default configuration share this root. For per-agent isolation, set AgentConfig.cwd; for a different shared root, set OrchestratorConfig.defaultCwd; pass null to disable. (sandbox config) |
Production controls (context strategies, task retry with backoff, loop detection, tool output truncation/compression) are covered in the Production Checklist.
Orchestration Controls
Fine-grained control over a runTeam run. All optional; defaults keep behavior unchanged.
Inject team context. Prepend the goal, roster, and this worker's role to every worker prompt — helps workers stay aligned and makes multi-step runs easier to debug. Off by default; worker prompts stay byte-identical when omitted.
await orchestrator.runTeam(team, goal, { revealCoordinator: true })
Approve before running. Inspect the coordinator's plan before any agent executes, and again between task rounds. These live on the orchestrator. Returning false aborts; remaining tasks are marked skipped.
const orchestrator = new OpenMultiAgent({
  onPlanReady: async (tasks) => tasks.length <= 10,        // gate the whole plan
  onApproval:  async (completed, next) => next.length > 0, // gate each round
})
Cap estimated cost. Keep the price table in your app and provide an estimator. OMA passes the effective model, provider, phase, and taskId (when available) so you can price per model. The cap is checked at the same turn/task boundaries as maxTokenBudget, so a run can overshoot by up to one model turn; it is not a cent-exact stop.
const prices = {
  'gpt-5.4-mini': { input: 0.75, output: 4.5 }, // USD per 1M tokens
}

const orchestrator = new OpenMultiAgent({
  maxCostBudget: 0.25,
  estimateCost: (usage, { model }) => {
    const price = prices[model] ?? { input: 0, output: 0 }
    return (usage.input_tokens / 1_000_000) * price.input
      + (usage.output_tokens / 1_000_000) * price.output
  },
})
Cancel a run. Pass an AbortSignal; aborting stops the run in flight.
const controller = new AbortController()
const run = orchestrator.runTeam(team, goal, { abortSignal: controller.signal })
// controller.abort() from elsewhere to cancel
Configure the coordinator. Give the planner its own model, adapter, or extra instructions without touching the worker agents.
await orchestrator.runTeam(team, goal, {
  coordinator: { model: 'claude-opus-4-6', instructions: 'Prefer fewer, larger tasks.' },
})
Fan-out without dependencies. For MapReduce-style parallelism, use AgentPool.runParallel() directly. See patterns/fan-out-aggregate.
Shell & CI. Use the JSON-first oma binary. See docs/cli.md.
Ecosystem
open-multi-agent launched 2026-04-01 under MIT. Known users and integrations to date:
Built with OMA
- temodar-agent (~60 stars). WordPress security analysis platform by Ali Sünbül. Uses our built-in tools (
bash,file_*,grep) directly inside a Docker runtime. Confirmed production use. - Mark Galyan runs OMA fully offline on local quantized models, using the Coordinator and context compaction to keep autonomous agent loops alive under tight VRAM limits. Contributor since the framework's first month, across compaction, sampling, and tool-call parsing.
- PR-Copilot. AI pull-request review assistant by kidoom. Runs an OMA review team (coordinator + scoped reviewer agents), defines repo-context tools with
defineTool, and adds a customContextStrategyfor token-aware PR-diff compression. Public code on@open-multi-agent/core. - StuFlow by znc15. Terminal AI coding assistant on OMA's orchestration core: builds a team and drives it through
runAgent/runTasks/runTeamwith a customRunTeamOptionscoordinator, paired with DeepSeek. Public code on@open-multi-agent/core.
Using open-multi-agent in production or a side project? Open a discussion and we will list it here.
Integrations
- Engram — "Git for AI memory." Syncs knowledge across agents instantly and flags conflicts. (repo)
- @agentsonar/oma — Sidecar detecting cross-run delegation cycles, repetition, and rate bursts.
- CodingScaffold — Agentic-coding scaffold that lists OMA as an optional orchestration backend, with a
runTeamworkflow template.
Built an integration? See the integration guide for how to submit a reference or vendor example and get your product listed.
Featured partner
For products and platforms with a deep open-multi-agent integration. See the Featured partner program for terms and how to apply.
Examples
examples/ is organized by category: basics, cookbook, patterns, providers, and integrations. See examples/README.md for the full index. (production/ is open for contributions — see the acceptance criteria.)
Real-world workflows (cookbook/)
End-to-end scenarios you can run today. Each one is a complete, opinionated workflow.
contract-review-dag: four-task DAG for contract review with parallel branches and step-level retry on failure.meeting-summarizer: three specialised agents fan out on a transcript, an aggregator merges them into one Markdown report with action items and sentiment.competitive-monitoring: three parallel source agents extract claims from feeds; an aggregator cross-checks them and flags contradictions.translation-backtranslation: translate EN to target with one provider, back-translate with another, flag semantic drift.incident-postmortem-dag: three independent root tasks fan out at t=0, then a root-cause hypothesizer and postmortem writer synthesize them into one document.personalized-interview-simulator: a stateful interviewer (Agent.prompt()across turns) plus a transcript-reading observer, withreadlinehuman input and a Zod-validated debrief.
Patterns and integrations
basics/team-collaboration:runTeam()coordinator pattern.patterns/structured-output: any agent returns Zod-validated JSON.patterns/multi-perspective-code-review: a generator feeds security, performance, and style reviewers running in parallel, then a synthesizer returns Zod-validated findings.patterns/cross-provider-reasoning: preserve a reasoning model's thought stream across a provider switch viapreserveReasoningAsText.patterns/cost-tiered-pipeline: assign a different model per stage and estimate per-model USD cost fromonTracetoken counts.patterns/fan-out-aggregate: MapReduce-style fan-out viaAgentPool.runParallel().patterns/agent-handoff: synchronous sub-agent delegation viadelegate_to_agent.patterns/plan-replay: decompose a goal once withplanOnly, serialize it withcreatePlanArtifact, then replay the same DAG viarunFromPlanwithout re-running the coordinator.integrations/trace-observability:onTracespans for LLM calls, tools, and tasks.integrations/observability-v2/run-viewer: deterministic no-networkFileTraceStoredata exported as an offline single-run Viewer.integrations/mcp-github: expose an MCP server's tools to an agent viaconnectMCPTools().- Provider examples: scripts under
examples/providers/covering hosted providers, OpenAI-compatible endpoints, and local models.
Full applications
Clone-and-run apps with their own package.json, not npx tsx scripts. Each embeds OMA in a real backend.
integrations/express-customer-support: Express REST API.runTasks()behindPOST /ticketswith per-agent Zod schemas, swappable provider env vars, and HTTP error mapping. Runs on one DeepSeek key (npm install && npm start).integrations/with-vercel-ai-sdk: Next.js app. OMArunTeam()plus AI SDKuseChatstreaming (npm install && npm run dev).
Run any script with npx tsx packages/core/examples/<path>.ts; the full applications above use their own npm scripts.
How is this different from X?
Most TypeScript teams picking a multi-agent layer are really choosing between OMA, LangGraph JS, and Mastra. The mechanism is what differs: dynamic planning instead of rigid hand-wired graphs.
vs. LangGraph JS. LangGraph has you design a declarative graph (nodes, edges, conditional routing) up front, then compiles it into an invokable; OMA's Coordinator decomposes the goal into a task DAG at runtime and auto-parallelizes independents. Both checkpoint and resume, though LangGraph's persistence ecosystem runs deeper. Reach for OMA when the plan should adapt to the goal instead of being wired ahead of time.
vs. Mastra. Both are TypeScript-native; the difference is who drives orchestration. Mastra has you wire the workflow by hand. OMA is goal-driven: hand its Coordinator a goal and it builds the task DAG at runtime. runTeam(team, goal) in one call.
vs. CrewAI. CrewAI is the established multi-agent option in Python. OMA brings goal-driven decomposition to TypeScript backends with a deliberately governed dependency surface and direct Node.js embedding, with no separate Python service to stand up alongside your stack. New dependencies must justify their security, size, maintenance, and compatibility cost; optional or platform-specific SDKs remain isolated when that boundary is useful.
vs. Vercel AI SDK. AI SDK is the LLM-call layer (provider abstraction, streaming, tool calls, and structured outputs), not a multi-agent orchestrator. Use it alone for single-agent calls; reach for OMA the moment you need a coordinated team. OMA even ships an optional AI SDK bridge.
vs. Claude Code's dynamic workflows. Anthropic shipped dynamic workflows in Claude Code in May 2026: Claude writes its own orchestration scripts and fans out parallel subagents inside a session. The difference is form factor: dynamic workflows run inside Claude Code on Claude subagents, while OMA embeds the same goal-to-DAG mechanism in your own Node.js backend as an MIT library, on any provider. The plan stays data you can inspect and replay (planOnly, createPlanArtifact, runFromPlan), and over ACP an OMA team can even run Claude Code itself as one of its agents.
Architecture
┌─────────────────────────────────────────────────────────────────┐
│  OpenMultiAgent (Orchestrator)                                  │
│                                                                 │
│  createTeam()  runTeam()  runTasks()  runAgent()  getStatus()   │
└──────────────────────┬──────────────────────────────────────────┘
                       │
            ┌──────────▼──────────┐
            │  Team               │
            │  - AgentConfig[]    │
            │  - MessageBus       │
            │  - TaskQueue        │
            │  - SharedMemory     │
            └──────────┬──────────┘
                       │
         ┌─────────────┴─────────────┐
         │                           │
┌────────▼──────────┐    ┌───────────▼───────────┐
│  AgentPool        │    │  TaskQueue             │
│  - Semaphore      │    │  - dependency graph    │
│  - runParallel()  │    │  - auto unblock        │
└────────┬──────────┘    │  - cascade failure     │
         │               └───────────────────────┘
┌────────▼──────────┐
│  Agent            │
│  - run()          │    ┌────────────────────────┐
│  - prompt()       │───►│  LLMAdapter            │
│  - stream()       │    │  - 13 built-in         │
└────────┬──────────┘    │    providers           │
         │               │  - OpenAI-compatible   │
         │               │  - AI SDK bridge       │
         │               └────────────────────────┘
┌────────▼──────────┐
│  AgentRunner      │    ┌──────────────────────┐
│  - conversation   │───►│  ToolRegistry        │
│    loop           │    │  - defineTool()      │
│  - tool dispatch  │    │  - 6 built-in tools  │
└───────────────────┘    │  + delegate (opt-in) │
                         └──────────────────────┘
Observability is a parallel, optional data plane across every execution mode; stable identity and status remain part of the run result even when no sink is configured:
Execution runtime (runAgent / runTeam / runTasks / restore)
├─ RunIdentity + RunStatus ─────────────────────────► result / checkpoint continuation
├─ legacy TraceEvent ────────────────────────────► onTrace / LegacyCallbackTraceSink
└─ TraceRecord v2 (start / event / end + links)
   └─ metadata-only privacy processor (default)
      └─ TraceSink (fast emit + stats / diagnostics)
         ├─ BatchingTraceSink ─► TraceExporter
         │                      ├─ custom backend
         │                      └─ TraceStoreExporter
         │                         ├─ InMemoryTraceStore
         │                         └─ FileTraceStore (/observability/file)
         └─ @open-multi-agent/otel ─► application-owned TracerProvider
These stores have deliberately different responsibilities: a TraceStore
holds queryable telemetry, a checkpoint store holds resumable execution state,
and the Run Viewer renders an offline post-run task DAG plus hierarchical span
Waterfall. Use renderRunViewer({ result, run }), oma run --dashboard, or
oma dashboard --trace-store <path> --run-id <id> for current or historical
single-run artifacts. renderTeamRunDashboard(result) remains compatible. The application owns
forceFlush() / shutdown(), file-store flush() / close(), and shutdown of
any supplied OpenTelemetry provider. See the observability guide
and migration guide.
Supported Providers
Change provider, model, and set the env var. The agent config shape stays the same.
const agent: AgentConfig = {
  name: 'my-agent',
  provider: 'anthropic',
  model: 'claude-sonnet-4-6',
  systemPrompt: 'You are a helpful assistant.',
}
| Kind | How to configure | Services |
|---|---|---|
| Built-in, no extra install | Set provider to anthropic, openai, azure-openai, copilot, grok, deepseek, doubao, hunyuan, minimax, mimo, or qiniu; the bundled @anthropic-ai/sdk / openai SDK supplies the endpoint. |
Anthropic, OpenAI, Azure OpenAI, GitHub Copilot, xAI Grok, DeepSeek, Doubao (Volcengine), Hunyuan (Tencent MaaS), MiniMax, MiMo, Qiniu |
| Built-in, needs a peer install | Set provider: 'gemini' after npm i @google/genai, or provider: 'bedrock' after npm i @aws-sdk/client-bedrock-runtime. |
Google Gemini, AWS Bedrock |
| OpenAI-compatible endpoints | Set provider: 'openai' plus baseURL and, when needed, apiKey. No extra install. |
Ollama, vLLM, LM Studio, llama.cpp server, OpenRouter, Groq, Mistral, Moonshot (Kimi), Qwen, Zhipu |
| Vercel AI SDK | Import AISdkAdapter from @open-multi-agent/core/ai-sdk; install optional peer ai plus an @ai-sdk/* provider. |
Any AI SDK provider (60+ models and hosts) |
See docs/providers.md for env vars, model examples, local tool-calling, timeouts, and troubleshooting.
Dependencies
At present, @open-multi-agent/core directly installs @anthropic-ai/sdk, openai, and zod; this is an implementation detail, not a fixed dependency-count policy. Anthropic, OpenAI, and every OpenAI-compatible endpoint use those packages today.
Dependency changes are governed by demonstrated value plus security, install size, maintenance, and compatibility cost. Optional or platform-specific capabilities remain isolated when that keeps unused SDKs out of the root import; the boundary is architectural, not a permanent numeric cap.
Other provider integrations are opt-in peer dependencies that load lazily, so a project that never uses one never installs it. OpenTelemetry integration is a separately installable package: OTel APIs, SDKs, semantic-convention mappings, and exporter integrations live in @open-multi-agent/otel, so importing or running core does not require OpenTelemetry.
| Capability | Install | Trigger |
|---|---|---|
| Gemini provider | npm i @google/genai |
provider: 'gemini' |
| Bedrock provider | npm i @aws-sdk/client-bedrock-runtime |
provider: 'bedrock' |
| MCP tools | npm i @modelcontextprotocol/sdk |
connectMCPTools() |
| Vercel AI SDK bridge | npm i ai @ai-sdk/<provider> |
new AISdkAdapter(...) |
| OpenTelemetry traces | npm i @open-multi-agent/otel plus your application-selected OTel SDK/exporter |
createOtelTraceSink(...) |
Vercel AI SDK (optional)
With the bridge peers installed (see the table above), pass adapter: new AISdkAdapter(model) on AgentConfig to route that agent through the AI SDK instead of the built-in provider factory. provider, apiKey, baseURL, and region are ignored when adapter is set. Mixed teams work as usual: only agents with adapter use the AI SDK.
import { openai } from '@ai-sdk/openai'
import { AISdkAdapter } from '@open-multi-agent/core/ai-sdk'
import { OpenMultiAgent } from '@open-multi-agent/core'

const oma = new OpenMultiAgent()
await oma.runAgent(
  {
    name: 'researcher',
    model: 'gpt-4o',
    adapter: new AISdkAdapter(openai('gpt-4o')),
    systemPrompt: 'You are a researcher.',
  },
  'What are the latest AI trends?',
)
The coordinator accepts the same hook via runTeam(team, goal, { coordinator: { adapter: new AISdkAdapter(...) } }).
Production Checklist
Before going live, wire up the controls that protect token spend, recover from failure, and let you debug.
| Concern | Knob | Where it lives |
|---|---|---|
| Bound the conversation | maxTurns per agent + contextStrategy (sliding-window / summarize / compact / custom) |
AgentConfig |
| Bound wall-clock time | timeoutMs per agent (aborts a run that hangs, common with local models) |
AgentConfig |
| Bound a single LLM call | callTimeoutMs per agent (aborts one stalled adapter.chat(), uniform across providers) |
AgentConfig |
| Cap tool output | maxToolOutputChars (or per-tool maxOutputChars) + compressToolResults: true |
AgentConfig and defineTool() |
| Recover from failure | Per-task maxRetries, retryDelayMs, retryBackoff (exponential multiplier) |
Task config used via runTasks() |
| Survive a crash or restart | checkpoint (pass a runId, or a durable MemoryStore like the bundled FileStore) + restore() to resume, skipping completed tasks |
OrchestratorConfig / run options |
| Hard-cap token spend | maxTokenBudget on the orchestrator |
OrchestratorConfig |
| Cap estimated cost | maxCostBudget + estimateCost; you own the per-model price table, and checks happen at turn/task boundaries rather than cent-exact mid-call stops |
OrchestratorConfig |
| Catch stuck agents | loopDetection with onLoopDetected: 'terminate' (or a custom handler) |
AgentConfig |
| Trace and audit | Configure observability.sinks with batching + an exporter, TraceStore, or OTel adapter; render one run with renderRunViewer({ result, run }), oma run --dashboard, or historical oma dashboard --trace-store … --run-id …; explicitly flush/shut down application-owned telemetry |
OrchestratorConfig + application lifecycle |
| Redact secrets | Automatic — API keys, tokens, and Authorization headers stripped from traces, bash output, and Viewer payloads | built-in (on by default) |
| Grant tools deliberately | Built-in tools are opt-in (default-deny): an agent gets only what it lists in tools / toolPreset; list neither and it gets none. bash stays unsandboxed once granted, and every tool result is sent to your model provider — so grant read/exec access on purpose. defaultToolPreset restores the old "all tools" behavior in one line |
AgentConfig / OrchestratorConfig |
| Bound filesystem reach | cwd / defaultCwd (default .agent-workspace subdir; widen with process.cwd(), disable with null) |
AgentConfig / OrchestratorConfig |
Documentation
- Providers — env vars, model examples, local tool-calling, timeouts, troubleshooting.
- Tool configuration — tool presets, custom tools, the filesystem sandbox, and MCP.
- Observability — stable identity/status, TraceRecord v2, bounded sink/exporter lifecycle, InMemory/File TraceStore, and the offline single-run DAG/Waterfall Viewer. Existing callbacks have a staged
onTracemigration guide;@open-multi-agent/oteluses an application-owned provider. - Shared memory — the default store and custom
MemoryStorebackends. - Checkpoint & resume — checkpoint v2 identity rules, v1 compatibility, and restore over any
MemoryStore. - Context management — sliding window, summarization, compaction, and custom compressors.
- CLI — the JSON-first
omabinary for shell and CI. - Consensus — the
runConsensusproposer→judge primitive, the per-taskverifyhook, and the budget invariant. - Model routing — the opt-in
modelRoutingpolicy: match by phase / agent / role / priority / leaf, first match wins. - Plan preview & replay — preview the coordinator's task DAG with
planOnly, freeze it withcreatePlanArtifact, thenrunFromPlanreplays the exact graph without re-invoking the coordinator.
Contributing
Issues, feature requests, and PRs are welcome. Some areas where contributions would be especially valuable:
- Production examples. Real-world end-to-end workflows. See
examples/production/README.mdfor the acceptance criteria and submission format. - Documentation. Guides, tutorials, and API docs.
- Translations. Help translate this README into other languages. Open a PR.
Contributors
Contributor credits by area
Framework features
- @ibrahimkzmv (token budget, context strategy, dependency-scoped context, tool presets, glob, MCP integration, configurable coordinator, CLI, dashboard rendering, trace event types)
- @apollo-mg (context compaction fix, sampling parameters)
- @tizerluo (onPlanReady, onAgentStream)
- @CodingBangboo (planOnly mode)
- @Xin-Mai (output schema validation)
- @JasonOA888 (AbortSignal support)
- @EchoOfZion (coordinator skip for simple goals)
- voidborne-d (OpenAI mixed-content fix, text-tool-extractor depth fix)
- @NamelessNATM (agent delegation base implementation)
- @MyPrototypeWhat (reasoning blocks, reasoning_effort, sampling parity, trace input/output)
- @SiMinus (streaming reasoning events)
- @matthewYang08 (OpenAI reasoning-to-text fallback)
- @dvirarad (OpenAI-family adapter hardening)
- @cat0825 (model routing policy, plan replay, structured shared-memory handoff)
- @mvanhorn (checkpoint & resume)
- @lesbass (run-level metrics rollup on
TeamRunResult) - @tlysanhuo (trace span parent linkage)
- @LambIessz (orchestrator cost budget, MessageBus persistence in checkpoints)
- @Bobuyoucrypto (Windows bash timeout process-tree kill)
Provider integrations
- @ibrahimkzmv (Gemini)
- @hkalex (DeepSeek, MiniMax)
- @marceloceccon (Grok)
- @Klarline (Azure OpenAI)
- @Deathwing (GitHub Copilot)
- @JackChiang233 (Qiniu)
- @CodingBangboo (AWS Bedrock)
- @kidoom (MiMo, Doubao)
- @KaitlynFeng (Hunyuan)
- @octo-patch (MiniMax-M3 model upgrade)
Examples & cookbook
- @mvanhorn (research aggregation, code review, meeting summarizer, Groq example, Mistral example)
- @Kinoo0 (code review upgrade)
- @Optimisttt (research aggregation upgrade)
- @Agentscreator (Engram memory integration)
- @fault-segment (contract-review DAG)
- @HuXiangyu123 (cost-tiered example)
- @zouhh22333-beep (translation/backtranslation)
- @pei-pei45 (competitive monitoring)
- @mmjwxbc (interview simulator)
- @binghuaren96 (incident postmortem DAG)
- @DaiMao-UT (paper replication triage)
- @oooooowoooooo (rare disease information triage)
- @CodingBangboo (Express customer support pipeline)
- @nuthalapativarun (Doubao and Zhipu provider examples)
- @goodneamtakenbydogs (Moonshot and Qwen provider examples)
- @suans4746-del (narrative puzzle hint arbitration)
- @gregkonush (Bilig WorkPaper MCP integration)
Docs & tests
- @tmchow (llama.cpp docs)
- @kenrogers (OpenRouter docs)
- @jadegold55 (LLM adapter test coverage)
- @btroops (DeepSeek tool-calling tests)
- @nuthalapativarun (context-management docs)
- @Oxygen56 (errors.ts tests, provider docs for Grok/DeepSeek/Doubao)
- @RheagalFire (LiteLLM gateway docs)
License
MIT