
Open Multi-Agent
Describe the goal, not the graph.
Multi-agent orchestration that runs in your own environment.


Website · Docs · npm · Discussions
English · 中文
@open-multi-agent/core is the OMA orchestration runtime for TypeScript backends. Give it one agent, an explicit task graph, or a dynamic workflow that the coordinator generates from a goal at runtime.
The runtime schedules dependencies, runs independent work in parallel, shares context across agents, and returns an inspectable result. For product positioning and known users, see the project overview.
Contents
Quick Start · Execution Modes · Scheduling · Capabilities · Architecture · Examples · Providers · Production · Documentation
Quick Start
Requires Node.js 18 or newer. Scaffold and run a starter in one command:
npm create oma-app@latest my-oma
In an interactive terminal, the scaffolder selects a starter and Cloud/Ollama runtime, installs dependencies, then runs a deterministic demo and produces an offline dashboard. The demo uses scripted model responses, needs no API key, and makes no model request; OMA orchestration still runs locally for real. Pass --no-install to generate files only, or --no-run to install without starting the demo.
To add OMA to an existing backend:
npm install @open-multi-agent/core
Migrating from @jackchen_me/open-multi-agent? That package is deprecated; install @open-multi-agent/core instead.
import { OpenMultiAgent, type AgentConfig } from '@open-multi-agent/core'

const model = process.env.OMA_MODEL ?? 'gpt-5.4'

const agents: AgentConfig[] = [
  { name: 'researcher', model, systemPrompt: 'Find the relevant facts.' },
  { name: 'analyst', model, systemPrompt: 'Compare evidence and identify tradeoffs.' },
]

const orchestrator = new OpenMultiAgent({
  defaultProvider: 'openai',
  defaultModel: model,
})

const team = orchestrator.createTeam('research-team', {
  name: 'research-team',
  agents,
  sharedMemory: true,
})

const result = await orchestrator.runTeam(team, 'Compare three approaches and recommend one.')
console.log(result.agentResults.get('coordinator')?.output)
Set OPENAI_API_KEY for this example. For other hosted or local models, see Providers.
Execution Modes
| Mode | Method | When to use | Example |
|---|---|---|---|
| Single agent | runAgent() |
One agent, one prompt | basics/single-agent |
| Auto-orchestrated team | runTeam() |
Give a goal, let the coordinator plan and execute | basics/team-collaboration |
| Explicit pipeline | runTasks() |
You define the task graph and assignments | basics/task-pipeline |
Use planOnly to inspect a generated task graph before execution, then createPlanArtifact() and runFromPlan() to replay it. runConsensus() adds a proposer→judge verification loop when one answer needs extra scrutiny.
Automatic runTeam() topology is pluggable through executionRouter on OpenMultiAgent or one runTeam() call. The built-in DeterministicRouter uses language-neutral structure and script-aware length, with an empty-roster qualification for the Single path; custom routers receive a prompt-free roster summary and fall back safely when they fail. Explicit mode and declared governance always take precedence, and auto results expose routingDecision. See Execution Routing. Execution Routing selects Single versus Team; Model Routing selects models inside that topology.
When an application must enforce named independent roles, declare that governance intent instead of relying on wording in the goal:
const governed = await orchestrator.runTeam(team, 'Review the evidence and assess the risk.', {
  governanceIntent: 'required',
  requiredRoles: ['researcher', 'analyst'],
  requiredOrder: ['researcher', 'analyst'],
})

if (governed.governanceConclusion !== 'satisfied') {
  throw new Error('Required governance was not satisfied by the executed topology.')
}
required and preferred both bypass automatic decomposition and the simple-goal short circuit. OMA creates one task per declared roster name, assigns it to that agent, and chains tasks in requiredOrder; dependency outputs are passed to downstream roles. The topology comes only from these structured fields, so equivalent goals in different languages use the same roles and order. none or an omitted governanceIntent preserves the existing automatic runTeam() behavior.
After execution, governanceConclusion is satisfied, unsatisfied, or not-applicable. Governance-sensitive applications must check it separately from success: the verdict comes from the structured execution receipt, not from role names or approval wording in the model answer. See Tool configuration.
Scheduling
Set schedulingStrategy on OpenMultiAgent to choose how unassigned tasks are
mapped to agents. The setting applies to coordinator-generated runTeam()
plans and explicit or restored task queues. Tasks with an explicit assignee
keep that assignment.
Task DAG execution is event-driven: a downstream task starts as soon as its dependencies are satisfied, without waiting for unrelated tasks from the same ready set, and dependency outputs reach dependents as task-scoped results and validated structured handoffs.
const orchestrator = new OpenMultiAgent({
  schedulingStrategy: 'composite',
  schedulingWeights: { fit: 0.7, load: 0.3 },
})
| Strategy | Assignment behavior | Recommended when |
|---|---|---|
dependency-first (default) |
Assigns tasks that unblock the most downstream work first, rotating eligible agents | The task graph has meaningful dependencies |
round-robin |
Distributes tasks in queue order across eligible agents | Agents are interchangeable |
least-busy |
Chooses the eligible agent with the fewest active or newly assigned tasks | Task duration varies and load balance matters |
capability-match |
Filters explicit task requirements, then prefers declared capability tags before legacy keyword affinity | Tasks or agents declare differentiated requirements/capabilities |
composite |
Ranks tasks by blocked dependents, then maximizes fit and available capacity across eligible agents | Criticality, capability fit, and current load should influence one decision |
Agents may declare description, capabilities, costTier, and
latencyClass, and tasks may add hard requires constraints. All strategies
fail before worker execution when those constraints cannot be satisfied.
Coordinator plans also fail fast by default when they name an agent outside
the roster; set strictAssignees: false only to retain legacy reassignment.
Weight semantics, load normalization, NO_ELIGIBLE_AGENT and
INVALID_ASSIGNEE behavior, approval compatibility, and progress-event migration
are covered in
Task scheduling and dispatch.
Capabilities
| Capability | What you get |
|---|---|
| Dynamic orchestration | Runtime goal decomposition, dependency-aware scheduling, parallel branches, configurable assignment, task-scoped results and handoffs, opt-in team context for workers (revealCoordinator), and final synthesis. |
| Models and reasoning | Mix built-in, OpenAI-compatible, AI SDK, or local models; map one thinking config to each provider's reasoning setting, route phases separately, and preserve reasoning only when explicitly enabled. |
| Tools and handoffs | Built-in tools are default-deny; custom tools, MCP, and guarded delegate_to_agent handoffs are opt-in, and consequential tools on undeclared runs are flagged for confirmation. |
| Controlled outputs | Stream per agent, validate results with Zod, approve plans, legacy task rounds (onApproval), or individual dispatches (onTaskDispatch), rewrite prompts or post-process results with beforeRun / afterRun, and cancel with AbortSignal. |
| Evaluation | Version EvalSets, run reference scorers, gate CI with offline reports, persist results, or sample production runs on a best-effort path. |
| Memory and recovery | Shared memory is pluggable; checkpoints resume interrupted runs without repeating completed tasks. |
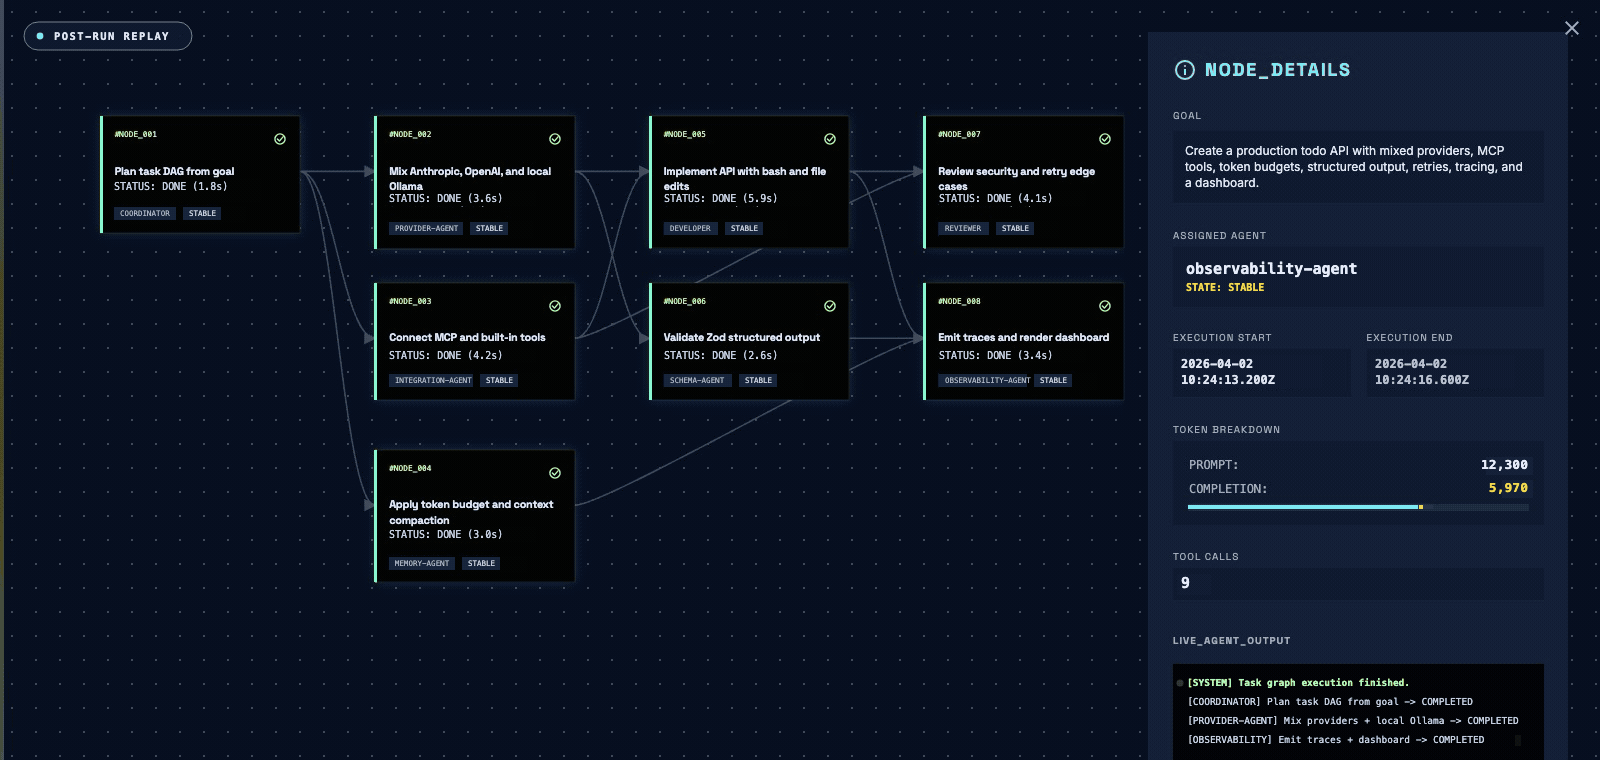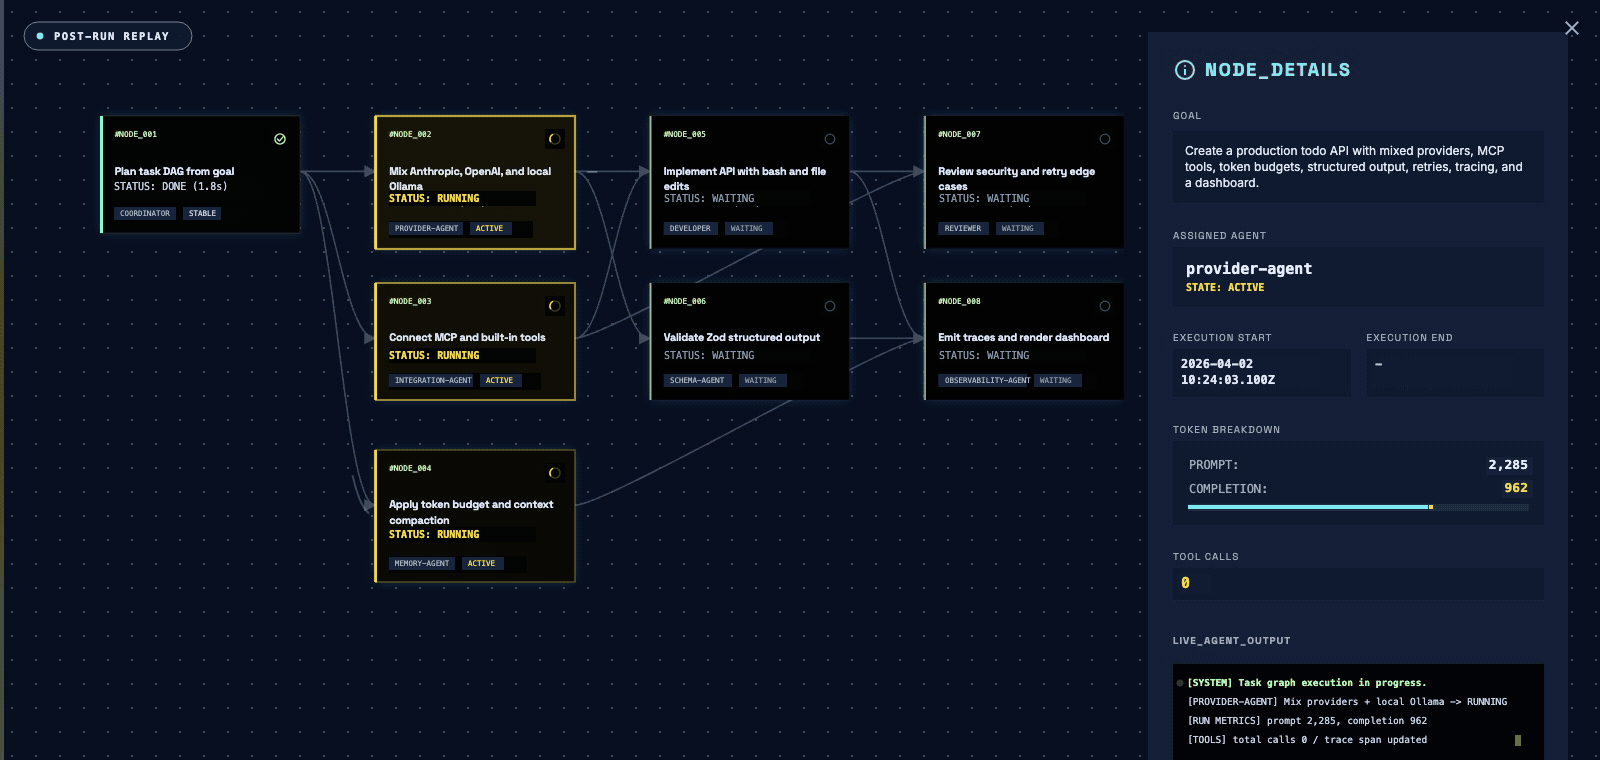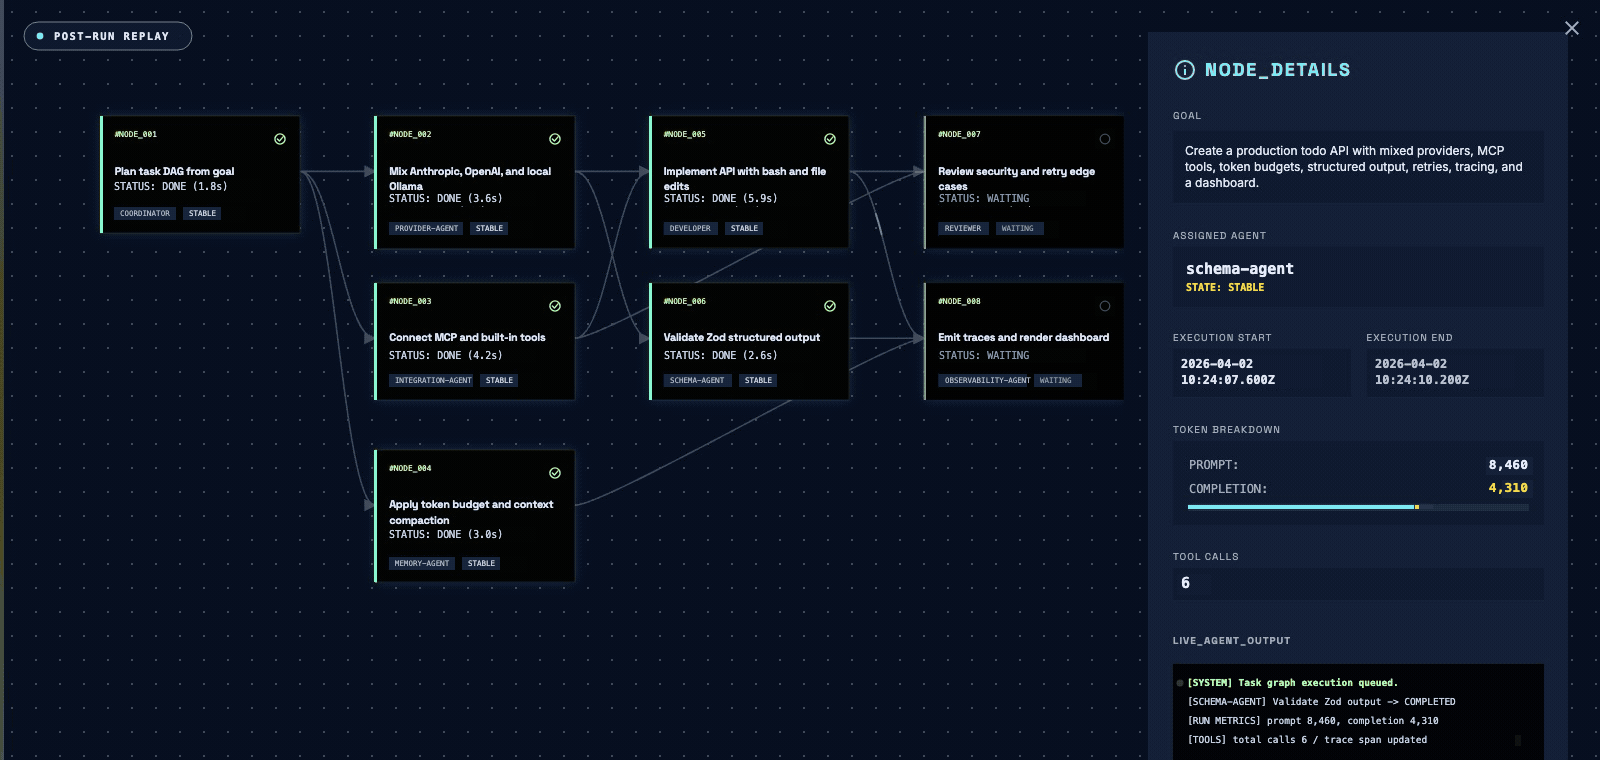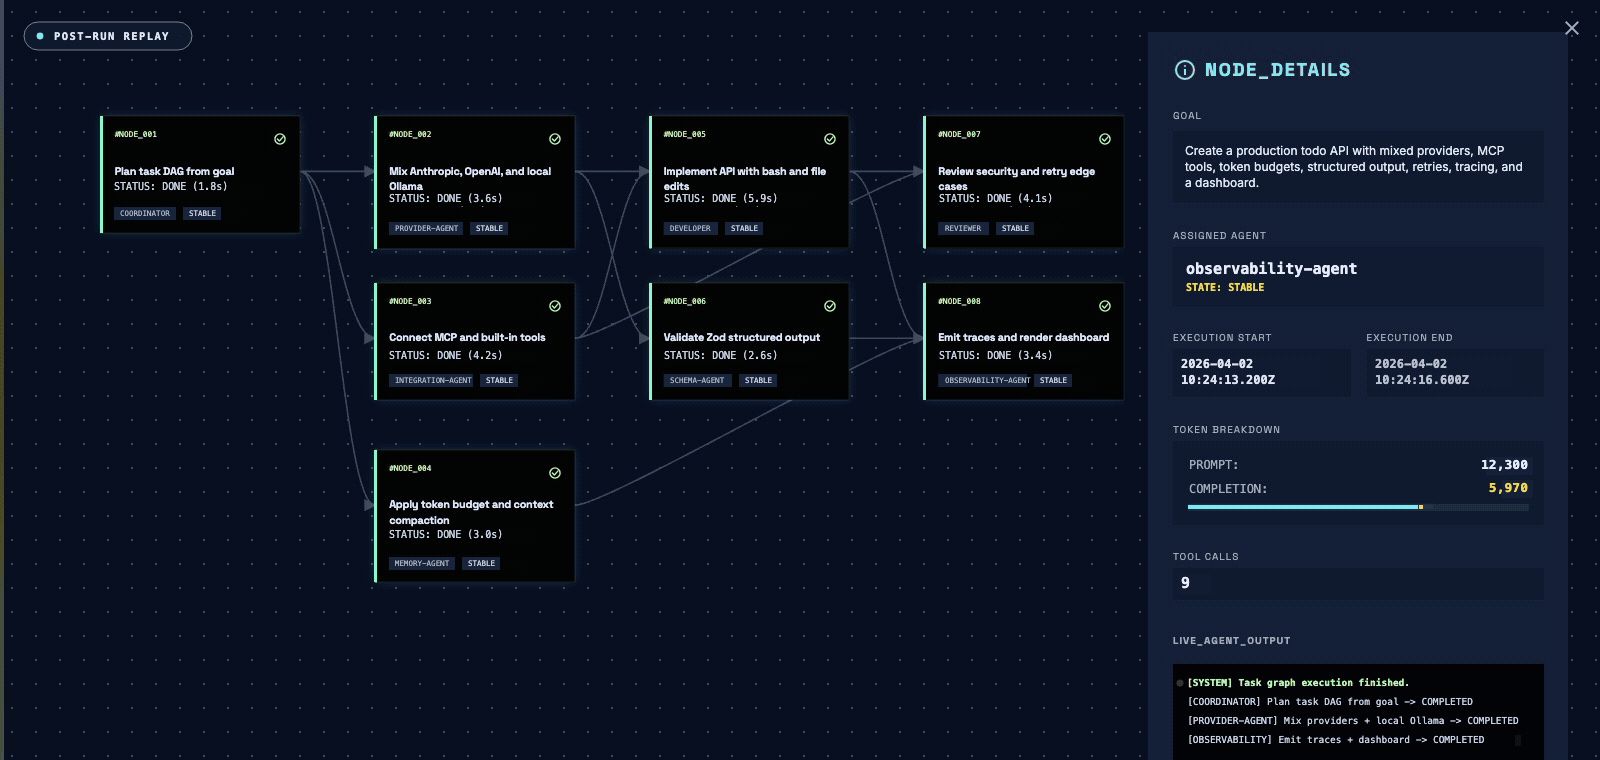
| Observability | Stable run identity, traces, execution receipts, redaction, TraceStore, and the offline DAG/Waterfall Viewer are available without a hosted service. |
| External agents | ACP and process backends let coding CLIs participate while OMA keeps scheduling, memory, and budgets. |
Architecture
goal or explicit tasks
         |
         v
Coordinator -> Task DAG -> Scheduler -> AgentPool
                    |                       |-- LLM adapters
                    |                       `-- tools / external backends
                    |
                    |-- SharedMemory / checkpoints
                    |-- TraceRecord -> TraceStore / Run Viewer / OTel
                    `-- results -> evaluation (offline / sampled, observe-only)
The coordinator plans once; the scheduler owns execution order. Agents share results through memory, while checkpoints and traces form separate recovery and observability paths. Evaluation observes completed results and never changes them. Detailed contracts live in the linked subsystem guides below.
Examples
Start with one example that matches the behavior you need:
| Goal | Example |
|---|---|
| See coordinator planning | basics/team-collaboration |
| Build an explicit DAG | cookbook/contract-review-dag |
| Observe event-driven DAG dispatch | patterns/event-driven-dag |
| Validate structured output | patterns/structured-output |
| Delegate between agents | patterns/agent-handoff |
| Replay a frozen plan | patterns/plan-replay |
| Embed OMA in a backend | integrations/express-customer-support |
| Export an offline trace viewer | integrations/observability-v2/run-viewer |
The example index lists 50+ runnable examples across basics, cookbook workflows, patterns, providers, and integrations.
Providers
Change provider, model, and credentials; the agent shape stays the same.
| Route | Use |
|---|---|
| Built in | Anthropic, OpenAI, Azure OpenAI, Copilot, Grok, DeepSeek, Doubao, Hunyuan, MiniMax, MiMo, Qiniu |
| Optional peers | Gemini (@google/genai) and Bedrock (@aws-sdk/client-bedrock-runtime) |
| OpenAI-compatible | Set provider: 'openai' + baseURL for Ollama, vLLM, LM Studio, OpenRouter, Groq, Mistral, Kimi, Qwen, or Zhipu |
| AI SDK | Use AISdkAdapter with ai and your selected @ai-sdk/* provider (AI SDK 7 needs Node.js 22+) |
Optional integrations load only when used: core directly installs only @anthropic-ai/sdk, openai, and zod; other SDKs are lazy-loading opt-in peers, and OpenTelemetry lives entirely in @open-multi-agent/otel. Dependency changes are weighed on demonstrated value plus security, size, maintenance, and compatibility cost, not a fixed count.
See Providers and Tool configuration for credentials, models, the AI SDK bridge, reasoning settings, MCP, and local endpoints.
Production
| Goal | Configure |
|---|---|
| Bound work | maxTurns, timeoutMs, callTimeoutMs, contextStrategy, loopDetection |
| Control spend | maxTokenBudget; maxCostBudget + application-owned estimateCost |
| Limit tools | tools / toolPreset, cwd / defaultCwd, tool-output caps |
| Recover | Task retries, checkpointing, and restore() |
| Review work | planOnly, onPlanReady, and approval callbacks |
| Observe | Trace sinks, TraceStore, execution receipts, Run Viewer, or the optional OTel adapter |
Budget checks run at turn and task boundaries, so a run can overshoot by up to one model turn; they are not a cent-exact stop. estimateCost receives each call's token usage plus the agent, effective model, provider, phase, and taskId, and your application owns the price table.
Built-in tools are default-deny, and every tool result is sent to your model provider, so grant read and exec access deliberately. Filesystem tools stay within the configured cwd; granted bash is not sandboxed. Secrets are redacted from traces, shell output, and Viewer payloads by default.
Observability
Core already provides run identity, trace sinks, execution receipts, queryable in-memory/file stores, and an offline Run Viewer. These cover local debugging, audit artifacts, and post-run analysis without OpenTelemetry.
@open-multi-agent/otel is an optional enterprise integration for teams that already operate a centralized OpenTelemetry stack. It converts OMA traces into standard OTel spans so multi-agent runs can join company-wide monitoring, alerting, and incident workflows. The application owns the provider and its lifecycle; telemetry failures never change the run result.
See the observability guide, migration guide, and performance guidance.
Documentation
| Area | Guides |
|---|---|
| Build agents | Providers, tools, context |
| Run reliably | Evaluation, checkpoint & resume, execution routing, model routing, consensus |
| Control workflows | Plan preview & replay, shared memory, external agents |
| Operate | Observability, CLI, production examples |
Contributing
Issues and PRs are welcome. For production examples, follow the acceptance criteria; for code changes, see the contribution guide.
Contributors
Contributor credits by area
Framework features
- @ibrahimkzmv (token budget, context strategy, dependency-scoped context, tool presets, glob, MCP integration, configurable coordinator, CLI, dashboard rendering, trace event types)
- @apollo-mg (context compaction fix, sampling parameters)
- @tizerluo (onPlanReady, onAgentStream)
- @CodingBangboo (planOnly mode)
- @Xin-Mai (output schema validation)
- @JasonOA888 (AbortSignal support)
- @EchoOfZion (coordinator skip for simple goals)
- voidborne-d (OpenAI mixed-content fix, text-tool-extractor depth fix)
- @NamelessNATM (agent delegation base implementation)
- @MyPrototypeWhat (reasoning blocks, reasoning_effort, sampling parity, trace input/output)
- @SiMinus (streaming reasoning events)
- @matthewYang08 (OpenAI reasoning-to-text fallback)
- @dvirarad (OpenAI-family adapter hardening)
- @cat0825 (model routing policy, plan replay, structured shared-memory handoff)
- @mvanhorn (checkpoint & resume)
- @lesbass (run-level metrics rollup on
TeamRunResult) - @tlysanhuo (trace span parent linkage)
- @LambIessz (orchestrator cost budget, MessageBus persistence in checkpoints, retryable route fallback)
- @Bobuyoucrypto (Windows bash timeout process-tree kill)
Provider integrations
- @ibrahimkzmv (Gemini)
- @hkalex (DeepSeek, MiniMax)
- @marceloceccon (Grok)
- @Klarline (Azure OpenAI)
- @Deathwing (GitHub Copilot)
- @JackChiang233 (Qiniu)
- @CodingBangboo (AWS Bedrock)
- @kidoom (MiMo, Doubao)
- @KaitlynFeng (Hunyuan)
- @octo-patch (MiniMax-M3 model upgrade)
Examples & cookbook
- @mvanhorn (research aggregation, code review, meeting summarizer, Groq example, Mistral example)
- @Kinoo0 (code review upgrade)
- @Optimisttt (research aggregation upgrade)
- @Agentscreator (Engram memory integration)
- @fault-segment (contract-review DAG)
- @HuXiangyu123 (cost-tiered example)
- @zouhh22333-beep (translation/backtranslation)
- @pei-pei45 (competitive monitoring)
- @mmjwxbc (interview simulator)
- @binghuaren96 (incident postmortem DAG)
- @DaiMao-UT (paper replication triage)
- @oooooowoooooo (rare disease information triage)
- @CodingBangboo (Express customer support pipeline)
- @nuthalapativarun (Doubao and Zhipu provider examples)
- @goodneamtakenbydogs (Moonshot and Qwen provider examples)
- @suans4746-del (narrative puzzle hint arbitration)
- @gregkonush (Bilig WorkPaper MCP integration)
Docs & tests
- @tmchow (llama.cpp docs)
- @kenrogers (OpenRouter docs)
- @jadegold55 (LLM adapter test coverage)
- @btroops (DeepSeek tool-calling tests)
- @nuthalapativarun (context-management docs)
- @Oxygen56 (errors.ts tests, provider docs for Grok/DeepSeek/Doubao)
- @RheagalFire (LiteLLM gateway docs)
License
MIT