mirror of
https://github.com/onyx-dot-app/onyx.git
synced 2026-10-22 03:14:06 -05:00
feat(indexing): add new embedding models and upgrade-only model selection (#15351)
## Description
Add 11 selectable embedding models and an upgrade-only model picker.
Fresh self-hosted installs use Granite. Existing deployments keep their
stored model until an admin starts a re-index. On startup, the API
server waits until the model server can embed with the self-hosted model
in use. If that model is not in its cache, the model server downloads it
first.
| Type | Model | Output dimensions |
| --- | --- | --- |
| Self-hosted | `ibm-granite/granite-embedding-97m-multilingual-r2`
(default, in the image) | 384 |
| Self-hosted | `voyageai/voyage-4-nano` | 2048 |
| Self-hosted | `nvidia/Nemotron-3-Embed-1B-BF16` | 2048 |
| Cohere | `embed-v5.0-pro`, `embed-v5.0-fast` | 2048 |
| Google | `gemini-embedding-2` | 3072 |
| OpenAI | `text-embedding-3-large`, `text-embedding-3-small` | 3072 /
1536 |
| Voyage | `voyage-4-large`, `voyage-4`, `voyage-4-lite` (added on main)
| 1024 |
The 16 older models are now **legacy**: nomic, E5, GTE-small, Cohere
v3/v4, Voyage v2 and older Gemini/Vertex models. Existing indexes on
them keep working. The API refuses a legacy model as a new target, but a
re-index with the current model is still allowed.
## Size of this PR
After review, I removed the parts that the feature does not need. The
behavior stays the same. The diff against `main` went from **80 files,
+9,855 / −504** to **69 files, +4,740 / −467**.
| Area | Files | Added | Removed |
| --- | --- | --- | --- |
| Backend source | 16 | 1,004 | 96 |
| Backend unit tests and test managers | 16 | 1,568 | 32 |
| Backend manual suites (opt-in, not in CI) | 7 | 617 | 0 |
| Web source | 6 | 617 | 255 |
| Web tests | 5 | 630 | 1 |
| Web messages (9 locales) | 9 | 225 | 72 |
| Deployment, CI and feature map | 10 | 79 | 11 |
The feature map (`.agents/feature-map/`) now describes the new selection
rules.
Removed:
- **The branch's own cloud probe.** All selectable cloud models now use
main's probe (`probe_embedding_dimension`), which Bifrost already used.
It now also sends the stored Vertex configuration, the Azure API version
and the deployment name. Before this change, the branch's probe ignored
the Vertex configuration, so a Google provider that uses Workload
Identity could not switch to `gemini-embedding-2`.
- **The Vertex fan-out.** Main already sends `gemini-embedding-2` texts
one at a time. The Vertex code is now the same as on main.
- **The `expected_dim` path** in the model-server loader, and the
startup warning for custom models with registry names. These protected
only one rare case; see **Custom models with a registry name** in [Known
limits](#known-limits).
- **The UI fallback** that tested a new key with a default model when
the key failed with the current model. The credential test now embeds
with the staged or current model of that provider. Only a provider with
neither uses its first selectable model.
- **Picker cards for current and staged bring-your-own models.** Main
does not show them either. The current model shows in the summary at the
top of the page.
- **Shared gates and fixtures for the manual suites.** Each suite has
one gate env var.
- **The screenshots in `docs/assets`.** The images below come from an
earlier commit of this PR.
- **Tests for removed code, and repeated test cases.** The unit tests
went from 3,842 to 2,667 lines.
### CPU speed and memory cards
All nine locales show these planning estimates:
| Model | Card speed | Recommended CPU RAM |
| --- | --- | --- |
| Granite 97M | Up to **200 docs / min / CPU core** | **4 GB** per model
server |
| Voyage 4 Nano | Up to **50 docs / min / CPU core** | **4 GB** per
model server |
| Nemotron 3 Embed 1B BF16 | Up to **5 docs / min / CPU core** | **8
GB** per model server |
Nemotron says **GPU recommended**. It runs on CPU too, but slowly. The
cards tell the admin that speed changes with the hardware and the
document size. The RAM value is for one loaded model. A re-index and the
rest of Onyx need more memory.
These values are planning estimates, not guarantees. The Nemotron
per-core value is an extrapolation from an earlier multi-thread run.
Document counts depend on chunking, and throughput does not always scale
linearly with cores. The RAM values are recommendations, not measured
minimum or peak values.
## Implementation
- **Registry.** `shared_configs/embedding_models.py` defines the model
names, dimensions, prefixes, normalization, status and pinned Hugging
Face revisions. A parity test compares it with the web registry.
- **Upgrade-only guard.** `_check_embedding_model_target` runs in
`set-new-search-settings`:
- The current model can always re-index, legacy models too. The
dimension must stay the same. In Onyx Cloud, `reduced_dimension` must
also stay the same, because tenants share the index of a model.
- A selectable model must use the registry settings (dimension,
normalization, prefixes).
- Other OpenAI, Cohere, Google and Voyage models, and legacy self-hosted
models, get `INVALID_INPUT`. The error lists the selectable models.
- Custom Hugging Face models, LiteLLM, Azure and Bifrost stay open.
- A self-hosted model gets `INVALID_INPUT` for a new
`reduced_dimension`, because the model server ignores it. A re-index
keeps a stored value.
- **Cloud probe.** Before a re-index to a selectable cloud model, the
API embeds a test text with the stored credentials and checks the
dimension. A bad key, region or model ID fails before indexing starts.
The probe runs before the PRESENT row lock, with no open transaction, as
main's Bifrost probe does.
- **Self-hosted loads.** New models load at a pinned revision with
`trust_remote_code=False`, a dimension check and a finite-vector check.
CPU-only hosts load FP32. CUDA and MPS keep the checkpoint dtype. Legacy
and custom models keep main's `SentenceTransformer` call, so their
vectors do not change.
- **Voyage 4 Nano.** An Onyx loader adds bidirectional attention and the
learned 1024-to-2048 projection. The generic loader with remote code
disabled does not apply them.
- **Model server.** All models load from the cache first, then from
Hugging Face. Loads run off the event loop on two load workers, so at
most two sets of weights (PRESENT and FUTURE) load at the same time.
Registry models get 32 tokens of headroom for the prefix. The RoPE
pre-warm now runs again only for a longer context. On main, it ran for
every change of context length.
- **Image.** The model-server image bundles pinned Granite. It no longer
bundles nomic: nomic downloads on first use. The startup cache merge
keeps the models that a volume already has.
- **Picker.** Self-hosted and cloud groups, a Legacy label on the
current legacy model, and an **Advanced** section for custom Hugging
Face models, LiteLLM, Azure and Bifrost. A staged custom model keeps the
custom provider, also when its name is the same as a registry model.
- **Error detail.** `EmbeddingModel` now keeps the model server's error
detail. Before, every HTTP failure showed "HTTP error occurred -
response is None".
### Startup wait for self-hosted models
On startup, the API server waits until the inference model server can
embed with the current self-hosted model. The model server loads the
model on the first request, and downloads it first if it is not cached.
Example: a deployment that upgrades while it uses nomic, which the new
image does not bundle.
- The API server logs the wait, each failed attempt with its cause, and
the time when the model is ready. The model server logs a download.
- `LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT` sets the wait (default 1800
seconds). When the wait runs out, startup fails. The error names the
model server, the model, the last error and the fix. `0` disables the
wait.
- The check request runs in a daemon thread. A request that still waits
at the deadline (for example, during a slow download) therefore does not
keep the failed process alive. Before this fix, the process stayed alive
until the model server read timeout (600 s by default).
- There is no wait in Onyx Lite (`DISABLE_VECTOR_DB`), for cloud models,
in multi-tenant deployments, in integration tests, or with
`DISABLE_MODEL_SERVER`.
- The wait uses the existing embed endpoint, so it also works with an
older model server during a rolling upgrade.
- This replaces the startup call to `warm_up_bi_encoder`. `SKIP_WARM_UP`
(default `true`) skipped that call, so it did not run by default.
- Only the inference model server is checked. The indexing model server
still loads a model on first use. In Compose, the API server does not
know the host of the indexing model server.
- `env.template` and Helm `values.yaml` document the setting. The Helm
chart is now 0.9.19.
Live test at commit `0eb5881da9`, with an existing nomic deployment on a
local stack. The size reduction did not change the wait:
| Case | Result |
| --- | --- |
| nomic not cached, model server online | The model server downloaded
nomic (523 MB). Startup continued after 19 s. |
| nomic cached | Ready in 3 s, with no download. |
| Model server starts after the API server | A warning every 10 s, then
ready at 33 s. |
| nomic not cached, no internet access | Each warning showed the cause
("not in the model server's Hugging Face cache and could not be
downloaded"). Startup failed at the timeout, and the process exited. |
| Onyx Lite, no model server | No wait. |
| Timeout `0` | No wait. The model loads on first use. |
## Upgrade notes
- **Offline deployments that use nomic.** The new image does not bundle
nomic. A deployment with no internet access and no kept model cache
cannot download it. The API server then fails at startup with a clear
error, instead of starting with a search that cannot embed queries.
Before you upgrade such a deployment, add the current model to the model
server's Hugging Face cache, or keep the cache on a volume. Helm has no
cache volume by default. This PR has no schema migration, so a return to
the previous image works while the current model stays the same.
- **Helm.** The chart has no Hugging Face cache volume for the model
servers, so a model that the image does not bundle (nomic, Voyage 4
Nano, Nemotron) downloads again on every pod start. `values.yaml`
documents an opt-in volume with the existing
`inferenceCapability.volumes` and `volumeMounts` values. A default
volume is not added: a ReadWriteOnce claim hangs rolling updates across
nodes, breaks `replicaCount` above 1, and needs a StorageClass. The
bundled Granite works with or without a volume.
- **API probes.** `/health` answers only after the startup wait. A
liveness probe needs a startup probe that allows the migrations plus
`LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT`. The api probe example in
`values.yaml` shows one.
- **Multi-tenant template snapshots.** Migration `dbaa756c2ccf` seeds a
search settings row with `DOCUMENT_ENCODER_MODEL`. When that variable is
empty, the seed is now Granite, not nomic. If a deploy runs
`alembic/check_tenant_snapshot.py`, it reports a difference in
`search_settings` until the template snapshots are built again
(`--snapshot-template`). To keep the seed the same as on main, set
`DOCUMENT_ENCODER_MODEL=nomic-ai/nomic-embed-text-v1`.
- **No return to a legacy model.** After a switch, the old index is
cleaned up and the upgrade-only rule blocks a return to a legacy model.
Keep a compatible backup before you switch.
## Audit: retries and failures
| Layer | Behavior | Compared with main |
| --- | --- | --- |
| Local encode | Catches `RuntimeError`, waits 0.1 seconds, then tries
again: **up to four encode attempts**. It also retries errors that do
not go away, such as OOM. | Unchanged. |
| API to model server | Passage requests retry request failures three
times with five-second waits. HTTP 429 allows ten attempts with
ten-second waits. Connect/read timeouts are 30/600 seconds. Query
requests do not get these retries. | Unchanged. |
| Document indexing | A failed batch falls back to one document at a
time after a two-second delay. Failures are recorded, and the other
documents continue. | Unchanged. |
| Cloud embedding | Authentication errors are separate. Errors mapped to
`RuntimeError` get exponential backoff with jitter: eight attempts in
indexing-only mode, else two. | Unchanged. `gemini-embedding-2` sends
one text per request, in sequence, as on main. |
| Model loading | Cache first, then online. A partial cache falls back
online. A failed load is not cached, so a later request can try again.
Requests for the same model and context length share one load job. |
Cache-first lookup is new for all models. Registry models add pinned
revisions and checks. |
Model downloads run off the event loop. When a waiting request is
cancelled, the shared load continues. A load job has no deadline, so it
can continue after an HTTP timeout.
One gap from main remains: the response JSON is parsed outside the retry
wrapper. See [local
retries](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/model_server/encoders.py#L157),
[request
retries](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/onyx/natural_language_processing/search_nlp_models.py#L1322),
and [cloud
retries](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/onyx/natural_language_processing/search_nlp_models.py#L942).
## Audit: migration and cancellation
There is **no schema migration, and no automatic change to existing
embedding settings**. Granite is the fresh-install default. Cloud tenant
provisioning still uses Cohere v3. Existing stored prefixes and
dimensions stay in use.
1. The API checks the target with the upgrade-only guard.
2. A new cloud target embeds a test text with the stored credentials
before the migration. The probe checks the dimension. It runs before the
PRESENT row lock.
3. The API locks PRESENT and refuses overlapping migrations. It also
refuses an index name that is live or still waiting for cleanup. FUTURE,
the first work and the cleanup consent commit together.
4. The existing port flow reads stored documents from the current index,
embeds them again and writes the new index. Connectors do not fetch
again. All-connectors mode includes paused connectors. Active-only mode
leaves them out and needs consent for the data that it leaves out. User
files are included.
5. Normal promotion waits for successful required ports, no open writers
or sync work, and a sample check in the new index. A failed or paused
required port blocks promotion. The sample check does not check the full
corpus.
6. Port batches retry up to five times. The cursor moves after a
successful batch. The first watchdog retry is immediate. Repeated
failures at the same cursor use exponential backoff from 30 seconds, up
to one hour. Five failures in sequence at that cursor pause the unit. An
operator can resume it.
7. A cancel of FUTURE keeps PRESENT active, stops port work at a batch
boundary, and removes the partial index after writers stop. **Instant
switch promotes first**, so search is not complete during backfill, and
this cancel path is not available.
See [migration
endpoint](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/onyx/server/manage/search_settings.py#L140),
[upgrade-only
guard](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/onyx/server/manage/search_settings.py#L456),
[swap
gates](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/onyx/db/swap_index.py#L367),
and
[cancellation](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/onyx/server/manage/search_settings.py#L668).
## Known limits
- **Model memory.** Two load workers limit how many models load at the
same time. Loaded models are not evicted (as on main), so the old and
new models stay in memory during a switch. Helm's default memory limit
for the indexing model server is **6 GiB**, below the **8 GB** that the
Nemotron card recommends. See [load
executor](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/backend/model_server/encoders.py#L35)
and [Helm
limits](https://github.com/onyx-dot-app/onyx/blob/4784da70697fb59261f43088383d85671544ec98/deployment/helm/charts/onyx/values.yaml#L309).
- **Legacy models are not selectable.** This is by design. The current
legacy model stays visible and can re-index. After a switch, the
standard flow cannot select it again.
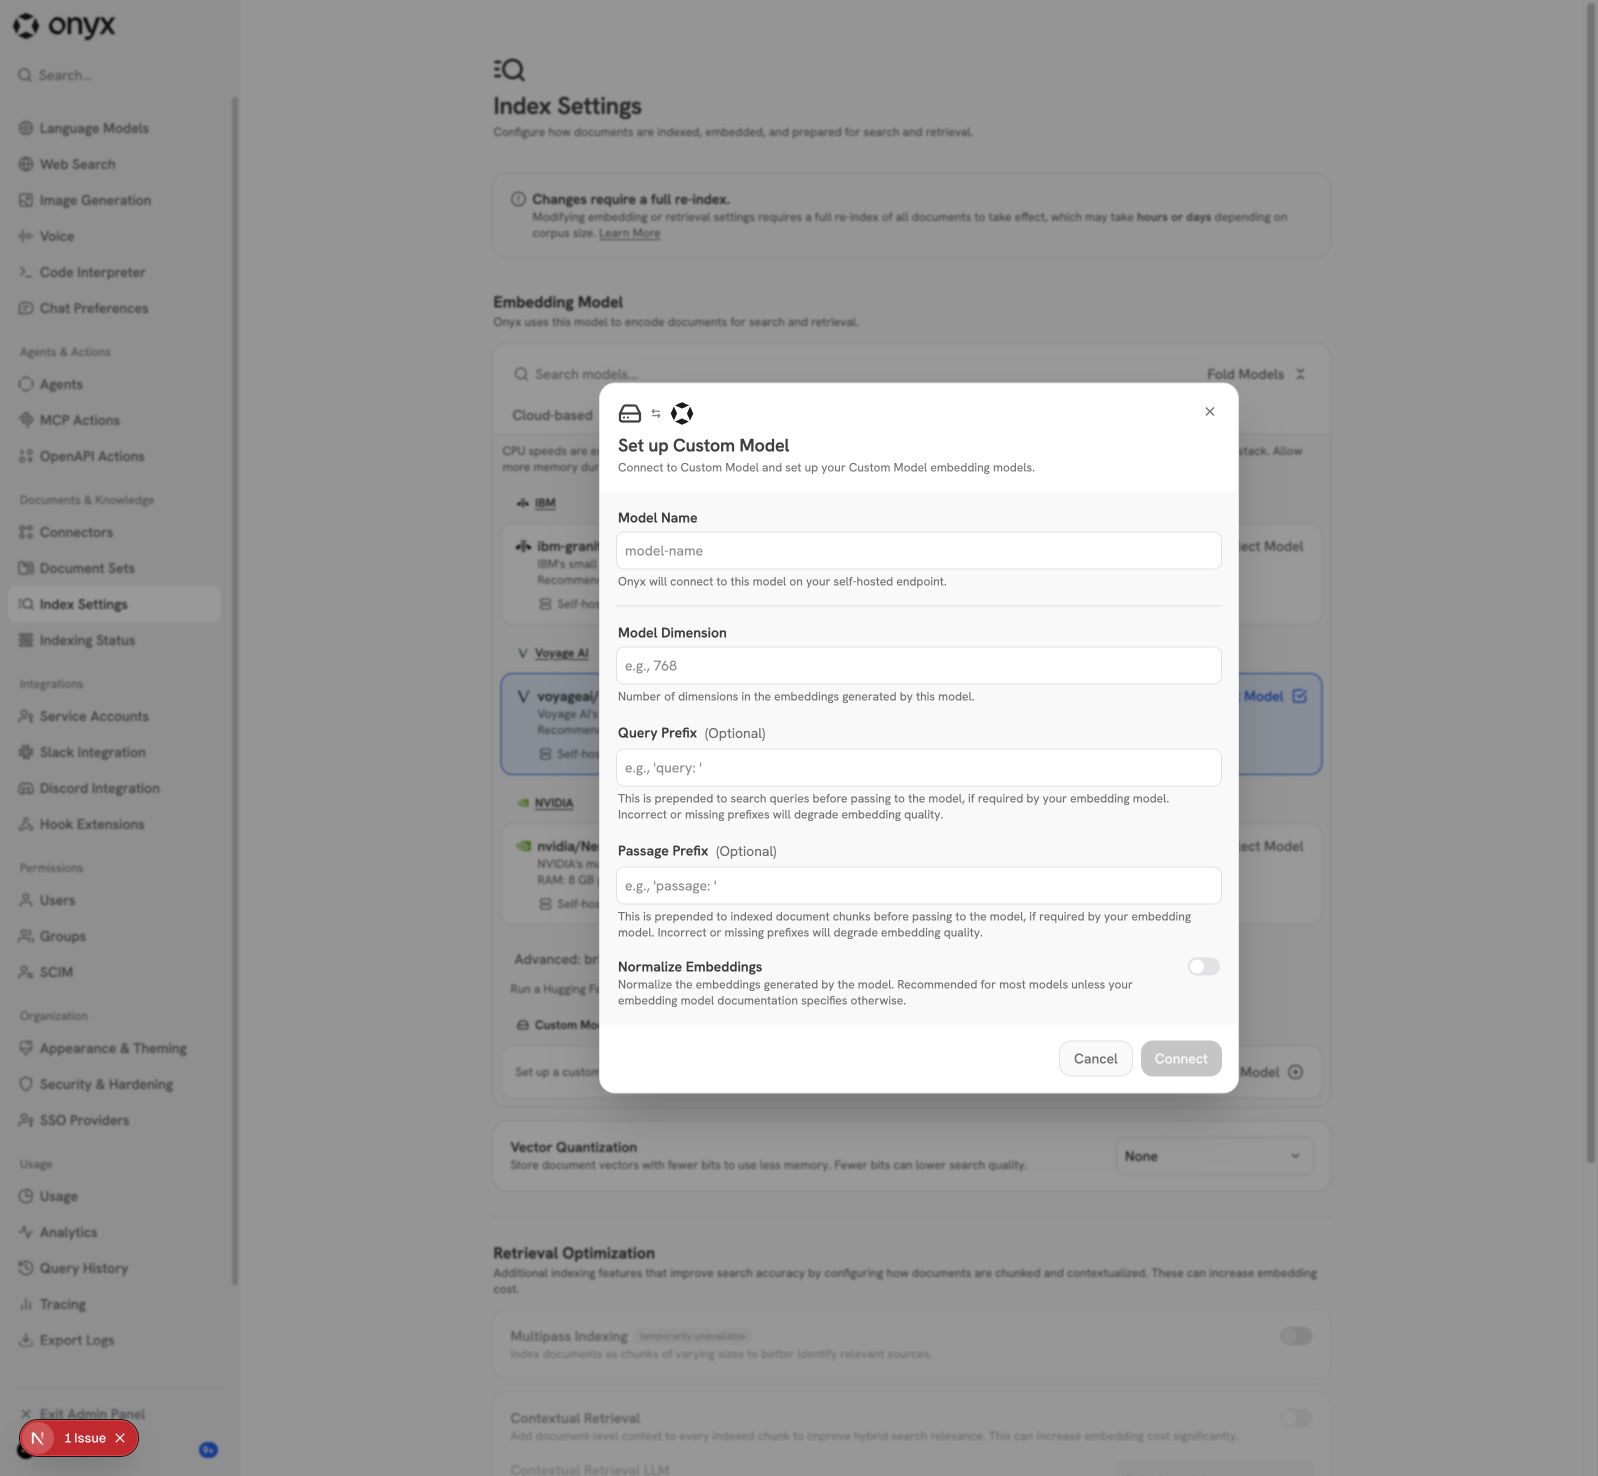
- **Bring-your-own options are under Advanced.** Unknown model names for
the built-in OpenAI, Cohere, Google and Voyage providers get
`INVALID_INPUT`. LiteLLM, Azure, Bifrost and custom models stay open.
- **The cloud probe reads the provider settings once.** If an admin
changes the key or region while a re-index starts, the probe can use the
old values. A key can also change at any time during a re-index, so no
preflight check can guarantee the key that the workers use. Indexing
failures then show in the re-index status, and the admin can cancel.
- **Custom models with a registry name.** Before this PR, an admin could
add a registry model name, such as `voyageai/voyage-4-nano`, as a custom
model. The model server now loads that name as the registry model. For
`voyage-4-nano`, the vectors then have 2048 dimensions, not 1024, so a
1024-dimension index fails with an error. Re-index to the registry model
to fix it. For the other registry models, a generic load gives the same
dimension.
- **Shared `max_seq_length`.** The model server changes `max_seq_length`
on the shared model for each request. Two requests with different
context lengths can overlap. This is the same on main. This PR does not
change it.
- **Voyage 4 Nano depends on the Transformers and SentenceTransformers
layout.** Run the real-weight suite when those dependencies change.
- **No reduced dimensions for Cohere v5 and the self-hosted models.**
Cloud provisioning stays on Cohere v3. These are follow-ups.
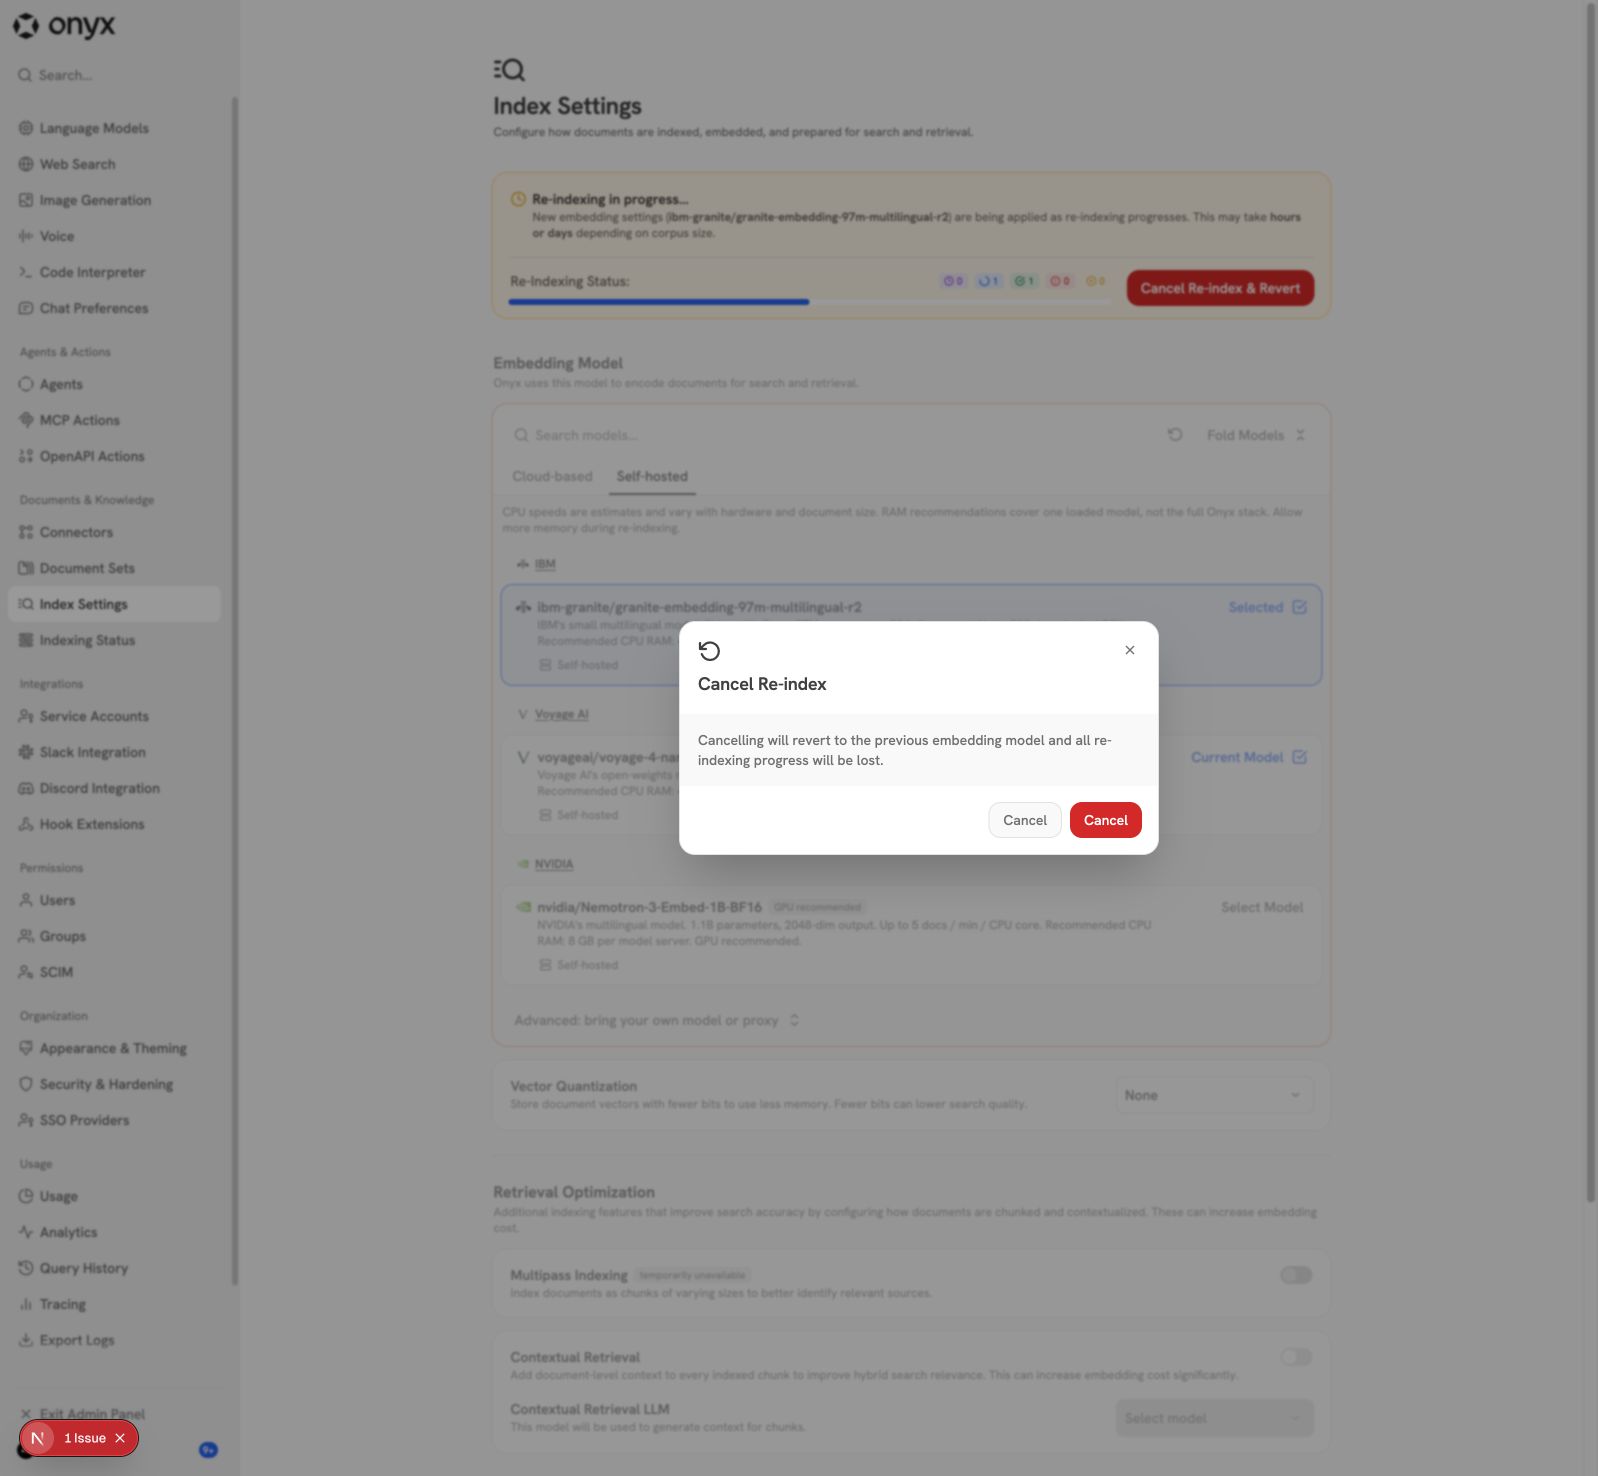
- **The cancel dialog has two buttons labeled Cancel.** One closes the
dialog, the other cancels the re-index. This is the same on main.
- The branch is rebased onto `main` at `ad9c0030e9`. This PR does not
claim better retrieval quality.
## Validation for this update
- **Backend: 15,343 unit tests passed** before the review fixes. I left
out the EE license tests, because they write a key to a live Redis. `ty`
and pre-commit passed. After the review fixes and the merge of `main`,
the PR's backend unit tests passed again (199 tests). Pre-commit passed
on all 69 changed files.
- **Startup exit check:** a fake model server that never answers, with a
3 s wait and a 20 s read timeout. The wait raised at 3.3 s. The process
exited at 5 s with the fix, and at 22 s without it.
- **Web: type check, lint and 3,236 Jest tests (307 suites) passed.**
- **Self-hosted real-weight suite: 6 of 6 passed.** Golden scores and
the bidirectional-attention check for Granite, Voyage 4 Nano and
Nemotron.
- **Cloud live suite: `gemini-embedding-2` passed.**
- **End to end on a local stack with branch code: 11 of 11 passed.** The
API refused all 6 legacy self-hosted targets and accepted a same-model
re-index. Then the stack switched to Granite, Voyage 4 Nano, Nemotron
and `gemini-embedding-2`, in sequence. After each switch, a pure vector
search found each of 5 seeded facts first.
- **Not run for this update: Cohere, OpenAI and Voyage cloud tests.** A
TLS proxy on the test network blocked `api.cohere.com` and
`api.openai.com`. The probe then refused the switch with `400`, as
designed. These tests passed on an earlier commit of this PR, and the
probe that they use is main's probe. I had no Voyage key.
- **CI:** at `9321cb51db`, every check passed except the Dependency
Audit: Playwright, integration, acceptance, database,
external-dependency unit, Jest and quality checks. The audit fails on
open Dependabot alerts for Pillow and certifi in other manifests
(`loadtest/uv.lock` and the Craft sandbox requirements). Other open PRs
fail the same way at the moment.
- **Not run for this update:** speed benchmarks.
<details>
<summary>Earlier validation in this PR, not run again for this
update</summary>
- 28 real-weight tests and 24 cloud tests passed.
- End-to-end switches to all eight selectable models of that time
passed. The API refused all 16 legacy targets.
- Legacy-upgrade equivalence, Docker cache keeping and multi-tenant
provisioning checks passed.
- 11,521 backend unit tests passed. 10 EE license failures also occurred
on main.
</details>
## Voyage retrieval-quality check — October 14, 2026
The branch's Voyage loader passed a local EnterpriseRAG-Bench loading
check. **Vector-only mean document Recall@10 was 91.85%**, above the
proposed 50% threshold. This supports a correct load. It does not prove
numerical equality with the upstream implementation.
The corpus had **5,000 documents**: all **722 labeled supporting
documents** and **4,278 random distractors**, sampled with seed
`20261013`. All **470 questions with document labels** were scored. The
30 questions with no labels were left out. No question or answer text
went into the corpus.
| Retrieval mode | Mean Recall@1 | Mean Recall@5 | Mean Recall@10 | Mean
Recall@20 |
| --- | --- | --- | --- | --- |
| Onyx content-vector-only retrieval | 66.13% | 87.37% | **91.85%** |
94.16% |
| Onyx hybrid search API | 75.85% | 93.32% | **96.37%** | 97.70% |
Recall is the fraction of labeled documents found for each question,
averaged over the questions. Rankings use the first hit of each
document. Vector-only hit rate@10 (at least one relevant document) was
94.26%. That is a different metric from recall.
| Question category | Questions | Vector-only Recall@10 | Hybrid
Recall@10 |
| --- | --- | --- | --- |
| Basic | 175 | 97.71% | 99.43% |
| Semantic | 125 | 84.80% | 92.80% |
| Intra-document reasoning | 40 | 97.50% | 100.00% |
| Project related | 40 | 86.43% | 95.35% |
| Constrained | 30 | 98.33% | 98.33% |
| Conflicting information | 20 | 90.00% | 97.50% |
| Completeness | 20 | 68.03% | 79.03% |
| Miscellaneous | 20 | 100.00% | 100.00% |
The check used CPU FP32, 2048-dimensional normalized vectors, and the
registry's query and document prefixes. MPS and CUDA were off. There was
no query expansion, reranking, or LLM document selection. All 5,000
document IDs matched the saved manifest, with 15,612 indexed chunks. All
query vectors were finite and had unit length. The last indexing attempt
had no document errors. Two earlier attempts stopped after
stale-heartbeat timeouts and continued from saved progress.
**Search path:** on this OpenSearch branch, `hybrid_alpha=1` still runs
hybrid retrieval, so the API result includes keyword scores. The
vector-only result calls `OpenSearchDocumentIndex.semantic_retrieval`
directly, with content vectors only. Keyword matches therefore cannot
hide a broken embedding loader in that result.
**Scope:** this is an easier 5,000-document subset that contains all
gold documents, not the full 511,958-document benchmark. Do not compare
these values with full-corpus leaderboard scores. No loader or ranking
code changed to get these results.
Revisions: Onyx `913bfa8d7a32c9cda340df92f42d0f706fd424c2`;
EnterpriseRAG-Bench `d36685e273713975ee20299bbf1ab64165575b3c`; Voyage
`67fabc9bef010dabc5f6024aa1b1b6b93410426f`. Runtime: PyTorch 2.9.1,
Transformers 5.14.1, SentenceTransformers 5.4.1.
## UI screenshots
From the local development stack at commit `98bfc70080`, before the size
reduction. These show the real flow, not mockups.
<details open>
<summary>Self-hosted cards and current model</summary>
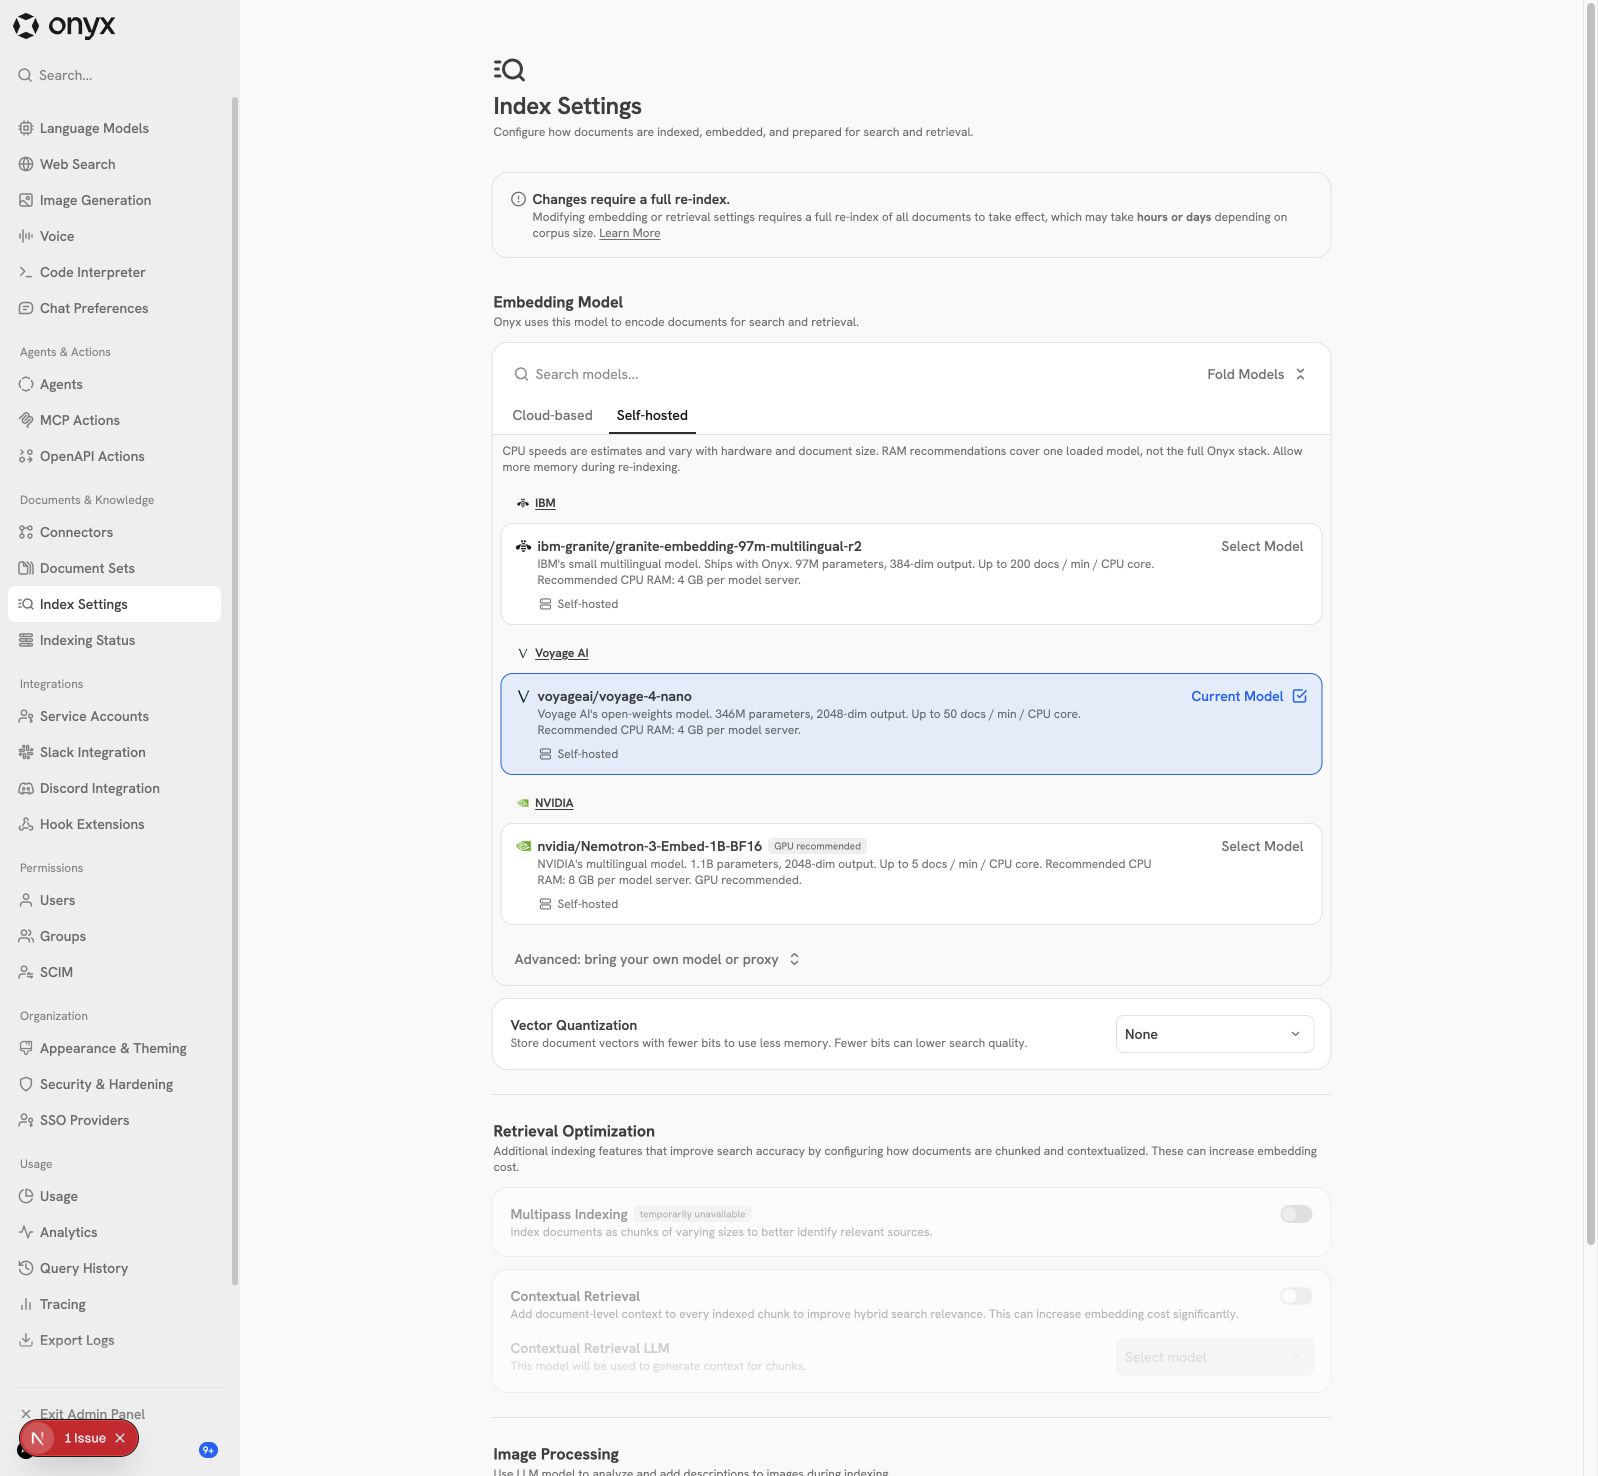
</details>
<details>
<summary>Cloud model catalog</summary>
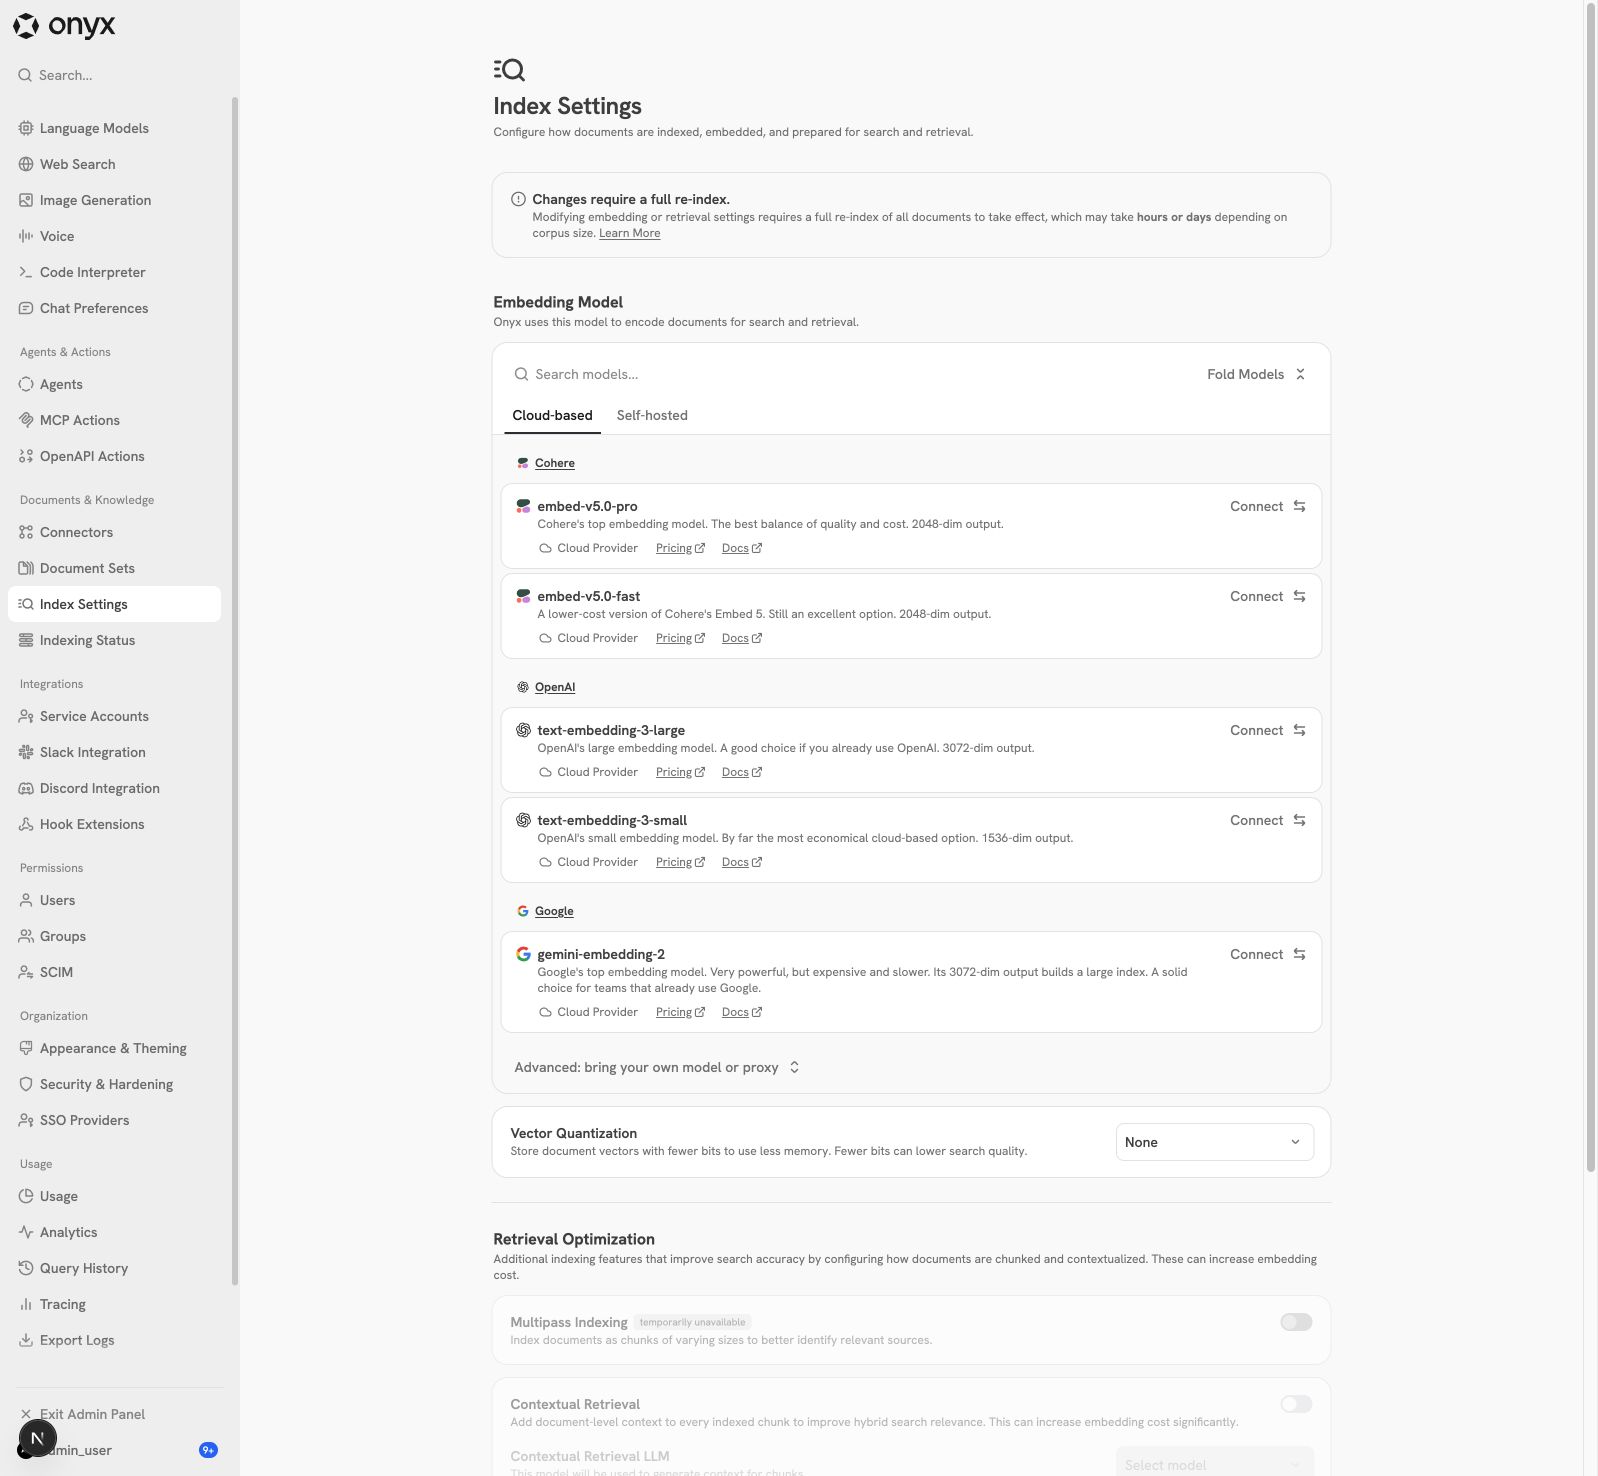
</details>
<details>
<summary>Staged Granite change and migration strategy</summary>
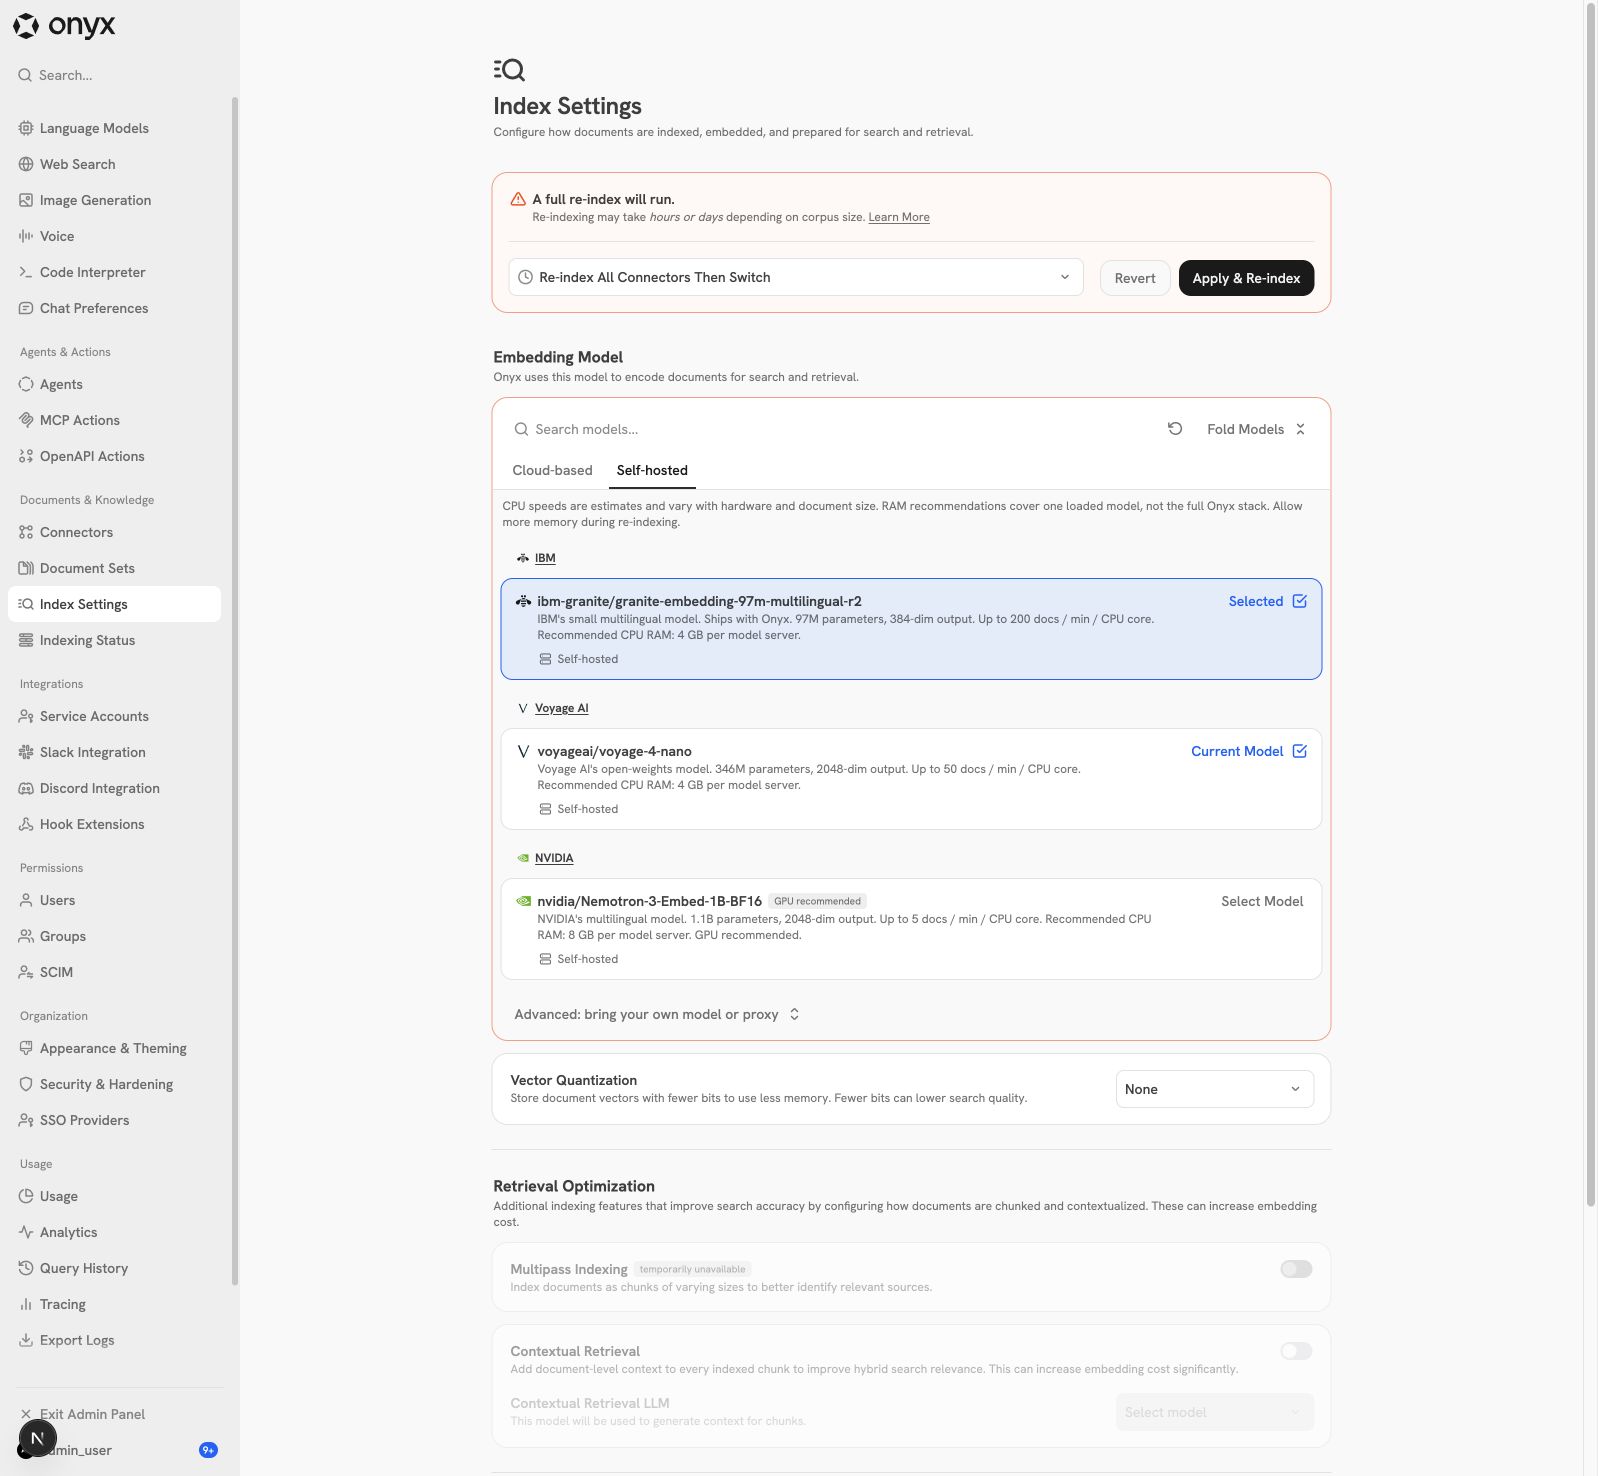
</details>
<details>
<summary>Re-index in progress</summary>
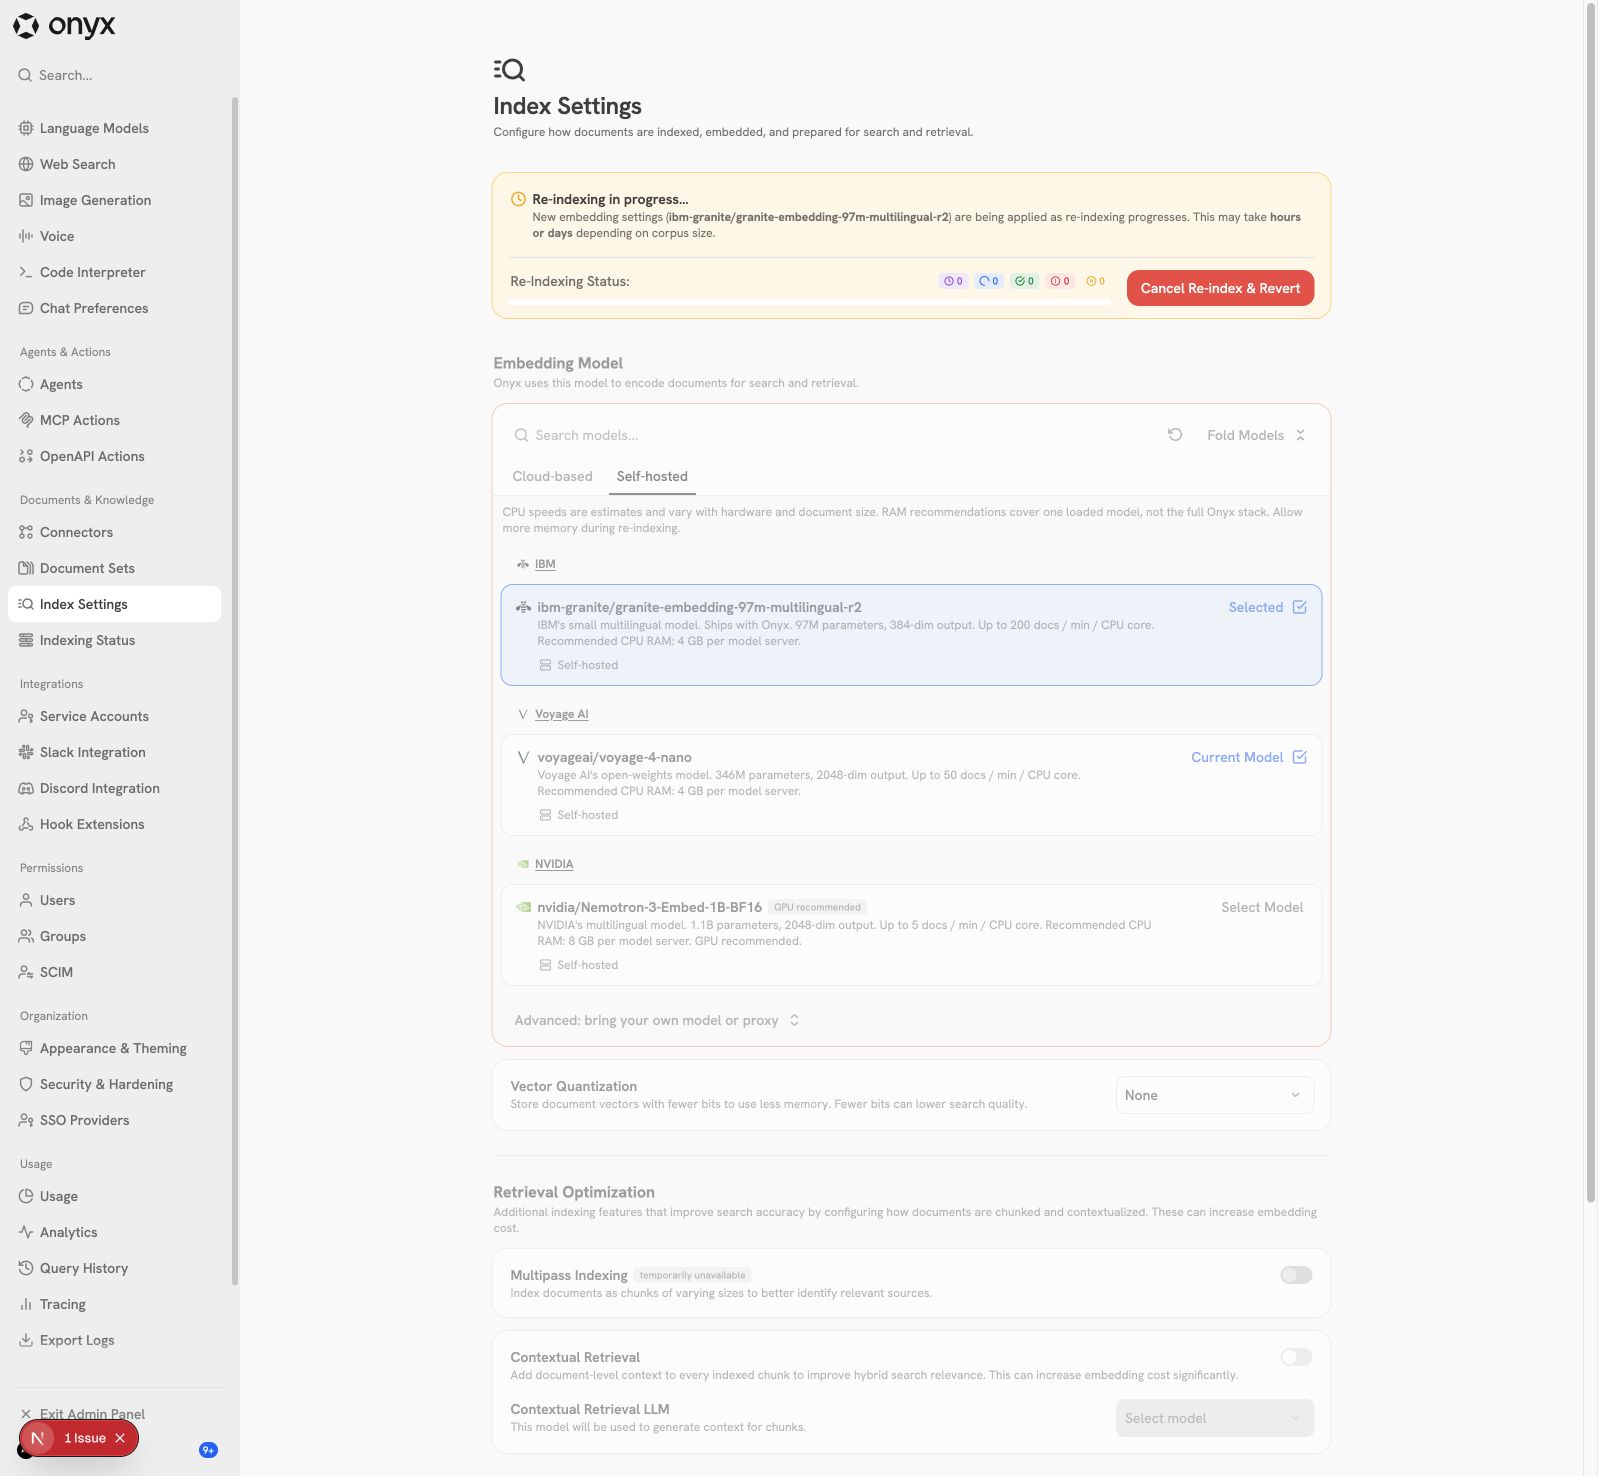
</details>
<details>
<summary>Cancel confirmation</summary>
</details>
<details>
<summary>Advanced custom model setup</summary>
</details>
## Additional Options
- [ ] [Optional] Please cherry-pick this PR to the latest release
version.
- [ ] [Optional] Override Linear Check
🤖 Generated with [Claude Code](https://claude.com/claude-code)
---------
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>






This commit is contained in:
 Yuhong SunandClaude Opus 5.5 authored and GitHub committed
1 parent
2f9ed2517e
commit
b86caa7332
69 files changed
+4779
-481
No files matched your search
@@ -66,6 +66,7 @@ here. Read the component that documents the setting in its env table.
|
||||
| `backend/onyx/natural_language_processing/` | document-index, internal-search |
|
||||
| `backend/onyx/db/search_settings.py`, `db/swap_index.py` | document-index |
|
||||
| `backend/onyx/server/manage/search_settings.py`, `server/manage/embedding/` | document-index |
|
||||
| `backend/shared_configs/embedding_models.py`, `backend/model_server/embedding_model_loader.py`, `backend/model_server/voyage_nano.py` | document-index |
|
||||
| `backend/onyx/server/features/search/`, `server/query_and_chat/query_backend.py`, `backend/ee/onyx/server/query_and_chat/search_backend.py`, `backend/ee/onyx/search/` | internal-search |
|
||||
| `backend/ee/onyx/server/query_and_chat/token_limit.py` | rate-and-usage-limits |
|
||||
| `backend/onyx/access/`, `backend/ee/onyx/access/`, `backend/onyx/db/document_access.py`, `db/permissions.py`, `db/scoped_permissions.py` | access-control |
|
||||
|
||||
@@ -14,7 +14,9 @@
|
||||
`port_copy.py`, `string_filtering.py`, `cc_pair_ids_backfill.py`),
|
||||
`backend/onyx/db/search_settings.py`, `swap_index.py`,
|
||||
`backend/onyx/natural_language_processing/search_nlp_models.py`,
|
||||
`backend/onyx/server/manage/search_settings.py`, `backend/onyx/server/manage/embedding/`
|
||||
`backend/onyx/server/manage/search_settings.py`, `backend/onyx/server/manage/embedding/`,
|
||||
`backend/shared_configs/embedding_models.py`, `backend/model_server/embedding_model_loader.py`,
|
||||
`backend/model_server/voyage_nano.py`
|
||||
|
||||
**Does not own:** the retrieval orchestration that decides what to search and how to
|
||||
merge results across sources ([[internal-search]]), or the chunking/embedding pipeline
|
||||
@@ -40,9 +42,13 @@ in the banner, but cannot trigger a popup. See `backend/onyx/document_index/open
|
||||
for thresholds, timeouts, and recovery behavior.
|
||||
|
||||
An admin experiences it directly on the embedding-model page. They pick a new
|
||||
embedding model (self-hosted, Cohere, OpenAI, Azure, Bedrock, Vertex, LiteLLM, Bifrost,
|
||||
and more), optionally run a sample embedding test (a fixed test string, not a document), and start a re-index. Bifrost
|
||||
always runs the test, because its model ID is free text. From that point,
|
||||
embedding model and start a re-index. The picker lists only the selectable models of
|
||||
the registry (self-hosted Granite, Voyage 4 Nano and Nemotron; Cohere, OpenAI, Google
|
||||
and Voyage cloud models). Custom Hugging Face models, LiteLLM, Azure and Bifrost are in
|
||||
a collapsed Advanced section. A legacy model (for example nomic, E5, Cohere v3) shows
|
||||
only while it is the current model. It can re-index, but it cannot be chosen as a new
|
||||
target. Before the re-index starts, the API embeds a fixed test string with the stored
|
||||
provider settings for Bifrost and for every selectable cloud model. From that point,
|
||||
Onyx builds a second, parallel index in the background using the new model while the
|
||||
old index keeps serving live search. A progress view shows re-index status and errors.
|
||||
When indexing catches up (the exact criterion depends on the switchover type chosen),
|
||||
@@ -64,7 +70,7 @@ dropped the migration tables, and #15336 removed Vespa and the retrieval toggle.
|
||||
|---|---|---|---|
|
||||
| GET | `/manage/admin/opensearch-health` | `read_resource_health` | Cached resource pressure; requires `FULL_ADMIN_PANEL_ACCESS`. |
|
||||
| POST | `/manage/admin/opensearch-health/popup` | `claim_resource_popup` | Claims a tenant-scoped, per-admin 24-hour popup allowance in Redis. |
|
||||
| POST | `/search-settings/set-new-search-settings` | `set_new_search_settings` | Creates a FUTURE `SearchSettings` row, starts a re-index. Requires `FULL_ADMIN_PANEL_ACCESS`. For Bifrost it first embeds a test string and rejects a failed call or a dimension mismatch. |
|
||||
| POST | `/search-settings/set-new-search-settings` | `set_new_search_settings` | Creates a FUTURE `SearchSettings` row, starts a re-index. Requires `FULL_ADMIN_PANEL_ACCESS`. For Bifrost and every selectable cloud model, it first embeds a test string with the stored provider settings (`_validate_cloud_embedding_model`) and rejects a failed call or a dimension mismatch. `_check_embedding_model_target` then refuses a legacy model or an unknown OpenAI, Cohere, Google or Voyage model as a new target with `INVALID_INPUT`. A re-index with the PRESENT model is allowed. |
|
||||
| POST | `/search-settings/cancel-new-embedding` | `cancel_new_embedding` | Cancels the in-flight FUTURE re-index. |
|
||||
| DELETE | `/search-settings/delete-search-settings` | | |
|
||||
| GET | `/search-settings/get-current-search-settings` | | The PRESENT row. |
|
||||
@@ -100,6 +106,7 @@ Per the frontend rule in `CLAUDE.md`, always call these through the web server
|
||||
| `OPENSEARCH_EXPLAIN_ENABLED` | false | Adds scoring breakdowns; documented as roughly 1000x slower for hybrid search in practice. |
|
||||
| `PIT_KEEP_ALIVE` | `"5m"` | Point-in-time lease used by the reindex port's consistent scan. |
|
||||
| `VERIFY_CREATE_OPENSEARCH_INDEX_ON_INIT_MT` | true | Whether multi-tenant cloud checks/creates the index on every `OpenSearchDocumentIndex` construction. |
|
||||
| `LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT` | 1800 | Seconds that API server startup (`setup.py:wait_for_local_embedding_model`) waits until the inference model server embeds with the PRESENT self-hosted model. The model server downloads the model first if it is not cached. Startup fails when the wait runs out. `0` disables the wait. There is no wait for cloud models, with `MULTI_TENANT`, `INTEGRATION_TESTS_MODE` or `DISABLE_MODEL_SERVER`. |
|
||||
|
||||
---
|
||||
|
||||
@@ -377,6 +384,17 @@ query-time embedding, pulling `model_name`, `normalize`, `query_prefix`,
|
||||
`reduced_dimension` straight off the `SearchSettings` row. Separate `server_host`
|
||||
values are used depending on whether the call is from indexing or inference.
|
||||
|
||||
The registry in `backend/shared_configs/embedding_models.py` lists each known model as
|
||||
SELECTABLE or LEGACY, with its dimension, prefixes, normalization and, for self-hosted
|
||||
models, a pinned Hugging Face revision. `web/src/lib/searchSettings/constants.ts` must
|
||||
match it (`backend/tests/unit/shared_configs/test_web_embedding_model_registry_parity.py`). On the model server,
|
||||
`model_server/embedding_model_loader.py` loads a self-hosted registry model at its pinned
|
||||
revision, in float32 on CPU-only hosts, and checks the output dimension.
|
||||
`voyageai/voyage-4-nano` also gets bidirectional attention and its 1024-to-2048
|
||||
projection (`model_server/voyage_nano.py`). Every other name keeps the plain
|
||||
`SentenceTransformer` call. All models load from the cache first, then from Hugging
|
||||
Face. The model-server image bundles only the default model, Granite.
|
||||
|
||||
`RerankingModel` (`search_nlp_models.py`) is a fully implemented class (local
|
||||
cross-encoder plus direct API paths for Cohere/Bedrock) with **no active call site**.
|
||||
Its only instantiation in the codebase is inside
|
||||
@@ -460,6 +478,7 @@ comment reads `# No longer used`. See §9.
|
||||
| changes hybrid weights or subqueries | run a retrieval-quality eval before shipping; the weights-sum-to-1.0 assert catches arithmetic mistakes but not quality regressions |
|
||||
| adds a filter | `_get_search_filters` and every one of its private helper functions that builds one clause; the hybrid, keyword, semantic, and random query builders all call the same function, so a filter added there applies everywhere automatically, but a filter added ad hoc to just one query builder will not |
|
||||
| changes `SearchSettings` | `create_search_settings`, `update_search_settings`, the reindex request models in `server/manage/search_settings.py`, and `EmbeddingModel.from_db_model` if the field feeds the embedder |
|
||||
| adds an embedding model or changes its registry entry | the web registry in `web/src/lib/searchSettings/constants.ts` (parity test), the card copy in every locale, `_check_embedding_model_target`, and for a new default the bake in `backend/Dockerfile.model_server`. Do not change the dimension or prefixes of a model that indexes already use. |
|
||||
| touches the swap state machine (`IndexModelStatus` or `IndexReclaimStatus`) | `swap_index.py:_perform_index_swap`, every `advance_to_*` helper's prior-state guard, and the reclaim beat task; a broken guard can double-delete or skip the soak window |
|
||||
| changes `get_default_document_index` or `OpenSearchIndexPair` fan-out rules | every caller, since most pass `None` as the secondary; a change to which calls reach the secondary affects the port backfill and swap-time deletes |
|
||||
|
||||
|
||||
@@ -312,8 +312,9 @@ Computed **at upload time**, before any chat turn runs:
|
||||
`natural_language_processing/utils.py:get_tokenizer(model_name, provider_type)`
|
||||
from the workspace's default LLM model
|
||||
(`db/llm.py:fetch_default_model(..., LLMModelFlowType.CHAT)`), falling back to
|
||||
`_get_default_tokenizer()` (`HuggingFaceTokenizer(DOCUMENT_ENCODER_MODEL)`)
|
||||
when the provider type is unrecognized. Text/document files are counted with
|
||||
`_get_default_tokenizer()` (`HuggingFaceTokenizer(DEFAULT_TOKENIZER_MODEL)`:
|
||||
the `DOCUMENT_ENCODER_MODEL` env var, else nomic, whose tokenizer the API image
|
||||
bakes) when the provider type is unrecognized. Text/document files are counted with
|
||||
`natural_language_processing/utils.py:count_tokens` against the extracted
|
||||
text. Images are **not** tokenized against real content; their count is a
|
||||
heuristic, `projects_file_utils.py:estimate_image_tokens_for_upload`, which
|
||||
|
||||
@@ -36,6 +36,7 @@ jobs:
|
||||
filters: |
|
||||
python:
|
||||
- 'backend/**'
|
||||
- 'web/src/lib/searchSettings/constants.ts'
|
||||
- '.agents/hooks/**'
|
||||
- 'pyproject.toml'
|
||||
- '.github/workflows/pr-python-tests.yml'
|
||||
|
||||
@@ -144,6 +144,12 @@ RUN ln -s /usr/local/bin/supervisord /usr/bin/supervisord && \
|
||||
RUN python -c "from tokenizers import Tokenizer; \
|
||||
Tokenizer.from_pretrained('nomic-ai/nomic-embed-text-v1')"
|
||||
|
||||
# Tokenizer of the default self-hosted embedding model (nomic above stays the
|
||||
# default tokenizer). The API server loads it at hf_revision from
|
||||
# shared_configs/embedding_models.py, so the revision must match.
|
||||
RUN python -c "from tokenizers import Tokenizer; \
|
||||
Tokenizer.from_pretrained('ibm-granite/granite-embedding-97m-multilingual-r2', revision='835ad14087e140460703cf0fae09f97d469d65c2')"
|
||||
|
||||
# Pre-downloading tiktoken for setups with limited egress
|
||||
RUN python -c "import tiktoken; \
|
||||
tiktoken.get_encoding('cl100k_base')"
|
||||
|
||||
@@ -55,10 +55,14 @@ RUN uv pip install --python /app/.venv/bin/python --no-cache-dir --no-deps --req
|
||||
-r /tmp/requirements.txt && \
|
||||
rm -rf ~/.cache/uv /tmp/*.txt
|
||||
|
||||
# Cache the embedding model's weights, tokenizer, and metadata in the image.
|
||||
# Cache the default embedding model at its pinned revision, so fresh and air-gapped
|
||||
# installs embed with no download. The name and revision must match
|
||||
# shared_configs/embedding_models.py (a unit test checks this). Other self-hosted
|
||||
# models, nomic included, download on first use.
|
||||
FROM builder AS embedding-models
|
||||
RUN python -c "from sentence_transformers import SentenceTransformer; \
|
||||
SentenceTransformer(model_name_or_path='nomic-ai/nomic-embed-text-v1', trust_remote_code=False);"
|
||||
SentenceTransformer(model_name_or_path='ibm-granite/granite-embedding-97m-multilingual-r2', \
|
||||
revision='835ad14087e140460703cf0fae09f97d469d65c2', trust_remote_code=False);"
|
||||
|
||||
# Runtime stage. We run as the `onyx` user (UID 1001, carried over from the previous
|
||||
# image; see USER below) and chown everything the runtime writes to it. The DHI runtime
|
||||
@@ -97,7 +101,8 @@ COPY --from=builder --chown=1001:1001 /var/log/onyx /var/log/onyx
|
||||
|
||||
# In case the user has volumes mounted to /app/.cache/huggingface that they've downloaded while
|
||||
# running Onyx, move the current contents of the cache folder to a temporary location to ensure
|
||||
# it's preserved in order to combine with the user's cache contents
|
||||
# it's preserved in order to combine with the user's cache contents. The model server merges it
|
||||
# in at startup without overwriting files, so a volume keeps its models (e.g. nomic).
|
||||
COPY --chown=1001:1001 --from=embedding-models /app/.cache/huggingface /app/.cache/temp_huggingface
|
||||
|
||||
# Utils used by model server
|
||||
|
||||
@@ -22,7 +22,7 @@ from onyx.db.enums import EmbeddingPrecision
|
||||
from onyx.db.models import IndexModelStatus
|
||||
from onyx.db.search_settings import user_has_overridden_embedding_model
|
||||
from onyx.indexing.models import IndexingSetting
|
||||
from onyx.natural_language_processing.search_nlp_models import clean_model_name
|
||||
from shared_configs.utils import clean_model_name
|
||||
|
||||
# revision identifiers, used by Alembic.
|
||||
revision = "dbaa756c2ccf"
|
||||
|
||||
@@ -0,0 +1,205 @@
|
||||
"""Loads self-hosted embedding models for the model server.
|
||||
|
||||
Registry models (the exact names that ``get_local_model_spec`` matches) load at
|
||||
a pinned revision, in float32 on CPU-only hosts, with a per-model fix-up and an
|
||||
output dimension check. Every other name (legacy and custom models) keeps the
|
||||
``SentenceTransformer`` call from before the registry, so existing vectors do
|
||||
not change; only the file lookup is local first. Settings come only from the
|
||||
server-side registry, never from a request. All functions here block.
|
||||
"""
|
||||
|
||||
import os
|
||||
from collections.abc import Callable
|
||||
from typing import TYPE_CHECKING, Any, TypeVar
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from model_server.voyage_nano import (
|
||||
VOYAGE_NANO_PROJECTION_FILE,
|
||||
add_bidirectional_projection,
|
||||
read_projection_weight,
|
||||
)
|
||||
from onyx.utils.logger import setup_logger
|
||||
from shared_configs.embedding_models import (
|
||||
EmbeddingModelSpec,
|
||||
LocalModelLoader,
|
||||
get_local_model_spec,
|
||||
)
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from sentence_transformers import SentenceTransformer
|
||||
|
||||
logger = setup_logger()
|
||||
|
||||
_T = TypeVar("_T")
|
||||
|
||||
# What a local-only load raises when an interrupted download left a partial
|
||||
# cache (sentence-transformers 5.4.1, huggingface-hub 1.26). The online retry
|
||||
# downloads the missing files; a real load error comes back from that retry.
|
||||
_PARTIAL_CACHE_ERRORS: tuple[type[Exception], ...] = (OSError, ValueError, TypeError)
|
||||
|
||||
# sentence-transformers reads this env var as its cache folder when it is set.
|
||||
_SENTENCE_TRANSFORMERS_HOME_ENV = "SENTENCE_TRANSFORMERS_HOME"
|
||||
_DIMENSION_PROBE_TEXT = "probe"
|
||||
|
||||
|
||||
class EmbeddingModelLoadError(RuntimeError):
|
||||
"""A self-hosted embedding model loaded, but is not usable."""
|
||||
|
||||
|
||||
def _cache_dir() -> str | None:
|
||||
return os.environ.get(_SENTENCE_TRANSFORMERS_HOME_ENV) or None
|
||||
|
||||
|
||||
def _modules_json_is_cached(model_name: str, revision: str | None) -> bool:
|
||||
"""True if the cache has modules.json at this revision, or a marker that the
|
||||
repo has none. Without it, a local-only load silently builds default modules
|
||||
(mean pooling, no Normalize)."""
|
||||
from huggingface_hub import try_to_load_from_cache
|
||||
|
||||
try:
|
||||
cached = try_to_load_from_cache(
|
||||
model_name, "modules.json", cache_dir=_cache_dir(), revision=revision
|
||||
)
|
||||
except ValueError:
|
||||
# Not a Hub repo id (e.g. a local directory). sentence-transformers
|
||||
# reads a local directory directly, with no download.
|
||||
return False
|
||||
return cached is not None
|
||||
|
||||
|
||||
def _load_local_first(
|
||||
model_name: str,
|
||||
revision: str | None,
|
||||
load: Callable[[bool], _T],
|
||||
) -> _T:
|
||||
"""Run ``load(local_files_only)`` from the local cache first, then online, so
|
||||
a cached model (baked or downloaded before) loads with no network access."""
|
||||
cached = _modules_json_is_cached(model_name, revision)
|
||||
if cached:
|
||||
try:
|
||||
return load(True)
|
||||
except _PARTIAL_CACHE_ERRORS as e:
|
||||
logger.warning(
|
||||
"Could not load %s from the local cache (%s: %s). Loading it from Hugging Face.",
|
||||
model_name,
|
||||
type(e).__name__,
|
||||
e,
|
||||
)
|
||||
else:
|
||||
logger.notice(
|
||||
"%s is not in the model server's Hugging Face cache. Downloading it.",
|
||||
model_name,
|
||||
)
|
||||
try:
|
||||
return load(False)
|
||||
except Exception as e:
|
||||
if cached:
|
||||
raise
|
||||
# huggingface_hub reports an unreachable Hub with unclear errors (e.g.
|
||||
# "the client has been closed"). Say what is missing and what to do.
|
||||
raise EmbeddingModelLoadError(
|
||||
f"{model_name} is not in the model server's Hugging Face cache and "
|
||||
f"could not be downloaded ({type(e).__name__}: {e}). If this "
|
||||
"deployment has no internet access, add the model to the cache "
|
||||
f"({_cache_dir() or 'the default HF_HOME cache'}) first."
|
||||
) from e
|
||||
|
||||
|
||||
def _registry_model_kwargs() -> dict[str, Any]:
|
||||
"""The new checkpoints are bf16, which is 8-10x slower than float32 on CPU,
|
||||
so CPU-only hosts load float32. CUDA and MPS keep the checkpoint dtype."""
|
||||
if torch.cuda.is_available() or torch.backends.mps.is_available():
|
||||
return {}
|
||||
return {"dtype": torch.float32}
|
||||
|
||||
|
||||
def _check_embedding_dim(
|
||||
model: "SentenceTransformer", spec: EmbeddingModelSpec
|
||||
) -> None:
|
||||
"""Fail unless a probe embedding has the registry dimension and is finite. The
|
||||
configured dimension is not enough: a wrong voyage-4-nano load reports 2048
|
||||
but returns 1024-dim vectors."""
|
||||
probe = model.encode([_DIMENSION_PROBE_TEXT], show_progress_bar=False)
|
||||
dim = probe.shape[-1]
|
||||
if dim != spec.model_dim:
|
||||
raise EmbeddingModelLoadError(
|
||||
f"{spec.model_name} returned {dim}-dim vectors, but the registry "
|
||||
f"expects {spec.model_dim}. The model is not used."
|
||||
)
|
||||
if not np.isfinite(probe).all():
|
||||
raise EmbeddingModelLoadError(
|
||||
f"{spec.model_name} returned non-finite values for a probe text. "
|
||||
"The model is not used."
|
||||
)
|
||||
|
||||
|
||||
def _load_registry_model(spec: EmbeddingModelSpec) -> "SentenceTransformer":
|
||||
from sentence_transformers import SentenceTransformer
|
||||
|
||||
revision = spec.hf_revision
|
||||
model_kwargs = _registry_model_kwargs()
|
||||
|
||||
def load(local_files_only: bool) -> "SentenceTransformer":
|
||||
return SentenceTransformer(
|
||||
model_name_or_path=spec.model_name,
|
||||
revision=revision,
|
||||
trust_remote_code=False,
|
||||
local_files_only=local_files_only,
|
||||
model_kwargs=model_kwargs,
|
||||
)
|
||||
|
||||
model = _load_local_first(spec.model_name, revision, load)
|
||||
|
||||
if spec.loader == LocalModelLoader.VOYAGE_BIDIRECTIONAL_PROJECTION:
|
||||
from huggingface_hub import hf_hub_download
|
||||
|
||||
# The base load cached this file, and a commit-sha revision reads a
|
||||
# cached file with no network call.
|
||||
weights_path = hf_hub_download(
|
||||
spec.model_name,
|
||||
VOYAGE_NANO_PROJECTION_FILE,
|
||||
revision=revision,
|
||||
cache_dir=_cache_dir(),
|
||||
)
|
||||
model = add_bidirectional_projection(
|
||||
model, read_projection_weight(weights_path)
|
||||
)
|
||||
logger.info(
|
||||
"%s: transformers reports 'linear.weight' as UNEXPECTED. This is "
|
||||
"expected: Onyx adds it back as the projection layer.",
|
||||
spec.model_name,
|
||||
)
|
||||
|
||||
_check_embedding_dim(model, spec)
|
||||
logger.notice(
|
||||
"Loaded %s at revision %s (device=%s, dtype=%s)",
|
||||
spec.model_name,
|
||||
revision,
|
||||
model.device,
|
||||
model.dtype,
|
||||
)
|
||||
return model
|
||||
|
||||
|
||||
def _load_legacy_model(model_name: str) -> "SentenceTransformer":
|
||||
from sentence_transformers import SentenceTransformer
|
||||
|
||||
def load(local_files_only: bool) -> "SentenceTransformer":
|
||||
# The call from before the registry. Only local_files_only changes.
|
||||
return SentenceTransformer(
|
||||
model_name_or_path=model_name,
|
||||
local_files_only=local_files_only,
|
||||
trust_remote_code=False,
|
||||
)
|
||||
|
||||
return _load_local_first(model_name, None, load)
|
||||
|
||||
|
||||
def load_embedding_model(model_name: str) -> "SentenceTransformer":
|
||||
"""Load a self-hosted embedding model. Blocking; raises on failure."""
|
||||
spec = get_local_model_spec(model_name)
|
||||
if spec is not None:
|
||||
return _load_registry_model(spec)
|
||||
return _load_legacy_model(model_name)
|
||||
@@ -1,12 +1,16 @@
|
||||
import asyncio
|
||||
import threading
|
||||
import time
|
||||
from concurrent.futures import Future, ThreadPoolExecutor
|
||||
from functools import partial
|
||||
from typing import TYPE_CHECKING, Any
|
||||
|
||||
from fastapi import APIRouter, HTTPException, Request
|
||||
|
||||
from model_server.embedding_model_loader import load_embedding_model
|
||||
from model_server.utils import simple_log_function_time
|
||||
from onyx.utils.logger import setup_logger
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import get_local_model_spec
|
||||
from shared_configs.enums import EmbedTextType
|
||||
from shared_configs.model_server_models import Embedding, EmbedRequest, EmbedResponse
|
||||
|
||||
@@ -19,6 +23,66 @@ router = APIRouter(prefix="/encoder")
|
||||
|
||||
|
||||
_GLOBAL_MODELS_DICT: dict[str, "SentenceTransformer"] = {}
|
||||
# The longest sequence that each model's RoPE caches are pre-warmed to.
|
||||
_ROPE_PREWARMED_TO: dict[str, int] = {}
|
||||
|
||||
# One lock per model, so a model loads once even if requests race.
|
||||
_MODEL_LOCKS: dict[str, threading.Lock] = {}
|
||||
_MODEL_LOCKS_GUARD = threading.Lock()
|
||||
|
||||
# Loads (downloads included) run here, off the event loop. Requests for the same
|
||||
# model and context length share one job, so requests that wait on a download
|
||||
# hold no threads.
|
||||
# Two workers: at most PRESENT + FUTURE weights load at once, which caps memory.
|
||||
_MODEL_LOAD_EXECUTOR = ThreadPoolExecutor(
|
||||
max_workers=2, thread_name_prefix="embedding-model-load"
|
||||
)
|
||||
_PENDING_MODEL_JOBS: dict[tuple[str, int], Future["SentenceTransformer"]] = {}
|
||||
_PENDING_MODEL_JOBS_GUARD = threading.Lock()
|
||||
|
||||
# Registry models get room for the query/passage prefix, which the chunker does
|
||||
# not count, so the prefix does not cut off the end of a full chunk.
|
||||
REGISTRY_MODEL_PREFIX_HEADROOM_TOKENS = 32
|
||||
|
||||
|
||||
def _model_lock(model_name: str) -> threading.Lock:
|
||||
with _MODEL_LOCKS_GUARD:
|
||||
lock = _MODEL_LOCKS.get(model_name)
|
||||
if lock is None:
|
||||
lock = threading.Lock()
|
||||
_MODEL_LOCKS[model_name] = lock
|
||||
return lock
|
||||
|
||||
|
||||
def _target_max_seq_length(model_name: str, max_context_length: int) -> int:
|
||||
if get_local_model_spec(model_name) is not None:
|
||||
return max_context_length + REGISTRY_MODEL_PREFIX_HEADROOM_TOKENS
|
||||
return max_context_length
|
||||
|
||||
|
||||
def _prewarm_rope(
|
||||
model_name: str, st_model: "SentenceTransformer", target_len: int
|
||||
) -> None:
|
||||
"""
|
||||
Build RoPE cos/sin caches once on the final device/dtype so later forwards only read.
|
||||
Works by calling the underlying HF model directly with dummy IDs/attention.
|
||||
"""
|
||||
try:
|
||||
# ensure > max seq after tokenization
|
||||
# Ideally we would use the saved tokenizer, but whatever it's ok
|
||||
# we'll make an assumption about tokenization here
|
||||
long_text = "x " * (target_len * 2)
|
||||
_ = st_model.encode(
|
||||
[long_text],
|
||||
batch_size=1,
|
||||
convert_to_tensor=True,
|
||||
show_progress_bar=False,
|
||||
normalize_embeddings=False,
|
||||
)
|
||||
_ROPE_PREWARMED_TO[model_name] = target_len
|
||||
logger.info("RoPE pre-warm successful")
|
||||
except Exception as e:
|
||||
logger.warning("RoPE pre-warm skipped/failed: %s", e)
|
||||
|
||||
|
||||
def get_embedding_model(
|
||||
@@ -26,53 +90,65 @@ def get_embedding_model(
|
||||
max_context_length: int,
|
||||
) -> "SentenceTransformer":
|
||||
"""
|
||||
Loads or returns a cached SentenceTransformer, sets max_seq_length, pins device,
|
||||
pre-warms rotary caches once, and wraps encode() with a lock to avoid cache races.
|
||||
Loads or returns a cached SentenceTransformer, sets max_seq_length and
|
||||
pre-warms rotary caches.
|
||||
|
||||
Blocking: a first load can download gigabytes. Async code must use
|
||||
`_get_embedding_model_off_loop`.
|
||||
"""
|
||||
from sentence_transformers import SentenceTransformer
|
||||
max_seq_length = _target_max_seq_length(model_name, max_context_length)
|
||||
|
||||
def _prewarm_rope(st_model: "SentenceTransformer", target_len: int) -> None:
|
||||
"""
|
||||
Build RoPE cos/sin caches once on the final device/dtype so later forwards only read.
|
||||
Works by calling the underlying HF model directly with dummy IDs/attention.
|
||||
"""
|
||||
try:
|
||||
# ensure > max seq after tokenization
|
||||
# Ideally we would use the saved tokenizer, but whatever it's ok
|
||||
# we'll make an assumption about tokenization here
|
||||
long_text = "x " * (target_len * 2)
|
||||
_ = st_model.encode(
|
||||
[long_text],
|
||||
batch_size=1,
|
||||
convert_to_tensor=True,
|
||||
show_progress_bar=False,
|
||||
normalize_embeddings=False,
|
||||
with _model_lock(model_name):
|
||||
model = _GLOBAL_MODELS_DICT.get(model_name)
|
||||
if model is None:
|
||||
logger.notice("Loading %s", model_name)
|
||||
# Raises on failure, so a failed or rejected model is never cached.
|
||||
model = load_embedding_model(model_name)
|
||||
model.max_seq_length = max_seq_length
|
||||
_prewarm_rope(model_name, model, max_seq_length)
|
||||
_GLOBAL_MODELS_DICT[model_name] = model
|
||||
elif max_seq_length != model.max_seq_length:
|
||||
model.max_seq_length = max_seq_length
|
||||
# Caches built for a longer sequence also serve a shorter one.
|
||||
if max_seq_length > _ROPE_PREWARMED_TO.get(model_name, 0):
|
||||
_prewarm_rope(model_name, model, max_seq_length)
|
||||
|
||||
return model
|
||||
|
||||
|
||||
def _forget_model_job(
|
||||
job_key: tuple[str, int], job: Future["SentenceTransformer"]
|
||||
) -> None:
|
||||
with _PENDING_MODEL_JOBS_GUARD:
|
||||
if _PENDING_MODEL_JOBS.get(job_key) is job:
|
||||
del _PENDING_MODEL_JOBS[job_key]
|
||||
|
||||
|
||||
async def _get_embedding_model_off_loop(
|
||||
model_name: str, max_context_length: int
|
||||
) -> "SentenceTransformer":
|
||||
"""`get_embedding_model` without blocking the event loop."""
|
||||
model = _GLOBAL_MODELS_DICT.get(model_name)
|
||||
if model is not None and model.max_seq_length == _target_max_seq_length(
|
||||
model_name, max_context_length
|
||||
):
|
||||
return model
|
||||
|
||||
job_key = (model_name, max_context_length)
|
||||
with _PENDING_MODEL_JOBS_GUARD:
|
||||
job = _PENDING_MODEL_JOBS.get(job_key)
|
||||
is_new_job = job is None
|
||||
if job is None:
|
||||
job = _MODEL_LOAD_EXECUTOR.submit(
|
||||
get_embedding_model, model_name, max_context_length
|
||||
)
|
||||
logger.info("RoPE pre-warm successful")
|
||||
except Exception as e:
|
||||
logger.warning("RoPE pre-warm skipped/failed: %s", e)
|
||||
_PENDING_MODEL_JOBS[job_key] = job
|
||||
if is_new_job:
|
||||
# Outside the guard: the callback runs at once if the job is done.
|
||||
job.add_done_callback(partial(_forget_model_job, job_key))
|
||||
|
||||
global _GLOBAL_MODELS_DICT
|
||||
|
||||
if model_name not in _GLOBAL_MODELS_DICT:
|
||||
logger.notice("Loading %s", model_name)
|
||||
model = SentenceTransformer(
|
||||
model_name_or_path=model_name,
|
||||
local_files_only=model_name == DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
trust_remote_code=False,
|
||||
)
|
||||
model.max_seq_length = max_context_length
|
||||
_prewarm_rope(model, max_context_length)
|
||||
_GLOBAL_MODELS_DICT[model_name] = model
|
||||
else:
|
||||
model = _GLOBAL_MODELS_DICT[model_name]
|
||||
if max_context_length != model.max_seq_length:
|
||||
model.max_seq_length = max_context_length
|
||||
prev = getattr(model, "_rope_prewarmed_to", 0) # ods: ignore[getattr]
|
||||
if max_context_length > int(prev or 0):
|
||||
_prewarm_rope(model, max_context_length)
|
||||
|
||||
return _GLOBAL_MODELS_DICT[model_name]
|
||||
# A cancelled request must not cancel the job that other requests share.
|
||||
return await asyncio.shield(asyncio.wrap_future(job))
|
||||
|
||||
|
||||
ENCODING_RETRIES = 3
|
||||
@@ -132,7 +208,7 @@ async def embed_text(
|
||||
|
||||
prefixed_texts = [f"{prefix}{text}" for text in texts] if prefix else texts
|
||||
|
||||
local_model = get_embedding_model(
|
||||
local_model = await _get_embedding_model_off_loop(
|
||||
model_name=model_name, max_context_length=max_context_length
|
||||
)
|
||||
# Run CPU-bound embedding in a thread pool
|
||||
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Onyx-owned load fix-up for ``voyageai/voyage-4-nano``, with no remote code.
|
||||
|
||||
A plain SentenceTransformer load of this checkpoint gives wrong vectors and no
|
||||
error: transformers loads the native, causal ``Qwen3Model`` and drops the
|
||||
bias-free ``linear.weight`` projection (1024 -> 2048). The checkpoint's remote
|
||||
code fails on transformers 5.14.1, and Onyx never runs remote code anyway. The
|
||||
fix makes attention bidirectional and adds the projection as a bias-free
|
||||
``Dense`` layer after mean pooling: pooling is linear, so this equals the remote
|
||||
code's per-token projection. Checked on real weights against an independent
|
||||
re-implementation of the remote model: 1 - cosine < 2e-7.
|
||||
"""
|
||||
|
||||
from typing import TYPE_CHECKING, cast
|
||||
|
||||
import torch
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from sentence_transformers import SentenceTransformer
|
||||
|
||||
# The checkpoint file that holds the projection, and the tensor name in it.
|
||||
VOYAGE_NANO_PROJECTION_FILE = "model.safetensors"
|
||||
_PROJECTION_WEIGHT_KEY = "linear.weight"
|
||||
|
||||
|
||||
def read_projection_weight(safetensors_path: str) -> torch.Tensor:
|
||||
"""Read the bias-free projection weight, shape [out_dim, hidden_dim]."""
|
||||
from safetensors import safe_open
|
||||
|
||||
with safe_open(safetensors_path, framework="pt") as checkpoint:
|
||||
return checkpoint.get_tensor(_PROJECTION_WEIGHT_KEY)
|
||||
|
||||
|
||||
def add_bidirectional_projection(
|
||||
model: "SentenceTransformer", projection_weight: torch.Tensor
|
||||
) -> "SentenceTransformer":
|
||||
"""Return voyage-4-nano with bidirectional attention and the 2048-dim projection.
|
||||
|
||||
``model`` is the plain native load (Transformer -> Pooling -> Normalize).
|
||||
"""
|
||||
from sentence_transformers import SentenceTransformer
|
||||
from sentence_transformers.base.modules import Transformer
|
||||
from sentence_transformers.sentence_transformer.modules import Dense
|
||||
|
||||
transformer, pooling, normalize = model[0], model[1], model[2]
|
||||
# The Qwen3 forward reads this on every call. It must be set after the load:
|
||||
# Qwen3Config ignores an is_causal config kwarg.
|
||||
cast(Transformer, transformer).auto_model.config.is_causal = False
|
||||
|
||||
projection = Dense(
|
||||
in_features=projection_weight.shape[1],
|
||||
out_features=projection_weight.shape[0],
|
||||
bias=False,
|
||||
activation_function=None, # identity
|
||||
init_weight=projection_weight,
|
||||
)
|
||||
return SentenceTransformer(modules=[transformer, pooling, projection, normalize])
|
||||
@@ -577,6 +577,13 @@ DOCUMENT_INDEX_NUM_ATTEMPTS_ON_STARTUP = int(
|
||||
os.environ.get("NUM_RETRIES_ON_STARTUP") or 10
|
||||
)
|
||||
|
||||
# Seconds the API server waits on startup for the model server to load the
|
||||
# self-hosted embedding model, which includes a download if it is not cached.
|
||||
# Startup fails when the wait runs out. 0 disables the wait.
|
||||
LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT = int(
|
||||
os.environ.get("LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT") or 1800
|
||||
)
|
||||
|
||||
# Number of documents in a batch during indexing (further batching done by chunks before passing to bi-encoder)
|
||||
INDEX_BATCH_SIZE = int(os.environ.get("INDEX_BATCH_SIZE") or 16)
|
||||
|
||||
|
||||
@@ -1,7 +1,9 @@
|
||||
import json
|
||||
import os
|
||||
from collections.abc import Mapping
|
||||
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import find_embedding_model_spec
|
||||
|
||||
#####
|
||||
# Embedding/Reranking Model Configs
|
||||
@@ -17,11 +19,38 @@ from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
DOCUMENT_ENCODER_MODEL = (
|
||||
os.environ.get("DOCUMENT_ENCODER_MODEL") or DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
)
|
||||
DOC_EMBEDDING_DIM = int(os.environ.get("DOC_EMBEDDING_DIM") or 768)
|
||||
# The settings below only seed the first search settings row of a fresh DB
|
||||
# (alembic dbaa756c2ccf). Defaults come from the registry spec of
|
||||
# DOCUMENT_ENCODER_MODEL (the old literals for other models). Their env vars
|
||||
# count only with DOCUMENT_ENCODER_MODEL set, so an env file written for nomic
|
||||
# cannot give the default model nomic's dimension or prefixes.
|
||||
_MODEL_ENV: Mapping[str, str] = (
|
||||
os.environ if os.environ.get("DOCUMENT_ENCODER_MODEL") else {}
|
||||
)
|
||||
_DOCUMENT_ENCODER_SPEC = find_embedding_model_spec(None, DOCUMENT_ENCODER_MODEL)
|
||||
|
||||
DOC_EMBEDDING_DIM = int(
|
||||
_MODEL_ENV.get("DOC_EMBEDDING_DIM")
|
||||
or (_DOCUMENT_ENCODER_SPEC.model_dim if _DOCUMENT_ENCODER_SPEC else 768)
|
||||
)
|
||||
_NORMALIZE_EMBEDDINGS_DEFAULT = (
|
||||
_DOCUMENT_ENCODER_SPEC.normalize if _DOCUMENT_ENCODER_SPEC else True
|
||||
)
|
||||
NORMALIZE_EMBEDDINGS = (
|
||||
os.environ.get("NORMALIZE_EMBEDDINGS") or "true"
|
||||
_MODEL_ENV.get("NORMALIZE_EMBEDDINGS")
|
||||
or ("true" if _NORMALIZE_EMBEDDINGS_DEFAULT else "false")
|
||||
).lower() == "true"
|
||||
|
||||
# The default self-hosted model before granite.
|
||||
PREVIOUS_DEFAULT_DOCUMENT_ENCODER_MODEL = "nomic-ai/nomic-embed-text-v1"
|
||||
|
||||
# Tokenizer for chat token counting and for the fallback when a model's own
|
||||
# tokenizer can't load: env DOCUMENT_ENCODER_MODEL, else nomic (baked into the
|
||||
# API image), so token counts do not depend on the default embedding model.
|
||||
DEFAULT_TOKENIZER_MODEL = (
|
||||
os.environ.get("DOCUMENT_ENCODER_MODEL") or PREVIOUS_DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
)
|
||||
|
||||
# Old default model settings, which are needed for an automatic easy upgrade
|
||||
OLD_DEFAULT_DOCUMENT_ENCODER_MODEL = "thenlper/gte-small"
|
||||
OLD_DEFAULT_MODEL_DOC_EMBEDDING_DIM = 384
|
||||
@@ -32,8 +61,19 @@ OLD_DEFAULT_MODEL_NORMALIZE_EMBEDDINGS = False
|
||||
SIM_SCORE_RANGE_LOW = float(os.environ.get("SIM_SCORE_RANGE_LOW") or 0.0)
|
||||
SIM_SCORE_RANGE_HIGH = float(os.environ.get("SIM_SCORE_RANGE_HIGH") or 1.0)
|
||||
# Certain models like e5, BGE, etc use a prefix for asymmetric retrievals (query generally shorter than docs)
|
||||
ASYM_QUERY_PREFIX = os.environ.get("ASYM_QUERY_PREFIX", "search_query: ")
|
||||
ASYM_PASSAGE_PREFIX = os.environ.get("ASYM_PASSAGE_PREFIX", "search_document: ")
|
||||
# An env var set to "" stays "" (no fallback to the default).
|
||||
ASYM_QUERY_PREFIX = _MODEL_ENV.get(
|
||||
"ASYM_QUERY_PREFIX",
|
||||
_DOCUMENT_ENCODER_SPEC.query_prefix if _DOCUMENT_ENCODER_SPEC else "search_query: ",
|
||||
)
|
||||
ASYM_PASSAGE_PREFIX = _MODEL_ENV.get(
|
||||
"ASYM_PASSAGE_PREFIX",
|
||||
(
|
||||
_DOCUMENT_ENCODER_SPEC.passage_prefix
|
||||
if _DOCUMENT_ENCODER_SPEC
|
||||
else "search_document: "
|
||||
),
|
||||
)
|
||||
# Purely an optimization, memory limitation consideration
|
||||
|
||||
# User's set embedding batch size overrides the default encoding batch sizes
|
||||
|
||||
@@ -5,6 +5,7 @@ from sqlalchemy.orm import Session
|
||||
from onyx.configs.model_configs import (
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
DOCUMENT_ENCODER_MODEL,
|
||||
PREVIOUS_DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
)
|
||||
from onyx.context.search.models import SavedSearchSettings
|
||||
from onyx.db.llm import fetch_embedding_provider
|
||||
@@ -283,7 +284,13 @@ def update_search_settings_status(
|
||||
|
||||
|
||||
def user_has_overridden_embedding_model() -> bool:
|
||||
return DOCUMENT_ENCODER_MODEL != DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
"""True if env DOCUMENT_ENCODER_MODEL names a non-default model, for the alembic
|
||||
seed (dbaa756c2ccf). nomic, the previous default, counts as a default so that
|
||||
DOCUMENT_ENCODER_MODEL=nomic seeds the same rows as an install before granite."""
|
||||
return DOCUMENT_ENCODER_MODEL not in (
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
PREVIOUS_DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
)
|
||||
|
||||
|
||||
# Old-index reclamation (post-reindex deletion of the now-PAST index).
|
||||
|
||||
@@ -333,10 +333,6 @@ WARM_UP_STRINGS = [
|
||||
]
|
||||
|
||||
|
||||
def clean_model_name(model_str: str) -> str:
|
||||
return model_str.replace("/", "_").replace("-", "_").replace(".", "_").lower()
|
||||
|
||||
|
||||
def build_model_server_url(
|
||||
model_server_host: str,
|
||||
model_server_port: int,
|
||||
@@ -496,7 +492,7 @@ def _extract_cohere_embeddings(response_embeddings: Any) -> list[Embedding]:
|
||||
"""Normalize Cohere's embed response across SDK versions.
|
||||
|
||||
v3 models return ``response.embeddings`` as a flat ``list[list[float]]``.
|
||||
v4 models return an ``EmbedByTypeResponseEmbeddings`` object that carries
|
||||
v4 and v5 models return an ``EmbedByTypeResponseEmbeddings`` object that carries
|
||||
the embeddings under ``float_`` (and possibly other per-type buckets when
|
||||
``embedding_types`` is set). We always read the float bucket here since
|
||||
we never request alternate types.
|
||||
@@ -1328,19 +1324,18 @@ class EmbeddingModel:
|
||||
reraise=True,
|
||||
)(final_make_request_func)
|
||||
|
||||
response: Response | None = None
|
||||
|
||||
try:
|
||||
response = final_make_request_func()
|
||||
return EmbedResponse(**response.json())
|
||||
except requests.HTTPError as e:
|
||||
if not response:
|
||||
# raise_for_status() raised, so the failed response is only on the error.
|
||||
if e.response is None:
|
||||
raise HTTPError("HTTP error occurred - response is None.") from e
|
||||
|
||||
try:
|
||||
error_detail = response.json().get("detail", str(e))
|
||||
error_detail = e.response.json().get("detail", str(e))
|
||||
except Exception:
|
||||
error_detail = response.text
|
||||
error_detail = e.response.text
|
||||
raise HTTPError(f"HTTP error occurred: {error_detail}") from e
|
||||
except requests.RequestException as e:
|
||||
raise HTTPError(f"Request failed: {str(e)}") from e
|
||||
|
||||
@@ -4,10 +4,11 @@ from copy import copy
|
||||
|
||||
from tokenizers import Encoding, Tokenizer
|
||||
|
||||
from onyx.configs.model_configs import DOCUMENT_ENCODER_MODEL
|
||||
from onyx.configs.model_configs import DEFAULT_TOKENIZER_MODEL
|
||||
from onyx.context.search.models import InferenceChunk
|
||||
from onyx.utils.logger import setup_logger
|
||||
from shared_configs.configs import DOC_EMBEDDING_CONTEXT_SIZE
|
||||
from shared_configs.embedding_models import get_local_model_spec
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
|
||||
TRIM_SEP_PAT = "\n... {n} tokens removed...\n"
|
||||
@@ -69,7 +70,15 @@ class TiktokenTokenizer(BaseTokenizer):
|
||||
|
||||
class HuggingFaceTokenizer(BaseTokenizer):
|
||||
def __init__(self, model_name: str):
|
||||
self.encoder: Tokenizer = Tokenizer.from_pretrained(model_name)
|
||||
# Registry models load at their pinned revision, the same one the model
|
||||
# server and the image bake use. Any other name keeps the plain call.
|
||||
local_model_spec = get_local_model_spec(model_name)
|
||||
revision = local_model_spec.hf_revision if local_model_spec else None
|
||||
self.encoder: Tokenizer = (
|
||||
Tokenizer.from_pretrained(model_name)
|
||||
if revision is None
|
||||
else Tokenizer.from_pretrained(model_name, revision=revision)
|
||||
)
|
||||
|
||||
def _safer_encode(self, string: str) -> Encoding:
|
||||
"""
|
||||
@@ -113,7 +122,7 @@ def _check_tokenizer_cache(
|
||||
if not tokenizer:
|
||||
logger.info(
|
||||
"Falling back to default embedding model tokenizer: %s",
|
||||
DOCUMENT_ENCODER_MODEL,
|
||||
DEFAULT_TOKENIZER_MODEL,
|
||||
)
|
||||
tokenizer = _get_default_tokenizer()
|
||||
|
||||
@@ -168,7 +177,7 @@ def _get_default_tokenizer() -> BaseTokenizer:
|
||||
"""Lazy-load the default tokenizer to avoid loading it at module import time."""
|
||||
global _DEFAULT_TOKENIZER
|
||||
if _DEFAULT_TOKENIZER is None:
|
||||
_DEFAULT_TOKENIZER = HuggingFaceTokenizer(DOCUMENT_ENCODER_MODEL)
|
||||
_DEFAULT_TOKENIZER = HuggingFaceTokenizer(DEFAULT_TOKENIZER_MODEL)
|
||||
return _DEFAULT_TOKENIZER
|
||||
|
||||
|
||||
|
||||
@@ -97,7 +97,6 @@ from onyx.file_processing.unstructured import (
|
||||
)
|
||||
from onyx.indexing.port_reembed import ReembedStrategy, select_reembed_strategy
|
||||
from onyx.natural_language_processing.embedding_auth import build_embedding_auth
|
||||
from onyx.natural_language_processing.search_nlp_models import clean_model_name
|
||||
from onyx.server.manage.embedding.models import SearchSettingsDeleteRequest
|
||||
from onyx.server.manage.embedding.probe import probe_embedding_dimension
|
||||
from onyx.server.manage.models import (
|
||||
@@ -123,7 +122,15 @@ from shared_configs.configs import (
|
||||
PRESERVED_SEARCH_FIELDS,
|
||||
)
|
||||
from shared_configs.contextvars import get_current_tenant_id
|
||||
from shared_configs.embedding_models import (
|
||||
EmbeddingModelSpec,
|
||||
EmbeddingModelStatus,
|
||||
embedding_model_match_key,
|
||||
find_embedding_model_spec,
|
||||
selectable_embedding_model_specs,
|
||||
)
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
from shared_configs.utils import clean_model_name
|
||||
|
||||
router = APIRouter(prefix="/search-settings")
|
||||
logger = setup_logger()
|
||||
@@ -140,15 +147,32 @@ def set_new_search_settings(
|
||||
Only one re-index runs at a time. This raises CONFLICT instead of superseding an
|
||||
existing one: either a secondary FUTURE is already in flight, or an INSTANT
|
||||
switchover is still backfilling the live index. Cancel the running re-index first.
|
||||
|
||||
Embedding models only move forward: legacy models are refused as a new target,
|
||||
except for a re-index with the PRESENT model (see _check_embedding_model_target).
|
||||
"""
|
||||
if search_settings_new.index_name:
|
||||
logger.warning("Index name was specified by request, this is not suggested")
|
||||
|
||||
# Disallow contextual RAG for cloud deployments.
|
||||
if MULTI_TENANT and search_settings_new.enable_contextual_rag:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_400_BAD_REQUEST,
|
||||
detail="Contextual RAG disabled in Onyx Cloud",
|
||||
raise OnyxError(
|
||||
OnyxErrorCode.INVALID_INPUT, "Contextual RAG disabled in Onyx Cloud"
|
||||
)
|
||||
|
||||
spec = find_embedding_model_spec(
|
||||
search_settings_new.provider_type, search_settings_new.model_name
|
||||
)
|
||||
selectable_spec = (
|
||||
spec
|
||||
if spec is not None and spec.status == EmbeddingModelStatus.SELECTABLE
|
||||
else None
|
||||
)
|
||||
# A selectable model gets its canonical name: the probe, the model server and
|
||||
# the tokenizer match it exactly.
|
||||
if selectable_spec is not None:
|
||||
search_settings_new = search_settings_new.model_copy(
|
||||
update={"model_name": selectable_spec.model_name}
|
||||
)
|
||||
|
||||
# Validate cloud provider exists or create new LiteLLM provider.
|
||||
@@ -163,8 +187,14 @@ def set_new_search_settings(
|
||||
f"No embedding provider exists for cloud embedding type {search_settings_new.provider_type}",
|
||||
)
|
||||
|
||||
if search_settings_new.provider_type == EmbeddingProvider.BIFROST:
|
||||
_validate_gateway_embedding_model(search_settings_new, cloud_provider)
|
||||
# Before the PRESENT row lock below: the probe is a network call. Nothing
|
||||
# is written yet, so end the read transaction instead of idling in it.
|
||||
if (
|
||||
search_settings_new.provider_type == EmbeddingProvider.BIFROST
|
||||
or selectable_spec is not None
|
||||
):
|
||||
db_session.commit()
|
||||
_validate_cloud_embedding_model(search_settings_new, cloud_provider)
|
||||
|
||||
validate_contextual_rag_model(
|
||||
model_configuration_id=search_settings_new.contextual_rag_model_configuration_id,
|
||||
@@ -200,6 +230,10 @@ def set_new_search_settings(
|
||||
"A re-index is already in progress. Cancel it before starting a new one.",
|
||||
)
|
||||
|
||||
# Upgrade-only: a new target must be the PRESENT model or a selectable model.
|
||||
# Runs before anything below writes or commits.
|
||||
_check_embedding_model_target(search_settings_new, search_settings)
|
||||
|
||||
if search_settings_new.index_name is None:
|
||||
search_values = search_settings_new.model_dump()
|
||||
search_values["index_name"] = _compute_index_name(
|
||||
@@ -306,14 +340,13 @@ def set_new_search_settings(
|
||||
return IdReturn(id=new_search_settings.id)
|
||||
|
||||
|
||||
def _validate_gateway_embedding_model(
|
||||
def _validate_cloud_embedding_model(
|
||||
search_settings_new: SearchSettingsCreationRequest,
|
||||
cloud_provider: CloudEmbeddingProviderModel,
|
||||
) -> None:
|
||||
"""A gateway accepts any model ID, so prove the model embeds at the set dimension.
|
||||
|
||||
Rejects a chat model or a wrong dimension before indexing starts.
|
||||
"""
|
||||
"""Prove the model embeds at the set dimension with the stored credentials, so
|
||||
a bad key, region or model ID (a gateway accepts any) fails before indexing
|
||||
starts."""
|
||||
api_key: str | None = (
|
||||
cloud_provider.api_key.get_value(apply_mask=False)
|
||||
if cloud_provider.api_key is not None
|
||||
@@ -324,7 +357,11 @@ def _validate_gateway_embedding_model(
|
||||
api_key=api_key,
|
||||
api_url=cloud_provider.api_url,
|
||||
model_name=search_settings_new.model_name,
|
||||
auth=build_embedding_auth(cloud_provider.provider_type, api_key),
|
||||
auth=build_embedding_auth(
|
||||
cloud_provider.provider_type, api_key, cloud_provider.vertex_config
|
||||
),
|
||||
api_version=cloud_provider.api_version,
|
||||
deployment_name=cloud_provider.deployment_name,
|
||||
reduced_dimension=search_settings_new.reduced_dimension,
|
||||
)
|
||||
if dimension != search_settings_new.final_embedding_dim:
|
||||
@@ -336,6 +373,153 @@ def _validate_gateway_embedding_model(
|
||||
)
|
||||
|
||||
|
||||
# Providers whose model list Onyx owns. Only SELECTABLE registry models are valid
|
||||
# new targets for them. LiteLLM, Azure and Bifrost take free-form names, so they
|
||||
# stay open.
|
||||
_REGISTRY_ONLY_CLOUD_PROVIDERS = frozenset(
|
||||
{
|
||||
EmbeddingProvider.OPENAI,
|
||||
EmbeddingProvider.COHERE,
|
||||
EmbeddingProvider.GOOGLE,
|
||||
EmbeddingProvider.VOYAGE,
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
def _embedding_provider_label(provider_type: EmbeddingProvider | None) -> str:
|
||||
return provider_type.value if provider_type is not None else "self-hosted"
|
||||
|
||||
|
||||
def _selectable_embedding_models_hint() -> str:
|
||||
names_by_provider: dict[str, list[str]] = {}
|
||||
for spec in selectable_embedding_model_specs():
|
||||
names_by_provider.setdefault(
|
||||
_embedding_provider_label(spec.provider_type), []
|
||||
).append(spec.model_name)
|
||||
return "; ".join(
|
||||
f"{provider_label}: {', '.join(names)}"
|
||||
for provider_label, names in names_by_provider.items()
|
||||
)
|
||||
|
||||
|
||||
def _not_selectable_error(
|
||||
request: SearchSettingsCreationRequest, spec: EmbeddingModelSpec | None
|
||||
) -> OnyxError:
|
||||
model = (
|
||||
f"'{request.model_name}' ({_embedding_provider_label(request.provider_type)})"
|
||||
)
|
||||
if spec is not None:
|
||||
reason = (
|
||||
f"{model} is a legacy embedding model. Existing indexes on it keep "
|
||||
"working, but it can't be chosen for a new index."
|
||||
)
|
||||
else:
|
||||
reason = f"{model} is not an embedding model that Onyx supports."
|
||||
return OnyxError(
|
||||
OnyxErrorCode.INVALID_INPUT,
|
||||
f"{reason} Choose one of these models: {_selectable_embedding_models_hint()}. "
|
||||
"A re-index with the current model is still allowed.",
|
||||
)
|
||||
|
||||
|
||||
def _validate_selectable_embedding_request(
|
||||
request: SearchSettingsCreationRequest, spec: EmbeddingModelSpec
|
||||
) -> None:
|
||||
"""A selectable model must use the registry's settings: the index and the
|
||||
embedding code depend on them."""
|
||||
problems: list[str] = []
|
||||
if request.model_dim != spec.model_dim:
|
||||
problems.append(f"model_dim must be {spec.model_dim}, not {request.model_dim}")
|
||||
if request.normalize != spec.normalize:
|
||||
problems.append(f"normalize must be {spec.normalize}")
|
||||
if (request.query_prefix or "") != spec.query_prefix:
|
||||
problems.append(f"query_prefix must be {spec.query_prefix!r}")
|
||||
if (request.passage_prefix or "") != spec.passage_prefix:
|
||||
problems.append(f"passage_prefix must be {spec.passage_prefix!r}")
|
||||
if request.reduced_dimension is not None:
|
||||
if MULTI_TENANT:
|
||||
problems.append("reduced_dimension is not supported in Onyx Cloud")
|
||||
elif not spec.supports_reduced_dimension:
|
||||
problems.append("this model does not support reduced_dimension")
|
||||
elif not 0 < request.reduced_dimension < spec.model_dim:
|
||||
problems.append(
|
||||
f"reduced_dimension must be between 1 and {spec.model_dim - 1}"
|
||||
)
|
||||
if problems:
|
||||
raise OnyxError(
|
||||
OnyxErrorCode.INVALID_INPUT,
|
||||
f"Invalid settings for embedding model '{spec.model_name}': "
|
||||
f"{'; '.join(problems)}.",
|
||||
)
|
||||
|
||||
|
||||
def _check_embedding_model_target(
|
||||
request: SearchSettingsCreationRequest, present: SearchSettings
|
||||
) -> None:
|
||||
"""Upgrade-only rules for a new embedding target. Allowed: the PRESENT model
|
||||
(legacy included), a selectable model with the registry settings, and any
|
||||
model of a provider whose list Onyx does not own (custom HF models, LiteLLM,
|
||||
Azure, Bifrost). Other OpenAI, Cohere, Google and Voyage models and legacy
|
||||
self-hosted models raise OnyxError(INVALID_INPUT)."""
|
||||
spec = find_embedding_model_spec(request.provider_type, request.model_name)
|
||||
selectable_spec = (
|
||||
spec
|
||||
if spec is not None and spec.status == EmbeddingModelStatus.SELECTABLE
|
||||
else None
|
||||
)
|
||||
is_present_model = embedding_model_match_key(
|
||||
request.provider_type, request.model_name
|
||||
) == embedding_model_match_key(present.provider_type, present.model_name)
|
||||
|
||||
# The model server ignores reduced_dimension, so a self-hosted index with it
|
||||
# gets vectors of the wrong size. A re-index keeps a stored value.
|
||||
if (
|
||||
request.provider_type is None
|
||||
and request.reduced_dimension is not None
|
||||
and not (
|
||||
is_present_model and request.reduced_dimension == present.reduced_dimension
|
||||
)
|
||||
):
|
||||
raise OnyxError(
|
||||
OnyxErrorCode.INVALID_INPUT,
|
||||
"Self-hosted embedding models do not support reduced_dimension: the "
|
||||
"model server returns vectors of the full dimension.",
|
||||
)
|
||||
|
||||
# A re-index with the PRESENT model (quantization, contextual RAG, switchover).
|
||||
# Stored rows often differ from the registry (e.g. empty prefixes), so only
|
||||
# the dimension is checked. Tenants share the index of a model, so
|
||||
# MULTI_TENANT also keeps reduced_dimension.
|
||||
if is_present_model:
|
||||
allowed_dims = {present.model_dim}
|
||||
if selectable_spec is not None:
|
||||
allowed_dims.add(selectable_spec.model_dim)
|
||||
if request.model_dim not in allowed_dims:
|
||||
raise OnyxError(
|
||||
OnyxErrorCode.INVALID_INPUT,
|
||||
f"A re-index with the current model must keep its dimension: "
|
||||
f"model_dim must be {' or '.join(str(d) for d in sorted(allowed_dims))}, "
|
||||
f"not {request.model_dim}.",
|
||||
)
|
||||
if MULTI_TENANT and request.reduced_dimension != present.reduced_dimension:
|
||||
raise OnyxError(
|
||||
OnyxErrorCode.INVALID_INPUT,
|
||||
"reduced_dimension can't be changed in Onyx Cloud: "
|
||||
"all tenants on a model share its index.",
|
||||
)
|
||||
return
|
||||
|
||||
if selectable_spec is not None:
|
||||
_validate_selectable_embedding_request(request, selectable_spec)
|
||||
return
|
||||
|
||||
# Any spec left here is LEGACY.
|
||||
if request.provider_type in _REGISTRY_ONLY_CLOUD_PROVIDERS or (
|
||||
request.provider_type is None and spec is not None
|
||||
):
|
||||
raise _not_selectable_error(request, spec)
|
||||
|
||||
|
||||
def _validate_vector_quantization_supported(
|
||||
vector_quantization: VectorQuantization,
|
||||
) -> None:
|
||||
|
||||
+81
-14
@@ -7,6 +7,7 @@ from onyx.configs.app_configs import (
|
||||
DISABLE_VECTOR_DB,
|
||||
DOCUMENT_INDEX_NUM_ATTEMPTS_ON_STARTUP,
|
||||
INTEGRATION_TESTS_MODE,
|
||||
LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT,
|
||||
)
|
||||
from onyx.configs.constants import KV_REINDEX_KEY
|
||||
from onyx.configs.model_configs import GEN_AI_API_KEY, GEN_AI_MODEL_VERSION
|
||||
@@ -30,6 +31,7 @@ from onyx.db.llm import (
|
||||
update_default_model,
|
||||
upsert_llm_provider,
|
||||
)
|
||||
from onyx.db.models import SearchSettings
|
||||
from onyx.db.search_settings import (
|
||||
get_active_search_settings,
|
||||
get_current_search_settings,
|
||||
@@ -49,10 +51,7 @@ from onyx.key_value_store.factory import get_kv_store
|
||||
from onyx.key_value_store.interface import KvKeyNotFoundError
|
||||
from onyx.llm.constants import LlmProviderNames
|
||||
from onyx.llm.well_known_providers.llm_provider_options import get_openai_model_names
|
||||
from onyx.natural_language_processing.search_nlp_models import (
|
||||
EmbeddingModel,
|
||||
warm_up_bi_encoder,
|
||||
)
|
||||
from onyx.natural_language_processing.search_nlp_models import EmbeddingModel
|
||||
from onyx.server.manage.llm.models import (
|
||||
LLMProviderUpsertRequest,
|
||||
ModelConfigurationUpsertRequest,
|
||||
@@ -64,14 +63,20 @@ from onyx.server.settings.store import (
|
||||
)
|
||||
from onyx.utils.gpu_utils import gpu_status_request
|
||||
from onyx.utils.logger import setup_logger
|
||||
from onyx.utils.threadpool_concurrency import start_thread_future
|
||||
from shared_configs.configs import (
|
||||
DISABLE_MODEL_SERVER,
|
||||
MODEL_SERVER_HOST,
|
||||
MODEL_SERVER_PORT,
|
||||
MULTI_TENANT,
|
||||
)
|
||||
from shared_configs.enums import EmbedTextType
|
||||
|
||||
logger = setup_logger()
|
||||
|
||||
_STARTUP_EMBED_TEXT = "Onyx startup check"
|
||||
_STARTUP_RETRY_SECONDS = 10
|
||||
|
||||
|
||||
def setup_onyx(
|
||||
db_session: Session,
|
||||
@@ -145,21 +150,83 @@ def setup_onyx(
|
||||
logger.notice(
|
||||
"Model Server: http://%s:%s", MODEL_SERVER_HOST, MODEL_SERVER_PORT
|
||||
)
|
||||
if search_settings.provider_type is None:
|
||||
# In integration tests, do not block API startup on warm-up
|
||||
warm_up_bi_encoder(
|
||||
embedding_model=EmbeddingModel.from_db_model(
|
||||
search_settings=search_settings,
|
||||
server_host=MODEL_SERVER_HOST,
|
||||
server_port=MODEL_SERVER_PORT,
|
||||
),
|
||||
non_blocking=INTEGRATION_TESTS_MODE,
|
||||
)
|
||||
# Multi-tenant tenant creation and integration tests must not block on it.
|
||||
if (
|
||||
search_settings.provider_type is None
|
||||
and LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT > 0
|
||||
and not (MULTI_TENANT or INTEGRATION_TESTS_MODE or DISABLE_MODEL_SERVER)
|
||||
):
|
||||
wait_for_local_embedding_model(search_settings)
|
||||
|
||||
# update multipass indexing setting based on GPU availability
|
||||
update_default_multipass_indexing(db_session)
|
||||
|
||||
|
||||
def wait_for_local_embedding_model(search_settings: SearchSettings) -> None:
|
||||
"""Block until the inference model server embeds with the self-hosted model in
|
||||
use. Its first request loads the model, with a download if it is not cached
|
||||
(e.g. nomic, which the image does not bundle). Raise when the wait runs out,
|
||||
so the API server does not start with search that cannot embed queries."""
|
||||
model_name = search_settings.model_name
|
||||
embedding_model = EmbeddingModel.from_db_model(
|
||||
search_settings=search_settings,
|
||||
server_host=MODEL_SERVER_HOST,
|
||||
server_port=MODEL_SERVER_PORT,
|
||||
)
|
||||
logger.notice(
|
||||
"Waiting up to %ss for the model server to load embedding model %s. "
|
||||
"It downloads the model first if the model is not in its cache.",
|
||||
LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT,
|
||||
model_name,
|
||||
)
|
||||
start = time.monotonic()
|
||||
deadline = start + LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT
|
||||
last_error: Exception | None = None
|
||||
while (remaining := deadline - time.monotonic()) > 0:
|
||||
try:
|
||||
# A daemon thread: a request that still waits at the deadline does
|
||||
# not keep the failed process from exiting.
|
||||
start_thread_future(
|
||||
lambda: embedding_model.encode(
|
||||
texts=[_STARTUP_EMBED_TEXT], text_type=EmbedTextType.QUERY
|
||||
),
|
||||
name="embedding-model-startup-check",
|
||||
).result(timeout=remaining)
|
||||
except TimeoutError:
|
||||
# The deadline passed during a request, e.g. a slow download.
|
||||
last_error = None
|
||||
break
|
||||
except Exception as e:
|
||||
last_error = e
|
||||
logger.warning(
|
||||
"Embedding model %s is not ready on the model server after %.0fs: %s",
|
||||
model_name,
|
||||
time.monotonic() - start,
|
||||
e,
|
||||
)
|
||||
time.sleep(min(_STARTUP_RETRY_SECONDS, max(deadline - time.monotonic(), 0)))
|
||||
continue
|
||||
logger.notice(
|
||||
"Embedding model %s is ready on the model server (%.0fs).",
|
||||
model_name,
|
||||
time.monotonic() - start,
|
||||
)
|
||||
return
|
||||
|
||||
reason = (
|
||||
f"Last error: {last_error}"
|
||||
if last_error
|
||||
else "The last request was still waiting for the model server."
|
||||
)
|
||||
raise RuntimeError(
|
||||
f"The model server at {MODEL_SERVER_HOST}:{MODEL_SERVER_PORT} did not load "
|
||||
f"embedding model {model_name} within {LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT}s. "
|
||||
f"{reason} If the model server cannot download the model (for example, it "
|
||||
"has no internet access), add the model to its Hugging Face cache. "
|
||||
"LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT sets the wait; 0 disables it."
|
||||
) from last_error
|
||||
|
||||
|
||||
def mark_reindex_flag(db_session: Session) -> None:
|
||||
kv_store = get_kv_store()
|
||||
try:
|
||||
|
||||
@@ -35,7 +35,8 @@ INDEXING_MODEL_SERVER_PORT = int(
|
||||
CONNECTOR_CLASSIFIER_MODEL_REPO = "Danswer/filter-extraction-model"
|
||||
CONNECTOR_CLASSIFIER_MODEL_TAG = "1.0.0"
|
||||
INTENT_MODEL_VERSION = "onyx-dot-app/hybrid-intent-token-classifier"
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL = "nomic-ai/nomic-embed-text-v1"
|
||||
# Fresh-install default self-hosted model, baked into the model-server image.
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL = "ibm-granite/granite-embedding-97m-multilingual-r2"
|
||||
# INTENT_MODEL_TAG = "v1.0.3"
|
||||
INTENT_MODEL_TAG: str | None = None
|
||||
# Bi-Encoder, other details
|
||||
|
||||
@@ -0,0 +1,244 @@
|
||||
"""Registry of known embedding models, shared by the API server (upgrade-only
|
||||
guard, tokenizer revision, config defaults) and the model server (loader
|
||||
settings). Keep it pure (pydantic, the stdlib, ``shared_configs``): the
|
||||
model-server image has no ``onyx`` package and the API image has no torch.
|
||||
|
||||
Only add entries: a deployment can hold any entry as PRESENT, FUTURE or PAST.
|
||||
``model_name`` is the exact ``SearchSettings.model_name``: the bare name for
|
||||
cloud providers, the HF repo id for self-hosted models.
|
||||
"""
|
||||
|
||||
from enum import Enum
|
||||
|
||||
from pydantic import BaseModel
|
||||
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
from shared_configs.utils import clean_model_name
|
||||
|
||||
|
||||
class EmbeddingModelStatus(str, Enum):
|
||||
"""Whether a model can be chosen as a new embedding target."""
|
||||
|
||||
# Offered to admins as a new target.
|
||||
SELECTABLE = "selectable"
|
||||
# Kept only so existing deployments keep working. Not a valid new target,
|
||||
# except for a same-model re-index of the PRESENT model.
|
||||
LEGACY = "legacy"
|
||||
|
||||
|
||||
class LocalModelLoader(str, Enum):
|
||||
"""How the model server loads a SELECTABLE self-hosted model."""
|
||||
|
||||
# Plain SentenceTransformer load.
|
||||
STANDARD = "standard"
|
||||
# voyage-4-nano: native Qwen3 with bidirectional attention, plus the
|
||||
# bias-free 1024 -> 2048 projection from the checkpoint. No remote code.
|
||||
VOYAGE_BIDIRECTIONAL_PROJECTION = "voyage_bidirectional_projection"
|
||||
|
||||
|
||||
class EmbeddingModelSpec(BaseModel, frozen=True):
|
||||
"""One known embedding model. LEGACY values only seed env defaults
|
||||
(``onyx.configs.model_configs``). Stored rows often differ (e.g. empty
|
||||
prefixes), so never compare a request or a row against them."""
|
||||
|
||||
# None means self-hosted (the model server runs it).
|
||||
provider_type: EmbeddingProvider | None
|
||||
model_name: str
|
||||
model_dim: int
|
||||
normalize: bool
|
||||
query_prefix: str
|
||||
passage_prefix: str
|
||||
status: EmbeddingModelStatus
|
||||
# Pinned HF commit sha. Set only for SELECTABLE self-hosted models.
|
||||
hf_revision: str | None = None
|
||||
loader: LocalModelLoader = LocalModelLoader.STANDARD
|
||||
# True if the embedding path honors `reduced_dimension` (Matryoshka).
|
||||
supports_reduced_dimension: bool = False
|
||||
|
||||
|
||||
_SELECTABLE = EmbeddingModelStatus.SELECTABLE
|
||||
_LEGACY = EmbeddingModelStatus.LEGACY
|
||||
|
||||
_E5_QUERY_PREFIX = "query: "
|
||||
_E5_PASSAGE_PREFIX = "passage: "
|
||||
|
||||
|
||||
def _cloud_spec(
|
||||
provider_type: EmbeddingProvider,
|
||||
model_name: str,
|
||||
model_dim: int,
|
||||
status: EmbeddingModelStatus,
|
||||
supports_reduced_dimension: bool = False,
|
||||
) -> EmbeddingModelSpec:
|
||||
"""Cloud models: no Onyx-side normalize and no prefixes."""
|
||||
return EmbeddingModelSpec(
|
||||
provider_type=provider_type,
|
||||
model_name=model_name,
|
||||
model_dim=model_dim,
|
||||
normalize=False,
|
||||
query_prefix="",
|
||||
passage_prefix="",
|
||||
status=status,
|
||||
supports_reduced_dimension=supports_reduced_dimension,
|
||||
)
|
||||
|
||||
|
||||
def _legacy_self_hosted_spec(
|
||||
model_name: str,
|
||||
model_dim: int,
|
||||
normalize: bool,
|
||||
query_prefix: str,
|
||||
passage_prefix: str,
|
||||
) -> EmbeddingModelSpec:
|
||||
return EmbeddingModelSpec(
|
||||
provider_type=None,
|
||||
model_name=model_name,
|
||||
model_dim=model_dim,
|
||||
normalize=normalize,
|
||||
query_prefix=query_prefix,
|
||||
passage_prefix=passage_prefix,
|
||||
status=_LEGACY,
|
||||
)
|
||||
|
||||
|
||||
EMBEDDING_MODEL_SPECS: tuple[EmbeddingModelSpec, ...] = (
|
||||
# ---- SELECTABLE: self-hosted ----
|
||||
EmbeddingModelSpec(
|
||||
provider_type=None,
|
||||
model_name=DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
model_dim=384,
|
||||
normalize=True,
|
||||
query_prefix="",
|
||||
passage_prefix="",
|
||||
status=_SELECTABLE,
|
||||
hf_revision="835ad14087e140460703cf0fae09f97d469d65c2",
|
||||
),
|
||||
EmbeddingModelSpec(
|
||||
provider_type=None,
|
||||
model_name="voyageai/voyage-4-nano",
|
||||
model_dim=2048,
|
||||
normalize=True,
|
||||
query_prefix="Represent the query for retrieving supporting documents: ",
|
||||
passage_prefix="Represent the document for retrieval: ",
|
||||
status=_SELECTABLE,
|
||||
hf_revision="67fabc9bef010dabc5f6024aa1b1b6b93410426f",
|
||||
loader=LocalModelLoader.VOYAGE_BIDIRECTIONAL_PROJECTION,
|
||||
),
|
||||
EmbeddingModelSpec(
|
||||
provider_type=None,
|
||||
model_name="nvidia/Nemotron-3-Embed-1B-BF16",
|
||||
model_dim=2048,
|
||||
normalize=True,
|
||||
query_prefix="query: ",
|
||||
passage_prefix="passage: ",
|
||||
status=_SELECTABLE,
|
||||
hf_revision="c0c9fea93ea424587517f2c59e20db9f1d6bf615",
|
||||
),
|
||||
# ---- SELECTABLE: cloud ----
|
||||
_cloud_spec(EmbeddingProvider.COHERE, "embed-v5.0-pro", 2048, _SELECTABLE),
|
||||
_cloud_spec(EmbeddingProvider.COHERE, "embed-v5.0-fast", 2048, _SELECTABLE),
|
||||
_cloud_spec(
|
||||
EmbeddingProvider.GOOGLE,
|
||||
"gemini-embedding-2",
|
||||
3072,
|
||||
_SELECTABLE,
|
||||
supports_reduced_dimension=True,
|
||||
),
|
||||
_cloud_spec(
|
||||
EmbeddingProvider.OPENAI,
|
||||
"text-embedding-3-large",
|
||||
3072,
|
||||
_SELECTABLE,
|
||||
supports_reduced_dimension=True,
|
||||
),
|
||||
_cloud_spec(
|
||||
EmbeddingProvider.OPENAI,
|
||||
"text-embedding-3-small",
|
||||
1536,
|
||||
_SELECTABLE,
|
||||
supports_reduced_dimension=True,
|
||||
),
|
||||
_cloud_spec(EmbeddingProvider.VOYAGE, "voyage-4-large", 1024, _SELECTABLE),
|
||||
_cloud_spec(EmbeddingProvider.VOYAGE, "voyage-4", 1024, _SELECTABLE),
|
||||
_cloud_spec(EmbeddingProvider.VOYAGE, "voyage-4-lite", 1024, _SELECTABLE),
|
||||
# ---- LEGACY: self-hosted ----
|
||||
_legacy_self_hosted_spec(
|
||||
"nomic-ai/nomic-embed-text-v1", 768, True, "search_query: ", "search_document: "
|
||||
),
|
||||
_legacy_self_hosted_spec(
|
||||
"intfloat/e5-base-v2", 768, True, _E5_QUERY_PREFIX, _E5_PASSAGE_PREFIX
|
||||
),
|
||||
_legacy_self_hosted_spec(
|
||||
"intfloat/e5-small-v2", 384, True, _E5_QUERY_PREFIX, _E5_PASSAGE_PREFIX
|
||||
),
|
||||
_legacy_self_hosted_spec(
|
||||
"intfloat/multilingual-e5-base", 768, True, _E5_QUERY_PREFIX, _E5_PASSAGE_PREFIX
|
||||
),
|
||||
_legacy_self_hosted_spec(
|
||||
"intfloat/multilingual-e5-small",
|
||||
384,
|
||||
True,
|
||||
_E5_QUERY_PREFIX,
|
||||
_E5_PASSAGE_PREFIX,
|
||||
),
|
||||
_legacy_self_hosted_spec("thenlper/gte-small", 384, False, "", ""),
|
||||
# ---- LEGACY: cloud ----
|
||||
_cloud_spec(EmbeddingProvider.COHERE, "embed-english-v3.0", 1024, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.COHERE, "embed-english-light-v3.0", 384, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.COHERE, "embed-v4.0", 1536, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.GOOGLE, "gemini-embedding-001", 3072, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.GOOGLE, "text-embedding-005", 768, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.GOOGLE, "gemini-embedding-2-preview", 3072, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.GOOGLE, "text-embedding-004", 768, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.GOOGLE, "textembedding-gecko@003", 768, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.VOYAGE, "voyage-large-2-instruct", 1024, _LEGACY),
|
||||
_cloud_spec(EmbeddingProvider.VOYAGE, "voyage-light-2-instruct", 1024, _LEGACY),
|
||||
)
|
||||
|
||||
|
||||
def embedding_model_match_key(
|
||||
provider_type: EmbeddingProvider | None, model_name: str
|
||||
) -> tuple[EmbeddingProvider | None, str]:
|
||||
"""The fold that names indexes, so case, punctuation and whitespace variants
|
||||
of a model name match."""
|
||||
return provider_type, clean_model_name(model_name.strip())
|
||||
|
||||
|
||||
_SPECS_BY_MATCH_KEY = {
|
||||
embedding_model_match_key(spec.provider_type, spec.model_name): spec
|
||||
for spec in EMBEDDING_MODEL_SPECS
|
||||
}
|
||||
if len(_SPECS_BY_MATCH_KEY) != len(EMBEDDING_MODEL_SPECS):
|
||||
raise ValueError("Two embedding model specs share a match key")
|
||||
|
||||
|
||||
def find_embedding_model_spec(
|
||||
provider_type: EmbeddingProvider | None, model_name: str
|
||||
) -> EmbeddingModelSpec | None:
|
||||
"""The SELECTABLE or LEGACY spec for ``embedding_model_match_key``, or None."""
|
||||
return _SPECS_BY_MATCH_KEY.get(embedding_model_match_key(provider_type, model_name))
|
||||
|
||||
|
||||
def get_local_model_spec(model_name: str) -> EmbeddingModelSpec | None:
|
||||
"""The spec the model server loads ``model_name`` with: only the exact name of
|
||||
a pinned SELECTABLE self-hosted entry. Any other name (legacy, custom, a case
|
||||
variant) returns None and keeps the legacy load."""
|
||||
for spec in EMBEDDING_MODEL_SPECS:
|
||||
if (
|
||||
spec.provider_type is None
|
||||
and spec.status == EmbeddingModelStatus.SELECTABLE
|
||||
and spec.hf_revision is not None
|
||||
and spec.model_name == model_name
|
||||
):
|
||||
return spec
|
||||
return None
|
||||
|
||||
|
||||
def selectable_embedding_model_specs() -> tuple[EmbeddingModelSpec, ...]:
|
||||
"""Return the SELECTABLE entries, in registry order."""
|
||||
return tuple(
|
||||
spec
|
||||
for spec in EMBEDDING_MODEL_SPECS
|
||||
if spec.status == EmbeddingModelStatus.SELECTABLE
|
||||
)
|
||||
@@ -8,3 +8,9 @@ def batch_list(
|
||||
batch_size: int,
|
||||
) -> list[list[T]]:
|
||||
return [lst[i : i + batch_size] for i in range(0, len(lst), batch_size)]
|
||||
|
||||
|
||||
def clean_model_name(model_str: str) -> str:
|
||||
"""Fold a model name into the form used in index names
|
||||
(`danswer_chunk_<cleaned>`), so the output must never change."""
|
||||
return model_str.replace("/", "_").replace("-", "_").replace(".", "_").lower()
|
||||
@@ -2,16 +2,13 @@ import json
|
||||
import math
|
||||
import urllib.request
|
||||
|
||||
from onyx.configs.model_configs import (
|
||||
ASYM_QUERY_PREFIX,
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
DOC_EMBEDDING_DIM,
|
||||
)
|
||||
from shared_configs.configs import (
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
DOC_EMBEDDING_CONTEXT_SIZE,
|
||||
MODEL_SERVER_HOST,
|
||||
MODEL_SERVER_PORT,
|
||||
)
|
||||
from shared_configs.embedding_models import EmbeddingModelSpec, get_local_model_spec
|
||||
from shared_configs.enums import EmbedTextType
|
||||
from shared_configs.model_server_models import EmbedRequest, EmbedResponse
|
||||
|
||||
@@ -22,16 +19,18 @@ _HTTP_POST_METHOD = "POST"
|
||||
_JSON_HEADERS = {"Content-Type": "application/json"}
|
||||
_SAMPLE_TEXT = "hello world"
|
||||
_REQUEST_TIMEOUT_SECONDS = 120
|
||||
# float32 on CPU gives norm 1.0. bf16 on a GPU normalizes in bf16: up to ~0.4% off.
|
||||
_UNIT_NORM_TOLERANCE = 1e-2
|
||||
|
||||
|
||||
def _embed_sample_text() -> EmbedResponse:
|
||||
def _embed_sample_text(spec: EmbeddingModelSpec) -> EmbedResponse:
|
||||
embed_request = EmbedRequest(
|
||||
texts=[_SAMPLE_TEXT],
|
||||
model_name=DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
model_name=spec.model_name,
|
||||
max_context_length=DOC_EMBEDDING_CONTEXT_SIZE,
|
||||
normalize_embeddings=True,
|
||||
normalize_embeddings=spec.normalize,
|
||||
text_type=EmbedTextType.QUERY,
|
||||
manual_query_prefix=ASYM_QUERY_PREFIX,
|
||||
manual_query_prefix=spec.query_prefix,
|
||||
)
|
||||
request = urllib.request.Request(
|
||||
_EMBEDDING_ENDPOINT,
|
||||
@@ -44,11 +43,19 @@ def _embed_sample_text() -> EmbedResponse:
|
||||
|
||||
|
||||
def test_default_model_server_embeddings_are_finite() -> None:
|
||||
response = _embed_sample_text()
|
||||
"""The default model of fresh installs, which the image bundles, embeds with
|
||||
no network access."""
|
||||
spec = get_local_model_spec(DEFAULT_DOCUMENT_ENCODER_MODEL)
|
||||
assert spec is not None
|
||||
response = _embed_sample_text(spec)
|
||||
|
||||
assert len(response.embeddings) == 1
|
||||
assert len(response.embeddings[0]) == DOC_EMBEDDING_DIM
|
||||
assert all(math.isfinite(value) for value in response.embeddings[0])
|
||||
embedding = response.embeddings[0]
|
||||
assert len(embedding) == spec.model_dim
|
||||
assert all(math.isfinite(value) for value in embedding)
|
||||
if spec.normalize:
|
||||
norm = math.sqrt(sum(value * value for value in embedding))
|
||||
assert abs(norm - 1.0) < _UNIT_NORM_TOLERANCE
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
|
||||
@@ -7,6 +7,8 @@ from tenacity import (
|
||||
)
|
||||
|
||||
from onyx.natural_language_processing.search_nlp_models import EmbeddingModel
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import EmbeddingModelSpec, get_local_model_spec
|
||||
from shared_configs.enums import EmbedTextType
|
||||
from shared_configs.model_server_models import EmbeddingProvider
|
||||
from tests.utils.secret_names import TestSecret
|
||||
@@ -69,8 +71,41 @@ def test_cohere_embedding(cohere_embedding_model: EmbeddingModel) -> None:
|
||||
_run_embeddings(TOO_LONG_SAMPLE, cohere_embedding_model, 384)
|
||||
|
||||
|
||||
def _default_model_spec() -> EmbeddingModelSpec:
|
||||
# The default self-hosted model, baked into the model-server image.
|
||||
spec = get_local_model_spec(DEFAULT_DOCUMENT_ENCODER_MODEL)
|
||||
assert spec is not None
|
||||
return spec
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def local_default_embedding_model() -> EmbeddingModel:
|
||||
spec = _default_model_spec()
|
||||
return EmbeddingModel(
|
||||
server_host="localhost",
|
||||
server_port=9000,
|
||||
model_name=spec.model_name,
|
||||
normalize=spec.normalize,
|
||||
query_prefix=spec.query_prefix,
|
||||
passage_prefix=spec.passage_prefix,
|
||||
api_key=None,
|
||||
provider_type=None,
|
||||
api_url=None,
|
||||
)
|
||||
|
||||
|
||||
def test_local_default_embedding(
|
||||
local_default_embedding_model: EmbeddingModel,
|
||||
) -> None:
|
||||
model_dim = _default_model_spec().model_dim
|
||||
_run_embeddings(VALID_SAMPLE, local_default_embedding_model, model_dim)
|
||||
_run_embeddings(TOO_LONG_SAMPLE, local_default_embedding_model, model_dim)
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def local_nomic_embedding_model() -> EmbeddingModel:
|
||||
# Legacy model. It is no longer baked into the model-server image, so the
|
||||
# first request downloads it from Hugging Face.
|
||||
return EmbeddingModel(
|
||||
server_host="localhost",
|
||||
server_port=9000,
|
||||
@@ -91,9 +126,9 @@ def test_local_nomic_embedding(local_nomic_embedding_model: EmbeddingModel) -> N
|
||||
|
||||
@pytest.fixture
|
||||
def local_e5_small_embedding_model() -> EmbeddingModel:
|
||||
# Unlike nomic (pre-baked into the image), e5-small is not in the image, so the
|
||||
# first request forces the model server to download it from HuggingFace at
|
||||
# runtime -- exercising the outbound-TLS path that the custom-CA bundle governs.
|
||||
# e5-small is not in the image, so the first request forces the model server
|
||||
# to download it from HuggingFace at runtime -- exercising the outbound-TLS
|
||||
# path that the custom-CA bundle governs.
|
||||
return EmbeddingModel(
|
||||
server_host="localhost",
|
||||
server_port=9000,
|
||||
|
||||
@@ -58,8 +58,8 @@ from onyx.db.search_settings import (
|
||||
)
|
||||
from onyx.error_handling.error_codes import OnyxErrorCode
|
||||
from onyx.error_handling.exceptions import OnyxError
|
||||
from onyx.natural_language_processing.search_nlp_models import clean_model_name
|
||||
from shared_configs.configs import ALT_INDEX_SUFFIX
|
||||
from shared_configs.utils import clean_model_name
|
||||
from tests.external_dependency_unit.conftest import create_test_user, delete_test_user
|
||||
from tests.external_dependency_unit.indexing_helpers import (
|
||||
cleanup_cc_pair,
|
||||
|
||||
@@ -12,6 +12,7 @@ class DocumentSearchManager:
|
||||
def search_documents(
|
||||
query: str,
|
||||
user_performing_action: DATestUser,
|
||||
hybrid_alpha: float | None = None,
|
||||
) -> list[str]:
|
||||
"""
|
||||
Search for documents using the EE search API.
|
||||
@@ -19,6 +20,7 @@ class DocumentSearchManager:
|
||||
Args:
|
||||
query: The search query string
|
||||
user_performing_action: The user performing the search (for auth)
|
||||
hybrid_alpha: 1.0 for a pure vector search. None keeps the default.
|
||||
|
||||
Returns:
|
||||
A list of document content strings (blurbs) from the search results
|
||||
@@ -27,6 +29,7 @@ class DocumentSearchManager:
|
||||
search_query=query,
|
||||
filters=None,
|
||||
stream=False,
|
||||
hybrid_alpha=hybrid_alpha,
|
||||
)
|
||||
result = client.post(
|
||||
url=f"{API_SERVER_URL}/search/send-search-message",
|
||||
|
||||
@@ -74,6 +74,7 @@ class ReindexPortManager:
|
||||
vector_quantization: str | None = None,
|
||||
passage_prefix: str | None = None,
|
||||
index_name: str | None = None,
|
||||
settings_overrides: dict[str, Any] | None = None,
|
||||
) -> httpx.Response:
|
||||
"""Reindex to the current embedding model (a new ALT index). With no vector
|
||||
setting changed, the port copies the stored vectors; a changed
|
||||
@@ -91,7 +92,10 @@ class ReindexPortManager:
|
||||
|
||||
Leaving `enable_contextual_rag` / `contextual_rag_model_configuration_id` unset
|
||||
preserves whatever the tenant already has, so a reindex that isn't testing
|
||||
contextual RAG can't silently disable it. Pass either explicitly to change it."""
|
||||
contextual RAG can't silently disable it. Pass either explicitly to change it.
|
||||
|
||||
`settings_overrides` replaces payload fields, for example the model fields of
|
||||
another target model."""
|
||||
if acknowledged_wont_port_cc_pair_ids is None:
|
||||
acknowledged_wont_port_cc_pair_ids = (
|
||||
ReindexPortManager.wont_port_cc_pair_ids(
|
||||
@@ -129,6 +133,7 @@ class ReindexPortManager:
|
||||
"contextual_rag_model_configuration_id": contextual_rag_model_configuration_id,
|
||||
"acknowledged_wont_port_cc_pair_ids": acknowledged_wont_port_cc_pair_ids,
|
||||
}
|
||||
payload.update(settings_overrides or {})
|
||||
return client.post(
|
||||
f"{SEARCH_SETTINGS_URL}/set-new-search-settings",
|
||||
json=payload,
|
||||
|
||||
Whitespace-only changes.
@@ -0,0 +1,58 @@
|
||||
# Manual embedding model tests
|
||||
|
||||
Opt-in suites for the selectable embedding models. CI never collects
|
||||
`backend/tests/manual`, and each suite skips unless its gate env var is `true`.
|
||||
The suites read keys from plain env vars only. Do not put a gate in
|
||||
`backend/.test.env`: pytest loads that file on every run.
|
||||
|
||||
| Suite | Gate env var | Needs |
|
||||
|---|---|---|
|
||||
| `test_self_hosted_embedding_models.py` | `ONYX_RUN_SELF_HOSTED_EMBEDDING_TESTS` | Internet for the first download (about 3.2 GB). About 8 GB of free RAM for Nemotron. No keys, no services. |
|
||||
| `test_cloud_embedding_models_live.py` | `ONYX_RUN_CLOUD_EMBEDDING_TESTS` | Provider keys. No services. Costs less than 0.10 USD. |
|
||||
| `test_embedding_model_switch_e2e.py` | `ONYX_EMBEDDING_E2E_ALLOW_MUTATION` | A disposable Onyx stack with EE search. **Changes the stack.** |
|
||||
|
||||
Key env vars. A cloud model without its key skips: `COHERE_API_KEY`,
|
||||
`OPENAI_API_KEY`, `VOYAGE_API_KEY`, `VERTEX_CREDENTIALS` (the path to a Google
|
||||
service-account JSON file). Keep them, and the e2e admin login
|
||||
(`ONYX_E2E_ADMIN_EMAIL`, `ONYX_E2E_ADMIN_PASSWORD`), in the gitignored
|
||||
`.vscode/.env.embedding-tests`, not on the command line.
|
||||
|
||||
## Commands
|
||||
|
||||
Run each command from the repository root. Add `-k <model>` to run one model.
|
||||
|
||||
```bash
|
||||
ONYX_RUN_SELF_HOSTED_EMBEDDING_TESTS=true \
|
||||
uv run pytest -v -rs backend/tests/manual/embedding_models/test_self_hosted_embedding_models.py
|
||||
|
||||
ONYX_RUN_CLOUD_EMBEDDING_TESTS=true uv run --env-file .vscode/.env.embedding-tests \
|
||||
pytest -v -rs backend/tests/manual/embedding_models/test_cloud_embedding_models_live.py
|
||||
|
||||
ONYX_EMBEDDING_E2E_ALLOW_MUTATION=true API_SERVER_PORT=18080 \
|
||||
ONYX_EMBEDDING_E2E_MODELS=ibm-granite/granite-embedding-97m-multilingual-r2,embed-v5.0-fast \
|
||||
uv run --env-file .vscode/.env.embedding-tests \
|
||||
pytest -v -s -rs backend/tests/manual/embedding_models/test_embedding_model_switch_e2e.py
|
||||
```
|
||||
|
||||
## End to end
|
||||
|
||||
The e2e suite re-embeds every document on the stack once for each target. It
|
||||
saves the provider keys on the stack. The last target stays live, and the
|
||||
upgrade-only rule then blocks a return to a legacy model. Use a disposable
|
||||
stack, or take a Postgres and OpenSearch snapshot first.
|
||||
|
||||
- `API_SERVER_HOST`, `API_SERVER_PORT`: the target api_server. The suite refuses
|
||||
port 8080 (the normal dev stack) unless `ONYX_EMBEDDING_E2E_ALLOW_PORT_8080=true`.
|
||||
- `ONYX_E2E_ADMIN_EMAIL`, `ONYX_E2E_ADMIN_PASSWORD`: an existing admin. The suite
|
||||
never creates users or resets the database.
|
||||
- `ONYX_EMBEDDING_E2E_MODELS`: optional. Comma-separated exact model names, run
|
||||
in this order. The default is every selectable model.
|
||||
- `ONYX_EMBEDDING_E2E_TIMEOUT_SECONDS`: optional wait for each swap. The default
|
||||
is 3600.
|
||||
|
||||
Start the stack with `ENABLE_PAID_ENTERPRISE_EDITION_FEATURES=true`: the search
|
||||
check uses the EE search API. The suite never consents to connector deletion,
|
||||
so the API refuses to re-index a stack with INVALID connectors. Fix or delete
|
||||
them first. To check the same-model re-index of a legacy model, start with a
|
||||
stack that uses a legacy model, for example nomic. Do not use `-n`: the tests
|
||||
run in file order.
|
||||
Whitespace-only changes.
@@ -0,0 +1,28 @@
|
||||
"""Cloud embedding keys for the manual suites, from plain env vars only."""
|
||||
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
|
||||
KEY_ENV_BY_PROVIDER: dict[EmbeddingProvider, str] = {
|
||||
EmbeddingProvider.COHERE: "COHERE_API_KEY",
|
||||
EmbeddingProvider.OPENAI: "OPENAI_API_KEY",
|
||||
EmbeddingProvider.VOYAGE: "VOYAGE_API_KEY",
|
||||
# The path to a Google service-account JSON file.
|
||||
EmbeddingProvider.GOOGLE: "VERTEX_CREDENTIALS",
|
||||
}
|
||||
|
||||
|
||||
def provider_api_key(provider: EmbeddingProvider) -> str:
|
||||
"""The api_key that Onyx stores for ``provider``. Skips the test if unset."""
|
||||
env_name = KEY_ENV_BY_PROVIDER[provider]
|
||||
value = os.environ.get(env_name, "").strip()
|
||||
if not value:
|
||||
pytest.skip(f"{env_name} is not set.")
|
||||
if provider == EmbeddingProvider.GOOGLE:
|
||||
# Onyx stores the service-account JSON itself as the Google api_key.
|
||||
return Path(value).expanduser().read_text()
|
||||
return value
|
||||
@@ -0,0 +1,98 @@
|
||||
"""Live checks for the SELECTABLE cloud embedding models.
|
||||
|
||||
Opt in with ONYX_RUN_CLOUD_EMBEDDING_TESTS=true. A model whose key env var is
|
||||
unset (see provider_env.py) skips. A full run costs less than 0.10 USD. Calls
|
||||
go through EmbeddingModel.encode, the path that indexing and queries use, so no
|
||||
Onyx service has to run.
|
||||
"""
|
||||
|
||||
import os
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
|
||||
from shared_configs.embedding_models import (
|
||||
EmbeddingModelSpec,
|
||||
selectable_embedding_model_specs,
|
||||
)
|
||||
from shared_configs.enums import EmbedTextType
|
||||
from tests.manual.embedding_models.provider_env import provider_api_key
|
||||
|
||||
pytestmark = pytest.mark.skipif(
|
||||
os.environ.get("ONYX_RUN_CLOUD_EMBEDDING_TESTS") != "true",
|
||||
reason="Set ONYX_RUN_CLOUD_EMBEDDING_TESTS=true to run.",
|
||||
)
|
||||
|
||||
CLOUD_SPECS = [
|
||||
spec
|
||||
for spec in selectable_embedding_model_specs()
|
||||
if spec.provider_type is not None
|
||||
]
|
||||
|
||||
TOPICAL_PASSAGES: dict[str, str] = {
|
||||
"pto": "Full-time employees accrue 1.5 days of paid time off per month, up to "
|
||||
"30 days per year. Unused vacation days roll over until the end of March.",
|
||||
"expenses": "Expense reports and receipts for reimbursement must be submitted "
|
||||
"in the finance portal within 30 days of the purchase date, otherwise they "
|
||||
"will be rejected.",
|
||||
"vpn": "To reach internal services from home, install the corporate VPN "
|
||||
"client, sign in with SSO, and approve the push notification on your phone.",
|
||||
"k8s": "Our Kubernetes clusters use the cluster autoscaler; worker nodes are "
|
||||
"added when pending pods cannot be scheduled because of CPU or memory "
|
||||
"pressure.",
|
||||
"retirement": "The company matches 401(k) retirement contributions dollar for "
|
||||
"dollar up to 4% of salary, vesting immediately.",
|
||||
"parking": "Visitors can park in lot B; badge holders may use the underground "
|
||||
"garage after 6pm.",
|
||||
"oncall": "The on-call engineer must acknowledge PagerDuty alerts within 5 "
|
||||
"minutes and open an incident channel for any SEV1.",
|
||||
"laptop": "Replacement laptops are issued every three years; request one "
|
||||
"through the IT helpdesk with your asset tag.",
|
||||
}
|
||||
QUERY_ANSWERS: dict[str, str] = {
|
||||
"How many vacation days do I get each year?": "pto",
|
||||
"deadline to hand in receipts to get my money back": "expenses",
|
||||
"how do I access internal tools while working remotely": "vpn",
|
||||
"how do we add more machines when pods can't be scheduled": "k8s",
|
||||
"does my employer match my retirement savings": "retirement",
|
||||
# German: "How do I connect to the company VPN from home?"
|
||||
"Wie verbinde ich mich von zu Hause mit dem Firmen-VPN?": "vpn",
|
||||
}
|
||||
# Filler first, so the topical passages come after the first provider request
|
||||
# (Cohere takes 96 texts, Voyage 128, Gemini 2 one). If Onyx joins the provider
|
||||
# responses in the wrong order, the ranking check fails.
|
||||
PASSAGES = [
|
||||
f"Cafeteria note #{i}: the kitchen serves soup, salad and dessert number {i % 7}."
|
||||
for i in range(122)
|
||||
] + list(TOPICAL_PASSAGES.values())
|
||||
|
||||
|
||||
@pytest.mark.parametrize("spec", CLOUD_SPECS, ids=lambda spec: spec.model_name)
|
||||
def test_embeds_in_order_with_registry_dim(spec: EmbeddingModelSpec) -> None:
|
||||
from onyx.natural_language_processing.search_nlp_models import EmbeddingModel
|
||||
|
||||
provider = spec.provider_type
|
||||
assert provider is not None
|
||||
model = EmbeddingModel(
|
||||
# Not used: cloud models do not call the model server.
|
||||
server_host="localhost",
|
||||
server_port=9000,
|
||||
model_name=spec.model_name,
|
||||
normalize=spec.normalize,
|
||||
query_prefix=None,
|
||||
passage_prefix=None,
|
||||
api_key=provider_api_key(provider),
|
||||
api_url=None,
|
||||
provider_type=provider,
|
||||
)
|
||||
passages = np.asarray(model.encode(PASSAGES, EmbedTextType.PASSAGE))
|
||||
queries = np.asarray(model.encode(list(QUERY_ANSWERS), EmbedTextType.QUERY))
|
||||
for vectors, count in ((passages, len(PASSAGES)), (queries, len(QUERY_ANSWERS))):
|
||||
assert vectors.shape == (count, spec.model_dim)
|
||||
assert np.isfinite(vectors).all()
|
||||
assert (np.linalg.norm(vectors, axis=1) > 0).all()
|
||||
|
||||
passages /= np.linalg.norm(passages, axis=1, keepdims=True)
|
||||
queries /= np.linalg.norm(queries, axis=1, keepdims=True)
|
||||
best = [PASSAGES[i] for i in (queries @ passages.T).argmax(axis=1)]
|
||||
assert best == [TOPICAL_PASSAGES[key] for key in QUERY_ANSWERS.values()]
|
||||
@@ -0,0 +1,301 @@
|
||||
"""End-to-end embedding model switches against a live, disposable Onyx stack.
|
||||
|
||||
WARNING: this suite changes the target stack. Read README.md before you run it.
|
||||
Opt in with ONYX_EMBEDDING_E2E_ALLOW_MUTATION=true. The tests run in file
|
||||
order, so do not use -n:
|
||||
1. The API refuses each LEGACY self-hosted model as a new target.
|
||||
2. The API accepts a re-index to the live model. The suite cancels it.
|
||||
3. For each target model: re-index to it, wait for the swap, and check that a
|
||||
pure vector search finds each seeded fact first.
|
||||
"""
|
||||
|
||||
import os
|
||||
import time
|
||||
from collections.abc import Generator
|
||||
from datetime import datetime, timezone
|
||||
from typing import Any
|
||||
|
||||
import httpx
|
||||
import pytest
|
||||
|
||||
from onyx.configs.constants import DocumentSource
|
||||
from onyx.error_handling.error_codes import OnyxErrorCode
|
||||
from onyx.server.documents.models import FileUploadResponse
|
||||
from shared_configs.embedding_models import (
|
||||
EMBEDDING_MODEL_SPECS,
|
||||
EmbeddingModelSpec,
|
||||
EmbeddingModelStatus,
|
||||
find_embedding_model_spec,
|
||||
selectable_embedding_model_specs,
|
||||
)
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
from tests.integration.common_utils import http_client
|
||||
from tests.integration.common_utils.constants import (
|
||||
API_SERVER_PORT,
|
||||
API_SERVER_URL,
|
||||
GENERAL_HEADERS,
|
||||
)
|
||||
from tests.integration.common_utils.http_client import client
|
||||
from tests.integration.common_utils.managers.cc_pair import CCPairManager
|
||||
from tests.integration.common_utils.managers.document_search import (
|
||||
DocumentSearchManager,
|
||||
)
|
||||
from tests.integration.common_utils.managers.file import FileManager
|
||||
from tests.integration.common_utils.managers.reindex_port import ReindexPortManager
|
||||
from tests.integration.common_utils.managers.user import UserManager
|
||||
from tests.integration.common_utils.test_models import DATestUser
|
||||
from tests.manual.embedding_models.provider_env import provider_api_key
|
||||
|
||||
pytestmark = pytest.mark.skipif(
|
||||
os.environ.get("ONYX_EMBEDDING_E2E_ALLOW_MUTATION") != "true",
|
||||
reason="Changes the target stack. Set ONYX_EMBEDDING_E2E_ALLOW_MUTATION=true.",
|
||||
)
|
||||
|
||||
SELECTABLE_BY_NAME = {
|
||||
spec.model_name: spec for spec in selectable_embedding_model_specs()
|
||||
}
|
||||
# Comma-separated exact model names, run in this order. The last one stays live.
|
||||
_MODEL_NAMES = os.environ.get("ONYX_EMBEDDING_E2E_MODELS", "").split(",")
|
||||
TARGETS = [
|
||||
SELECTABLE_BY_NAME[name.strip()] for name in _MODEL_NAMES if name.strip()
|
||||
] or list(SELECTABLE_BY_NAME.values())
|
||||
LEGACY_SELF_HOSTED = [
|
||||
spec
|
||||
for spec in EMBEDDING_MODEL_SPECS
|
||||
if spec.status == EmbeddingModelStatus.LEGACY and spec.provider_type is None
|
||||
]
|
||||
SWAP_TIMEOUT_SECONDS = float(
|
||||
os.environ.get("ONYX_EMBEDDING_E2E_TIMEOUT_SECONDS", "3600")
|
||||
)
|
||||
# A cloud target is probed before the API accepts it, and the first query after
|
||||
# a swap can load the new model on the model server.
|
||||
HTTP_TIMEOUT = httpx.Timeout(900.0, connect=10.0)
|
||||
|
||||
# (content, query). Each query is a paraphrase with little word overlap, so only
|
||||
# the vectors can match it. The search still mixes in keyword scores, so a query
|
||||
# must share no words with the other facts either.
|
||||
FACTS: list[tuple[str, str]] = [
|
||||
(
|
||||
"Employees of the Halvorsen Robotics lab must wear anti-static wrist "
|
||||
"straps whenever they handle the prototype circuit boards.",
|
||||
"What protective gear does Halvorsen Robotics require when staff touch "
|
||||
"unfinished electronics?",
|
||||
),
|
||||
(
|
||||
"The Pinecrest community garden waters its tomato beds with rainwater "
|
||||
"collected in three large barrels behind the tool shed.",
|
||||
"How are the vegetable plots at Pinecrest irrigated?",
|
||||
),
|
||||
(
|
||||
"At Ostrander Middle School, students who forget their lunch can get a "
|
||||
"free sandwich from the front office before noon.",
|
||||
"What happens at Ostrander when a pupil arrives without the midday meal?",
|
||||
),
|
||||
(
|
||||
"The Vellmar ferry stops running across the bay whenever wind speeds "
|
||||
"exceed forty knots.",
|
||||
"When is the Vellmar boat service suspended because of the weather?",
|
||||
),
|
||||
(
|
||||
"Kestrel Analytics reimburses staff for up to two hundred dollars of "
|
||||
"home office furniture each calendar year.",
|
||||
"How much can Kestrel Analytics workers claim back each year for desks "
|
||||
"and chairs they buy for remote work?",
|
||||
),
|
||||
]
|
||||
|
||||
|
||||
@pytest.fixture(scope="module", autouse=True)
|
||||
def _live_api_server() -> Generator[None, None, None]:
|
||||
"""Point the shared Manager client at the target stack."""
|
||||
# The Managers fall back to port 8080, the port of the normal dev stack.
|
||||
if (
|
||||
API_SERVER_PORT == "8080"
|
||||
and os.environ.get("ONYX_EMBEDDING_E2E_ALLOW_PORT_8080") != "true"
|
||||
):
|
||||
pytest.fail(
|
||||
"Set API_SERVER_PORT to the api_server of a disposable stack. If the "
|
||||
"stack on port 8080 is disposable, set "
|
||||
"ONYX_EMBEDDING_E2E_ALLOW_PORT_8080=true."
|
||||
)
|
||||
with httpx.Client(
|
||||
transport=http_client.RetryingTransport(), timeout=HTTP_TIMEOUT
|
||||
) as live_client:
|
||||
http_client.set_test_client(live_client)
|
||||
yield
|
||||
|
||||
|
||||
@pytest.fixture(scope="module")
|
||||
def admin() -> DATestUser:
|
||||
"""An existing admin. The suite never creates users or resets the database."""
|
||||
return UserManager.login_as_user(
|
||||
DATestUser(
|
||||
id="",
|
||||
email=os.environ["ONYX_E2E_ADMIN_EMAIL"],
|
||||
password=os.environ["ONYX_E2E_ADMIN_PASSWORD"],
|
||||
headers=dict(GENERAL_HEADERS),
|
||||
# login_as_user sets the real values from /me.
|
||||
is_admin=False,
|
||||
is_active=True,
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
@pytest.fixture(scope="module")
|
||||
def seeded_facts(admin: DATestUser) -> Generator[None, None, None]:
|
||||
"""Index FACTS once through a File connector. Each switch re-embeds them.
|
||||
|
||||
A File connector needs no license tier, unlike ingestion API keys. A clean-up
|
||||
failure fails the teardown, so leftovers show in the report.
|
||||
"""
|
||||
response = FileManager.upload_connector_files(
|
||||
[(f"fact_{i}.txt", content.encode()) for i, (content, _) in enumerate(FACTS)],
|
||||
admin,
|
||||
content_type="text/plain",
|
||||
)
|
||||
response.raise_for_status()
|
||||
uploaded = FileUploadResponse(**response.json())
|
||||
started = datetime.now(timezone.utc)
|
||||
cc_pair = CCPairManager.create_from_scratch(
|
||||
user_performing_action=admin,
|
||||
source=DocumentSource.FILE,
|
||||
connector_specific_config={
|
||||
"file_locations": uploaded.file_paths,
|
||||
"file_names": uploaded.file_names,
|
||||
"zip_metadata_file_id": None,
|
||||
},
|
||||
)
|
||||
try:
|
||||
CCPairManager.wait_for_indexing_completion(
|
||||
cc_pair=cc_pair, after=started, user_performing_action=admin
|
||||
)
|
||||
# Fails before the first switch if the stack has no EE search API.
|
||||
DocumentSearchManager.search_documents(FACTS[0][1], admin, hybrid_alpha=1.0)
|
||||
yield
|
||||
finally:
|
||||
# The deletion task removes the seeded documents.
|
||||
CCPairManager.delete(cc_pair, user_performing_action=admin)
|
||||
|
||||
|
||||
def _target_settings(spec: EmbeddingModelSpec) -> dict[str, Any]:
|
||||
"""The search settings fields that select ``spec``."""
|
||||
return {
|
||||
"model_name": spec.model_name,
|
||||
"model_dim": spec.model_dim,
|
||||
"normalize": spec.normalize,
|
||||
"query_prefix": spec.query_prefix,
|
||||
"passage_prefix": spec.passage_prefix,
|
||||
"provider_type": spec.provider_type.value if spec.provider_type else None,
|
||||
"reduced_dimension": None,
|
||||
}
|
||||
|
||||
|
||||
def _connect_provider(provider: EmbeddingProvider, admin: DATestUser) -> None:
|
||||
"""Save the key from the provider's env var on the stack. Skips if unset."""
|
||||
response = client.put(
|
||||
f"{API_SERVER_URL}/admin/embedding/embedding-provider",
|
||||
json={
|
||||
"provider_type": provider.value,
|
||||
"api_key": provider_api_key(provider),
|
||||
"api_key_changed": True,
|
||||
},
|
||||
headers=admin.headers,
|
||||
)
|
||||
assert response.is_success, response.text
|
||||
|
||||
|
||||
def _wait_for_swap(original_index_name: str, admin: DATestUser) -> dict[str, Any]:
|
||||
"""Poll until the new index is live.
|
||||
|
||||
A FAILED port unit retries on its own. A PAUSED unit waits for an operator,
|
||||
so it fails at once.
|
||||
"""
|
||||
deadline = time.monotonic() + SWAP_TIMEOUT_SECONDS
|
||||
while time.monotonic() < deadline:
|
||||
current = ReindexPortManager.get_current_settings(admin)
|
||||
if current["index_name"] != original_index_name:
|
||||
return current
|
||||
progress = ReindexPortManager.get_progress(admin)
|
||||
assert not progress.paused, (
|
||||
f"Port paused: {ReindexPortManager.get_errors(admin)}"
|
||||
)
|
||||
print(f"Waiting for the swap: {progress}")
|
||||
time.sleep(30)
|
||||
pytest.fail(
|
||||
f"No swap within {SWAP_TIMEOUT_SECONDS:.0f}s. Errors: "
|
||||
f"{ReindexPortManager.get_errors(admin)}"
|
||||
)
|
||||
|
||||
|
||||
def _missed_queries(admin: DATestUser) -> list[str]:
|
||||
"""The fact queries whose top pure vector search hit is not their fact."""
|
||||
return [
|
||||
query
|
||||
for content, query in FACTS
|
||||
if DocumentSearchManager.search_documents(query, admin, hybrid_alpha=1.0)[:1]
|
||||
!= [content]
|
||||
]
|
||||
|
||||
|
||||
@pytest.mark.parametrize("legacy", LEGACY_SELF_HOSTED, ids=lambda spec: spec.model_name)
|
||||
def test_legacy_target_is_rejected(
|
||||
legacy: EmbeddingModelSpec, admin: DATestUser
|
||||
) -> None:
|
||||
current = ReindexPortManager.get_current_settings(admin)
|
||||
if (
|
||||
current.get("provider_type") is None
|
||||
and find_embedding_model_spec(None, current["model_name"]) == legacy
|
||||
):
|
||||
pytest.skip("This legacy model is live. A same-model re-index is allowed.")
|
||||
response = ReindexPortManager.start_reindex_response(
|
||||
admin,
|
||||
acknowledged_wont_port_cc_pair_ids=[],
|
||||
settings_overrides=_target_settings(legacy),
|
||||
)
|
||||
if response.is_success:
|
||||
# Do not leave a re-index to a legacy model running.
|
||||
ReindexPortManager.cancel_reindex(admin)
|
||||
assert response.json().get("error_code") == OnyxErrorCode.INVALID_INPUT.code, (
|
||||
response.text
|
||||
)
|
||||
|
||||
|
||||
def test_same_model_reindex_is_accepted(admin: DATestUser) -> None:
|
||||
# An empty consent list: the API refuses the re-index if it would delete
|
||||
# connectors (INVALID status), so the suite never deletes them.
|
||||
ReindexPortManager.wait_for_reindex_accepted(
|
||||
admin, acknowledged_wont_port_cc_pair_ids=[]
|
||||
)
|
||||
ReindexPortManager.cancel_reindex(admin)
|
||||
|
||||
|
||||
@pytest.mark.usefixtures("seeded_facts")
|
||||
@pytest.mark.parametrize("spec", TARGETS, ids=lambda spec: spec.model_name)
|
||||
def test_switch_to_model(spec: EmbeddingModelSpec, admin: DATestUser) -> None:
|
||||
provider = spec.provider_type
|
||||
if provider is not None:
|
||||
_connect_provider(provider, admin)
|
||||
original_index_name = ReindexPortManager.get_current_settings(admin)["index_name"]
|
||||
ReindexPortManager.wait_for_reindex_accepted(
|
||||
admin,
|
||||
acknowledged_wont_port_cc_pair_ids=[],
|
||||
settings_overrides=_target_settings(spec),
|
||||
)
|
||||
try:
|
||||
current = _wait_for_swap(original_index_name, admin)
|
||||
except BaseException:
|
||||
# Do not leave a failed re-index running on the stack.
|
||||
ReindexPortManager.cancel_reindex(admin)
|
||||
raise
|
||||
assert (current["model_name"], current["model_dim"]) == (
|
||||
spec.model_name,
|
||||
spec.model_dim,
|
||||
)
|
||||
|
||||
# The new index and the model server can take a short time to settle.
|
||||
deadline = time.monotonic() + 60
|
||||
missed = _missed_queries(admin)
|
||||
while missed and time.monotonic() < deadline:
|
||||
time.sleep(10)
|
||||
missed = _missed_queries(admin)
|
||||
assert not missed, f"Pure vector search with {spec.model_name} missed: {missed}"
|
||||
@@ -0,0 +1,132 @@
|
||||
"""Real-weights checks for the SELECTABLE self-hosted embedding models.
|
||||
|
||||
Opt in with ONYX_RUN_SELF_HOSTED_EMBEDDING_TESTS=true. The first run downloads
|
||||
about 3.2 GB of weights. Each request goes through the model server's
|
||||
process_embed_request in this process. CUDA and MPS are hidden, so the models
|
||||
run in fp32 on CPU, like the golden scores. Add -k voyage to run one model.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import os
|
||||
from collections.abc import Generator
|
||||
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
import pytest
|
||||
|
||||
from shared_configs.configs import DOC_EMBEDDING_CONTEXT_SIZE
|
||||
from shared_configs.embedding_models import (
|
||||
EmbeddingModelSpec,
|
||||
selectable_embedding_model_specs,
|
||||
)
|
||||
from shared_configs.enums import EmbedTextType
|
||||
|
||||
pytestmark = pytest.mark.skipif(
|
||||
os.environ.get("ONYX_RUN_SELF_HOSTED_EMBEDDING_TESTS") != "true",
|
||||
reason="Set ONYX_RUN_SELF_HOSTED_EMBEDDING_TESTS=true to run.",
|
||||
)
|
||||
|
||||
SELF_HOSTED_SPECS = [
|
||||
spec for spec in selectable_embedding_model_specs() if spec.provider_type is None
|
||||
]
|
||||
|
||||
RED_PLANET_QUERY = "Which planet is known as the Red Planet?"
|
||||
RED_PLANET_DOCS = [
|
||||
"Venus is often called Earth's twin because of its similar size and proximity.",
|
||||
"Mars, known for its reddish appearance, is often referred to as the Red Planet.",
|
||||
"Jupiter, the largest planet in our solar system, has a prominent red spot.",
|
||||
"Saturn, famous for its rings, is sometimes mistaken for the Red Planet.",
|
||||
]
|
||||
# fp32 cosine scores of the query against each doc, with the registry prefixes,
|
||||
# from the verified reference loader. The Onyx load matches them to 4 decimals
|
||||
# on transformers 5.14.1 and sentence-transformers 5.6.0.
|
||||
GOLDEN_SCORES: dict[str, list[float]] = {
|
||||
"ibm-granite/granite-embedding-97m-multilingual-r2": [
|
||||
0.8453,
|
||||
0.9388,
|
||||
0.9119,
|
||||
0.8907,
|
||||
],
|
||||
"voyageai/voyage-4-nano": [0.4044, 0.6517, 0.5437, 0.5342],
|
||||
"nvidia/Nemotron-3-Embed-1B-BF16": [0.2481, 0.6449, 0.4405, 0.4168],
|
||||
}
|
||||
# Embedded in the same batch as the docs, so each doc gets about 50 pad tokens.
|
||||
# If bidirectional attention ignores the padding mask, the scores move.
|
||||
PADDING_TEXT = (
|
||||
"The rover team planned a long traverse across the crater floor. Engineers "
|
||||
"checked the wheels, the power budget and the communication windows before "
|
||||
"they sent the drive commands. Scientists picked three rock targets for the "
|
||||
"arm instruments and asked for images of the layered outcrops near the rim."
|
||||
)
|
||||
|
||||
|
||||
@pytest.fixture(scope="module", autouse=True)
|
||||
def _cpu_only() -> Generator[None, None, None]:
|
||||
"""Hide CUDA and MPS, so the model server takes its CPU (fp32) path."""
|
||||
import torch
|
||||
|
||||
with pytest.MonkeyPatch.context() as monkeypatch:
|
||||
monkeypatch.setattr(torch.cuda, "is_available", lambda: False)
|
||||
monkeypatch.setattr(torch.backends.mps, "is_available", lambda: False)
|
||||
yield
|
||||
|
||||
|
||||
def _embed(
|
||||
spec: EmbeddingModelSpec, texts: list[str], text_type: EmbedTextType
|
||||
) -> npt.NDArray[np.float64]:
|
||||
from model_server.encoders import process_embed_request
|
||||
from shared_configs.model_server_models import EmbedRequest
|
||||
|
||||
request = EmbedRequest(
|
||||
texts=texts,
|
||||
model_name=spec.model_name,
|
||||
max_context_length=DOC_EMBEDDING_CONTEXT_SIZE,
|
||||
normalize_embeddings=True,
|
||||
text_type=text_type,
|
||||
manual_query_prefix=spec.query_prefix,
|
||||
manual_passage_prefix=spec.passage_prefix,
|
||||
)
|
||||
response = asyncio.run(process_embed_request(request))
|
||||
return np.asarray(response.embeddings, dtype=np.float64)
|
||||
|
||||
|
||||
def _short_name(spec: EmbeddingModelSpec) -> str:
|
||||
return spec.model_name.split("/")[-1]
|
||||
|
||||
|
||||
@pytest.mark.parametrize("spec", SELF_HOSTED_SPECS, ids=_short_name)
|
||||
def test_vectors_match_golden_scores(spec: EmbeddingModelSpec) -> None:
|
||||
query = _embed(spec, [RED_PLANET_QUERY], EmbedTextType.QUERY)
|
||||
docs = _embed(spec, [*RED_PLANET_DOCS, PADDING_TEXT], EmbedTextType.PASSAGE)
|
||||
for vectors in (query, docs):
|
||||
assert vectors.shape[1] == spec.model_dim
|
||||
assert np.isfinite(vectors).all()
|
||||
assert np.allclose(np.linalg.norm(vectors, axis=1), 1.0, atol=1e-3)
|
||||
scores = docs[: len(RED_PLANET_DOCS)] @ query[0]
|
||||
assert np.allclose(scores, GOLDEN_SCORES[spec.model_name], atol=0.01), (
|
||||
f"scores {np.round(scores, 4).tolist()}"
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize("spec", SELF_HOSTED_SPECS, ids=_short_name)
|
||||
def test_attention_is_bidirectional(spec: EmbeddingModelSpec) -> None:
|
||||
"""A change to the last token must change the output of the first token.
|
||||
|
||||
A causal model gives exactly 0. voyage-4-nano, the weakest, gave 0.0485.
|
||||
"""
|
||||
from model_server.encoders import get_embedding_model
|
||||
|
||||
model = get_embedding_model(spec.model_name, DOC_EMBEDDING_CONTEXT_SIZE)
|
||||
first_a, first_b = (
|
||||
model.encode(
|
||||
[f"{spec.passage_prefix}The quick brown fox jumps over the lazy {word}"],
|
||||
output_value="token_embeddings",
|
||||
convert_to_numpy=False,
|
||||
)[0]
|
||||
for word in ("dog", "cat")
|
||||
)
|
||||
# Each is a (tokens, hidden) matrix. One input has no padding, so row 0 is
|
||||
# the first real token. Only row 0 tells causal from bidirectional.
|
||||
assert first_a.dim() == 2 and first_b.dim() == 2
|
||||
change = (first_a[0] - first_b[0]).abs().max().item()
|
||||
assert change > 1e-3, f"Max change {change:.3g}: the attention is causal."
|
||||
@@ -0,0 +1,57 @@
|
||||
"""The images bake the default model at its pinned revision: the model-server image
|
||||
its weights, the API image its tokenizer. The API image also bakes the nomic
|
||||
tokenizer for chat token counting."""
|
||||
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import get_local_model_spec
|
||||
|
||||
_BACKEND_DIR = Path(__file__).resolve().parents[3]
|
||||
_NOMIC = "nomic-ai/nomic-embed-text-v1"
|
||||
_BAKED_NAME_PATTERN = re.compile(r"model_name_or_path='(?P<name>[^']+)'")
|
||||
_BAKE_PATTERN = re.compile(
|
||||
r"SentenceTransformer\(model_name_or_path='(?P<name>[^']+)',\s*\\?\s*"
|
||||
r"revision='(?P<revision>[^']+)',\s*trust_remote_code=False\)"
|
||||
)
|
||||
_TOKENIZER_BAKE_PATTERN = re.compile(
|
||||
r"Tokenizer\.from_pretrained\('(?P<name>[^']+)'"
|
||||
r"(?:,\s*revision='(?P<revision>[^']+)')?\)"
|
||||
)
|
||||
|
||||
|
||||
def _default_model_revision() -> str:
|
||||
spec = get_local_model_spec(DEFAULT_DOCUMENT_ENCODER_MODEL)
|
||||
assert spec is not None and spec.hf_revision is not None
|
||||
return spec.hf_revision
|
||||
|
||||
|
||||
def test_model_server_image_bakes_only_the_default_model() -> None:
|
||||
text = (_BACKEND_DIR / "Dockerfile.model_server").read_text()
|
||||
|
||||
baked = {
|
||||
match.group("name"): match.group("revision")
|
||||
for match in _BAKE_PATTERN.finditer(text)
|
||||
}
|
||||
assert baked == {DEFAULT_DOCUMENT_ENCODER_MODEL: _default_model_revision()}
|
||||
# No other model (e.g. nomic-ai/nomic-embed-text-v1) is baked.
|
||||
all_baked_names = {m.group("name") for m in _BAKED_NAME_PATTERN.finditer(text)}
|
||||
assert all_baked_names == set(baked)
|
||||
|
||||
|
||||
def test_api_image_bakes_the_tokenizers_it_loads() -> None:
|
||||
text = (_BACKEND_DIR / "Dockerfile").read_text()
|
||||
|
||||
baked = {
|
||||
match.group("name"): match.group("revision")
|
||||
for match in _TOKENIZER_BAKE_PATTERN.finditer(text)
|
||||
}
|
||||
# The default tokenizer (chat token counting, the fallback) must work offline.
|
||||
# It loads without a revision, so the bake has none.
|
||||
assert _NOMIC in baked and baked[_NOMIC] is None
|
||||
# The API server loads registry tokenizers at their pinned revision.
|
||||
assert baked.get(DEFAULT_DOCUMENT_ENCODER_MODEL) == _default_model_revision()
|
||||
for model_name, revision in baked.items():
|
||||
spec = get_local_model_spec(model_name)
|
||||
assert spec is None or revision == spec.hf_revision, model_name
|
||||
@@ -1,5 +1,8 @@
|
||||
import asyncio
|
||||
import threading
|
||||
import time
|
||||
from collections.abc import Callable, Iterator
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from typing import Any, List
|
||||
from unittest.mock import MagicMock, patch
|
||||
|
||||
@@ -12,33 +15,163 @@ from shared_configs.enums import EmbedTextType
|
||||
from shared_configs.model_server_models import EmbedRequest
|
||||
|
||||
_CUSTOM_MODEL_NAME = "custom/embedding-model"
|
||||
_NOMIC_MODEL_NAME = "nomic-ai/nomic-embed-text-v1"
|
||||
_LOAD_EMBEDDING_MODEL = "model_server.encoders.load_embedding_model"
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def _empty_model_cache() -> Iterator[None]:
|
||||
with (
|
||||
patch.object(encoders, "_GLOBAL_MODELS_DICT", {}),
|
||||
patch.object(encoders, "_ROPE_PREWARMED_TO", {}),
|
||||
patch.object(encoders, "_PENDING_MODEL_JOBS", {}),
|
||||
):
|
||||
yield
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("model_name", "expected_local_files_only"),
|
||||
("model_name", "headroom"),
|
||||
[
|
||||
(DEFAULT_DOCUMENT_ENCODER_MODEL, True),
|
||||
(_CUSTOM_MODEL_NAME, False),
|
||||
(
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
encoders.REGISTRY_MODEL_PREFIX_HEADROOM_TOKENS,
|
||||
),
|
||||
(_NOMIC_MODEL_NAME, 0),
|
||||
],
|
||||
ids=["registry-model", "legacy-model"],
|
||||
)
|
||||
def test_only_bundled_embedding_model_uses_local_files(
|
||||
model_name: str,
|
||||
expected_local_files_only: bool,
|
||||
def test_only_registry_models_get_prefix_headroom(
|
||||
model_name: str, headroom: int
|
||||
) -> None:
|
||||
model = MagicMock()
|
||||
with (
|
||||
patch("sentence_transformers.SentenceTransformer", return_value=model) as load,
|
||||
patch.object(encoders, "_GLOBAL_MODELS_DICT", {}),
|
||||
):
|
||||
encoders.get_embedding_model(model_name, max_context_length=512)
|
||||
"""The chunker does not count a registry model's query/passage prefix, so the
|
||||
prefix must not cut off the end of a full chunk."""
|
||||
with patch(_LOAD_EMBEDDING_MODEL, return_value=MagicMock()):
|
||||
for max_context_length in (512, 2048):
|
||||
model = encoders.get_embedding_model(
|
||||
model_name, max_context_length=max_context_length
|
||||
)
|
||||
assert model.max_seq_length == max_context_length + headroom
|
||||
|
||||
load.assert_called_once_with(
|
||||
model_name_or_path=model_name,
|
||||
local_files_only=expected_local_files_only,
|
||||
trust_remote_code=False,
|
||||
|
||||
def test_rope_prewarm_runs_again_only_for_a_longer_context() -> None:
|
||||
model = MagicMock()
|
||||
with patch(_LOAD_EMBEDDING_MODEL, return_value=model):
|
||||
for max_context_length in (512, 2048, 512, 2048):
|
||||
encoders.get_embedding_model(
|
||||
_NOMIC_MODEL_NAME, max_context_length=max_context_length
|
||||
)
|
||||
# The load pre-warms to 512 and the first 2048 to 2048. The rest reuse them.
|
||||
assert model.encode.call_count == 2
|
||||
|
||||
|
||||
# ---- Loading off the event loop ----
|
||||
|
||||
|
||||
def _slow_loader(
|
||||
delay_seconds: float,
|
||||
calls: list[str],
|
||||
started: threading.Event | None = None,
|
||||
) -> Callable[[str], MagicMock]:
|
||||
def load(model_name: str) -> MagicMock:
|
||||
calls.append(model_name)
|
||||
if started is not None:
|
||||
started.set()
|
||||
time.sleep(delay_seconds)
|
||||
model = MagicMock()
|
||||
model.encode.return_value = [[0.1, 0.2]]
|
||||
return model
|
||||
|
||||
return load
|
||||
|
||||
|
||||
async def _embed(model_name: str, max_context_length: int = 512) -> list[list[float]]:
|
||||
return await embed_text(
|
||||
texts=["hello"],
|
||||
model_name=model_name,
|
||||
max_context_length=max_context_length,
|
||||
normalize_embeddings=True,
|
||||
prefix=None,
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_model_load_does_not_block_event_loop() -> None:
|
||||
started = threading.Event()
|
||||
with patch(_LOAD_EMBEDDING_MODEL, side_effect=_slow_loader(0.3, [], started)):
|
||||
embed_task = asyncio.create_task(_embed(_CUSTOM_MODEL_NAME))
|
||||
|
||||
ticks = 0
|
||||
while not embed_task.done():
|
||||
await asyncio.sleep(0.02)
|
||||
ticks += 1
|
||||
|
||||
assert started.is_set()
|
||||
assert await embed_task == [[0.1, 0.2]]
|
||||
# The loop kept running while the load slept.
|
||||
assert ticks >= 5
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_concurrent_requests_share_one_load() -> None:
|
||||
"""Requests for a model and context length share one load job, so waiting
|
||||
requests hold no threads. A job for another context length waits on the
|
||||
model lock and does not load the model again."""
|
||||
calls: list[str] = []
|
||||
executor = encoders._MODEL_LOAD_EXECUTOR
|
||||
with (
|
||||
patch(_LOAD_EMBEDDING_MODEL, side_effect=_slow_loader(0.3, calls)),
|
||||
patch.object(executor, "submit", wraps=executor.submit) as submit,
|
||||
):
|
||||
results = await asyncio.gather(
|
||||
*[_embed(_CUSTOM_MODEL_NAME) for _ in range(8)],
|
||||
_embed(_CUSTOM_MODEL_NAME, max_context_length=1024),
|
||||
)
|
||||
|
||||
assert results == [[[0.1, 0.2]]] * 9
|
||||
assert calls == [_CUSTOM_MODEL_NAME]
|
||||
assert submit.call_count == 2
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_cancelled_request_does_not_cancel_shared_load() -> None:
|
||||
calls: list[str] = []
|
||||
with (
|
||||
ThreadPoolExecutor(max_workers=1) as busy_executor,
|
||||
patch.object(encoders, "_MODEL_LOAD_EXECUTOR", busy_executor),
|
||||
patch(_LOAD_EMBEDDING_MODEL, side_effect=_slow_loader(0.1, calls)),
|
||||
):
|
||||
# The shared job waits in the queue. A cancel there would succeed.
|
||||
busy_executor.submit(time.sleep, 0.2)
|
||||
cancelled = asyncio.create_task(_embed(_CUSTOM_MODEL_NAME))
|
||||
kept = asyncio.create_task(_embed(_CUSTOM_MODEL_NAME))
|
||||
await asyncio.sleep(0.05)
|
||||
cancelled.cancel()
|
||||
|
||||
assert await kept == [[0.1, 0.2]]
|
||||
with pytest.raises(asyncio.CancelledError):
|
||||
await cancelled
|
||||
|
||||
assert calls == [_CUSTOM_MODEL_NAME]
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_failed_load_is_retried_by_next_request() -> None:
|
||||
model = MagicMock()
|
||||
model.encode.return_value = [[0.1, 0.2]]
|
||||
with patch(
|
||||
_LOAD_EMBEDDING_MODEL, side_effect=[OSError("network down"), model]
|
||||
) as load:
|
||||
with pytest.raises(OSError, match="network down"):
|
||||
await _embed(_CUSTOM_MODEL_NAME)
|
||||
assert await _embed(_CUSTOM_MODEL_NAME) == [[0.1, 0.2]]
|
||||
|
||||
assert load.call_count == 2
|
||||
assert encoders._PENDING_MODEL_JOBS == {}
|
||||
|
||||
|
||||
# ---- embed_text / process_embed_request ----
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_embed_text_no_model_name() -> None:
|
||||
# Test that the function raises an error when no model name is provided
|
||||
@@ -99,6 +232,10 @@ async def test_concurrent_embeddings() -> None:
|
||||
reduced_dimension=None,
|
||||
)
|
||||
|
||||
# process_embed_request imports litellm on first use, which takes seconds.
|
||||
# Import it before the clock starts so the test only measures the embeds.
|
||||
import litellm.exceptions # noqa: F401
|
||||
|
||||
with patch("model_server.encoders.get_embedding_model") as mock_get_model:
|
||||
mock_model = MagicMock()
|
||||
mock_model.encode = mock_encode
|
||||
|
||||
@@ -0,0 +1,304 @@
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
from unittest.mock import MagicMock, patch
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
import torch
|
||||
from safetensors.torch import save_file
|
||||
from sentence_transformers.base.modules import Transformer
|
||||
from sentence_transformers.sentence_transformer.modules import Dense
|
||||
|
||||
from model_server import embedding_model_loader as loader
|
||||
from model_server.embedding_model_loader import (
|
||||
EmbeddingModelLoadError,
|
||||
load_embedding_model,
|
||||
)
|
||||
from model_server.voyage_nano import VOYAGE_NANO_PROJECTION_FILE
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import EmbeddingModelSpec, get_local_model_spec
|
||||
|
||||
_ST_CLASS = "sentence_transformers.SentenceTransformer"
|
||||
_MODULES_JSON_IS_CACHED = "model_server.embedding_model_loader._modules_json_is_cached"
|
||||
_HF_HUB_DOWNLOAD = "huggingface_hub.hf_hub_download"
|
||||
_SHA_A = "a" * 40
|
||||
_SHA_B = "b" * 40
|
||||
|
||||
|
||||
def _registry_spec(model_name: str) -> EmbeddingModelSpec:
|
||||
spec = get_local_model_spec(model_name)
|
||||
assert spec is not None
|
||||
return spec
|
||||
|
||||
|
||||
_GRANITE = _registry_spec(DEFAULT_DOCUMENT_ENCODER_MODEL)
|
||||
_VOYAGE = _registry_spec("voyageai/voyage-4-nano")
|
||||
|
||||
|
||||
def _fake_model(dim: int) -> MagicMock:
|
||||
model = MagicMock()
|
||||
model.encode.return_value = np.zeros((1, dim), dtype=np.float32)
|
||||
return model
|
||||
|
||||
|
||||
# ---- Registry models ----
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("cuda", "mps", "model_kwargs"),
|
||||
[
|
||||
(False, False, {"dtype": torch.float32}),
|
||||
(True, False, {}),
|
||||
(False, True, {}),
|
||||
],
|
||||
ids=["cpu", "cuda", "mps"],
|
||||
)
|
||||
def test_registry_model_load_call(
|
||||
cuda: bool,
|
||||
mps: bool,
|
||||
model_kwargs: dict[str, Any],
|
||||
monkeypatch: pytest.MonkeyPatch,
|
||||
) -> None:
|
||||
"""The pinned revision, no remote code, the local cache first. CPU-only hosts
|
||||
load the bf16 checkpoints as float32."""
|
||||
monkeypatch.setattr(torch.cuda, "is_available", lambda: cuda)
|
||||
monkeypatch.setattr(torch.backends.mps, "is_available", lambda: mps)
|
||||
model = _fake_model(_GRANITE.model_dim)
|
||||
with (
|
||||
patch(_MODULES_JSON_IS_CACHED, return_value=True) as is_cached,
|
||||
patch(_ST_CLASS, return_value=model) as load,
|
||||
):
|
||||
assert load_embedding_model(_GRANITE.model_name) is model
|
||||
|
||||
is_cached.assert_called_once_with(_GRANITE.model_name, _GRANITE.hf_revision)
|
||||
load.assert_called_once_with(
|
||||
model_name_or_path=_GRANITE.model_name,
|
||||
revision=_GRANITE.hf_revision,
|
||||
trust_remote_code=False,
|
||||
local_files_only=True,
|
||||
model_kwargs=model_kwargs,
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("output", "error"),
|
||||
[
|
||||
(np.zeros((1, _GRANITE.model_dim // 2)), f"expects {_GRANITE.model_dim}"),
|
||||
(np.full((1, _GRANITE.model_dim), np.nan), "non-finite"),
|
||||
],
|
||||
ids=["wrong-dim", "non-finite"],
|
||||
)
|
||||
def test_registry_model_with_unusable_output_is_rejected(
|
||||
output: np.ndarray, error: str
|
||||
) -> None:
|
||||
model = MagicMock()
|
||||
model.encode.return_value = output
|
||||
with (
|
||||
patch(_MODULES_JSON_IS_CACHED, return_value=True),
|
||||
patch(_ST_CLASS, return_value=model),
|
||||
pytest.raises(EmbeddingModelLoadError, match=error),
|
||||
):
|
||||
load_embedding_model(_GRANITE.model_name)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("model_name", "cached"),
|
||||
[
|
||||
("nomic-ai/nomic-embed-text-v1", True),
|
||||
("my-org/custom-model", False),
|
||||
# Only the exact registry name gets the registry load.
|
||||
("IBM-Granite/granite-embedding-97m-multilingual-r2", False),
|
||||
],
|
||||
)
|
||||
def test_other_models_keep_the_load_call_from_before_the_registry(
|
||||
model_name: str, cached: bool
|
||||
) -> None:
|
||||
"""Another call would change the vectors of existing indexes."""
|
||||
with (
|
||||
patch(_MODULES_JSON_IS_CACHED, return_value=cached),
|
||||
patch(_ST_CLASS, return_value=MagicMock()) as load,
|
||||
):
|
||||
load_embedding_model(model_name)
|
||||
|
||||
load.assert_called_once_with(
|
||||
model_name_or_path=model_name,
|
||||
local_files_only=cached,
|
||||
trust_remote_code=False,
|
||||
)
|
||||
|
||||
|
||||
def test_voyage_loader_adds_bidirectional_projection(tmp_path: Path) -> None:
|
||||
weight = torch.randn(6, 4)
|
||||
weights_path = tmp_path / VOYAGE_NANO_PROJECTION_FILE
|
||||
save_file({"linear.weight": weight, "other.weight": torch.zeros(1)}, weights_path)
|
||||
transformer = MagicMock(spec=Transformer)
|
||||
pooling = MagicMock()
|
||||
normalize = MagicMock()
|
||||
base = MagicMock()
|
||||
base.__getitem__.side_effect = [transformer, pooling, normalize].__getitem__
|
||||
final = _fake_model(_VOYAGE.model_dim)
|
||||
|
||||
with (
|
||||
patch(_MODULES_JSON_IS_CACHED, return_value=True),
|
||||
patch(_ST_CLASS, side_effect=[base, final]) as st_class,
|
||||
patch(_HF_HUB_DOWNLOAD, return_value=str(weights_path)) as download,
|
||||
):
|
||||
assert load_embedding_model(_VOYAGE.model_name) is final
|
||||
|
||||
base_load, rebuild = st_class.call_args_list
|
||||
assert base_load.kwargs["revision"] == _VOYAGE.hf_revision
|
||||
download.assert_called_once_with(
|
||||
_VOYAGE.model_name,
|
||||
VOYAGE_NANO_PROJECTION_FILE,
|
||||
revision=_VOYAGE.hf_revision,
|
||||
cache_dir=None,
|
||||
)
|
||||
|
||||
assert transformer.auto_model.config.is_causal is False
|
||||
modules = rebuild.kwargs["modules"]
|
||||
assert modules[0] is transformer
|
||||
assert modules[1] is pooling
|
||||
assert modules[3] is normalize
|
||||
projection = modules[2]
|
||||
assert isinstance(projection, Dense)
|
||||
assert (projection.in_features, projection.out_features) == (4, 6)
|
||||
assert projection.linear.bias is None
|
||||
assert isinstance(projection.activation_function, torch.nn.Identity)
|
||||
assert torch.equal(projection.linear.weight.detach(), weight)
|
||||
# The dimension check ran on the final model.
|
||||
final.encode.assert_called_once()
|
||||
|
||||
|
||||
# ---- Local-first resolution ----
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"error",
|
||||
[
|
||||
OSError("couldn't find them in the cached files"),
|
||||
ValueError("Unrecognized processing class"),
|
||||
TypeError("missing 1 required positional argument"),
|
||||
],
|
||||
)
|
||||
def test_load_local_first_retries_online_on_partial_cache(error: Exception) -> None:
|
||||
calls: list[bool] = []
|
||||
|
||||
def load(local_files_only: bool) -> str:
|
||||
calls.append(local_files_only)
|
||||
if local_files_only:
|
||||
raise error
|
||||
return "online"
|
||||
|
||||
with patch(_MODULES_JSON_IS_CACHED, return_value=True):
|
||||
assert loader._load_local_first("org/model", None, load) == "online"
|
||||
assert calls == [True, False]
|
||||
|
||||
|
||||
def test_load_local_first_raises_real_errors() -> None:
|
||||
calls: list[bool] = []
|
||||
|
||||
def load(local_files_only: bool) -> str:
|
||||
calls.append(local_files_only)
|
||||
raise RuntimeError("Error(s) in loading state_dict")
|
||||
|
||||
with (
|
||||
patch(_MODULES_JSON_IS_CACHED, return_value=True),
|
||||
pytest.raises(RuntimeError, match="state_dict"),
|
||||
):
|
||||
loader._load_local_first("org/model", None, load)
|
||||
assert calls == [True]
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("cached", "expected_error"),
|
||||
[
|
||||
# The online retry reads the same cached files, so its error is the real one.
|
||||
(True, RuntimeError),
|
||||
# Air-gapped hosts get a clear error, not huggingface_hub's retry noise.
|
||||
(False, EmbeddingModelLoadError),
|
||||
],
|
||||
)
|
||||
def test_load_local_first_online_failure(
|
||||
cached: bool, expected_error: type[Exception]
|
||||
) -> None:
|
||||
def load(local_files_only: bool) -> str:
|
||||
if local_files_only:
|
||||
raise OSError("partial cache")
|
||||
raise RuntimeError("Cannot send a request, as the client has been closed.")
|
||||
|
||||
with (
|
||||
patch(_MODULES_JSON_IS_CACHED, return_value=cached),
|
||||
pytest.raises(RuntimeError) as exc_info,
|
||||
):
|
||||
loader._load_local_first("org/model", None, load)
|
||||
|
||||
# EmbeddingModelLoadError is a RuntimeError, so compare the exact type.
|
||||
assert type(exc_info.value) is expected_error
|
||||
if not cached:
|
||||
assert "org/model is not in the model server's Hugging Face cache" in str(
|
||||
exc_info.value
|
||||
)
|
||||
assert isinstance(exc_info.value.__cause__, RuntimeError)
|
||||
|
||||
|
||||
def _make_hub_cache(
|
||||
root: Path,
|
||||
repo_id: str,
|
||||
commit: str,
|
||||
files: list[str],
|
||||
ref_main: bool,
|
||||
no_exist: list[str] | None = None,
|
||||
) -> None:
|
||||
repo_dir = root / f"models--{repo_id.replace('/', '--')}"
|
||||
snapshot = repo_dir / "snapshots" / commit
|
||||
snapshot.mkdir(parents=True)
|
||||
for name in files:
|
||||
(snapshot / name).write_text("{}")
|
||||
if ref_main:
|
||||
(repo_dir / "refs").mkdir()
|
||||
(repo_dir / "refs" / "main").write_text(commit)
|
||||
for name in no_exist or []:
|
||||
marker = repo_dir / ".no_exist" / commit / name
|
||||
marker.parent.mkdir(parents=True, exist_ok=True)
|
||||
marker.touch()
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def hub_cache(tmp_path: Path, monkeypatch: pytest.MonkeyPatch) -> Path:
|
||||
import huggingface_hub.constants
|
||||
|
||||
cache = tmp_path / "hub"
|
||||
cache.mkdir()
|
||||
monkeypatch.delenv("SENTENCE_TRANSFORMERS_HOME", raising=False)
|
||||
monkeypatch.setattr(huggingface_hub.constants, "HF_HUB_CACHE", str(cache))
|
||||
return cache
|
||||
|
||||
|
||||
def test_modules_json_is_cached(hub_cache: Path) -> None:
|
||||
_make_hub_cache(hub_cache, "org/st-model", _SHA_A, ["modules.json"], ref_main=True)
|
||||
# A snapshot at a pinned revision with no refs/main, like the image bake.
|
||||
_make_hub_cache(hub_cache, "org/pinned", _SHA_B, ["modules.json"], ref_main=False)
|
||||
# config.json and weights cached (e.g. by transformers) but no modules.json.
|
||||
_make_hub_cache(
|
||||
hub_cache,
|
||||
"org/partial",
|
||||
_SHA_A,
|
||||
["config.json", "model.safetensors"],
|
||||
ref_main=True,
|
||||
)
|
||||
# A plain transformers model: the cache records that modules.json is absent.
|
||||
_make_hub_cache(
|
||||
hub_cache,
|
||||
"org/plain-hf",
|
||||
_SHA_A,
|
||||
["config.json"],
|
||||
ref_main=True,
|
||||
no_exist=["modules.json"],
|
||||
)
|
||||
|
||||
assert loader._modules_json_is_cached("org/st-model", None) is True
|
||||
assert loader._modules_json_is_cached("org/pinned", _SHA_B) is True
|
||||
assert loader._modules_json_is_cached("org/partial", None) is False
|
||||
assert loader._modules_json_is_cached("org/plain-hf", None) is True
|
||||
# A local directory is not a repo id. sentence-transformers reads it directly.
|
||||
assert loader._modules_json_is_cached("/models/my-model", None) is False
|
||||
@@ -0,0 +1,151 @@
|
||||
"""The first search settings rows of a fresh DB (alembic dbaa756c2ccf) and the
|
||||
default tokenizer, which onyx.configs.model_configs derives from the env and the
|
||||
embedding registry."""
|
||||
|
||||
import json
|
||||
import os
|
||||
import subprocess
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import pytest
|
||||
|
||||
_MODEL_ENV_VARS = (
|
||||
"DOCUMENT_ENCODER_MODEL",
|
||||
"DOC_EMBEDDING_DIM",
|
||||
"NORMALIZE_EMBEDDINGS",
|
||||
"ASYM_QUERY_PREFIX",
|
||||
"ASYM_PASSAGE_PREFIX",
|
||||
)
|
||||
|
||||
_BACKEND_DIR = Path(__file__).resolve().parents[4]
|
||||
|
||||
|
||||
def _run_python(code: str, env: dict[str, str]) -> subprocess.CompletedProcess[str]:
|
||||
"""Run code in a new interpreter with exactly the given model env vars.
|
||||
|
||||
model_configs reads the env at import. A reload in this process would rebind
|
||||
its globals for every later test, so each case gets its own process."""
|
||||
child_env = {k: v for k, v in os.environ.items() if k not in _MODEL_ENV_VARS}
|
||||
child_env.update(env)
|
||||
child_env["PYTHONPATH"] = str(_BACKEND_DIR)
|
||||
result = subprocess.run(
|
||||
[sys.executable, "-c", code],
|
||||
cwd=_BACKEND_DIR,
|
||||
env=child_env,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
timeout=120,
|
||||
)
|
||||
assert result.returncode == 0, result.stderr
|
||||
return result
|
||||
|
||||
|
||||
def _last_json_line(result: subprocess.CompletedProcess[str]) -> Any:
|
||||
return json.loads(result.stdout.strip().splitlines()[-1])
|
||||
|
||||
|
||||
# Loads alembic dbaa756c2ccf from its file and prints the default tokenizer and
|
||||
# the rows that the migration seeds.
|
||||
_SEED_PROBE = """
|
||||
import importlib.util
|
||||
import json
|
||||
|
||||
spec = importlib.util.spec_from_file_location(
|
||||
"seed", "alembic/versions/dbaa756c2ccf_embedding_models.py"
|
||||
)
|
||||
migration = importlib.util.module_from_spec(spec)
|
||||
spec.loader.exec_module(migration)
|
||||
from onyx.configs.model_configs import DEFAULT_TOKENIZER_MODEL
|
||||
|
||||
rows = [["PRESENT", migration._get_old_default_embedding_model()]]
|
||||
if not migration.user_has_overridden_embedding_model():
|
||||
rows.append(["FUTURE", migration._get_new_default_embedding_model()])
|
||||
print(json.dumps([DEFAULT_TOKENIZER_MODEL, [
|
||||
[status, s.model_name, s.model_dim, s.normalize, s.query_prefix,
|
||||
s.passage_prefix, s.index_name]
|
||||
for status, s in rows
|
||||
]]))
|
||||
"""
|
||||
|
||||
NOMIC = "nomic-ai/nomic-embed-text-v1"
|
||||
CUSTOM = "my-org/custom-model"
|
||||
_GTE_PLACEHOLDER = [
|
||||
"PRESENT",
|
||||
"thenlper/gte-small",
|
||||
384,
|
||||
False,
|
||||
"",
|
||||
"",
|
||||
"danswer_chunk",
|
||||
]
|
||||
_GRANITE_FUTURE = [
|
||||
"FUTURE",
|
||||
"ibm-granite/granite-embedding-97m-multilingual-r2",
|
||||
384,
|
||||
True,
|
||||
"",
|
||||
"",
|
||||
"danswer_chunk_ibm_granite_granite_embedding_97m_multilingual_r2",
|
||||
]
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"env,tokenizer,rows",
|
||||
[
|
||||
# Fresh default: the gte-small placeholder plus a granite FUTURE row, from
|
||||
# granite's registry spec. The tokenizer stays nomic.
|
||||
({}, NOMIC, [_GTE_PLACEHOLDER, _GRANITE_FUTURE]),
|
||||
# nomic via env (the previous default) seeds exactly what main seeded.
|
||||
(
|
||||
{"DOCUMENT_ENCODER_MODEL": NOMIC},
|
||||
NOMIC,
|
||||
[
|
||||
_GTE_PLACEHOLDER,
|
||||
[
|
||||
"FUTURE",
|
||||
NOMIC,
|
||||
768,
|
||||
True,
|
||||
"search_query: ",
|
||||
"search_document: ",
|
||||
"danswer_chunk_nomic_ai_nomic_embed_text_v1",
|
||||
],
|
||||
],
|
||||
),
|
||||
# Any other model via env is an override: PRESENT on danswer_chunk, with
|
||||
# the model env vars over the old literal defaults.
|
||||
(
|
||||
{"DOCUMENT_ENCODER_MODEL": CUSTOM, "DOC_EMBEDDING_DIM": "1024"},
|
||||
CUSTOM,
|
||||
[
|
||||
[
|
||||
"PRESENT",
|
||||
CUSTOM,
|
||||
1024,
|
||||
True,
|
||||
"search_query: ",
|
||||
"search_document: ",
|
||||
"danswer_chunk",
|
||||
]
|
||||
],
|
||||
),
|
||||
# An env file written for nomic, without DOCUMENT_ENCODER_MODEL: a working
|
||||
# granite row, not granite with nomic's 768 dims and prefixes.
|
||||
(
|
||||
{
|
||||
"DOC_EMBEDDING_DIM": "768",
|
||||
"ASYM_QUERY_PREFIX": "search_query: ",
|
||||
"ASYM_PASSAGE_PREFIX": "search_document: ",
|
||||
},
|
||||
NOMIC,
|
||||
[_GTE_PLACEHOLDER, _GRANITE_FUTURE],
|
||||
),
|
||||
],
|
||||
ids=["no-env", "nomic-env", "custom-env", "nomic-era-env-without-model"],
|
||||
)
|
||||
def test_alembic_dbaa756c2ccf_seed(
|
||||
env: dict[str, str], tokenizer: str, rows: list[list[object]]
|
||||
) -> None:
|
||||
assert _last_json_line(_run_python(_SEED_PROBE, env)) == [tokenizer, rows]
|
||||
@@ -3,7 +3,9 @@ from threading import Lock
|
||||
from typing import Any
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
import httpx
|
||||
import pytest
|
||||
import requests
|
||||
from google.auth.credentials import Credentials
|
||||
from httpx import AsyncClient
|
||||
from litellm.exceptions import RateLimitError
|
||||
@@ -17,11 +19,11 @@ from onyx.natural_language_processing.search_nlp_models import (
|
||||
EmbeddingModel,
|
||||
EmbeddingRequestPolicy,
|
||||
EmbeddingRetryBackoff,
|
||||
clean_model_name,
|
||||
)
|
||||
from onyx.natural_language_processing.vertex_auth import VertexEmbeddingConfig
|
||||
from shared_configs.enums import EmbeddingProvider, EmbedTextType
|
||||
from shared_configs.model_server_models import EmbedRequest, EmbedResponse
|
||||
from shared_configs.utils import clean_model_name
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
@@ -824,6 +826,19 @@ def test_query_embeddings_never_wait_for_the_rate_limit() -> None:
|
||||
load_limiter.assert_not_called()
|
||||
|
||||
|
||||
def test_model_server_error_detail_reaches_the_caller() -> None:
|
||||
model = _make_local_embedding_model()
|
||||
failed = MagicMock(status_code=500)
|
||||
failed.raise_for_status.side_effect = requests.HTTPError("500", response=failed)
|
||||
failed.json.return_value = {"detail": "model is not in the cache"}
|
||||
|
||||
with (
|
||||
patch(f"{_SEARCH_NLP_MODULE}.requests.post", return_value=failed),
|
||||
pytest.raises(httpx.HTTPError, match="model is not in the cache"),
|
||||
):
|
||||
model.encode(texts=["text_0"], text_type=EmbedTextType.QUERY)
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
@pytest.mark.parametrize(
|
||||
("block_on_provider_rate_limit", "expected_retries"),
|
||||
|
||||
@@ -0,0 +1,54 @@
|
||||
"""API-side HF tokenizers: registry models load at their pinned revision, other
|
||||
names keep the plain call, and the default tokenizer stays the pre-granite model."""
|
||||
|
||||
from unittest.mock import patch
|
||||
|
||||
import pytest
|
||||
|
||||
from onyx.natural_language_processing import utils
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import get_local_model_spec
|
||||
|
||||
_HF_TOKENIZER_CLASS = "onyx.natural_language_processing.utils.Tokenizer"
|
||||
_NOMIC = "nomic-ai/nomic-embed-text-v1"
|
||||
|
||||
|
||||
def _pinned_revision(model_name: str) -> str | None:
|
||||
spec = get_local_model_spec(model_name)
|
||||
assert spec is not None
|
||||
return spec.hf_revision
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("model_name", "kwargs"),
|
||||
[
|
||||
(
|
||||
DEFAULT_DOCUMENT_ENCODER_MODEL,
|
||||
{"revision": _pinned_revision(DEFAULT_DOCUMENT_ENCODER_MODEL)},
|
||||
),
|
||||
(_NOMIC, {}),
|
||||
# Only the exact registry name is pinned; a variant keeps the plain call.
|
||||
(DEFAULT_DOCUMENT_ENCODER_MODEL.upper(), {}),
|
||||
],
|
||||
ids=["registry-model", "legacy-model", "registry-name-variant"],
|
||||
)
|
||||
def test_tokenizer_load_call(model_name: str, kwargs: dict[str, str | None]) -> None:
|
||||
with patch(_HF_TOKENIZER_CLASS) as mock_class:
|
||||
utils.HuggingFaceTokenizer(model_name)
|
||||
|
||||
mock_class.from_pretrained.assert_called_once_with(model_name, **kwargs)
|
||||
|
||||
|
||||
def test_no_model_name_uses_the_default_tokenizer_model(
|
||||
monkeypatch: pytest.MonkeyPatch,
|
||||
) -> None:
|
||||
"""Not DOCUMENT_ENCODER_MODEL, which defaults to granite. The env semantics of
|
||||
DEFAULT_TOKENIZER_MODEL are pinned in test_embedding_model_registry_configs.py."""
|
||||
monkeypatch.setattr(utils, "_DEFAULT_TOKENIZER", None)
|
||||
monkeypatch.setattr(utils, "_TOKENIZER_CACHE", {})
|
||||
monkeypatch.setattr(utils, "DEFAULT_TOKENIZER_MODEL", _NOMIC)
|
||||
with patch(_HF_TOKENIZER_CLASS) as mock_class:
|
||||
result = utils.get_tokenizer(model_name=None, provider_type=None)
|
||||
|
||||
mock_class.from_pretrained.assert_called_once_with(_NOMIC)
|
||||
assert isinstance(result, utils.HuggingFaceTokenizer)
|
||||
@@ -0,0 +1,516 @@
|
||||
"""Upgrade-only guard in set_new_search_settings: a new embedding target must be the
|
||||
PRESENT model (same-model re-index) or a selectable registry model. Legacy registry
|
||||
models are refused; custom self-hosted models, LiteLLM and Azure stay open. Bifrost
|
||||
and selectable cloud targets are probed before the PRESENT row lock."""
|
||||
|
||||
from collections.abc import Iterator
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
from unittest.mock import MagicMock, patch
|
||||
|
||||
import pytest
|
||||
|
||||
from onyx.context.search.models import (
|
||||
SavedSearchSettings,
|
||||
SearchSettingsCreationRequest,
|
||||
)
|
||||
from onyx.error_handling.error_codes import OnyxErrorCode
|
||||
from onyx.error_handling.exceptions import OnyxError
|
||||
from onyx.natural_language_processing.embedding_auth import VertexEmbeddingAuth
|
||||
from onyx.server.manage.search_settings import (
|
||||
_check_embedding_model_target,
|
||||
_validate_cloud_embedding_model,
|
||||
set_new_search_settings,
|
||||
)
|
||||
from shared_configs.configs import DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
from shared_configs.embedding_models import (
|
||||
EmbeddingModelSpec,
|
||||
find_embedding_model_spec,
|
||||
selectable_embedding_model_specs,
|
||||
)
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
from shared_configs.utils import clean_model_name
|
||||
|
||||
_MODULE = "onyx.server.manage.search_settings"
|
||||
|
||||
NOMIC = "nomic-ai/nomic-embed-text-v1"
|
||||
E5 = "intfloat/e5-base-v2"
|
||||
GRANITE = DEFAULT_DOCUMENT_ENCODER_MODEL
|
||||
VOYAGE_NANO = "voyageai/voyage-4-nano"
|
||||
NEMOTRON = "nvidia/Nemotron-3-Embed-1B-BF16"
|
||||
COHERE = EmbeddingProvider.COHERE
|
||||
GOOGLE = EmbeddingProvider.GOOGLE
|
||||
OPENAI = EmbeddingProvider.OPENAI
|
||||
|
||||
|
||||
def _request(
|
||||
model_name: str,
|
||||
*,
|
||||
provider_type: EmbeddingProvider | None = None,
|
||||
model_dim: int = 768,
|
||||
normalize: bool = True,
|
||||
query_prefix: str | None = "",
|
||||
passage_prefix: str | None = "",
|
||||
reduced_dimension: int | None = None,
|
||||
) -> SearchSettingsCreationRequest:
|
||||
return SearchSettingsCreationRequest(
|
||||
model_name=model_name,
|
||||
model_dim=model_dim,
|
||||
normalize=normalize,
|
||||
query_prefix=query_prefix,
|
||||
passage_prefix=passage_prefix,
|
||||
provider_type=provider_type,
|
||||
index_name=None,
|
||||
multipass_indexing=False,
|
||||
reduced_dimension=reduced_dimension,
|
||||
enable_contextual_rag=False,
|
||||
contextual_rag_model_configuration_id=None,
|
||||
)
|
||||
|
||||
|
||||
def _spec_request(
|
||||
provider_type: EmbeddingProvider | None,
|
||||
model_name: str,
|
||||
*,
|
||||
sent_name: str | None = None,
|
||||
**overrides: Any,
|
||||
) -> SearchSettingsCreationRequest:
|
||||
"""A request with the registry's settings for the model, as the UI sends it.
|
||||
sent_name replaces the model name in the request (e.g. a case variant)."""
|
||||
spec = find_embedding_model_spec(provider_type, model_name)
|
||||
assert spec is not None
|
||||
values: dict[str, Any] = {
|
||||
"provider_type": spec.provider_type,
|
||||
"model_dim": spec.model_dim,
|
||||
"normalize": spec.normalize,
|
||||
"query_prefix": spec.query_prefix,
|
||||
"passage_prefix": spec.passage_prefix,
|
||||
}
|
||||
values.update(overrides)
|
||||
return _request(sent_name or model_name, **values)
|
||||
|
||||
|
||||
def _present(
|
||||
model_name: str,
|
||||
provider_type: EmbeddingProvider | None = None,
|
||||
*,
|
||||
model_dim: int | None = None,
|
||||
reduced_dimension: int | None = None,
|
||||
) -> MagicMock:
|
||||
"""PRESENT row. model_dim defaults to the registry dim, else 768."""
|
||||
if model_dim is None:
|
||||
spec = find_embedding_model_spec(provider_type, model_name)
|
||||
model_dim = spec.model_dim if spec is not None else 768
|
||||
present = MagicMock()
|
||||
present.id = 2
|
||||
present.use_port_flow = False
|
||||
present.port_backfill_source_id = None
|
||||
present.model_name = model_name
|
||||
present.provider_type = provider_type
|
||||
present.model_dim = model_dim
|
||||
present.reduced_dimension = reduced_dimension
|
||||
present.index_name = f"danswer_chunk_{clean_model_name(model_name)}"
|
||||
return present
|
||||
|
||||
|
||||
# ---- The rules ----
|
||||
|
||||
_ALLOWED = [
|
||||
pytest.param(
|
||||
_present(NOMIC), _request(NOMIC), False, id="same-legacy-model-empty-prefixes"
|
||||
),
|
||||
pytest.param(
|
||||
_present(E5), _request("IntFloat/E5_Base.V2"), False, id="same-model-variant"
|
||||
),
|
||||
pytest.param(
|
||||
_present(VOYAGE_NANO, model_dim=1024),
|
||||
_request(VOYAGE_NANO, model_dim=1024),
|
||||
False,
|
||||
id="same-model-keeps-a-custom-dim",
|
||||
),
|
||||
pytest.param(
|
||||
_present(VOYAGE_NANO, model_dim=1024),
|
||||
_spec_request(None, VOYAGE_NANO),
|
||||
False,
|
||||
id="same-model-moves-to-the-registry-dim",
|
||||
),
|
||||
pytest.param(
|
||||
_present("embed-english-v3.0", COHERE),
|
||||
_request("embed-english-v3.0", provider_type=COHERE, model_dim=1024),
|
||||
False,
|
||||
id="same-legacy-cloud-model",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC, reduced_dimension=256),
|
||||
_request(NOMIC, reduced_dimension=256),
|
||||
False,
|
||||
id="same-self-hosted-model-keeps-a-stored-reduced-dimension",
|
||||
),
|
||||
pytest.param(
|
||||
_present("text-embedding-3-large", OPENAI, reduced_dimension=1024),
|
||||
_spec_request(OPENAI, "text-embedding-3-large", reduced_dimension=1024),
|
||||
True,
|
||||
id="same-model-keeps-reduced-dimension-in-multi-tenant",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(None, GRANITE, query_prefix=None, passage_prefix=None),
|
||||
False,
|
||||
id="selectable-with-null-prefixes",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(OPENAI, "text-embedding-3-large", reduced_dimension=1024),
|
||||
False,
|
||||
id="selectable-with-reduced-dimension",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request("my-org/custom-embedder", model_dim=1024),
|
||||
False,
|
||||
id="custom-self-hosted-model",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request(
|
||||
"embed-english-v3.0", provider_type=EmbeddingProvider.LITELLM, model_dim=123
|
||||
),
|
||||
False,
|
||||
id="litellm-with-a-legacy-looking-name",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request(
|
||||
"text-embedding-3-large",
|
||||
provider_type=EmbeddingProvider.AZURE,
|
||||
model_dim=123,
|
||||
),
|
||||
False,
|
||||
id="azure",
|
||||
),
|
||||
]
|
||||
|
||||
_REJECTED = [
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request(GRANITE, model_dim=768),
|
||||
False,
|
||||
"must keep its dimension",
|
||||
id="same-model-with-another-dim",
|
||||
),
|
||||
pytest.param(
|
||||
_present("text-embedding-3-large", OPENAI),
|
||||
_spec_request(OPENAI, "text-embedding-3-large", reduced_dimension=1024),
|
||||
True,
|
||||
"share its index",
|
||||
id="same-model-changes-reduced-dimension-in-multi-tenant",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_spec_request(None, GRANITE, reduced_dimension=256),
|
||||
False,
|
||||
"do not support reduced_dimension",
|
||||
id="same-self-hosted-model-adds-reduced-dimension",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request("my-org/custom-embedder", model_dim=1024, reduced_dimension=256),
|
||||
False,
|
||||
"do not support reduced_dimension",
|
||||
id="custom-self-hosted-model-with-reduced-dimension",
|
||||
),
|
||||
pytest.param(
|
||||
_present("embed-english-v3.0"),
|
||||
_request("embed-english-v3.0", provider_type=COHERE, model_dim=1024),
|
||||
False,
|
||||
"legacy embedding model",
|
||||
id="same-name-but-another-provider",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(None, GRANITE, model_dim=768),
|
||||
False,
|
||||
"model_dim must be 384",
|
||||
id="selectable-with-another-dim",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(None, GRANITE, normalize=False),
|
||||
False,
|
||||
"normalize must be True",
|
||||
id="selectable-with-another-normalize",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(None, NEMOTRON, query_prefix="query:"),
|
||||
False,
|
||||
"query_prefix must be 'query: '",
|
||||
id="selectable-prefix-without-its-trailing-space",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(OPENAI, "text-embedding-3-large", reduced_dimension=0),
|
||||
False,
|
||||
"between 1 and 3071",
|
||||
id="reduced-dimension-zero",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(OPENAI, "text-embedding-3-large", reduced_dimension=3072),
|
||||
False,
|
||||
"between 1 and 3071",
|
||||
id="reduced-dimension-full-size",
|
||||
),
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(COHERE, "embed-v5.0-pro", reduced_dimension=256),
|
||||
False,
|
||||
"does not support reduced_dimension",
|
||||
id="reduced-dimension-without-support",
|
||||
),
|
||||
pytest.param(
|
||||
_present("embed-english-v3.0", COHERE),
|
||||
_spec_request(OPENAI, "text-embedding-3-large", reduced_dimension=1024),
|
||||
True,
|
||||
"not supported in Onyx Cloud",
|
||||
id="reduced-dimension-in-multi-tenant",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_spec_request(None, NOMIC),
|
||||
False,
|
||||
"legacy embedding model",
|
||||
id="legacy-self-hosted-model",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request(" nomic_ai/Nomic.Embed.Text.V1 "),
|
||||
False,
|
||||
"legacy embedding model",
|
||||
id="legacy-self-hosted-name-variant",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_spec_request(GOOGLE, "text-embedding-005"),
|
||||
False,
|
||||
"legacy embedding model",
|
||||
id="legacy-cloud-model",
|
||||
),
|
||||
pytest.param(
|
||||
_present(GRANITE),
|
||||
_request("text-embedding-ada-002", provider_type=OPENAI),
|
||||
False,
|
||||
"not an embedding model that Onyx supports",
|
||||
id="unknown-model-of-a-registry-provider",
|
||||
),
|
||||
]
|
||||
|
||||
|
||||
@pytest.mark.parametrize(("present", "target", "multi_tenant"), _ALLOWED)
|
||||
def test_allowed_target(
|
||||
present: MagicMock, target: SearchSettingsCreationRequest, multi_tenant: bool
|
||||
) -> None:
|
||||
with patch(f"{_MODULE}.MULTI_TENANT", multi_tenant):
|
||||
_check_embedding_model_target(target, present)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(("present", "target", "multi_tenant", "problem"), _REJECTED)
|
||||
def test_rejected_target(
|
||||
present: MagicMock,
|
||||
target: SearchSettingsCreationRequest,
|
||||
multi_tenant: bool,
|
||||
problem: str,
|
||||
) -> None:
|
||||
with (
|
||||
patch(f"{_MODULE}.MULTI_TENANT", multi_tenant),
|
||||
pytest.raises(OnyxError) as exc,
|
||||
):
|
||||
_check_embedding_model_target(target, present)
|
||||
|
||||
assert exc.value.error_code == OnyxErrorCode.INVALID_INPUT
|
||||
assert problem in exc.value.detail
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"spec", selectable_embedding_model_specs(), ids=lambda spec: spec.model_name
|
||||
)
|
||||
def test_every_selectable_model_is_allowed_with_registry_settings(
|
||||
spec: EmbeddingModelSpec,
|
||||
) -> None:
|
||||
_check_embedding_model_target(
|
||||
_spec_request(spec.provider_type, spec.model_name), _present(NOMIC)
|
||||
)
|
||||
|
||||
|
||||
def test_rejection_names_the_selectable_models() -> None:
|
||||
with pytest.raises(OnyxError) as exc:
|
||||
_check_embedding_model_target(_spec_request(None, NOMIC), _present(GRANITE))
|
||||
|
||||
for spec in selectable_embedding_model_specs():
|
||||
assert spec.model_name in exc.value.detail
|
||||
|
||||
|
||||
# ---- Wiring in set_new_search_settings ----
|
||||
|
||||
|
||||
class _GuardPassed(Exception):
|
||||
"""Patched into create_search_settings to prove the guards let the request through."""
|
||||
|
||||
|
||||
@dataclass
|
||||
class _EndpointMocks:
|
||||
provider: MagicMock
|
||||
current: MagicMock
|
||||
create: MagicMock
|
||||
probe: MagicMock
|
||||
|
||||
def created_settings(self) -> SavedSearchSettings:
|
||||
self.create.assert_called_once()
|
||||
return self.create.call_args.kwargs["search_settings"]
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def mocks() -> Iterator[_EndpointMocks]:
|
||||
with (
|
||||
patch(f"{_MODULE}.validate_contextual_rag_model"),
|
||||
patch(f"{_MODULE}._validate_vector_quantization_supported"),
|
||||
patch(f"{_MODULE}.get_embedding_provider_from_provider_type") as provider,
|
||||
patch(f"{_MODULE}.get_current_search_settings") as current,
|
||||
patch(f"{_MODULE}.get_secondary_search_settings", return_value=None),
|
||||
patch(f"{_MODULE}.port_backfill_has_pending_work", return_value=False),
|
||||
patch(f"{_MODULE}._guard_index_name_reuse"),
|
||||
patch(f"{_MODULE}.compute_wont_port_cc_pair_ids", return_value=[]),
|
||||
patch(f"{_MODULE}.set_reclaim_intent_on_current__no_commit"),
|
||||
patch(f"{_MODULE}.create_search_settings", side_effect=_GuardPassed) as create,
|
||||
patch(f"{_MODULE}._validate_cloud_embedding_model") as probe,
|
||||
):
|
||||
yield _EndpointMocks(
|
||||
provider=provider, current=current, create=create, probe=probe
|
||||
)
|
||||
|
||||
|
||||
def _submit(
|
||||
target: SearchSettingsCreationRequest, db_session: MagicMock | None = None
|
||||
) -> None:
|
||||
set_new_search_settings(target, _=MagicMock(), db_session=db_session or MagicMock())
|
||||
|
||||
|
||||
def test_selectable_cloud_target_is_probed_before_the_present_lock(
|
||||
mocks: _EndpointMocks,
|
||||
) -> None:
|
||||
events: list[str] = []
|
||||
|
||||
def _locked_read(*_args: object, **_kwargs: object) -> MagicMock:
|
||||
events.append("locked_read")
|
||||
return _present(GRANITE)
|
||||
|
||||
mocks.current.side_effect = _locked_read
|
||||
mocks.probe.side_effect = lambda *_args: events.append("probe")
|
||||
db_session = MagicMock()
|
||||
db_session.commit.side_effect = lambda: events.append("commit")
|
||||
|
||||
with pytest.raises(_GuardPassed):
|
||||
_submit(
|
||||
_spec_request(COHERE, "embed-v5.0-pro", sent_name="Embed-V5.0-Pro"),
|
||||
db_session,
|
||||
)
|
||||
|
||||
# The read transaction ends before the network call; nothing is locked yet.
|
||||
assert events == ["commit", "probe", "locked_read"]
|
||||
probed_request, probed_provider = mocks.probe.call_args.args
|
||||
assert probed_request.model_name == "embed-v5.0-pro"
|
||||
assert probed_provider is mocks.provider.return_value
|
||||
assert mocks.created_settings().model_name == "embed-v5.0-pro"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("present", "target", "stored_name"),
|
||||
[
|
||||
pytest.param(
|
||||
_present(NOMIC),
|
||||
_spec_request(
|
||||
None,
|
||||
GRANITE,
|
||||
sent_name=" IBM-Granite/Granite-Embedding-97M-Multilingual-R2 ",
|
||||
),
|
||||
GRANITE,
|
||||
id="new-target",
|
||||
),
|
||||
pytest.param(
|
||||
_present(VOYAGE_NANO),
|
||||
_spec_request(None, VOYAGE_NANO, sent_name="VoyageAI/Voyage-4-Nano"),
|
||||
VOYAGE_NANO,
|
||||
id="same-model-reindex",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_selectable_target_is_stored_with_its_canonical_name(
|
||||
mocks: _EndpointMocks,
|
||||
present: MagicMock,
|
||||
target: SearchSettingsCreationRequest,
|
||||
stored_name: str,
|
||||
) -> None:
|
||||
"""The model server and the tokenizer match registry names exactly. A variant
|
||||
would load without the pinned revision and the model's fix-ups."""
|
||||
mocks.current.return_value = present
|
||||
|
||||
with pytest.raises(_GuardPassed):
|
||||
_submit(target)
|
||||
|
||||
created = mocks.created_settings()
|
||||
assert created.model_name == stored_name
|
||||
assert created.index_name is not None
|
||||
assert created.index_name.startswith(
|
||||
f"danswer_chunk_{clean_model_name(stored_name)}"
|
||||
)
|
||||
mocks.probe.assert_not_called()
|
||||
|
||||
|
||||
def test_rejected_target_creates_nothing(mocks: _EndpointMocks) -> None:
|
||||
mocks.current.return_value = _present(GRANITE)
|
||||
|
||||
with pytest.raises(OnyxError) as exc:
|
||||
_submit(_spec_request(COHERE, "embed-english-v3.0"))
|
||||
|
||||
assert exc.value.error_code == OnyxErrorCode.INVALID_INPUT
|
||||
# Only Bifrost and selectable cloud targets are probed.
|
||||
mocks.probe.assert_not_called()
|
||||
mocks.create.assert_not_called()
|
||||
|
||||
|
||||
def test_cloud_probe_failure_blocks_the_reindex(mocks: _EndpointMocks) -> None:
|
||||
mocks.probe.side_effect = OnyxError(OnyxErrorCode.VALIDATION_ERROR, "no access")
|
||||
|
||||
with pytest.raises(OnyxError) as exc:
|
||||
_submit(_spec_request(GOOGLE, "gemini-embedding-2"))
|
||||
|
||||
assert exc.value.detail == "no access"
|
||||
mocks.create.assert_not_called()
|
||||
mocks.current.assert_not_called()
|
||||
|
||||
|
||||
def test_cloud_probe_uses_the_stored_vertex_config() -> None:
|
||||
"""A Workload Identity provider has no service account JSON, so the probe
|
||||
needs the stored vertex_config to authenticate."""
|
||||
provider = MagicMock()
|
||||
provider.provider_type = EmbeddingProvider.GOOGLE
|
||||
provider.api_key = None
|
||||
provider.api_url = None
|
||||
provider.api_version = None
|
||||
provider.deployment_name = None
|
||||
provider.vertex_config = {
|
||||
"auth_method": "workload_identity",
|
||||
"project_id": "target-project",
|
||||
"location": "us",
|
||||
}
|
||||
|
||||
with patch(f"{_MODULE}.probe_embedding_dimension", return_value=3072) as probe:
|
||||
_validate_cloud_embedding_model(
|
||||
_spec_request(GOOGLE, "gemini-embedding-2"), provider
|
||||
)
|
||||
|
||||
auth = probe.call_args.kwargs["auth"]
|
||||
assert isinstance(auth, VertexEmbeddingAuth)
|
||||
assert auth.config.auth_method == "workload_identity"
|
||||
assert auth.config.project_id == "target-project"
|
||||
assert probe.call_args.kwargs["model_name"] == "gemini-embedding-2"
|
||||
@@ -45,6 +45,7 @@ def _provider(
|
||||
provider.provider_type = provider_type
|
||||
provider.api_url = "https://bifrost.example"
|
||||
provider.api_key.get_value.return_value = "sk-bf-stored"
|
||||
provider.vertex_config = None
|
||||
return provider
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,112 @@
|
||||
"""API server startup waits for the model server to load the self-hosted
|
||||
embedding model, and fails with a clear error when the wait runs out."""
|
||||
|
||||
import threading
|
||||
from collections.abc import Iterator
|
||||
from unittest.mock import MagicMock, patch
|
||||
|
||||
import pytest
|
||||
|
||||
from onyx.setup import wait_for_local_embedding_model
|
||||
|
||||
_NOMIC = "nomic-ai/nomic-embed-text-v1"
|
||||
_NOT_CACHED_ERROR = (
|
||||
"HTTP error occurred: Error during embedding process: nomic-ai/nomic-embed-text-v1 "
|
||||
"is not in the model server's Hugging Face cache and could not be downloaded"
|
||||
)
|
||||
|
||||
|
||||
class _FakeClock:
|
||||
"""Stands in for the `time` module in onyx.setup: sleep advances monotonic."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self.now = 0.0
|
||||
self.sleeps: list[float] = []
|
||||
|
||||
def monotonic(self) -> float:
|
||||
return self.now
|
||||
|
||||
def sleep(self, seconds: float) -> None:
|
||||
self.sleeps.append(seconds)
|
||||
self.now += seconds
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def clock() -> Iterator[_FakeClock]:
|
||||
fake = _FakeClock()
|
||||
with patch("onyx.setup.time", fake):
|
||||
yield fake
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def encode() -> Iterator[MagicMock]:
|
||||
with patch("onyx.setup.EmbeddingModel") as embedding_model_cls:
|
||||
yield embedding_model_cls.from_db_model.return_value.encode
|
||||
|
||||
|
||||
def _search_settings() -> MagicMock:
|
||||
settings = MagicMock()
|
||||
settings.model_name = _NOMIC
|
||||
return settings
|
||||
|
||||
|
||||
def test_retries_until_the_model_server_is_ready(
|
||||
clock: _FakeClock, encode: MagicMock
|
||||
) -> None:
|
||||
encode.side_effect = [
|
||||
Exception("Request failed: Connection refused"),
|
||||
Exception(_NOT_CACHED_ERROR),
|
||||
[[0.1, 0.2]],
|
||||
]
|
||||
|
||||
wait_for_local_embedding_model(_search_settings())
|
||||
|
||||
assert encode.call_count == 3
|
||||
assert clock.sleeps == [10, 10]
|
||||
|
||||
|
||||
def test_fails_with_the_last_error_when_the_wait_runs_out(
|
||||
clock: _FakeClock, encode: MagicMock
|
||||
) -> None:
|
||||
encode.side_effect = Exception(_NOT_CACHED_ERROR)
|
||||
|
||||
with (
|
||||
patch("onyx.setup.LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT", 30),
|
||||
pytest.raises(RuntimeError) as exc_info,
|
||||
):
|
||||
wait_for_local_embedding_model(_search_settings())
|
||||
|
||||
# The operator sees the last error and the setting that controls the wait.
|
||||
assert _NOT_CACHED_ERROR in str(exc_info.value)
|
||||
assert "LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT" in str(exc_info.value)
|
||||
assert str(exc_info.value.__cause__) == _NOT_CACHED_ERROR
|
||||
assert encode.call_count == 3
|
||||
assert clock.now == 30
|
||||
|
||||
|
||||
@pytest.mark.usefixtures("clock")
|
||||
def test_fails_when_a_request_is_still_waiting_at_the_deadline(
|
||||
encode: MagicMock,
|
||||
) -> None:
|
||||
release = threading.Event()
|
||||
started = threading.Event()
|
||||
request_threads: list[threading.Thread] = []
|
||||
|
||||
def wait_for_release(**_: object) -> None:
|
||||
request_threads.append(threading.current_thread())
|
||||
started.set()
|
||||
release.wait()
|
||||
|
||||
encode.side_effect = wait_for_release
|
||||
try:
|
||||
with (
|
||||
patch("onyx.setup.LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT", 0.1),
|
||||
pytest.raises(RuntimeError, match="still waiting for the model server"),
|
||||
):
|
||||
wait_for_local_embedding_model(_search_settings())
|
||||
# The waiting request must not keep the failed process from exiting.
|
||||
# On a slow runner, the request thread can start after the deadline.
|
||||
assert started.wait(timeout=5)
|
||||
assert [thread.daemon for thread in request_threads] == [True]
|
||||
finally:
|
||||
release.set()
|
||||
@@ -0,0 +1,50 @@
|
||||
"""Integrity of the shared embedding-model registry."""
|
||||
|
||||
import re
|
||||
import subprocess
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from shared_configs.embedding_models import (
|
||||
EMBEDDING_MODEL_SPECS,
|
||||
EmbeddingModelStatus,
|
||||
LocalModelLoader,
|
||||
)
|
||||
|
||||
_BACKEND_DIR = Path(__file__).resolve().parents[3]
|
||||
|
||||
|
||||
def test_registry_invariants() -> None:
|
||||
for spec in EMBEDDING_MODEL_SPECS:
|
||||
# get_local_model_spec only matches pinned entries, so a selectable
|
||||
# self-hosted model without a revision would get the legacy load.
|
||||
needs_revision = spec.provider_type is None and (
|
||||
spec.status == EmbeddingModelStatus.SELECTABLE
|
||||
)
|
||||
assert (spec.hf_revision is not None) == needs_revision, spec.model_name
|
||||
if spec.hf_revision is not None:
|
||||
assert re.fullmatch(r"[0-9a-f]{40}", spec.hf_revision), spec.model_name
|
||||
if spec.provider_type is not None:
|
||||
# The cloud path refuses prefixes, and loader settings are local-only.
|
||||
assert spec.query_prefix == spec.passage_prefix == "", spec.model_name
|
||||
assert spec.normalize is False, spec.model_name
|
||||
assert spec.loader == LocalModelLoader.STANDARD, spec.model_name
|
||||
|
||||
|
||||
def test_registry_imports_no_onyx_or_ml_packages() -> None:
|
||||
"""The model-server image has no onyx package and the API image has no torch."""
|
||||
code = (
|
||||
"import sys\n"
|
||||
"import shared_configs.embedding_models\n"
|
||||
"banned = {'onyx', 'ee', 'model_server', 'torch', 'transformers',"
|
||||
" 'sentence_transformers'}\n"
|
||||
"print(sorted(m for m in sys.modules if m.split('.')[0] in banned))\n"
|
||||
)
|
||||
result = subprocess.run(
|
||||
[sys.executable, "-c", code],
|
||||
cwd=_BACKEND_DIR,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
check=True,
|
||||
)
|
||||
assert result.stdout.strip() == "[]"
|
||||
@@ -0,0 +1,89 @@
|
||||
"""The web model picker mirrors the backend embedding model registry.
|
||||
|
||||
The admin page sends a model's name, dimension, normalize flag and prefixes
|
||||
as-is to set-new-search-settings, and the upgrade-only guard rejects a
|
||||
selectable model whose values differ from the backend registry. So the two
|
||||
copies must agree, and a model the backend treats as legacy must be marked
|
||||
legacy in the web registry (the picker hides it)."""
|
||||
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
from shared_configs.embedding_models import (
|
||||
EMBEDDING_MODEL_SPECS,
|
||||
EmbeddingModelStatus,
|
||||
)
|
||||
from shared_configs.enums import EmbeddingProvider
|
||||
|
||||
_WEB_REGISTRY = (
|
||||
Path(__file__).resolve().parents[4]
|
||||
/ "web"
|
||||
/ "src"
|
||||
/ "lib"
|
||||
/ "searchSettings"
|
||||
/ "constants.ts"
|
||||
)
|
||||
_GROUP = re.compile(r"providerName:\s*EmbeddingProviderName\.(\w+)")
|
||||
# Model objects hold no nested braces.
|
||||
_MODEL_BLOCK = re.compile(r"\{([^{}]*\bmodelName:[^{}]*)\}")
|
||||
|
||||
# (provider_type, model_name) -> (dim, normalize, query_prefix, passage_prefix,
|
||||
# legacy). Legacy values are informational only, so a legacy entry keeps only
|
||||
# its legacy flag.
|
||||
_ModelKey = tuple[EmbeddingProvider | None, str]
|
||||
_ModelValues = tuple[int | None, bool | None, str | None, str | None, bool]
|
||||
|
||||
|
||||
def _field(block: str, name: str, value_pattern: str) -> str:
|
||||
match = re.search(rf"\b{name}:\s*{value_pattern}", block)
|
||||
assert match, f"No literal `{name}` in a model of {_WEB_REGISTRY.name}:\n{block}"
|
||||
return match.group(1)
|
||||
|
||||
|
||||
def _web_models() -> dict[_ModelKey, _ModelValues]:
|
||||
source = _WEB_REGISTRY.read_text()
|
||||
source = source[: source.index("export const CUSTOM_PROVIDER")]
|
||||
self_hosted_start = source.index("export const SELF_HOSTED_PROVIDERS")
|
||||
groups = list(_GROUP.finditer(source))
|
||||
group_ends = [group.start() for group in groups[1:]] + [len(source)]
|
||||
models: dict[_ModelKey, _ModelValues] = {}
|
||||
for group, end in zip(groups, group_ends, strict=True):
|
||||
# Self-hosted groups have provider_type None on the backend.
|
||||
provider_type = (
|
||||
None
|
||||
if group.start() > self_hosted_start
|
||||
else EmbeddingProvider(group.group(1).lower())
|
||||
)
|
||||
for block in _MODEL_BLOCK.findall(source[group.end() : end]):
|
||||
key = (provider_type, _field(block, "modelName", r'"([^"]*)"'))
|
||||
assert key not in models, f"Duplicate model {key} in the web registry"
|
||||
if re.search(r"\blegacy:\s*true\b", block):
|
||||
models[key] = (None, None, None, None, True)
|
||||
continue
|
||||
models[key] = (
|
||||
int(_field(block, "modelDim", r"(\d+)")),
|
||||
_field(block, "normalize", r"(true|false)") == "true",
|
||||
_field(block, "queryPrefix", r'"([^"]*)"'),
|
||||
_field(block, "passagePrefix", r'"([^"]*)"'),
|
||||
False,
|
||||
)
|
||||
return models
|
||||
|
||||
|
||||
def test_web_registry_matches_the_backend_registry() -> None:
|
||||
expected: dict[_ModelKey, _ModelValues] = {
|
||||
(spec.provider_type, spec.model_name): (
|
||||
(None, None, None, None, True)
|
||||
if spec.status == EmbeddingModelStatus.LEGACY
|
||||
else (
|
||||
spec.model_dim,
|
||||
spec.normalize,
|
||||
spec.query_prefix,
|
||||
spec.passage_prefix,
|
||||
False,
|
||||
)
|
||||
)
|
||||
for spec in EMBEDDING_MODEL_SPECS
|
||||
}
|
||||
|
||||
assert _web_models() == expected
|
||||
@@ -135,3 +135,20 @@ Every image publishes a `-dev` twin for each of its tags (e.g. `latest-dev`, `v1
|
||||
its `-dev` twin adds interactive debugging tools (vim, nano, curl, ps, psql) that the default image leaves out to stay
|
||||
minimal. The web-server, model-server, and sandbox `-dev` tags are identical to their plain counterparts and exist so
|
||||
that one version string covers every image.
|
||||
|
||||
### Self-hosted embedding models and air-gapped deployments
|
||||
The model-server image contains one embedding model: `ibm-granite/granite-embedding-97m-multilingual-r2`,
|
||||
the default for new installs. It works with no network access.
|
||||
|
||||
The model servers download all other self-hosted embedding models from Hugging Face the first time
|
||||
they use them. This includes `nomic-ai/nomic-embed-text-v1`, which older images contained. The
|
||||
downloads go to the `model_cache_huggingface` and `indexing_huggingface_model_cache` volumes.
|
||||
When a model is in these volumes, the model servers load it from there with no network access. An
|
||||
upgrade keeps the models that are already in the volumes.
|
||||
|
||||
For an air-gapped deployment:
|
||||
- Keep these volumes when you upgrade. Do not delete them.
|
||||
- To use a self-hosted model that is not in the volumes, give the model servers network access to
|
||||
Hugging Face once, or copy the model into the Hugging Face cache in both volumes before you select it.
|
||||
Onyx loads its recommended self-hosted models at the revision that
|
||||
`backend/shared_configs/embedding_models.py` pins, so copy that revision.
|
||||
@@ -398,6 +398,10 @@ LOG_ONYX_MODEL_INTERACTIONS=False
|
||||
# ASYM_PASSAGE_PREFIX=
|
||||
# DISABLE_RERANK_FOR_STREAMING=
|
||||
# MODEL_SERVER_PORT=
|
||||
# Seconds the API server waits on startup for the model server to load a self-hosted
|
||||
# embedding model, including a download if it is not cached (default 1800). Startup
|
||||
# fails when the wait runs out. 0 disables the wait.
|
||||
# LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT=
|
||||
# INDEX_BATCH_SIZE=
|
||||
# MIN_THREADS_ML_MODELS=
|
||||
|
||||
|
||||
@@ -5,7 +5,7 @@ home: https://www.onyx.app/
|
||||
sources:
|
||||
- "https://github.com/onyx-dot-app/onyx"
|
||||
type: application
|
||||
version: 0.9.18
|
||||
version: 0.9.19
|
||||
appVersion: latest
|
||||
annotations:
|
||||
category: Productivity
|
||||
@@ -21,9 +21,9 @@ annotations:
|
||||
image: docker.io/onyxdotapp/onyx-backend:latest
|
||||
artifacthub.io/changes: |
|
||||
- kind: added
|
||||
description: Add the TABULAR_RECHUNK_ENABLED setting. It runs a one-time
|
||||
migration that re-chunks already indexed tabular documents with the current
|
||||
chunker, without re-crawling the source.
|
||||
description: Add the LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT setting. The API
|
||||
server waits on startup until the model server loads the self-hosted
|
||||
embedding model, which includes a download if it is not cached.
|
||||
dependencies:
|
||||
# Helm uses the first condition path that exists: `postgresqlOperator.enabled`
|
||||
# is unset by default, so this falls through to `postgresql.enabled`. Set it
|
||||
|
||||
@@ -201,6 +201,19 @@ autoscaling:
|
||||
|
||||
inferenceCapability:
|
||||
extraEnv: []
|
||||
# Optional Hugging Face cache volume. Without one, a model that the image
|
||||
# does not bundle (only the default model is bundled; nomic is not) downloads
|
||||
# again on every pod start. At startup, the model server copies the bundled
|
||||
# model into the volume. The chart does not create the claim. With a
|
||||
# ReadWriteOnce claim, keep replicaCount at 1 and set strategy.type: Recreate.
|
||||
# Give indexCapability its own claim.
|
||||
# volumes:
|
||||
# - name: hf-cache
|
||||
# persistentVolumeClaim:
|
||||
# claimName: onyx-inference-model-hf-cache
|
||||
# volumeMounts:
|
||||
# - name: hf-cache
|
||||
# mountPath: /app/.cache/huggingface
|
||||
volumes: []
|
||||
volumeMounts: []
|
||||
service:
|
||||
@@ -278,6 +291,7 @@ inferenceCapability:
|
||||
|
||||
indexCapability:
|
||||
extraEnv: []
|
||||
# Optional Hugging Face cache volume: see inferenceCapability.volumes.
|
||||
volumes: []
|
||||
volumeMounts: []
|
||||
service:
|
||||
@@ -624,10 +638,21 @@ api:
|
||||
# every replica at once, and a lone not-ready pod leaves the Service empty.
|
||||
# Do NOT put /health/ready on the liveness probe.
|
||||
#
|
||||
# Liveness and startup probes stay opt-in. Size a startupProbe for the longest
|
||||
# migration you expect, or it kills the pod mid-migration.
|
||||
# Liveness and startup probes stay opt-in. /health answers only after startup:
|
||||
# the migrations, then the wait for the model server to load a self-hosted
|
||||
# embedding model, with a download if it is not cached (up to
|
||||
# LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT, 1800 s by default). A livenessProbe
|
||||
# with no startupProbe therefore restarts the pod during a download. Size the
|
||||
# startupProbe (periodSeconds x failureThreshold) for the longest migration
|
||||
# you expect plus that timeout.
|
||||
#
|
||||
# Example:
|
||||
# startupProbe:
|
||||
# httpGet:
|
||||
# path: /health
|
||||
# port: api-server-port
|
||||
# periodSeconds: 10
|
||||
# failureThreshold: 200 # 2000 s
|
||||
# readinessProbe:
|
||||
# httpGet:
|
||||
# path: /health/ready
|
||||
@@ -1755,6 +1780,10 @@ configMap:
|
||||
ASYM_PASSAGE_PREFIX: ""
|
||||
DISABLE_RERANK_FOR_STREAMING: ""
|
||||
MODEL_SERVER_PORT: ""
|
||||
# Seconds the API server waits on startup for the model server to load a
|
||||
# self-hosted embedding model, including a download if it is not cached;
|
||||
# "" = 1800. Startup fails when the wait runs out. "0" disables the wait.
|
||||
LOCAL_EMBEDDING_MODEL_STARTUP_TIMEOUT: ""
|
||||
MIN_THREADS_ML_MODELS: ""
|
||||
# Indexing Configs
|
||||
NUM_INDEXING_WORKERS: ""
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "الاسترجاع السياقي معطّل لعدم وجود نماذج مهيأة. قم بإعداد [نموذج لغة]({link}) أولًا.",
|
||||
"title": "الاسترجاع السياقي"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "هذا نموذج قديم. يستمر في العمل، لكن لا يمكنك اختياره مرة أخرى لفهرس جديد. للترقية، انقر على «عرض جميع النماذج» واختر نموذجًا أحدث."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "نموذج التضمين وإعداداته يديرهما Onyx Cloud."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "النموذج الحالي"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "نموذج التضمين هذا مهمل ولا يمكن الاتصال به.",
|
||||
"selectTooltip": "نموذج التضمين هذا مهمل ولا يمكن اختياره."
|
||||
"gpuRecommended": {
|
||||
"tag": "يُنصح باستخدام GPU"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "قديم",
|
||||
"tooltip": "لا يمكنك اختيار هذا النموذج لفهرس جديد. يستمر في العمل حتى تغيّر النموذج."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "اختيار النموذج"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "سرعات CPU تقديرية وتختلف حسب العتاد وحجم المستند. توصيات RAM تخص نموذجًا واحدًا محمّلًا، وليست متطلبات نظام Onyx بالكامل. وفّر ذاكرة إضافية أثناء إعادة الفهرسة.",
|
||||
"addCustomModel": {
|
||||
"label": "إضافة نموذج مخصص"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "اربط وكيل LiteLLM أو نشر Azure OpenAI أو بوابة Bifrost. تحدد أنت اسم النموذج. وفي LiteLLM وAzure تحدد أيضًا الأبعاد.",
|
||||
"selfHostedDescription": "شغّل نموذج تضمين من Hugging Face غير موجود في القائمة أعلاه. تحدد أنت اسم النموذج وأبعاده وبادئاته.",
|
||||
"title": "متقدم: استخدم نموذجك أو الوكيل الخاص بك"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "سحابي"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"title": "{count, plural, one {سيُحذف هذا الموصل} other {ستُحذف هذه الموصلات (#)}}"
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "أفضل نموذج تضمين من Cohere. أفضل توازن بين الجودة والتكلفة. مخرجات بأبعاد 2048.",
|
||||
"cohereEmbedV5Fast": "إصدار أقل تكلفة من Embed 5 من Cohere. ولا يزال خيارًا ممتازًا. مخرجات بأبعاد 2048.",
|
||||
"cohereEmbedEnglishV3": "نموذج التضمين الإنجليزي من Cohere. أداء جيد للمهام باللغة الإنجليزية.",
|
||||
"cohereEmbedEnglishLightV3": "نموذج التضمين الإنجليزي الخفيف من Cohere. أسرع وأكثر كفاءة للمهام الأبسط.",
|
||||
"cohereEmbedV4": "أحدث نموذج تضمين متعدد اللغات من Cohere بمخرجات افتراضية بأبعاد 1536 لجودة استرجاع أعلى.",
|
||||
"openaiTextEmbedding3Large": "نموذج التضمين الكبير من OpenAI. أفضل أداء لكنه أعلى تكلفة.",
|
||||
"openaiTextEmbedding3Small": "نموذج التضمين الأحدث والأكثر كفاءة من OpenAI. توازن جيد بين الأداء والتكلفة.",
|
||||
"cohereEmbedV4": "نموذج التضمين متعدد اللغات من Cohere، بمخرجات بأبعاد 1536.",
|
||||
"openaiTextEmbedding3Large": "نموذج التضمين الكبير من OpenAI. خيار جيد إذا كنت تستخدم OpenAI بالفعل. مخرجات بأبعاد 3072.",
|
||||
"openaiTextEmbedding3Small": "نموذج التضمين الصغير من OpenAI. الخيار السحابي الأكثر اقتصادًا بفارق كبير. مخرجات بأبعاد 1536.",
|
||||
"googleGeminiEmbedding001": "نموذج تضمين Gemini من Google. قوي وفعّال.",
|
||||
"googleTextEmbedding005": "نموذج تضمين أصغر وأخف من Google.",
|
||||
"googleGeminiEmbedding2": "أحدث نموذج تضمين متعدد الوسائط من Google (متاح للعموم). أعلى جودة استرجاع بمخرجات بأبعاد 3072.",
|
||||
"googleGeminiEmbedding2": "أفضل نموذج تضمين من Google. قوي جدًا، لكنه مكلف وأبطأ. مخرجاته بأبعاد 3072 تبني فهرسًا كبيرًا. خيار متين للفرق التي تستخدم Google بالفعل.",
|
||||
"googleGeminiEmbedding2Preview": "الإصدار التجريبي من Gemini Embedding 2. حلّ محله gemini-embedding-2 في عمليات الإعداد الجديدة.",
|
||||
"voyageLarge2Instruct": "نموذج التضمين الكبير من Voyage. أداء عالٍ مع ضبط دقيق بالتعليمات.",
|
||||
"voyage4Large": "أكبر نموذج تضمين في سلسلة Voyage 4. أفضل جودة استرجاع لدى Voyage، ويدعم لغات متعددة.",
|
||||
"voyage4": "نموذج التضمين متعدد الأغراض من سلسلة Voyage 4. جودة استرجاع عالية بتكلفة معتدلة.",
|
||||
"voyage4Lite": "نموذج التضمين الخفيف من سلسلة Voyage 4. أقل تكلفة وأعلى حدود للمعدل.",
|
||||
"voyageLight2Instruct": "نموذج التضمين الخفيف من Voyage. توازن جيد بين الأداء والكفاءة.",
|
||||
"graniteEmbedding97mMultilingualR2": "نموذج IBM الصغير متعدد اللغات. مضمّن مع {appName}. 97 مليون معلمة ومخرجات ذات 384 بُعدًا. حتى 200 مستند / دقيقة / نواة CPU. ذاكرة RAM الموصى بها للتشغيل على CPU: 4 جيجابايت لكل خادم نماذج.",
|
||||
"voyage4Nano": "نموذج Voyage AI ذو الأوزان المفتوحة. 346 مليون معلمة ومخرجات ذات 2048 بُعدًا. حتى 50 مستندًا / دقيقة / نواة CPU. ذاكرة RAM الموصى بها للتشغيل على CPU: 4 جيجابايت لكل خادم نماذج.",
|
||||
"nemotron3Embed1b": "نموذج NVIDIA متعدد اللغات. 1.1 مليار معلمة ومخرجات ذات 2048 بُعدًا. حتى 5 مستندات / دقيقة / نواة CPU. ذاكرة RAM الموصى بها للتشغيل على CPU: 8 جيجابايت لكل خادم نماذج. يُنصح باستخدام GPU.",
|
||||
"nomicEmbedTextV1": "نموذج التضمين من Nomic المتخصص في الاسترجاع والتشابه والتجميع والتصنيف.",
|
||||
"e5BaseV2": "نموذج أصغر وأسرع من النموذج الافتراضي. أسرع بنحو مرتين من النموذج الافتراضي على حساب جودة بحث أقل.",
|
||||
"e5BaseV2": "نموذج تضمين للغة الإنجليزية من عائلة E5 من Microsoft. يوازن بين السرعة وجودة البحث.",
|
||||
"e5SmallV2": "أصغر وأسرع إصدار من سلسلة نماذج E5. إذا كنت تشغّل {appName} على نظام محدود الموارد فقد يكون هذا خيارًا جيدًا.",
|
||||
"multilingualE5Base": "للمجموعات النصية بلغات غير الإنجليزية، هذا هو الخيار المناسب.",
|
||||
"multilingualE5Small": "للمجموعات النصية بلغات غير الإنجليزية مع نظام محدود الموارد، هذا هو الخيار المناسب."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "Contextual Retrieval ist deaktiviert, weil keine Modelle konfiguriert sind. Richten Sie zuerst ein [Sprachmodell]({link}) ein.",
|
||||
"title": "Contextual Retrieval"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "Dies ist ein veraltetes Modell. Es funktioniert weiter, aber Sie können es nicht erneut für einen neuen Index auswählen. Klicken Sie zum Upgrade auf „Alle Modelle anzeigen“ und wählen Sie ein neueres Modell."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "Das Embedding-Modell und die Einstellungen werden von Onyx Cloud verwaltet."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "Aktuelles Modell"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "Dieses Embedding-Modell ist veraltet und kann nicht verbunden werden.",
|
||||
"selectTooltip": "Dieses Embedding-Modell ist veraltet und kann nicht ausgewählt werden."
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU empfohlen"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "Veraltet",
|
||||
"tooltip": "Sie können dieses Modell nicht für einen neuen Index auswählen. Es funktioniert weiter, bis Sie das Modell wechseln."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "Modell auswählen"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "CPU-Geschwindigkeiten sind Schätzungen und hängen von Hardware und Dokumentgröße ab. RAM-Empfehlungen gelten für ein geladenes Modell, nicht für den gesamten Onyx-Stack. Planen Sie beim Neuindizieren mehr Speicher ein.",
|
||||
"addCustomModel": {
|
||||
"label": "Benutzerdefiniertes Modell hinzufügen"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "Verbinden Sie einen LiteLLM-Proxy, ein Azure-OpenAI-Deployment oder ein Bifrost-Gateway. Den Modellnamen geben Sie selbst an. Für LiteLLM und Azure geben Sie auch die Dimension an.",
|
||||
"selfHostedDescription": "Betreiben Sie ein Hugging-Face-Embedding-Modell, das nicht in der Liste oben steht. Modellname, Dimension und Präfixe geben Sie selbst an.",
|
||||
"title": "Erweitert: eigenes Modell oder eigenen Proxy verwenden"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "Cloud-basiert"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "Um einen Konnektor zu behalten, brechen Sie hier ab, setzen Sie ihn fort oder korrigieren Sie ihn und starten Sie die Neuindizierung erneut – dann wird er übernommen. Andernfalls fügen Sie ihn nach Abschluss der Neuindizierung erneut hinzu."
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "Das Top-Embedding-Modell von Cohere. Das beste Verhältnis von Qualität und Kosten. 2048 Dimensionen.",
|
||||
"cohereEmbedV5Fast": "Günstigere Variante von Embed 5 von Cohere. Trotzdem eine ausgezeichnete Wahl. 2048 Dimensionen.",
|
||||
"cohereEmbedEnglishV3": "Englisches Embedding-Modell von Cohere. Gute Leistung bei englischsprachigen Aufgaben.",
|
||||
"cohereEmbedEnglishLightV3": "Leichtgewichtiges englisches Embedding-Modell von Cohere. Schneller und effizienter für einfachere Aufgaben.",
|
||||
"cohereEmbedV4": "Neuestes mehrsprachiges Embedding-Modell von Cohere mit standardmäßig 1536 Dimensionen für bessere Retrieval-Qualität.",
|
||||
"openaiTextEmbedding3Large": "Großes Embedding-Modell von OpenAI. Beste Leistung, aber teurer.",
|
||||
"openaiTextEmbedding3Small": "Neueres, effizienteres Embedding-Modell von OpenAI. Gutes Verhältnis von Leistung und Kosten.",
|
||||
"cohereEmbedV4": "Mehrsprachiges Embedding-Modell von Cohere mit 1536 Dimensionen.",
|
||||
"openaiTextEmbedding3Large": "Großes Embedding-Modell von OpenAI. Eine gute Wahl, wenn Sie OpenAI bereits nutzen. 3072 Dimensionen.",
|
||||
"openaiTextEmbedding3Small": "Kleines Embedding-Modell von OpenAI. Mit Abstand die günstigste Cloud-basierte Option. 1536 Dimensionen.",
|
||||
"googleGeminiEmbedding001": "Gemini-Embedding-Modell von Google. Leistungsstark und effizient.",
|
||||
"googleTextEmbedding005": "Kleineres, leichteres Embedding-Modell von Google.",
|
||||
"googleGeminiEmbedding2": "Neuestes multimodales Embedding-Modell von Google (GA). Höchste Retrieval-Qualität mit 3072 Dimensionen.",
|
||||
"googleGeminiEmbedding2": "Das Top-Embedding-Modell von Google. Sehr leistungsstark, aber teuer und langsamer. Mit 3072 Dimensionen entsteht ein großer Index. Eine solide Wahl für Teams, die Google bereits nutzen.",
|
||||
"googleGeminiEmbedding2Preview": "Vorschauversion von Gemini Embedding 2. Für neue Einrichtungen durch gemini-embedding-2 ersetzt.",
|
||||
"voyageLarge2Instruct": "Großes Embedding-Modell von Voyage. Hohe Leistung durch Instruction-Fine-Tuning.",
|
||||
"voyage4Large": "Größtes Embedding-Modell der Voyage-4-Serie. Beste Retrieval-Qualität von Voyage, mehrsprachig.",
|
||||
"voyage4": "Universelles Embedding-Modell der Voyage-4-Serie. Hohe Retrieval-Qualität zu moderaten Kosten.",
|
||||
"voyage4Lite": "Leichtgewichtiges Embedding-Modell der Voyage-4-Serie. Niedrigste Kosten und höchste Rate-Limits.",
|
||||
"voyageLight2Instruct": "Leichtgewichtiges Embedding-Modell von Voyage. Gutes Verhältnis von Leistung und Effizienz.",
|
||||
"graniteEmbedding97mMultilingualR2": "Das kleine mehrsprachige Modell von IBM. In {appName} enthalten. 97 Mio. Parameter, 384 Dimensionen. Bis zu 200 Dokumente / Min. / CPU-Kern. Empfohlener CPU-RAM: 4 GB pro Modellserver.",
|
||||
"voyage4Nano": "Das Modell mit offenen Gewichten von Voyage AI. 346 Mio. Parameter, 2048 Dimensionen. Bis zu 50 Dokumente / Min. / CPU-Kern. Empfohlener CPU-RAM: 4 GB pro Modellserver.",
|
||||
"nemotron3Embed1b": "Das mehrsprachige Modell von NVIDIA. 1,1 Mrd. Parameter, 2048 Dimensionen. Bis zu 5 Dokumente / Min. / CPU-Kern. Empfohlener CPU-RAM: 8 GB pro Modellserver. GPU empfohlen.",
|
||||
"nomicEmbedTextV1": "Embedding-Modell von Nomic, spezialisiert auf Retrieval, Ähnlichkeit, Clustering und Klassifikation.",
|
||||
"e5BaseV2": "Ein kleineres und schnelleres Modell als der Standard. Etwa doppelt so schnell wie das Standardmodell, bei geringerer Suchqualität.",
|
||||
"e5BaseV2": "Englisches Embedding-Modell aus der E5-Familie von Microsoft. Ausgewogen zwischen Geschwindigkeit und Suchqualität.",
|
||||
"e5SmallV2": "Die kleinste und schnellste Variante der E5-Modellreihe. Eine gute Wahl, wenn {appName} auf einem System mit begrenzten Ressourcen läuft.",
|
||||
"multilingualE5Base": "Für Korpora in anderen Sprachen als Englisch ist dies die richtige Wahl.",
|
||||
"multilingualE5Small": "Für Korpora in anderen Sprachen als Englisch auf einem System mit begrenzten Ressourcen ist dies die richtige Wahl."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "Contextual Retrieval is disabled because you have no models configured. Set up a [Language Model]({link}) first.",
|
||||
"title": "Contextual Retrieval"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "This is a legacy model. It keeps working, but you cannot select it again for a new index. To upgrade, click View All Models and select a newer model."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "Embedding model and settings are managed by Onyx Cloud."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "Current Model"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "This embedding model is deprecated and cannot be connected to.",
|
||||
"selectTooltip": "This embedding model is deprecated and cannot be selected."
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU recommended"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "Legacy",
|
||||
"tooltip": "You cannot select this model for a new index. It keeps working until you change the model."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "Select Model"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "CPU speeds are estimates and vary with hardware and document size. RAM recommendations cover one loaded model, not the full Onyx stack. Allow more memory during re-indexing.",
|
||||
"addCustomModel": {
|
||||
"label": "Add Custom Model"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "Connect a LiteLLM proxy, an Azure OpenAI deployment or a Bifrost gateway. You supply the model name. For LiteLLM and Azure, you also supply the dimension.",
|
||||
"selfHostedDescription": "Run a Hugging Face embedding model that is not in the list above. You supply the model name, dimension and prefixes.",
|
||||
"title": "Advanced: bring your own model or proxy"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "Cloud-based"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "To keep a connector, cancel here, resume or fix it, then re-index — it will be carried over. Otherwise, add it back once the re-index finishes."
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "Cohere's top embedding model. The best balance of quality and cost. 2048-dim output.",
|
||||
"cohereEmbedV5Fast": "A lower-cost version of Cohere's Embed 5. Still an excellent option. 2048-dim output.",
|
||||
"cohereEmbedEnglishV3": "Cohere's English embedding model. Good performance for English-language tasks.",
|
||||
"cohereEmbedEnglishLightV3": "Cohere's lightweight English embedding model. Faster and more efficient for simpler tasks.",
|
||||
"cohereEmbedV4": "Cohere's latest multilingual embedding model with the default 1536-dim output for stronger retrieval quality.",
|
||||
"openaiTextEmbedding3Large": "OpenAI's large embedding model. Best performance, but more expensive.",
|
||||
"openaiTextEmbedding3Small": "OpenAI's newer, more efficient embedding model. Good balance of performance and cost.",
|
||||
"cohereEmbedV4": "Cohere's multilingual embedding model, with a 1536-dim output.",
|
||||
"openaiTextEmbedding3Large": "OpenAI's large embedding model. A good choice if you already use OpenAI. 3072-dim output.",
|
||||
"openaiTextEmbedding3Small": "OpenAI's small embedding model. By far the most economical cloud-based option. 1536-dim output.",
|
||||
"googleGeminiEmbedding001": "Google's Gemini embedding model. Powerful and efficient.",
|
||||
"googleTextEmbedding005": "Smaller, lighter-weight embedding model from Google.",
|
||||
"googleGeminiEmbedding2": "Google's latest multimodal embedding model (GA). Highest-quality retrieval with a 3072-dim output.",
|
||||
"googleGeminiEmbedding2": "Google's top embedding model. Very powerful, but expensive and slower. Its 3072-dim output builds a large index. A solid choice for teams that already use Google.",
|
||||
"googleGeminiEmbedding2Preview": "Preview version of Gemini Embedding 2. Superseded by gemini-embedding-2 for new setups.",
|
||||
"voyageLarge2Instruct": "Voyage's large embedding model. High performance with instruction fine-tuning.",
|
||||
"voyage4Large": "Voyage's largest 4-series embedding model. Best Voyage retrieval quality, multilingual.",
|
||||
"voyage4": "Voyage's general-purpose 4-series embedding model. High retrieval quality at moderate cost.",
|
||||
"voyage4Lite": "Voyage's lightweight 4-series embedding model. Lowest cost and highest rate limits.",
|
||||
"voyageLight2Instruct": "Voyage's lightweight embedding model. Good balance of performance and efficiency.",
|
||||
"graniteEmbedding97mMultilingualR2": "IBM's small multilingual model. Ships with {appName}. 97M parameters, 384-dim output. Up to 200 docs / min / CPU core. Recommended CPU RAM: 4 GB per model server.",
|
||||
"voyage4Nano": "Voyage AI's open-weights model. 346M parameters, 2048-dim output. Up to 50 docs / min / CPU core. Recommended CPU RAM: 4 GB per model server.",
|
||||
"nemotron3Embed1b": "NVIDIA's multilingual model. 1.1B parameters, 2048-dim output. Up to 5 docs / min / CPU core. Recommended CPU RAM: 8 GB per model server. GPU recommended.",
|
||||
"nomicEmbedTextV1": "Nomic's embedding model specialized for retrieval, similarity, clustering and classification.",
|
||||
"e5BaseV2": "A smaller and faster model than the default. It is around 2x faster than the default model at the cost of lower search quality.",
|
||||
"e5BaseV2": "English embedding model from Microsoft's E5 family. A balance of speed and search quality.",
|
||||
"e5SmallV2": "The smallest and fastest version of the E5 line of models. If you're running {appName} on a resource constrained system, then this may be a good choice.",
|
||||
"multilingualE5Base": "For corpora in other languages besides English, this is the one to choose.",
|
||||
"multilingualE5Small": "For corpora in other languages besides English, as well as being on a resource constrained system, this is the one to choose."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "La recuperación contextual está desactivada porque no tienes modelos configurados. Configura primero un [modelo de lenguaje]({link}).",
|
||||
"title": "Recuperación contextual"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "Este es un modelo heredado. Sigue funcionando, pero no puedes volver a seleccionarlo para un índice nuevo. Para actualizar, haz clic en «Ver todos los modelos» y selecciona un modelo más reciente."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "Onyx Cloud gestiona el modelo de embeddings y su configuración."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "Modelo actual"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "Este modelo de embeddings está obsoleto y no se puede conectar.",
|
||||
"selectTooltip": "Este modelo de embeddings está obsoleto y no se puede seleccionar."
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU recomendada"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "Heredado",
|
||||
"tooltip": "No puedes seleccionar este modelo para un índice nuevo. Seguirá funcionando hasta que cambies de modelo."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "Seleccionar modelo"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "Las velocidades de CPU son estimaciones y varían según el hardware y el tamaño del documento. La RAM recomendada cubre un modelo cargado, no toda la infraestructura de Onyx. Reserva más memoria durante la reindexación.",
|
||||
"addCustomModel": {
|
||||
"label": "Añadir modelo personalizado"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "Conecta un proxy de LiteLLM, una implementación de Azure OpenAI o una puerta de enlace de Bifrost. Tú indicas el nombre del modelo. Para LiteLLM y Azure, también indicas la dimensión.",
|
||||
"selfHostedDescription": "Ejecuta un modelo de embeddings de Hugging Face que no esté en la lista anterior. Tú indicas el nombre, la dimensión y los prefijos del modelo.",
|
||||
"title": "Avanzado: usa tu propio modelo o proxy"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "En la nube"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "Para conservar un conector, cancela aquí, reanúdalo o corrígelo y vuelve a reindexar: así se trasladará. Si no, añádelo de nuevo cuando termine la reindexación."
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "El modelo de embeddings principal de Cohere. El mejor equilibrio entre calidad y coste. Salida de 2048 dimensiones.",
|
||||
"cohereEmbedV5Fast": "Versión de menor coste de Embed 5 de Cohere. Sigue siendo una opción excelente. Salida de 2048 dimensiones.",
|
||||
"cohereEmbedEnglishV3": "Modelo de embeddings en inglés de Cohere. Buen rendimiento en tareas en inglés.",
|
||||
"cohereEmbedEnglishLightV3": "Modelo ligero de embeddings en inglés de Cohere. Más rápido y eficiente para tareas sencillas.",
|
||||
"cohereEmbedV4": "El modelo de embeddings multilingüe más reciente de Cohere, con salida de 1536 dimensiones por defecto para una mejor calidad de recuperación.",
|
||||
"openaiTextEmbedding3Large": "Modelo de embeddings grande de OpenAI. El mejor rendimiento, pero más caro.",
|
||||
"openaiTextEmbedding3Small": "Modelo de embeddings más nuevo y eficiente de OpenAI. Buen equilibrio entre rendimiento y coste.",
|
||||
"cohereEmbedV4": "El modelo de embeddings multilingüe de Cohere, con salida de 1536 dimensiones.",
|
||||
"openaiTextEmbedding3Large": "Modelo de embeddings grande de OpenAI. Una buena opción si ya usas OpenAI. Salida de 3072 dimensiones.",
|
||||
"openaiTextEmbedding3Small": "Modelo de embeddings pequeño de OpenAI. Con diferencia, la opción en la nube más económica. Salida de 1536 dimensiones.",
|
||||
"googleGeminiEmbedding001": "Modelo de embeddings Gemini de Google. Potente y eficiente.",
|
||||
"googleTextEmbedding005": "Modelo de embeddings más pequeño y ligero de Google.",
|
||||
"googleGeminiEmbedding2": "El modelo de embeddings multimodal más reciente de Google (GA). Recuperación de máxima calidad con salida de 3072 dimensiones.",
|
||||
"googleGeminiEmbedding2": "El modelo de embeddings principal de Google. Muy potente, pero caro y más lento. Su salida de 3072 dimensiones genera un índice grande. Una opción sólida para equipos que ya usan Google.",
|
||||
"googleGeminiEmbedding2Preview": "Versión preliminar de Gemini Embedding 2. Sustituida por gemini-embedding-2 en nuevas configuraciones.",
|
||||
"voyageLarge2Instruct": "Modelo de embeddings grande de Voyage. Alto rendimiento con ajuste fino por instrucciones.",
|
||||
"voyage4Large": "El modelo de embeddings más grande de la serie 4 de Voyage. La mejor calidad de recuperación de Voyage, multilingüe.",
|
||||
"voyage4": "Modelo de embeddings de uso general de la serie 4 de Voyage. Alta calidad de recuperación a un coste moderado.",
|
||||
"voyage4Lite": "Modelo ligero de embeddings de la serie 4 de Voyage. El menor coste y los límites de uso más altos.",
|
||||
"voyageLight2Instruct": "Modelo ligero de embeddings de Voyage. Buen equilibrio entre rendimiento y eficiencia.",
|
||||
"graniteEmbedding97mMultilingualR2": "El modelo multilingüe pequeño de IBM. Incluido en {appName}. 97 M de parámetros, 384 dimensiones. Hasta 200 documentos / min / núcleo de CPU. RAM recomendada para CPU: 4 GB por servidor de modelos.",
|
||||
"voyage4Nano": "El modelo de pesos abiertos de Voyage AI. 346 M de parámetros, 2048 dimensiones. Hasta 50 documentos / min / núcleo de CPU. RAM recomendada para CPU: 4 GB por servidor de modelos.",
|
||||
"nemotron3Embed1b": "El modelo multilingüe de NVIDIA. 1100 M de parámetros, 2048 dimensiones. Hasta 5 documentos / min / núcleo de CPU. RAM recomendada para CPU: 8 GB por servidor de modelos. GPU recomendada.",
|
||||
"nomicEmbedTextV1": "Modelo de embeddings de Nomic especializado en recuperación, similitud, agrupación y clasificación.",
|
||||
"e5BaseV2": "Un modelo más pequeño y rápido que el predeterminado. Es unas 2 veces más rápido que el modelo predeterminado a costa de una menor calidad de búsqueda.",
|
||||
"e5BaseV2": "Modelo de embeddings en inglés de la familia E5 de Microsoft. Equilibra velocidad y calidad de búsqueda.",
|
||||
"e5SmallV2": "La versión más pequeña y rápida de la línea de modelos E5. Si ejecutas {appName} en un sistema con recursos limitados, puede ser una buena opción.",
|
||||
"multilingualE5Base": "Para corpus en idiomas distintos del inglés, esta es la opción indicada.",
|
||||
"multilingualE5Small": "Para corpus en idiomas distintos del inglés en un sistema con recursos limitados, esta es la opción indicada."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "La récupération contextuelle est désactivée car aucun modèle n'est configuré. Configurez d'abord un [modèle de langage]({link}).",
|
||||
"title": "Récupération contextuelle"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "Ce modèle est un ancien modèle. Il continue de fonctionner, mais vous ne pouvez plus le sélectionner pour un nouvel index. Pour passer à un modèle plus récent, cliquez sur « Voir tous les modèles » et sélectionnez-en un."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "Le modèle d'embedding et ses paramètres sont gérés par Onyx Cloud."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "Modèle actuel"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "Ce modèle d'embedding est obsolète et ne peut pas être connecté.",
|
||||
"selectTooltip": "Ce modèle d'embedding est obsolète et ne peut pas être sélectionné."
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU recommandé"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "Ancien",
|
||||
"tooltip": "Vous ne pouvez pas sélectionner ce modèle pour un nouvel index. Il continue de fonctionner jusqu'à ce que vous changiez de modèle."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "Sélectionner le modèle"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "Les vitesses CPU sont des estimations qui varient selon le matériel et la taille des documents. La RAM recommandée couvre un modèle chargé, pas toute l’infrastructure Onyx. Prévoyez plus de mémoire pendant la réindexation.",
|
||||
"addCustomModel": {
|
||||
"label": "Ajouter un modèle personnalisé"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "Connectez un proxy LiteLLM, un déploiement Azure OpenAI ou une passerelle Bifrost. Vous indiquez vous-même le nom du modèle. Pour LiteLLM et Azure, vous indiquez aussi la dimension.",
|
||||
"selfHostedDescription": "Exécutez un modèle d'embedding Hugging Face absent de la liste ci-dessus. Vous indiquez vous-même le nom, la dimension et les préfixes du modèle.",
|
||||
"title": "Avancé : utiliser votre propre modèle ou proxy"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "Dans le cloud"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "Pour conserver un connecteur, annulez ici, reprenez-le ou corrigez-le, puis relancez la réindexation : il sera alors repris. Sinon, rajoutez-le une fois la réindexation terminée."
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "Le modèle d'embedding phare de Cohere. Le meilleur équilibre entre qualité et coût. Sortie de 2048 dimensions.",
|
||||
"cohereEmbedV5Fast": "Version moins coûteuse d'Embed 5 de Cohere. Reste une excellente option. Sortie de 2048 dimensions.",
|
||||
"cohereEmbedEnglishV3": "Modèle d'embedding anglais de Cohere. Bonnes performances pour les tâches en anglais.",
|
||||
"cohereEmbedEnglishLightV3": "Modèle d'embedding anglais léger de Cohere. Plus rapide et plus efficace pour les tâches simples.",
|
||||
"cohereEmbedV4": "Dernier modèle d'embedding multilingue de Cohere, avec une sortie par défaut de 1536 dimensions pour une meilleure qualité de recherche.",
|
||||
"openaiTextEmbedding3Large": "Grand modèle d'embedding d'OpenAI. Meilleures performances, mais plus coûteux.",
|
||||
"openaiTextEmbedding3Small": "Modèle d'embedding plus récent et plus efficace d'OpenAI. Bon équilibre entre performances et coût.",
|
||||
"cohereEmbedV4": "Modèle d'embedding multilingue de Cohere, avec une sortie de 1536 dimensions.",
|
||||
"openaiTextEmbedding3Large": "Grand modèle d'embedding d'OpenAI. Un bon choix si vous utilisez déjà OpenAI. Sortie de 3072 dimensions.",
|
||||
"openaiTextEmbedding3Small": "Petit modèle d'embedding d'OpenAI. De loin l'option dans le cloud la plus économique. Sortie de 1536 dimensions.",
|
||||
"googleGeminiEmbedding001": "Modèle d'embedding Gemini de Google. Puissant et efficace.",
|
||||
"googleTextEmbedding005": "Modèle d'embedding plus petit et plus léger de Google.",
|
||||
"googleGeminiEmbedding2": "Dernier modèle d'embedding multimodal de Google (GA). Recherche de la plus haute qualité avec une sortie de 3072 dimensions.",
|
||||
"googleGeminiEmbedding2": "Le modèle d'embedding phare de Google. Très puissant, mais coûteux et plus lent. Sa sortie de 3072 dimensions produit un index volumineux. Un choix solide pour les équipes qui utilisent déjà Google.",
|
||||
"googleGeminiEmbedding2Preview": "Version préliminaire de Gemini Embedding 2. Remplacée par gemini-embedding-2 pour les nouvelles configurations.",
|
||||
"voyageLarge2Instruct": "Grand modèle d'embedding de Voyage. Hautes performances grâce au fine-tuning par instructions.",
|
||||
"voyage4Large": "Le plus grand modèle d'embedding de la série 4 de Voyage. Meilleure qualité de recherche de Voyage, multilingue.",
|
||||
"voyage4": "Modèle d'embedding polyvalent de la série 4 de Voyage. Haute qualité de recherche à coût modéré.",
|
||||
"voyage4Lite": "Modèle d'embedding léger de la série 4 de Voyage. Coût le plus bas et limites de débit les plus élevées.",
|
||||
"voyageLight2Instruct": "Modèle d'embedding léger de Voyage. Bon équilibre entre performances et efficacité.",
|
||||
"graniteEmbedding97mMultilingualR2": "Le petit modèle multilingue d’IBM. Inclus dans {appName}. 97 M de paramètres, sortie de 384 dimensions. Jusqu’à 200 documents / min / cœur CPU. RAM CPU recommandée : 4 Go par serveur de modèles.",
|
||||
"voyage4Nano": "Le modèle à poids ouverts de Voyage AI. 346 M de paramètres, sortie de 2048 dimensions. Jusqu’à 50 documents / min / cœur CPU. RAM CPU recommandée : 4 Go par serveur de modèles.",
|
||||
"nemotron3Embed1b": "Le modèle multilingue de NVIDIA. 1,1 milliard de paramètres, sortie de 2048 dimensions. Jusqu’à 5 documents / min / cœur CPU. RAM CPU recommandée : 8 Go par serveur de modèles. GPU recommandé.",
|
||||
"nomicEmbedTextV1": "Modèle d'embedding de Nomic spécialisé dans la recherche, la similarité, le clustering et la classification.",
|
||||
"e5BaseV2": "Un modèle plus petit et plus rapide que celui par défaut. Environ 2 fois plus rapide que le modèle par défaut, au prix d'une qualité de recherche moindre.",
|
||||
"e5BaseV2": "Modèle d'embedding anglais de la famille E5 de Microsoft. Un équilibre entre vitesse et qualité de recherche.",
|
||||
"e5SmallV2": "La version la plus petite et la plus rapide de la gamme E5. Un bon choix si {appName} tourne sur un système aux ressources limitées.",
|
||||
"multilingualE5Base": "Pour les corpus dans d'autres langues que l'anglais, c'est le modèle à choisir.",
|
||||
"multilingualE5Small": "Pour les corpus dans d'autres langues que l'anglais sur un système aux ressources limitées, c'est le modèle à choisir."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "モデルが設定されていないため、コンテキスト検索は無効です。先に [言語モデル]({link}) を設定してください。",
|
||||
"title": "コンテキスト検索"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "これはレガシーモデルです。引き続き動作しますが、新しいインデックスに再度選択することはできません。アップグレードするには、「すべてのモデルを表示」をクリックして新しいモデルを選択してください。"
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "embedding モデルと関連設定は Onyx Cloud が管理します。"
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "現在のモデル"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "この embedding モデルは非推奨のため接続できません。",
|
||||
"selectTooltip": "この embedding モデルは非推奨のため選択できません。"
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU推奨"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "レガシー",
|
||||
"tooltip": "このモデルは新しいインデックスには選択できません。モデルを変更するまでは引き続き動作します。"
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "モデルを選択"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "CPUの速度は目安で、ハードウェアと文書サイズによって異なります。推奨RAMは読み込んだモデル1つ分であり、Onyx全体の必要量ではありません。再インデックス時は追加のメモリを確保してください。",
|
||||
"addCustomModel": {
|
||||
"label": "カスタムモデルを追加"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "LiteLLM プロキシ、Azure OpenAI デプロイメント、または Bifrost ゲートウェイを接続します。モデル名はご自身で指定します。LiteLLM と Azure では次元も指定します。",
|
||||
"selfHostedDescription": "上の一覧にない Hugging Face の埋め込みモデルを実行します。モデル名、次元、プレフィックスはご自身で指定します。",
|
||||
"title": "詳細設定: 独自のモデルまたはプロキシを使用"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "クラウド型"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "コネクタを残したい場合は、ここでキャンセルし、再開または修正してから再インデックスを実行してください。そうすれば新しいインデックスに引き継がれます。そうしない場合は、再インデックスの完了後に追加し直してください。"
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "Cohere の主力埋め込みモデル。品質とコストのバランスが最も優れています。2048 次元出力。",
|
||||
"cohereEmbedV5Fast": "Cohere の Embed 5 の低コスト版。それでも非常に優れた選択肢です。2048 次元出力。",
|
||||
"cohereEmbedEnglishV3": "Cohere の英語向け埋め込みモデル。英語タスクで良好な性能。",
|
||||
"cohereEmbedEnglishLightV3": "Cohere の軽量な英語向け埋め込みモデル。単純なタスクではより高速で効率的。",
|
||||
"cohereEmbedV4": "Cohere の最新の多言語埋め込みモデル。デフォルトの 1536 次元出力で検索品質を向上。",
|
||||
"openaiTextEmbedding3Large": "OpenAI の大規模埋め込みモデル。最高の性能だが高コスト。",
|
||||
"openaiTextEmbedding3Small": "OpenAI の新しく効率的な埋め込みモデル。性能とコストのバランスが良い。",
|
||||
"cohereEmbedV4": "Cohere の多言語埋め込みモデル。1536 次元出力。",
|
||||
"openaiTextEmbedding3Large": "OpenAI の大規模埋め込みモデル。すでに OpenAI を利用している場合に適しています。3072 次元出力。",
|
||||
"openaiTextEmbedding3Small": "OpenAI の小型埋め込みモデル。クラウド型の選択肢の中で群を抜いて経済的です。1536 次元出力。",
|
||||
"googleGeminiEmbedding001": "Google の Gemini 埋め込みモデル。強力で効率的。",
|
||||
"googleTextEmbedding005": "Google のより小型で軽量な埋め込みモデル。",
|
||||
"googleGeminiEmbedding2": "Google の最新のマルチモーダル埋め込みモデル(GA)。3072 次元出力で最高品質の検索。",
|
||||
"googleGeminiEmbedding2": "Google の主力埋め込みモデル。非常に高性能ですが、コストが高く低速です。3072 次元出力のためインデックスが大きくなります。すでに Google を利用しているチームには堅実な選択肢です。",
|
||||
"googleGeminiEmbedding2Preview": "Gemini Embedding 2 のプレビュー版。新規セットアップでは gemini-embedding-2 に置き換えられました。",
|
||||
"voyageLarge2Instruct": "Voyage の大規模埋め込みモデル。指示によるファインチューニングで高性能。",
|
||||
"voyage4Large": "Voyage 4 シリーズ最大の埋め込みモデル。Voyage で最高の検索品質、多言語対応。",
|
||||
"voyage4": "Voyage 4 シリーズの汎用埋め込みモデル。手頃なコストで高い検索品質。",
|
||||
"voyage4Lite": "Voyage 4 シリーズの軽量埋め込みモデル。最も低コストで、レート制限が最も高い。",
|
||||
"voyageLight2Instruct": "Voyage の軽量な埋め込みモデル。性能と効率のバランスが良い。",
|
||||
"graniteEmbedding97mMultilingualR2": "IBMの小型多言語モデル。{appName}に同梱。9700万パラメータ、384次元出力。CPUコアあたり最大200文書/分。CPU実行時の推奨RAM:モデルサーバーあたり4 GB。",
|
||||
"voyage4Nano": "Voyage AIのオープンウェイトモデル。3億4600万パラメータ、2048次元出力。CPUコアあたり最大50文書/分。CPU実行時の推奨RAM:モデルサーバーあたり4 GB。",
|
||||
"nemotron3Embed1b": "NVIDIAの多言語モデル。11億パラメータ、2048次元出力。CPUコアあたり最大5文書/分。CPU実行時の推奨RAM:モデルサーバーあたり8 GB。GPU推奨。",
|
||||
"nomicEmbedTextV1": "検索、類似度、クラスタリング、分類に特化した Nomic の埋め込みモデル。",
|
||||
"e5BaseV2": "デフォルトより小型で高速なモデル。検索品質は下がるが、デフォルトモデルの約 2 倍高速。",
|
||||
"e5BaseV2": "Microsoft の E5 ファミリーの英語埋め込みモデル。速度と検索品質のバランスが取れています。",
|
||||
"e5SmallV2": "E5 系モデルの中で最小かつ最速のバージョン。リソースが限られた環境で {appName} を実行している場合に適しています。",
|
||||
"multilingualE5Base": "英語以外の言語のコーパスには、これを選択してください。",
|
||||
"multilingualE5Small": "英語以外の言語のコーパスで、かつリソースが限られた環境の場合は、これを選択してください。"
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "설정된 모델이 없어 컨텍스트 검색을 사용할 수 없습니다. 먼저 [언어 모델]({link})을 설정하세요.",
|
||||
"title": "컨텍스트 검색"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "레거시 모델입니다. 계속 작동하지만 새 인덱스에 다시 선택할 수는 없습니다. 업그레이드하려면 “모든 모델 보기”를 클릭하고 최신 모델을 선택하세요."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "Embedding 모델과 설정은 Onyx Cloud에서 관리합니다."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "현재 모델"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "이 embedding 모델은 지원이 중단되어 연결할 수 없습니다.",
|
||||
"selectTooltip": "이 embedding 모델은 지원이 중단되어 선택할 수 없습니다."
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU 권장"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "레거시",
|
||||
"tooltip": "이 모델은 새 인덱스에 선택할 수 없습니다. 모델을 변경하기 전까지는 계속 작동합니다."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "모델 선택"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "CPU 속도는 추정치이며 하드웨어와 문서 크기에 따라 달라집니다. 권장 RAM은 로드된 모델 하나에 대한 값이며 전체 Onyx 구성의 요구량이 아닙니다. 재인덱싱 시 메모리를 추가로 확보하세요.",
|
||||
"addCustomModel": {
|
||||
"label": "사용자 지정 모델 추가"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "LiteLLM 프록시, Azure OpenAI 배포 또는 Bifrost 게이트웨이를 연결합니다. 모델 이름은 직접 입력합니다. LiteLLM과 Azure는 차원도 입력합니다.",
|
||||
"selfHostedDescription": "위 목록에 없는 Hugging Face 임베딩 모델을 실행합니다. 모델 이름, 차원, 접두사는 직접 입력합니다.",
|
||||
"title": "고급: 자체 모델 또는 프록시 사용"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "클라우드 기반"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "커넥터를 유지하려면 여기서 취소하고 재개하거나 문제를 해결한 뒤 다시 재인덱싱하세요. 그러면 새 인덱스로 이전됩니다. 그렇지 않으면 재인덱싱이 끝난 뒤 다시 추가하세요."
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "Cohere의 대표 임베딩 모델입니다. 품질과 비용의 균형이 가장 좋습니다. 2048차원 출력.",
|
||||
"cohereEmbedV5Fast": "Cohere Embed 5의 저비용 버전입니다. 그래도 매우 훌륭한 선택입니다. 2048차원 출력.",
|
||||
"cohereEmbedEnglishV3": "Cohere의 영어 임베딩 모델입니다. 영어 작업에 좋은 성능을 보입니다.",
|
||||
"cohereEmbedEnglishLightV3": "Cohere의 경량 영어 임베딩 모델입니다. 단순한 작업에 더 빠르고 효율적입니다.",
|
||||
"cohereEmbedV4": "Cohere의 최신 다국어 임베딩 모델로, 기본 1536차원 출력으로 더 높은 검색 품질을 제공합니다.",
|
||||
"openaiTextEmbedding3Large": "OpenAI의 대형 임베딩 모델입니다. 성능은 가장 좋지만 비용이 더 높습니다.",
|
||||
"openaiTextEmbedding3Small": "OpenAI의 더 새롭고 효율적인 임베딩 모델입니다. 성능과 비용의 균형이 좋습니다.",
|
||||
"cohereEmbedV4": "Cohere의 다국어 임베딩 모델로, 1536차원 출력을 제공합니다.",
|
||||
"openaiTextEmbedding3Large": "OpenAI의 대형 임베딩 모델입니다. 이미 OpenAI를 사용 중이라면 좋은 선택입니다. 3072차원 출력.",
|
||||
"openaiTextEmbedding3Small": "OpenAI의 소형 임베딩 모델입니다. 클라우드 기반 옵션 중 단연 가장 경제적입니다. 1536차원 출력.",
|
||||
"googleGeminiEmbedding001": "Google의 Gemini 임베딩 모델입니다. 강력하고 효율적입니다.",
|
||||
"googleTextEmbedding005": "Google의 더 작고 가벼운 임베딩 모델입니다.",
|
||||
"googleGeminiEmbedding2": "Google의 최신 멀티모달 임베딩 모델(GA)입니다. 3072차원 출력으로 최고 품질의 검색을 제공합니다.",
|
||||
"googleGeminiEmbedding2": "Google의 대표 임베딩 모델입니다. 매우 강력하지만 비용이 높고 더 느립니다. 3072차원 출력으로 인덱스가 커집니다. 이미 Google을 사용하는 팀에게 탄탄한 선택입니다.",
|
||||
"googleGeminiEmbedding2Preview": "Gemini Embedding 2의 프리뷰 버전입니다. 새 설정에서는 gemini-embedding-2로 대체되었습니다.",
|
||||
"voyageLarge2Instruct": "Voyage의 대형 임베딩 모델입니다. 지시 미세 조정으로 높은 성능을 제공합니다.",
|
||||
"voyage4Large": "Voyage 4 시리즈의 가장 큰 임베딩 모델입니다. Voyage 최고의 검색 품질과 다국어를 지원합니다.",
|
||||
"voyage4": "Voyage 4 시리즈의 범용 임베딩 모델입니다. 적당한 비용으로 높은 검색 품질을 제공합니다.",
|
||||
"voyage4Lite": "Voyage 4 시리즈의 경량 임베딩 모델입니다. 비용이 가장 낮고 속도 제한이 가장 높습니다.",
|
||||
"voyageLight2Instruct": "Voyage의 경량 임베딩 모델입니다. 성능과 효율의 균형이 좋습니다.",
|
||||
"graniteEmbedding97mMultilingualR2": "IBM의 소형 다국어 모델입니다. {appName}에 포함됩니다. 9700만 개 파라미터, 384차원 출력. CPU 코어당 분당 최대 200개 문서. CPU 권장 RAM: 모델 서버당 4 GB.",
|
||||
"voyage4Nano": "Voyage AI의 오픈 웨이트 모델입니다. 3억 4600만 개 파라미터, 2048차원 출력. CPU 코어당 분당 최대 50개 문서. CPU 권장 RAM: 모델 서버당 4 GB.",
|
||||
"nemotron3Embed1b": "NVIDIA의 다국어 모델입니다. 11억 개 파라미터, 2048차원 출력. CPU 코어당 분당 최대 5개 문서. CPU 권장 RAM: 모델 서버당 8 GB. GPU를 권장합니다.",
|
||||
"nomicEmbedTextV1": "검색, 유사도, 클러스터링, 분류에 특화된 Nomic의 임베딩 모델입니다.",
|
||||
"e5BaseV2": "기본 모델보다 더 작고 빠른 모델입니다. 검색 품질은 낮아지지만 기본 모델보다 약 2배 빠릅니다.",
|
||||
"e5BaseV2": "Microsoft E5 계열의 영어 임베딩 모델입니다. 속도와 검색 품질의 균형을 갖추었습니다.",
|
||||
"e5SmallV2": "E5 모델 계열 중 가장 작고 빠른 버전입니다. 리소스가 제한된 시스템에서 {appName}를 실행한다면 좋은 선택입니다.",
|
||||
"multilingualE5Base": "영어 이외의 언어로 된 코퍼스에는 이 모델을 선택하세요.",
|
||||
"multilingualE5Small": "영어 이외의 언어로 된 코퍼스이면서 리소스가 제한된 시스템이라면 이 모델을 선택하세요."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "A recuperação contextual está desativada porque você não tem modelos configurados. Configure primeiro um [modelo de linguagem]({link}).",
|
||||
"title": "Recuperação contextual"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "Este é um modelo legado. Ele continua funcionando, mas você não pode selecioná-lo de novo para um novo índice. Para atualizar, clique em “Ver todos os modelos” e selecione um modelo mais recente."
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "O modelo de embedding e as configurações são gerenciados pelo Onyx Cloud."
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "Modelo atual"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "Este modelo de embedding está descontinuado e não é possível se conectar a ele.",
|
||||
"selectTooltip": "Este modelo de embedding está descontinuado e não pode ser selecionado."
|
||||
"gpuRecommended": {
|
||||
"tag": "GPU recomendada"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "Legado",
|
||||
"tooltip": "Você não pode selecionar este modelo para um novo índice. Ele continua funcionando até você trocar de modelo."
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "Selecionar modelo"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "As velocidades de CPU são estimativas e variam conforme o hardware e o tamanho dos documentos. A RAM recomendada cobre um modelo carregado, não toda a infraestrutura do Onyx. Reserve mais memória durante a reindexação.",
|
||||
"addCustomModel": {
|
||||
"label": "Adicionar modelo personalizado"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "Conecte um proxy LiteLLM, uma implantação do Azure OpenAI ou um gateway Bifrost. Você informa o nome do modelo. Para LiteLLM e Azure, você também informa a dimensão.",
|
||||
"selfHostedDescription": "Execute um modelo de embeddings do Hugging Face que não está na lista acima. Você informa o nome, a dimensão e os prefixos do modelo.",
|
||||
"title": "Avançado: use seu próprio modelo ou proxy"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "Na nuvem"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "Para manter um conector, cancele aqui, retome-o ou corrija-o e reindexe novamente — assim ele será levado adiante. Caso contrário, adicione-o de volta quando a reindexação terminar."
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "O principal modelo de embeddings da Cohere. O melhor equilíbrio entre qualidade e custo. Saída de 2048 dimensões.",
|
||||
"cohereEmbedV5Fast": "Versão de menor custo do Embed 5 da Cohere. Ainda assim, uma excelente opção. Saída de 2048 dimensões.",
|
||||
"cohereEmbedEnglishV3": "Modelo de embeddings em inglês da Cohere. Bom desempenho em tarefas em inglês.",
|
||||
"cohereEmbedEnglishLightV3": "Modelo leve de embeddings em inglês da Cohere. Mais rápido e eficiente para tarefas simples.",
|
||||
"cohereEmbedV4": "O modelo de embeddings multilíngue mais recente da Cohere, com saída padrão de 1536 dimensões para melhor qualidade de recuperação.",
|
||||
"openaiTextEmbedding3Large": "Modelo de embeddings grande da OpenAI. Melhor desempenho, porém mais caro.",
|
||||
"openaiTextEmbedding3Small": "Modelo de embeddings mais novo e eficiente da OpenAI. Bom equilíbrio entre desempenho e custo.",
|
||||
"cohereEmbedV4": "O modelo de embeddings multilíngue da Cohere, com saída de 1536 dimensões.",
|
||||
"openaiTextEmbedding3Large": "Modelo de embeddings grande da OpenAI. Uma boa escolha se você já usa a OpenAI. Saída de 3072 dimensões.",
|
||||
"openaiTextEmbedding3Small": "Modelo de embeddings pequeno da OpenAI. De longe a opção na nuvem mais econômica. Saída de 1536 dimensões.",
|
||||
"googleGeminiEmbedding001": "Modelo de embeddings Gemini do Google. Poderoso e eficiente.",
|
||||
"googleTextEmbedding005": "Modelo de embeddings menor e mais leve do Google.",
|
||||
"googleGeminiEmbedding2": "O modelo de embeddings multimodal mais recente do Google (GA). Recuperação da mais alta qualidade com saída de 3072 dimensões.",
|
||||
"googleGeminiEmbedding2": "O principal modelo de embeddings do Google. Muito poderoso, mas caro e mais lento. Sua saída de 3072 dimensões gera um índice grande. Uma escolha sólida para equipes que já usam o Google.",
|
||||
"googleGeminiEmbedding2Preview": "Versão prévia do Gemini Embedding 2. Substituída pelo gemini-embedding-2 em novas configurações.",
|
||||
"voyageLarge2Instruct": "Modelo de embeddings grande da Voyage. Alto desempenho com ajuste fino por instruções.",
|
||||
"voyage4Large": "O maior modelo de embeddings da série 4 da Voyage. A melhor qualidade de recuperação da Voyage, multilíngue.",
|
||||
"voyage4": "Modelo de embeddings de uso geral da série 4 da Voyage. Alta qualidade de recuperação a um custo moderado.",
|
||||
"voyage4Lite": "Modelo leve de embeddings da série 4 da Voyage. Menor custo e maiores limites de taxa.",
|
||||
"voyageLight2Instruct": "Modelo leve de embeddings da Voyage. Bom equilíbrio entre desempenho e eficiência.",
|
||||
"graniteEmbedding97mMultilingualR2": "O pequeno modelo multilíngue da IBM. Incluído no {appName}. 97 milhões de parâmetros, saída de 384 dimensões. Até 200 documentos / min / núcleo de CPU. RAM recomendada para CPU: 4 GB por servidor de modelos.",
|
||||
"voyage4Nano": "O modelo de pesos abertos da Voyage AI. 346 milhões de parâmetros, saída de 2048 dimensões. Até 50 documentos / min / núcleo de CPU. RAM recomendada para CPU: 4 GB por servidor de modelos.",
|
||||
"nemotron3Embed1b": "O modelo multilíngue da NVIDIA. 1,1 bilhão de parâmetros, saída de 2048 dimensões. Até 5 documentos / min / núcleo de CPU. RAM recomendada para CPU: 8 GB por servidor de modelos. GPU recomendada.",
|
||||
"nomicEmbedTextV1": "Modelo de embeddings da Nomic especializado em recuperação, similaridade, agrupamento e classificação.",
|
||||
"e5BaseV2": "Um modelo menor e mais rápido que o padrão. É cerca de 2x mais rápido que o modelo padrão, com menor qualidade de busca.",
|
||||
"e5BaseV2": "Modelo de embeddings em inglês da família E5 da Microsoft. Equilibra velocidade e qualidade de busca.",
|
||||
"e5SmallV2": "A versão menor e mais rápida da linha de modelos E5. Se você executa o {appName} em um sistema com recursos limitados, pode ser uma boa escolha.",
|
||||
"multilingualE5Base": "Para corpora em outros idiomas além do inglês, esta é a escolha certa.",
|
||||
"multilingualE5Small": "Para corpora em outros idiomas além do inglês em um sistema com recursos limitados, esta é a escolha certa."
|
||||
|
||||
@@ -6863,6 +6863,9 @@
|
||||
"noModelsTooltip": "上下文检索已禁用,因为您尚未配置任何模型。请先设置[语言模型]({link})。",
|
||||
"title": "上下文检索"
|
||||
},
|
||||
"currentModel": {
|
||||
"legacyHint": "这是旧版模型。它会继续工作,但不能再次选择用于新索引。如需升级,请点击“查看所有模型”并选择较新的模型。"
|
||||
},
|
||||
"embeddingModel": {
|
||||
"cloudManaged": {
|
||||
"title": "Embedding 模型和相关设置由 Onyx Cloud 管理。"
|
||||
@@ -7001,9 +7004,12 @@
|
||||
"currentButton": {
|
||||
"label": "当前模型"
|
||||
},
|
||||
"deprecated": {
|
||||
"connectTooltip": "此 embedding 模型已弃用,无法连接。",
|
||||
"selectTooltip": "此 embedding 模型已弃用,无法选择。"
|
||||
"gpuRecommended": {
|
||||
"tag": "建议使用 GPU"
|
||||
},
|
||||
"legacy": {
|
||||
"tag": "旧版",
|
||||
"tooltip": "此模型不能用于新索引。在您更换模型之前,它会继续工作。"
|
||||
},
|
||||
"selectButton": {
|
||||
"label": "选择模型"
|
||||
@@ -7013,9 +7019,15 @@
|
||||
}
|
||||
},
|
||||
"modelPicker": {
|
||||
"cpuEstimateHint": "CPU 速度为估计值,会因硬件和文档大小而异。RAM 建议适用于一个已加载模型,并非整个 Onyx 系统的内存要求。重新索引时请预留更多内存。",
|
||||
"addCustomModel": {
|
||||
"label": "添加自定义模型"
|
||||
},
|
||||
"bringYourOwn": {
|
||||
"cloudDescription": "连接 LiteLLM 代理、Azure OpenAI 部署或 Bifrost 网关。模型名称由您自行填写。对于 LiteLLM 和 Azure,还需填写维度。",
|
||||
"selfHostedDescription": "运行上方列表中没有的 Hugging Face 嵌入模型。模型名称、维度和前缀由您自行填写。",
|
||||
"title": "高级:使用自己的模型或代理"
|
||||
},
|
||||
"cloudTab": {
|
||||
"label": "云端"
|
||||
},
|
||||
@@ -7214,22 +7226,27 @@
|
||||
"restoreHint": "如需保留某个连接器,请在此取消,先恢复或修复它,然后重新索引,它就会被迁移过去。否则请在重新索引完成后重新添加。"
|
||||
},
|
||||
"modelDescriptions": {
|
||||
"cohereEmbedV5Pro": "Cohere 的旗舰嵌入模型。质量与成本的最佳平衡。2048 维输出。",
|
||||
"cohereEmbedV5Fast": "Cohere Embed 5 的低成本版本。依然是非常出色的选择。2048 维输出。",
|
||||
"cohereEmbedEnglishV3": "Cohere 的英语嵌入模型。在英语任务上表现良好。",
|
||||
"cohereEmbedEnglishLightV3": "Cohere 的轻量级英语嵌入模型。处理简单任务更快、更高效。",
|
||||
"cohereEmbedV4": "Cohere 最新的多语言嵌入模型,默认 1536 维输出,检索质量更高。",
|
||||
"openaiTextEmbedding3Large": "OpenAI 的大型嵌入模型。性能最佳,但成本更高。",
|
||||
"openaiTextEmbedding3Small": "OpenAI 更新、更高效的嵌入模型。性能与成本平衡良好。",
|
||||
"cohereEmbedV4": "Cohere 的多语言嵌入模型,1536 维输出。",
|
||||
"openaiTextEmbedding3Large": "OpenAI 的大型嵌入模型。适合已在使用 OpenAI 的团队。3072 维输出。",
|
||||
"openaiTextEmbedding3Small": "OpenAI 的小型嵌入模型。在云端选项中最经济,优势明显。1536 维输出。",
|
||||
"googleGeminiEmbedding001": "Google 的 Gemini 嵌入模型。强大且高效。",
|
||||
"googleTextEmbedding005": "Google 更小、更轻量的嵌入模型。",
|
||||
"googleGeminiEmbedding2": "Google 最新的多模态嵌入模型(GA)。3072 维输出,检索质量最高。",
|
||||
"googleGeminiEmbedding2": "Google 的旗舰嵌入模型。功能非常强大,但成本高、速度较慢。3072 维输出会生成较大的索引。对已在使用 Google 的团队来说是稳妥的选择。",
|
||||
"googleGeminiEmbedding2Preview": "Gemini Embedding 2 的预览版。新部署已由 gemini-embedding-2 取代。",
|
||||
"voyageLarge2Instruct": "Voyage 的大型嵌入模型。经过指令微调,性能出色。",
|
||||
"voyage4Large": "Voyage 4 系列中最大的嵌入模型。Voyage 最佳检索质量,支持多语言。",
|
||||
"voyage4": "Voyage 4 系列通用嵌入模型。以适中成本提供高检索质量。",
|
||||
"voyage4Lite": "Voyage 4 系列轻量级嵌入模型。成本最低,速率限制最高。",
|
||||
"voyageLight2Instruct": "Voyage 的轻量级嵌入模型。性能与效率平衡良好。",
|
||||
"graniteEmbedding97mMultilingualR2": "IBM 的小型多语言模型。随 {appName} 提供。9700 万参数,384 维输出。每个 CPU 核心每分钟最多处理 200 篇文档。CPU 推理建议 RAM:每个模型服务器 4 GB。",
|
||||
"voyage4Nano": "Voyage AI 的开放权重模型。3.46 亿参数,2048 维输出。每个 CPU 核心每分钟最多处理 50 篇文档。CPU 推理建议 RAM:每个模型服务器 4 GB。",
|
||||
"nemotron3Embed1b": "NVIDIA 的多语言模型。11 亿参数,2048 维输出。每个 CPU 核心每分钟最多处理 5 篇文档。CPU 推理建议 RAM:每个模型服务器 8 GB。建议使用 GPU。",
|
||||
"nomicEmbedTextV1": "Nomic 的嵌入模型,专注于检索、相似度、聚类和分类。",
|
||||
"e5BaseV2": "比默认模型更小、更快的模型。速度约为默认模型的 2 倍,但搜索质量较低。",
|
||||
"e5BaseV2": "Microsoft E5 系列的英文嵌入模型。在速度与搜索质量之间取得平衡。",
|
||||
"e5SmallV2": "E5 系列模型中最小、最快的版本。如果您在资源受限的系统上运行 {appName},这是一个不错的选择。",
|
||||
"multilingualE5Base": "如果语料库包含英语以外的语言,请选择此模型。",
|
||||
"multilingualE5Small": "如果语料库包含英语以外的语言,且系统资源受限,请选择此模型。"
|
||||
|
||||
@@ -1,12 +1,14 @@
|
||||
import { SvgHardDrive } from "@opal/icons";
|
||||
import { SvgHardDrive, SvgServer } from "@opal/icons";
|
||||
import {
|
||||
SvgAzure,
|
||||
SvgBifrost,
|
||||
SvgCohere,
|
||||
SvgGoogle,
|
||||
SvgIBM,
|
||||
SvgLiteLLM,
|
||||
SvgMicrosoft,
|
||||
SvgNomic,
|
||||
SvgNVIDIA,
|
||||
SvgOpenAI,
|
||||
SvgVoyage,
|
||||
} from "@opal/logos";
|
||||
@@ -18,6 +20,11 @@ import { DOCS_ADMINS_PATH } from "@/lib/constants";
|
||||
|
||||
// ═══════════════════════════════════════════════════════════════════════════
|
||||
// Embedding
|
||||
//
|
||||
// Mirrors backend/shared_configs/embedding_models.py, and
|
||||
// test_web_embedding_model_registry_parity.py pins the two together. Never
|
||||
// remove or rename an entry: mark it `legacy`. List selectable models first in
|
||||
// each group.
|
||||
// ═══════════════════════════════════════════════════════════════════════════
|
||||
|
||||
export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
@@ -29,6 +36,22 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
apiLink: "https://dashboard.cohere.ai/api-keys",
|
||||
costslink: "https://cohere.com/pricing",
|
||||
embeddingModels: [
|
||||
{
|
||||
modelName: "embed-v5.0-pro",
|
||||
modelDim: 2048,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.cohereEmbedV5Pro",
|
||||
},
|
||||
{
|
||||
modelName: "embed-v5.0-fast",
|
||||
modelDim: 2048,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.cohereEmbedV5Fast",
|
||||
},
|
||||
{
|
||||
modelName: "embed-english-v3.0",
|
||||
modelDim: 1024,
|
||||
@@ -36,6 +59,7 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.cohereEmbedEnglishV3",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "embed-english-light-v3.0",
|
||||
@@ -44,6 +68,7 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.cohereEmbedEnglishLightV3",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "embed-v4.0",
|
||||
@@ -52,6 +77,7 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.cohereEmbedV4",
|
||||
legacy: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
@@ -89,22 +115,6 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
apiLink: "https://console.cloud.google.com/apis/credentials",
|
||||
costslink: "https://cloud.google.com/vertex-ai/pricing",
|
||||
embeddingModels: [
|
||||
{
|
||||
modelName: "gemini-embedding-001",
|
||||
modelDim: 3072,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.googleGeminiEmbedding001",
|
||||
},
|
||||
{
|
||||
modelName: "text-embedding-005",
|
||||
modelDim: 768,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.googleTextEmbedding005",
|
||||
},
|
||||
{
|
||||
modelName: "gemini-embedding-2",
|
||||
modelDim: 3072,
|
||||
@@ -113,6 +123,24 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.googleGeminiEmbedding2",
|
||||
},
|
||||
{
|
||||
modelName: "gemini-embedding-001",
|
||||
modelDim: 3072,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.googleGeminiEmbedding001",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "text-embedding-005",
|
||||
modelDim: 768,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.googleTextEmbedding005",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "gemini-embedding-2-preview",
|
||||
modelDim: 3072,
|
||||
@@ -120,6 +148,23 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.googleGeminiEmbedding2Preview",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "text-embedding-004",
|
||||
modelDim: 768,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "textembedding-gecko@003",
|
||||
modelDim: 768,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
legacy: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
@@ -162,7 +207,7 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.voyageLarge2Instruct",
|
||||
deprecated: true,
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "voyage-light-2-instruct",
|
||||
@@ -171,10 +216,12 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.voyageLight2Instruct",
|
||||
deprecated: true,
|
||||
legacy: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
// Bring-your-own providers: no registry models. The admin enters the model
|
||||
// spec in the connect modal. See `isBringYourOwnProvider`.
|
||||
{
|
||||
providerName: EmbeddingProviderName.LITELLM,
|
||||
displayName: "LiteLLM",
|
||||
@@ -203,6 +250,56 @@ export const CLOUD_BASED_PROVIDERS: EmbeddingProvider[] = [
|
||||
];
|
||||
|
||||
export const SELF_HOSTED_PROVIDERS: EmbeddingProvider[] = [
|
||||
{
|
||||
providerName: EmbeddingProviderName.IBM,
|
||||
displayName: "IBM",
|
||||
icon: SvgIBM,
|
||||
docsLink: "https://huggingface.co/ibm-granite",
|
||||
embeddingModels: [
|
||||
{
|
||||
modelName: "ibm-granite/granite-embedding-97m-multilingual-r2",
|
||||
modelDim: 384,
|
||||
normalize: true,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
descriptionKey: "modelDescriptions.graniteEmbedding97mMultilingualR2",
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
providerName: EmbeddingProviderName.VOYAGE_SELF_HOSTED,
|
||||
displayName: "Voyage AI",
|
||||
icon: SvgVoyage,
|
||||
docsLink: "https://huggingface.co/voyageai",
|
||||
embeddingModels: [
|
||||
{
|
||||
modelName: "voyageai/voyage-4-nano",
|
||||
modelDim: 2048,
|
||||
normalize: true,
|
||||
queryPrefix:
|
||||
"Represent the query for retrieving supporting documents: ",
|
||||
passagePrefix: "Represent the document for retrieval: ",
|
||||
descriptionKey: "modelDescriptions.voyage4Nano",
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
providerName: EmbeddingProviderName.NVIDIA,
|
||||
displayName: "NVIDIA",
|
||||
icon: SvgNVIDIA,
|
||||
docsLink: "https://huggingface.co/nvidia",
|
||||
embeddingModels: [
|
||||
{
|
||||
modelName: "nvidia/Nemotron-3-Embed-1B-BF16",
|
||||
modelDim: 2048,
|
||||
normalize: true,
|
||||
queryPrefix: "query: ",
|
||||
passagePrefix: "passage: ",
|
||||
descriptionKey: "modelDescriptions.nemotron3Embed1b",
|
||||
gpuRecommended: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
providerName: EmbeddingProviderName.NOMIC,
|
||||
displayName: "Nomic",
|
||||
@@ -216,6 +313,7 @@ export const SELF_HOSTED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "search_query: ",
|
||||
passagePrefix: "search_document: ",
|
||||
descriptionKey: "modelDescriptions.nomicEmbedTextV1",
|
||||
legacy: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
@@ -232,6 +330,7 @@ export const SELF_HOSTED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "query: ",
|
||||
passagePrefix: "passage: ",
|
||||
descriptionKey: "modelDescriptions.e5BaseV2",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "intfloat/e5-small-v2",
|
||||
@@ -240,6 +339,7 @@ export const SELF_HOSTED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "query: ",
|
||||
passagePrefix: "passage: ",
|
||||
descriptionKey: "modelDescriptions.e5SmallV2",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "intfloat/multilingual-e5-base",
|
||||
@@ -248,6 +348,7 @@ export const SELF_HOSTED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "query: ",
|
||||
passagePrefix: "passage: ",
|
||||
descriptionKey: "modelDescriptions.multilingualE5Base",
|
||||
legacy: true,
|
||||
},
|
||||
{
|
||||
modelName: "intfloat/multilingual-e5-small",
|
||||
@@ -256,6 +357,23 @@ export const SELF_HOSTED_PROVIDERS: EmbeddingProvider[] = [
|
||||
queryPrefix: "query: ",
|
||||
passagePrefix: "passage: ",
|
||||
descriptionKey: "modelDescriptions.multilingualE5Small",
|
||||
legacy: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
providerName: EmbeddingProviderName.GTE,
|
||||
displayName: "GTE",
|
||||
icon: SvgServer,
|
||||
docsLink: "https://huggingface.co/thenlper",
|
||||
embeddingModels: [
|
||||
{
|
||||
modelName: "thenlper/gte-small",
|
||||
modelDim: 384,
|
||||
normalize: false,
|
||||
queryPrefix: "",
|
||||
passagePrefix: "",
|
||||
legacy: true,
|
||||
},
|
||||
],
|
||||
},
|
||||
|
||||
@@ -0,0 +1,151 @@
|
||||
import {
|
||||
CLOUD_BASED_PROVIDERS,
|
||||
SELF_HOSTED_PROVIDERS,
|
||||
} from "@/lib/searchSettings/constants";
|
||||
import {
|
||||
defaultTestModelName,
|
||||
findProviderModel,
|
||||
findRegistryModel,
|
||||
isBringYourOwnProvider,
|
||||
isCloudBased,
|
||||
visibleEmbeddingProviders,
|
||||
} from "@/lib/searchSettings";
|
||||
import {
|
||||
EmbeddingProvider,
|
||||
EmbeddingProviderName,
|
||||
} from "@/lib/searchSettings/types";
|
||||
|
||||
const ALL_PROVIDERS = [...CLOUD_BASED_PROVIDERS, ...SELF_HOSTED_PROVIDERS];
|
||||
|
||||
function modelNames(providers: EmbeddingProvider[]): string[] {
|
||||
return providers.flatMap((p) => p.embeddingModels.map((m) => m.modelName));
|
||||
}
|
||||
|
||||
function groupModels(
|
||||
providers: EmbeddingProvider[],
|
||||
providerName: EmbeddingProviderName
|
||||
): string[] | undefined {
|
||||
return providers
|
||||
.find((p) => p.providerName === providerName)
|
||||
?.embeddingModels.map((m) => m.modelName);
|
||||
}
|
||||
|
||||
// backend/tests/unit/shared_configs/test_web_embedding_model_registry_parity.py
|
||||
// pins the model specs and legacy flags. These tests cover what it cannot.
|
||||
describe("the embedding model registry", () => {
|
||||
it("uses each model name once, so a name lookup is unambiguous", () => {
|
||||
const names = modelNames(ALL_PROVIDERS);
|
||||
|
||||
expect(new Set(names).size).toBe(names.length);
|
||||
});
|
||||
|
||||
it("never routes a self-hosted group to a cloud API", () => {
|
||||
for (const provider of SELF_HOSTED_PROVIDERS) {
|
||||
expect(isCloudBased(provider.providerName)).toBe(false);
|
||||
}
|
||||
});
|
||||
|
||||
it("has a selectable model to test the credentials of each cloud provider", () => {
|
||||
for (const provider of CLOUD_BASED_PROVIDERS) {
|
||||
if (isBringYourOwnProvider(provider.providerName)) continue;
|
||||
const modelName = defaultTestModelName(provider.providerName);
|
||||
|
||||
expect(
|
||||
findProviderModel(provider.providerName, modelName)?.legacy
|
||||
).toBeFalsy();
|
||||
}
|
||||
});
|
||||
});
|
||||
|
||||
describe("visibleEmbeddingProviders", () => {
|
||||
const GRANITE = {
|
||||
providerName: EmbeddingProviderName.IBM,
|
||||
modelName: "ibm-granite/granite-embedding-97m-multilingual-r2",
|
||||
};
|
||||
// No cloud group of the registry has only legacy models, so build one.
|
||||
const LEGACY_ONLY_VOYAGE = CLOUD_BASED_PROVIDERS.map((p) =>
|
||||
p.providerName === EmbeddingProviderName.VOYAGE
|
||||
? { ...p, embeddingModels: p.embeddingModels.filter((m) => m.legacy) }
|
||||
: p
|
||||
);
|
||||
|
||||
it("hides legacy models that are not current and drops the groups it empties", () => {
|
||||
const visible = visibleEmbeddingProviders(ALL_PROVIDERS, null);
|
||||
|
||||
for (const name of modelNames(visible)) {
|
||||
expect(findRegistryModel(name)?.legacy).toBeFalsy();
|
||||
}
|
||||
expect(
|
||||
visibleEmbeddingProviders(SELF_HOSTED_PROVIDERS, null).map(
|
||||
(p) => p.providerName
|
||||
)
|
||||
).toEqual([
|
||||
EmbeddingProviderName.IBM,
|
||||
EmbeddingProviderName.VOYAGE_SELF_HOSTED,
|
||||
EmbeddingProviderName.NVIDIA,
|
||||
]);
|
||||
});
|
||||
|
||||
it("keeps the bring-your-own groups, which have no registry models", () => {
|
||||
expect(
|
||||
visibleEmbeddingProviders(LEGACY_ONLY_VOYAGE, GRANITE).map(
|
||||
(p) => p.providerName
|
||||
)
|
||||
).toEqual([
|
||||
EmbeddingProviderName.COHERE,
|
||||
EmbeddingProviderName.OPENAI,
|
||||
EmbeddingProviderName.GOOGLE,
|
||||
EmbeddingProviderName.LITELLM,
|
||||
EmbeddingProviderName.AZURE,
|
||||
EmbeddingProviderName.BIFROST,
|
||||
]);
|
||||
});
|
||||
|
||||
it("shows a current legacy model in its own group, after the selectable ones", () => {
|
||||
const selfHosted = visibleEmbeddingProviders(SELF_HOSTED_PROVIDERS, {
|
||||
providerName: EmbeddingProviderName.MICROSOFT,
|
||||
modelName: "intfloat/e5-base-v2",
|
||||
});
|
||||
|
||||
expect(groupModels(selfHosted, EmbeddingProviderName.MICROSOFT)).toEqual([
|
||||
"intfloat/e5-base-v2",
|
||||
]);
|
||||
expect(
|
||||
groupModels(selfHosted, EmbeddingProviderName.NOMIC)
|
||||
).toBeUndefined();
|
||||
|
||||
const cloud = visibleEmbeddingProviders(CLOUD_BASED_PROVIDERS, {
|
||||
providerName: EmbeddingProviderName.COHERE,
|
||||
modelName: "embed-english-v3.0",
|
||||
});
|
||||
|
||||
expect(groupModels(cloud, EmbeddingProviderName.COHERE)).toEqual([
|
||||
"embed-v5.0-pro",
|
||||
"embed-v5.0-fast",
|
||||
"embed-english-v3.0",
|
||||
]);
|
||||
});
|
||||
|
||||
it("keeps an emptied group with saved credentials, so they can be disconnected", () => {
|
||||
const visible = visibleEmbeddingProviders(
|
||||
LEGACY_ONLY_VOYAGE,
|
||||
GRANITE,
|
||||
new Set([EmbeddingProviderName.VOYAGE])
|
||||
);
|
||||
|
||||
expect(groupModels(visible, EmbeddingProviderName.VOYAGE)).toEqual([]);
|
||||
});
|
||||
|
||||
it("matches the current model on provider and name", () => {
|
||||
// An Azure deployment labelled like a legacy Cohere model.
|
||||
const visible = visibleEmbeddingProviders(CLOUD_BASED_PROVIDERS, {
|
||||
providerName: EmbeddingProviderName.AZURE,
|
||||
modelName: "embed-english-v3.0",
|
||||
});
|
||||
|
||||
expect(modelNames(visible)).not.toContain("embed-english-v3.0");
|
||||
expect(
|
||||
findProviderModel(EmbeddingProviderName.AZURE, "text-embedding-3-large")
|
||||
).toBeNull();
|
||||
});
|
||||
});
|
||||
@@ -5,6 +5,7 @@ import {
|
||||
} from "@/lib/searchSettings/constants";
|
||||
import {
|
||||
EmbeddingModel,
|
||||
EmbeddingModelRef,
|
||||
EmbeddingProvider,
|
||||
EmbeddingProviderName,
|
||||
IndexSettingsTranslator,
|
||||
@@ -35,12 +36,27 @@ export function findProvider(
|
||||
* provider — i.e. credentials are managed via API keys, the row should
|
||||
* have an editable creds modal, and the backend should route through a
|
||||
* cloud SDK rather than the local model server. Returns `false` for
|
||||
* self-hosted buckets (`NOMIC`, `MICROSOFT`) and `CUSTOM`.
|
||||
* self-hosted buckets (e.g. `IBM`, `VOYAGE_SELF_HOSTED`, `NOMIC`) and `CUSTOM`.
|
||||
*/
|
||||
export function isCloudBased(providerName: EmbeddingProviderName): boolean {
|
||||
return CLOUD_BASED_PROVIDERS.some((p) => p.providerName === providerName);
|
||||
}
|
||||
|
||||
/**
|
||||
* `true` for the cloud providers that have no registry models (LiteLLM,
|
||||
* Azure, Bifrost). The admin enters the model spec in the connect modal. The
|
||||
* picker shows them in the "bring your own" section, not in the main list.
|
||||
*/
|
||||
export function isBringYourOwnProvider(
|
||||
providerName: EmbeddingProviderName
|
||||
): boolean {
|
||||
return (
|
||||
providerName === EmbeddingProviderName.LITELLM ||
|
||||
providerName === EmbeddingProviderName.AZURE ||
|
||||
providerName === EmbeddingProviderName.BIFROST
|
||||
);
|
||||
}
|
||||
|
||||
/**
|
||||
* Find an {@link EmbeddingModel} spec by `modelName` across both registries.
|
||||
* Returns `null` for models that aren't pre-registered (e.g. custom
|
||||
@@ -59,6 +75,65 @@ export function findRegistryModel(modelName: string): EmbeddingModel | null {
|
||||
return null;
|
||||
}
|
||||
|
||||
/**
|
||||
* Find the registry model of one provider group. Unlike `findRegistryModel`,
|
||||
* a LiteLLM or Azure deployment whose label equals a registry name (e.g.
|
||||
* `text-embedding-3-large`) does not match the OpenAI entry.
|
||||
*/
|
||||
export function findProviderModel(
|
||||
providerName: EmbeddingProviderName,
|
||||
modelName: string
|
||||
): EmbeddingModel | null {
|
||||
return (
|
||||
findProvider(providerName).embeddingModels.find(
|
||||
(m) => m.modelName === modelName
|
||||
) ?? null
|
||||
);
|
||||
}
|
||||
|
||||
/**
|
||||
* The provider groups and models the picker lists and searches. A legacy model
|
||||
* shows only while it is the current model, matched on provider and name. A
|
||||
* group that this empties drops out, unless `keepProviders` has it (saved
|
||||
* credentials: its header holds the Edit and Disconnect buttons).
|
||||
*/
|
||||
export function visibleEmbeddingProviders(
|
||||
providers: EmbeddingProvider[],
|
||||
current: EmbeddingModelRef | null,
|
||||
keepProviders: {
|
||||
has(providerName: EmbeddingProviderName): boolean;
|
||||
} = new Set()
|
||||
): EmbeddingProvider[] {
|
||||
return providers.flatMap((provider) => {
|
||||
const models = provider.embeddingModels.filter(
|
||||
(m) =>
|
||||
!m.legacy ||
|
||||
(current?.providerName === provider.providerName &&
|
||||
current.modelName === m.modelName)
|
||||
);
|
||||
const emptied = models.length === 0 && provider.embeddingModels.length > 0;
|
||||
return emptied && !keepProviders.has(provider.providerName)
|
||||
? []
|
||||
: [{ ...provider, embeddingModels: models }];
|
||||
});
|
||||
}
|
||||
|
||||
/**
|
||||
* The model a credential test embeds with when no model is being connected or
|
||||
* edited: the provider's first selectable registry model.
|
||||
*/
|
||||
export function defaultTestModelName(
|
||||
providerName: EmbeddingProviderName
|
||||
): string {
|
||||
const model = findProvider(providerName).embeddingModels.find(
|
||||
(m) => !m.legacy
|
||||
);
|
||||
if (!model) {
|
||||
throw new Error(`No selectable ${providerName} model to test with`);
|
||||
}
|
||||
return model.modelName;
|
||||
}
|
||||
|
||||
/** Translated registry description, undefined without a key. */
|
||||
export function embeddingModelDescription(
|
||||
model: EmbeddingModel | null | undefined,
|
||||
@@ -98,8 +173,8 @@ export function embeddingModelDescription(
|
||||
*
|
||||
* 2. Which logical bucket does this model belong to for UI purposes —
|
||||
* icon, modal selection, displayName? (Currently UNREPRESENTED in the
|
||||
* schema for self-hosted models: Nomic vs Microsoft vs custom must
|
||||
* be inferred from `model_name` by walking a frontend registry.)
|
||||
* schema for self-hosted models: IBM vs Nomic vs Microsoft vs custom
|
||||
* must be inferred from `model_name` by walking a frontend registry.)
|
||||
*
|
||||
* Because (2) is unrepresented in the schema, the frontend has historically
|
||||
* resorted to one of two hacks:
|
||||
@@ -139,7 +214,7 @@ export function embeddingModelDescription(
|
||||
* backend already filled it in), this resolver SIMULATES the proper schema
|
||||
* by deriving the canonical `EmbeddingProviderName`, including the
|
||||
* synthetic self-hosted bucket values that the backend cannot currently
|
||||
* persist (`NOMIC`, `MICROSOFT`, `CUSTOM`).
|
||||
* persist (e.g. `IBM`, `NVIDIA`, `NOMIC`, `CUSTOM`).
|
||||
*
|
||||
* Resolution rules, in order:
|
||||
*
|
||||
@@ -156,7 +231,7 @@ export function embeddingModelDescription(
|
||||
* is yet available.
|
||||
*
|
||||
* 3. Otherwise, walk `SELF_HOSTED_PROVIDERS` for a `modelName` match and
|
||||
* return that bucket's `providerName` (e.g. `NOMIC`, `MICROSOFT`).
|
||||
* return that bucket's `providerName` (e.g. `IBM`, `MICROSOFT`).
|
||||
*
|
||||
* 4. Otherwise — the model isn't in any registry — fall through to
|
||||
* `EmbeddingProviderName.CUSTOM`. This is the "user added a custom
|
||||
|
||||
@@ -73,6 +73,7 @@ describe("Google embedding authentication", () => {
|
||||
providerType: "google",
|
||||
apiKey: null,
|
||||
apiUrl: "",
|
||||
modelName: "gemini-embedding-2",
|
||||
apiVersion: null,
|
||||
deploymentName: null,
|
||||
vertexConfig,
|
||||
@@ -88,6 +89,7 @@ describe("Google embedding authentication", () => {
|
||||
expect(fetchSpy.mock.calls[1]?.[1]?.method).toBe("PUT");
|
||||
const testBody = JSON.parse(String(fetchSpy.mock.calls[0]?.[1]?.body));
|
||||
const saveBody = JSON.parse(String(fetchSpy.mock.calls[1]?.[1]?.body));
|
||||
expect(testBody.model_name).toBe("gemini-embedding-2");
|
||||
expect(testBody.vertex_config).toEqual(vertexConfig);
|
||||
expect(testBody.api_key).toBeNull();
|
||||
expect(saveBody.vertex_config).toEqual(vertexConfig);
|
||||
@@ -106,6 +108,7 @@ describe("Google embedding authentication", () => {
|
||||
providerType: "google",
|
||||
apiKey: null,
|
||||
apiUrl: "",
|
||||
modelName: "gemini-embedding-2",
|
||||
apiVersion: null,
|
||||
deploymentName: null,
|
||||
vertexConfig: {
|
||||
|
||||
@@ -38,9 +38,6 @@ export async function testEmbedding({
|
||||
deploymentName,
|
||||
vertexConfig,
|
||||
}: TestEmbeddingArgs) {
|
||||
const testModelName =
|
||||
provider_type === "openai" ? "text-embedding-3-small" : modelName;
|
||||
|
||||
return await fetch("/api/admin/embedding/test-embedding", {
|
||||
method: "POST",
|
||||
headers: { "Content-Type": "application/json" },
|
||||
@@ -48,7 +45,7 @@ export async function testEmbedding({
|
||||
provider_type: provider_type,
|
||||
api_key: apiKey,
|
||||
api_url: apiUrl,
|
||||
model_name: testModelName,
|
||||
model_name: modelName,
|
||||
api_version: apiVersion,
|
||||
deployment_name: deploymentName,
|
||||
vertex_config: vertexConfig,
|
||||
@@ -67,13 +64,14 @@ export async function testEmbedding({
|
||||
*
|
||||
* Returns the vector length of the test embedding, or `null` when no test ran.
|
||||
* `alwaysTest` runs the test even when the stored key is kept, for providers
|
||||
* whose model is free text (Bifrost).
|
||||
* whose model is free text (Bifrost). The test embeds with `modelName`, which
|
||||
* must not be empty.
|
||||
*/
|
||||
export async function connectEmbeddingProvider({
|
||||
providerType,
|
||||
apiKey,
|
||||
apiUrl,
|
||||
modelName = "",
|
||||
modelName,
|
||||
apiVersion,
|
||||
deploymentName,
|
||||
vertexConfig,
|
||||
@@ -82,7 +80,7 @@ export async function connectEmbeddingProvider({
|
||||
providerType: string;
|
||||
apiKey: string | null;
|
||||
apiUrl: string;
|
||||
modelName?: string;
|
||||
modelName: string;
|
||||
apiVersion: string | null;
|
||||
deploymentName: string | null;
|
||||
vertexConfig?: VertexEmbeddingConfig | null;
|
||||
|
||||
@@ -22,9 +22,16 @@ export enum EmbeddingProviderName {
|
||||
AZURE = "azure",
|
||||
BIFROST = "bifrost",
|
||||
|
||||
// Self-hosted
|
||||
// Self-hosted display groups. Frontend-only: the backend stores
|
||||
// provider_type=null for every self-hosted model, so these values are never
|
||||
// sent. Do not reuse a cloud value (e.g. VOYAGE) for a self-hosted group:
|
||||
// `isCloudBased` would then route the model to that cloud API.
|
||||
IBM = "ibm",
|
||||
VOYAGE_SELF_HOSTED = "voyage_self_hosted",
|
||||
NVIDIA = "nvidia",
|
||||
NOMIC = "nomic",
|
||||
MICROSOFT = "microsoft",
|
||||
GTE = "gte",
|
||||
|
||||
// Custom self-hosted (frontend-only sentinel; backend stores provider_type=null)
|
||||
CUSTOM = "custom",
|
||||
@@ -73,19 +80,28 @@ export interface EmbeddingModel {
|
||||
passagePrefix?: string | null;
|
||||
// Absent for custom models, which have no registry description.
|
||||
descriptionKey?: IndexSettingsMessageKey;
|
||||
|
||||
/**
|
||||
* When true, existing usage is allowed, but selecting it as a new embedding
|
||||
* model is blocked.
|
||||
* Kept only so existing deployments still display and re-index correctly.
|
||||
* Not offered as a new target: the picker shows a legacy model only while it
|
||||
* is the current model, and the backend rejects it as a new target.
|
||||
*/
|
||||
deprecated?: boolean;
|
||||
legacy?: boolean;
|
||||
/** Indexing on CPU is too slow for practical use. */
|
||||
gpuRecommended?: boolean;
|
||||
}
|
||||
|
||||
/** The fields sent to the backend. Registry display flags are left out. */
|
||||
export type EmbeddingModelSpec = Omit<
|
||||
EmbeddingModel,
|
||||
"descriptionKey" | "deprecated"
|
||||
"descriptionKey" | "legacy" | "gpuRecommended"
|
||||
>;
|
||||
|
||||
/** The active embedding model, identified by its display group and name. */
|
||||
export interface EmbeddingModelRef {
|
||||
modelName: string;
|
||||
providerName: EmbeddingProviderName;
|
||||
}
|
||||
|
||||
/**
|
||||
* Always write all three fields together. A name without its spec and provider forces
|
||||
* the submit path to guess them back, which misroutes LiteLLM and Azure models.
|
||||
|
||||
@@ -0,0 +1,451 @@
|
||||
/**
|
||||
* @jest-environment jsdom
|
||||
*/
|
||||
|
||||
import {
|
||||
render,
|
||||
screen,
|
||||
setupUser,
|
||||
waitFor,
|
||||
within,
|
||||
} from "@tests/setup/test-utils";
|
||||
import { toast } from "@opal/layouts";
|
||||
import IndexSettingsPage from "@/views/admin/IndexSettingsPage";
|
||||
import type { useConnectorIndexingStatusWithPagination } from "@/lib/hooks";
|
||||
import type { LlmDefaults } from "@/lib/languageModels/types";
|
||||
import {
|
||||
ApplicationStatus,
|
||||
QueryHistoryType,
|
||||
type AppSettings,
|
||||
} from "@/lib/settings/types";
|
||||
import {
|
||||
EmbeddingProviderName,
|
||||
type ConfiguredEmbeddingProvider,
|
||||
type EmbeddingModelResponse,
|
||||
type ReindexProgress,
|
||||
type SavedSearchSettings,
|
||||
VectorQuantization,
|
||||
} from "@/lib/searchSettings/types";
|
||||
|
||||
jest.mock("next/navigation", () => ({
|
||||
useRouter: () => ({
|
||||
push: jest.fn(),
|
||||
replace: jest.fn(),
|
||||
refresh: jest.fn(),
|
||||
}),
|
||||
usePathname: () => "/admin/configuration/search",
|
||||
useSearchParams: () => new URLSearchParams(),
|
||||
}));
|
||||
|
||||
jest.mock("@/lib/settings/hooks", () => ({
|
||||
useSettings: () => mockAppSettings,
|
||||
}));
|
||||
|
||||
jest.mock("@/lib/adminNavLabels", () => ({
|
||||
useAdminRouteTitle: () => (route: { title: string }) => route.title,
|
||||
}));
|
||||
|
||||
// No requireActual: the real module has an import cycle through the
|
||||
// language-model modals.
|
||||
jest.mock("@/lib/hooks", () => ({
|
||||
useConnectorIndexingStatusWithPagination: () => mockIndexingStatuses,
|
||||
}));
|
||||
|
||||
jest.mock("@/lib/languageModels/hooks", () => ({
|
||||
...jest.requireActual("@/lib/languageModels/hooks"),
|
||||
useLlmDefaults: () => mockLlmDefaults,
|
||||
}));
|
||||
|
||||
jest.mock("@/lib/searchSettings/hooks", () => ({
|
||||
...jest.requireActual("@/lib/searchSettings/hooks"),
|
||||
useCurrentEmbeddingModel: () => ({
|
||||
data: mockState.currentModel,
|
||||
isLoading: false,
|
||||
}),
|
||||
useCurrentSearchSettings: () => ({
|
||||
data: mockState.searchSettings,
|
||||
isLoading: false,
|
||||
}),
|
||||
useSecondarySearchSettings: () => ({ data: null }),
|
||||
useReindexProgress: () => ({ data: mockReindexProgress }),
|
||||
useConfiguredEmbeddingProviders: () => ({
|
||||
data: mockState.configuredProviders,
|
||||
}),
|
||||
}));
|
||||
|
||||
// Stable objects: the page memoizes on these, as it does on SWR data.
|
||||
const mockAppSettings: AppSettings = {
|
||||
default_language: "en",
|
||||
anonymous_user_enabled: false,
|
||||
invite_only_enabled: false,
|
||||
notifications: [],
|
||||
needs_reindexing: false,
|
||||
gpu_enabled: false,
|
||||
application_status: ApplicationStatus.ACTIVE,
|
||||
auto_scroll: true,
|
||||
temperature_override_enabled: true,
|
||||
query_history_type: QueryHistoryType.NORMAL,
|
||||
image_extraction_and_analysis_enabled: false,
|
||||
image_analysis_max_size_mb: 20,
|
||||
hide_provider_grouping: false,
|
||||
enterprise: null,
|
||||
appName: "Onyx",
|
||||
logoUrl: null,
|
||||
vectorDbEnabled: false,
|
||||
isLoading: false,
|
||||
error: undefined,
|
||||
};
|
||||
const mockIndexingStatuses: Pick<
|
||||
ReturnType<typeof useConnectorIndexingStatusWithPagination>,
|
||||
"data" | "isLoading" | "isValidating" | "error"
|
||||
> = {
|
||||
data: [],
|
||||
isLoading: false,
|
||||
isValidating: false,
|
||||
error: undefined,
|
||||
};
|
||||
const mockLlmDefaults: LlmDefaults = {
|
||||
llmProviders: [],
|
||||
hasAnyLlm: false,
|
||||
hasAnyVisionLlm: false,
|
||||
defaultLlm: null,
|
||||
defaultVision: null,
|
||||
isLoading: false,
|
||||
};
|
||||
const mockReindexProgress: ReindexProgress = {
|
||||
total: 0,
|
||||
waiting: 0,
|
||||
in_progress: 0,
|
||||
completed: 0,
|
||||
failed: 0,
|
||||
paused: 0,
|
||||
reembeds: true,
|
||||
};
|
||||
|
||||
interface MockState {
|
||||
currentModel: EmbeddingModelResponse | null;
|
||||
searchSettings: SavedSearchSettings | null;
|
||||
configuredProviders: ConfiguredEmbeddingProvider[];
|
||||
}
|
||||
const mockState: MockState = {
|
||||
currentModel: null,
|
||||
searchSettings: null,
|
||||
configuredProviders: [],
|
||||
};
|
||||
|
||||
function setCurrentModel(
|
||||
modelName: string,
|
||||
providerType: EmbeddingProviderName | null,
|
||||
modelDim: number
|
||||
) {
|
||||
const current: EmbeddingModelResponse = {
|
||||
model_name: modelName,
|
||||
model_dim: modelDim,
|
||||
normalize: providerType === null,
|
||||
query_prefix: "",
|
||||
passage_prefix: "",
|
||||
provider_type: providerType,
|
||||
api_key: null,
|
||||
api_url: null,
|
||||
index_name: "danswer_chunk",
|
||||
};
|
||||
mockState.currentModel = current;
|
||||
mockState.searchSettings = {
|
||||
...current,
|
||||
index_name: current.index_name,
|
||||
multipass_indexing: false,
|
||||
enable_contextual_rag: false,
|
||||
contextual_rag_model_configuration_id: null,
|
||||
multilingual_expansion: [],
|
||||
disable_rerank_for_streaming: false,
|
||||
api_url: null,
|
||||
num_rerank: 0,
|
||||
reduced_dimension: null,
|
||||
vector_quantization: VectorQuantization.NONE,
|
||||
rerank_model_name: null,
|
||||
rerank_provider_type: null,
|
||||
rerank_api_key: null,
|
||||
rerank_api_url: null,
|
||||
use_port_flow: true,
|
||||
};
|
||||
}
|
||||
|
||||
function configureProviders(...providerTypes: EmbeddingProviderName[]) {
|
||||
mockState.configuredProviders = providerTypes.map((provider_type) => ({
|
||||
provider_type,
|
||||
api_key: "sk-****",
|
||||
api_url: null,
|
||||
api_version: null,
|
||||
deployment_name: null,
|
||||
}));
|
||||
}
|
||||
|
||||
function modelCard(providerName: EmbeddingProviderName, modelName: string) {
|
||||
return screen.getByTestId(
|
||||
`embedding-model-card:${providerName}:${modelName}`
|
||||
);
|
||||
}
|
||||
|
||||
function queryModelCard(
|
||||
providerName: EmbeddingProviderName,
|
||||
modelName: string
|
||||
) {
|
||||
return screen.queryByTestId(
|
||||
`embedding-model-card:${providerName}:${modelName}`
|
||||
);
|
||||
}
|
||||
|
||||
const BRING_YOUR_OWN = "Advanced: bring your own model or proxy";
|
||||
const GRANITE = "ibm-granite/granite-embedding-97m-multilingual-r2";
|
||||
|
||||
async function openModelPicker(user: ReturnType<typeof setupUser>) {
|
||||
await user.click(screen.getByRole("button", { name: "View All Models" }));
|
||||
}
|
||||
|
||||
interface SentRequest {
|
||||
url: string;
|
||||
method: string;
|
||||
body: Record<string, unknown>;
|
||||
}
|
||||
|
||||
describe("IndexSettingsPage embedding model picker", () => {
|
||||
let requests: SentRequest[];
|
||||
// A test embedding with this model fails, as with a retired model.
|
||||
let failingTestModel: string | null;
|
||||
|
||||
beforeEach(() => {
|
||||
mockState.currentModel = null;
|
||||
mockState.searchSettings = null;
|
||||
mockState.configuredProviders = [];
|
||||
requests = [];
|
||||
failingTestModel = null;
|
||||
jest
|
||||
.spyOn(global, "fetch")
|
||||
.mockImplementation(
|
||||
async (input: RequestInfo | URL, init?: RequestInit) => {
|
||||
const body = init?.body ? JSON.parse(String(init.body)) : {};
|
||||
requests.push({
|
||||
url: String(input),
|
||||
method: init?.method ?? "GET",
|
||||
body,
|
||||
});
|
||||
if (
|
||||
String(input).endsWith("/test-embedding") &&
|
||||
body.model_name === failingTestModel
|
||||
) {
|
||||
return new Response(JSON.stringify({ detail: "model retired" }), {
|
||||
status: 400,
|
||||
});
|
||||
}
|
||||
return new Response("{}", { status: 200 });
|
||||
}
|
||||
);
|
||||
});
|
||||
|
||||
afterEach(() => jest.restoreAllMocks());
|
||||
|
||||
function testedModels(): unknown[] {
|
||||
return requests
|
||||
.filter((r) => r.url.endsWith("/test-embedding"))
|
||||
.map((r) => r.body.model_name);
|
||||
}
|
||||
|
||||
it("shows a legacy current model as current, with a Legacy tag and an upgrade hint", async () => {
|
||||
setCurrentModel("nomic-ai/nomic-embed-text-v1", null, 768);
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
|
||||
const summary = await screen.findByTestId("current-embedding-model");
|
||||
expect(within(summary).getByText("Legacy")).toBeInTheDocument();
|
||||
expect(
|
||||
within(summary).getByText(/This is a legacy model/)
|
||||
).toBeInTheDocument();
|
||||
|
||||
await openModelPicker(user);
|
||||
|
||||
const card = modelCard(
|
||||
EmbeddingProviderName.NOMIC,
|
||||
"nomic-ai/nomic-embed-text-v1"
|
||||
);
|
||||
expect(
|
||||
within(card).getByRole("button", { name: "Current Model" })
|
||||
).toBeInTheDocument();
|
||||
expect(within(card).getByText("Legacy")).toBeInTheDocument();
|
||||
// Other legacy models stay hidden; the new ones are selectable.
|
||||
expect(
|
||||
queryModelCard(EmbeddingProviderName.MICROSOFT, "intfloat/e5-base-v2")
|
||||
).toBeNull();
|
||||
expect(
|
||||
within(modelCard(EmbeddingProviderName.IBM, GRANITE)).getByRole(
|
||||
"button",
|
||||
{ name: "Select Model" }
|
||||
)
|
||||
).toBeInTheDocument();
|
||||
expect(
|
||||
within(
|
||||
modelCard(
|
||||
EmbeddingProviderName.NVIDIA,
|
||||
"nvidia/Nemotron-3-Embed-1B-BF16"
|
||||
)
|
||||
).getByText("GPU recommended")
|
||||
).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("does not find a hidden legacy model by search", async () => {
|
||||
setCurrentModel(GRANITE, null, 384);
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
await openModelPicker(user);
|
||||
|
||||
await user.type(screen.getByPlaceholderText("Search models..."), "e5");
|
||||
|
||||
expect(
|
||||
await screen.findByText("No self-hosted models found")
|
||||
).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("keeps the bring-your-own options in the collapsed Advanced section", async () => {
|
||||
setCurrentModel(
|
||||
"text-embedding-3-small",
|
||||
EmbeddingProviderName.OPENAI,
|
||||
1536
|
||||
);
|
||||
configureProviders(EmbeddingProviderName.OPENAI);
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
await openModelPicker(user);
|
||||
|
||||
const toggle = screen.getByRole("button", { name: BRING_YOUR_OWN });
|
||||
expect(toggle).toHaveAttribute("aria-expanded", "false");
|
||||
expect(
|
||||
screen.queryByText("Add configs for your Azure embedding providers.")
|
||||
).toBeNull();
|
||||
|
||||
await user.click(toggle);
|
||||
|
||||
expect(
|
||||
screen.getByText("Add configs for your LiteLLM embedding providers.")
|
||||
).toBeInTheDocument();
|
||||
expect(
|
||||
screen.getByText("Add configs for your Azure embedding providers.")
|
||||
).toBeInTheDocument();
|
||||
await user.click(screen.getByRole("tab", { name: "Self-hosted" }));
|
||||
expect(
|
||||
screen.getByRole("button", { name: "Add Custom Model" })
|
||||
).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("keeps a current Azure deployment apart from the OpenAI model of the same name", async () => {
|
||||
setCurrentModel(
|
||||
"text-embedding-3-large",
|
||||
EmbeddingProviderName.AZURE,
|
||||
1536
|
||||
);
|
||||
configureProviders(
|
||||
EmbeddingProviderName.AZURE,
|
||||
EmbeddingProviderName.OPENAI
|
||||
);
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
|
||||
const summary = await screen.findByTestId("current-embedding-model");
|
||||
expect(
|
||||
within(summary).queryByText(/OpenAI's large embedding model/)
|
||||
).toBeNull();
|
||||
|
||||
await openModelPicker(user);
|
||||
const openAiCard = modelCard(
|
||||
EmbeddingProviderName.OPENAI,
|
||||
"text-embedding-3-large"
|
||||
);
|
||||
await user.click(
|
||||
within(openAiCard).getByRole("button", { name: "Select Model" })
|
||||
);
|
||||
|
||||
expect(
|
||||
within(openAiCard).getByRole("button", { name: "Selected" })
|
||||
).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("stages a custom model with a registry name as a custom model", async () => {
|
||||
setCurrentModel(GRANITE, null, 384);
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
await openModelPicker(user);
|
||||
await user.click(screen.getByRole("button", { name: BRING_YOUR_OWN }));
|
||||
await user.click(screen.getByRole("button", { name: "Add Custom Model" }));
|
||||
|
||||
const dialog = await screen.findByRole("dialog", {
|
||||
name: /set up custom model/i,
|
||||
});
|
||||
await user.type(
|
||||
within(dialog).getByLabelText(/model name/i),
|
||||
"voyageai/voyage-4-nano"
|
||||
);
|
||||
await user.type(within(dialog).getByLabelText(/model dimension/i), "1024");
|
||||
await user.click(within(dialog).getByRole("button", { name: "Connect" }));
|
||||
|
||||
expect(
|
||||
await screen.findByRole("button", { name: "Apply & Re-index" })
|
||||
).toBeInTheDocument();
|
||||
// The registry card of the same name is not the staged model.
|
||||
expect(
|
||||
within(
|
||||
modelCard(
|
||||
EmbeddingProviderName.VOYAGE_SELF_HOSTED,
|
||||
"voyageai/voyage-4-nano"
|
||||
)
|
||||
).getByRole("button", { name: "Select Model" })
|
||||
).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it("tests the credentials against the model being connected", async () => {
|
||||
setCurrentModel(
|
||||
"text-embedding-3-small",
|
||||
EmbeddingProviderName.OPENAI,
|
||||
1536
|
||||
);
|
||||
configureProviders(EmbeddingProviderName.OPENAI);
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
await openModelPicker(user);
|
||||
|
||||
await user.click(
|
||||
within(
|
||||
modelCard(EmbeddingProviderName.COHERE, "embed-v5.0-pro")
|
||||
).getByRole("button", { name: "Connect" })
|
||||
);
|
||||
const dialog = await screen.findByRole("dialog", {
|
||||
name: /set up cohere/i,
|
||||
});
|
||||
await user.type(within(dialog).getByLabelText(/api key/i), "co-key");
|
||||
await user.click(within(dialog).getByRole("button", { name: "Connect" }));
|
||||
|
||||
await waitFor(() => expect(testedModels()).toEqual(["embed-v5.0-pro"]));
|
||||
});
|
||||
|
||||
it("does not save new credentials that fail the test with the current model", async () => {
|
||||
setCurrentModel("embed-english-v3.0", EmbeddingProviderName.COHERE, 1024);
|
||||
configureProviders(EmbeddingProviderName.COHERE);
|
||||
failingTestModel = "embed-english-v3.0";
|
||||
const toastError = jest.spyOn(toast, "error");
|
||||
const user = setupUser();
|
||||
render(<IndexSettingsPage />);
|
||||
await openModelPicker(user);
|
||||
|
||||
await user.click(screen.getByRole("button", { name: "Edit credentials" }));
|
||||
const dialog = await screen.findByRole("dialog", {
|
||||
name: /manage cohere/i,
|
||||
});
|
||||
const apiKeyInput = within(dialog).getByLabelText(/api key/i);
|
||||
await user.clear(apiKeyInput);
|
||||
await user.type(apiKeyInput, "co-new-key");
|
||||
await user.click(within(dialog).getByRole("button", { name: "Update" }));
|
||||
|
||||
await waitFor(() =>
|
||||
expect(toastError).toHaveBeenCalledWith("model retired")
|
||||
);
|
||||
expect(testedModels()).toEqual(["embed-english-v3.0"]);
|
||||
expect(requests.some((r) => r.method === "PUT")).toBe(false);
|
||||
});
|
||||
});
|
||||
@@ -40,6 +40,7 @@ import {
|
||||
SvgClock,
|
||||
SvgCloud,
|
||||
SvgEmpty,
|
||||
SvgExpand,
|
||||
SvgExternalLink,
|
||||
SvgFold,
|
||||
SvgPlusCircle,
|
||||
@@ -62,6 +63,7 @@ import {
|
||||
VectorQuantization,
|
||||
type ConfiguredEmbeddingProvider,
|
||||
type EmbeddingModel,
|
||||
type EmbeddingModelRef,
|
||||
type EmbeddingModelRequest,
|
||||
type EmbeddingModelSelection,
|
||||
type EmbeddingModelState,
|
||||
@@ -77,9 +79,11 @@ import {
|
||||
import {
|
||||
embeddingModelDescription,
|
||||
findProvider,
|
||||
findRegistryModel,
|
||||
findProviderModel,
|
||||
isBringYourOwnProvider,
|
||||
isCloudBased,
|
||||
resolveProviderName,
|
||||
visibleEmbeddingProviders,
|
||||
} from "@/lib/searchSettings";
|
||||
import {
|
||||
isSameModelSelection,
|
||||
@@ -107,7 +111,6 @@ import {
|
||||
useSecondarySearchSettings,
|
||||
} from "@/lib/searchSettings/hooks";
|
||||
import { useLlmDefaults } from "@/lib/languageModels/hooks";
|
||||
import useFilter from "@/hooks/useFilter";
|
||||
import { SimpleModelSelector } from "@/lib/languageModels/components";
|
||||
import {
|
||||
filterModelConfigurations,
|
||||
@@ -225,8 +228,10 @@ function EmbeddingProviderInfo({ providerName }: EmbeddingProviderInfoProps) {
|
||||
|
||||
interface ProviderGroupProps {
|
||||
provider: EmbeddingProvider;
|
||||
currentModelName?: string;
|
||||
selectedModelName?: string;
|
||||
/** The active embedding model, in this group or another one. */
|
||||
current: EmbeddingModelRef | null;
|
||||
/** The staged model, in this group or another one. */
|
||||
staged: EmbeddingModelRef | null;
|
||||
isCloud?: boolean;
|
||||
existingCredentials?: ConfiguredEmbeddingProvider;
|
||||
/**
|
||||
@@ -248,8 +253,8 @@ interface ProviderGroupProps {
|
||||
|
||||
function ProviderGroup({
|
||||
provider,
|
||||
currentModelName,
|
||||
selectedModelName,
|
||||
current,
|
||||
staged,
|
||||
isCloud = false,
|
||||
existingCredentials,
|
||||
existingModel,
|
||||
@@ -258,6 +263,7 @@ function ProviderGroup({
|
||||
}: ProviderGroupProps) {
|
||||
const t = useTranslations("admin.indexSettings");
|
||||
const models = provider.embeddingModels;
|
||||
const isBringYourOwn = isBringYourOwnProvider(provider.providerName);
|
||||
const isConfigured = isCloud ? !!existingCredentials : true;
|
||||
const disconnectModal = useCreateModal();
|
||||
const connectModal = useCreateModal();
|
||||
@@ -265,9 +271,14 @@ function ProviderGroup({
|
||||
const providerCreationModal = useCreateModal();
|
||||
const [pendingConnectModel, setPendingConnectModel] =
|
||||
useState<EmbeddingModel | null>(null);
|
||||
const providerGroupContainsCurrentModelName = models.some(
|
||||
(m) => m.modelName === currentModelName
|
||||
);
|
||||
// The current model uses this provider's credentials, whether or not it is
|
||||
// a registry model, so they cannot be disconnected.
|
||||
const isCurrentProvider = current?.providerName === provider.providerName;
|
||||
const currentModelName = isCurrentProvider ? current?.modelName : undefined;
|
||||
const selectedModelName =
|
||||
staged?.providerName === provider.providerName
|
||||
? staged.modelName
|
||||
: undefined;
|
||||
|
||||
const handleDisconnect = useCallback(async () => {
|
||||
if (!isCloud) return;
|
||||
@@ -309,7 +320,6 @@ function ProviderGroup({
|
||||
|
||||
const handleModelSelect = useCallback(
|
||||
(model: EmbeddingModel) => {
|
||||
if (model.deprecated) return;
|
||||
const state = getModelState(model);
|
||||
|
||||
if (state === "selected" || state === "current") {
|
||||
@@ -317,6 +327,10 @@ function ProviderGroup({
|
||||
return;
|
||||
}
|
||||
|
||||
// A legacy model is listed only while it is current; it is never a new
|
||||
// target.
|
||||
if (model.legacy) return;
|
||||
|
||||
if (state === "unconnected" && isCloud) {
|
||||
setPendingConnectModel(model);
|
||||
connectModal.toggle(true);
|
||||
@@ -335,6 +349,23 @@ function ProviderGroup({
|
||||
]
|
||||
);
|
||||
|
||||
function renderModelCard(model: EmbeddingModel) {
|
||||
const state = getModelState(model);
|
||||
// The current card loses its highlight to a staged model in any group.
|
||||
const isPrioritized =
|
||||
state === "selected" || (state === "current" && staged === null);
|
||||
return (
|
||||
<EmbeddingModelCard
|
||||
key={model.modelName}
|
||||
model={model}
|
||||
provider={provider}
|
||||
modelState={state}
|
||||
cardState={isPrioritized ? "selected" : "filled"}
|
||||
onSelect={() => handleModelSelect(model)}
|
||||
/>
|
||||
);
|
||||
}
|
||||
|
||||
return (
|
||||
<>
|
||||
{isCloud && (
|
||||
@@ -433,9 +464,9 @@ function ProviderGroup({
|
||||
icon={SvgUnplug}
|
||||
prominence="tertiary"
|
||||
size="sm"
|
||||
disabled={providerGroupContainsCurrentModelName}
|
||||
disabled={isCurrentProvider}
|
||||
tooltip={
|
||||
providerGroupContainsCurrentModelName
|
||||
isCurrentProvider
|
||||
? t("providerGroup.disconnectButton.disabledTooltip")
|
||||
: undefined
|
||||
}
|
||||
@@ -456,7 +487,8 @@ function ProviderGroup({
|
||||
</GeneralLayouts.Section>
|
||||
</div>
|
||||
|
||||
{models.length === 0 ? (
|
||||
{models.map(renderModelCard)}
|
||||
{isBringYourOwn && (
|
||||
<SelectCard
|
||||
state="filled"
|
||||
rounding={3}
|
||||
@@ -483,23 +515,6 @@ function ProviderGroup({
|
||||
center
|
||||
/>
|
||||
</SelectCard>
|
||||
) : (
|
||||
models.map((model) => {
|
||||
const state = getModelState(model);
|
||||
const isPrioritized =
|
||||
state === "selected" ||
|
||||
(state === "current" && !selectedModelName);
|
||||
return (
|
||||
<EmbeddingModelCard
|
||||
key={model.modelName}
|
||||
model={model}
|
||||
provider={provider}
|
||||
modelState={state}
|
||||
cardState={isPrioritized ? "selected" : "filled"}
|
||||
onSelect={() => handleModelSelect(model)}
|
||||
/>
|
||||
);
|
||||
})
|
||||
)}
|
||||
</GeneralLayouts.Section>
|
||||
</>
|
||||
@@ -523,7 +538,6 @@ function EmbeddingModelCard({
|
||||
}: EmbeddingModelCardProps) {
|
||||
const t = useTranslations("admin.indexSettings");
|
||||
const { appName } = useSettings();
|
||||
const isDeprecated = model.deprecated;
|
||||
const topRightButton = (() => {
|
||||
switch (modelState) {
|
||||
case "unconnected":
|
||||
@@ -532,26 +546,13 @@ function EmbeddingModelCard({
|
||||
prominence="tertiary"
|
||||
rightIcon={SvgArrowExchange}
|
||||
onClick={onSelect}
|
||||
disabled={isDeprecated}
|
||||
tooltip={
|
||||
isDeprecated
|
||||
? t("modelCard.deprecated.connectTooltip")
|
||||
: undefined
|
||||
}
|
||||
>
|
||||
{t("modelCard.connectButton.label")}
|
||||
</Button>
|
||||
);
|
||||
case "connected":
|
||||
return (
|
||||
<Button
|
||||
prominence="tertiary"
|
||||
onClick={onSelect}
|
||||
disabled={isDeprecated}
|
||||
tooltip={
|
||||
isDeprecated ? t("modelCard.deprecated.selectTooltip") : undefined
|
||||
}
|
||||
>
|
||||
<Button prominence="tertiary" onClick={onSelect}>
|
||||
{t("modelCard.selectButton.label")}
|
||||
</Button>
|
||||
);
|
||||
@@ -580,19 +581,13 @@ function EmbeddingModelCard({
|
||||
}
|
||||
})();
|
||||
|
||||
const isClickable =
|
||||
!isDeprecated &&
|
||||
(modelState === "unconnected" ||
|
||||
modelState === "connected" ||
|
||||
modelState === "current" ||
|
||||
modelState === "selected");
|
||||
|
||||
return (
|
||||
<SelectCard
|
||||
state={cardState}
|
||||
rounding={3}
|
||||
padding={1}
|
||||
onClick={isClickable ? onSelect : undefined}
|
||||
onClick={onSelect}
|
||||
data-testid={`embedding-model-card:${provider.providerName}:${model.modelName}`}
|
||||
>
|
||||
<GeneralLayouts.Section flexDirection="row" alignItems="start">
|
||||
<GeneralLayouts.Section gap={0} padding={2} alignItems="start">
|
||||
@@ -600,6 +595,17 @@ function EmbeddingModelCard({
|
||||
icon={provider.icon}
|
||||
title={model.modelName}
|
||||
description={embeddingModelDescription(model, t, appName)}
|
||||
tag={
|
||||
model.legacy
|
||||
? {
|
||||
title: t("modelCard.legacy.tag"),
|
||||
color: "amber",
|
||||
tooltip: t("modelCard.legacy.tooltip"),
|
||||
}
|
||||
: model.gpuRecommended
|
||||
? { title: t("modelCard.gpuRecommended.tag"), color: "gray" }
|
||||
: undefined
|
||||
}
|
||||
sizePreset="main-ui"
|
||||
variant="section"
|
||||
/>
|
||||
@@ -613,6 +619,113 @@ function EmbeddingModelCard({
|
||||
);
|
||||
}
|
||||
|
||||
interface BringYourOwnSectionProps {
|
||||
open: boolean;
|
||||
onOpenChange: (open: boolean) => void;
|
||||
description: string | RichStr;
|
||||
children: React.ReactNode;
|
||||
}
|
||||
|
||||
/**
|
||||
* Low-prominence, collapsible home for the bring-your-own options (LiteLLM,
|
||||
* Azure, Bifrost, custom self-hosted models), below the registry models.
|
||||
*/
|
||||
function BringYourOwnSection({
|
||||
open,
|
||||
onOpenChange,
|
||||
description,
|
||||
children,
|
||||
}: BringYourOwnSectionProps) {
|
||||
const t = useTranslations("admin.indexSettings");
|
||||
return (
|
||||
<GeneralLayouts.Section gap={1} alignItems="stretch">
|
||||
<GeneralLayouts.Section
|
||||
flexDirection="row"
|
||||
justifyContent="start"
|
||||
height="fit"
|
||||
className="mt-2"
|
||||
>
|
||||
<Button
|
||||
prominence="tertiary"
|
||||
rightIcon={open ? SvgFold : SvgExpand}
|
||||
aria-expanded={open}
|
||||
onClick={() => onOpenChange(!open)}
|
||||
>
|
||||
{t("modelPicker.bringYourOwn.title")}
|
||||
</Button>
|
||||
</GeneralLayouts.Section>
|
||||
{open && (
|
||||
<>
|
||||
<GeneralLayouts.Section
|
||||
alignItems="start"
|
||||
width="auto"
|
||||
height="fit"
|
||||
className="mx-2 mb-1"
|
||||
>
|
||||
<Text font="secondary-body" color="text-03" as="p">
|
||||
{description}
|
||||
</Text>
|
||||
</GeneralLayouts.Section>
|
||||
{children}
|
||||
</>
|
||||
)}
|
||||
</GeneralLayouts.Section>
|
||||
);
|
||||
}
|
||||
|
||||
interface CustomModelGroupProps {
|
||||
onAddCustomModel: () => void;
|
||||
}
|
||||
|
||||
/** Self-hosted models entered by hand ("Add Custom Model"). */
|
||||
function CustomModelGroup({ onAddCustomModel }: CustomModelGroupProps) {
|
||||
const t = useTranslations("admin.indexSettings");
|
||||
return (
|
||||
<GeneralLayouts.Section gap={1}>
|
||||
<GeneralLayouts.Section
|
||||
flexDirection="row"
|
||||
justifyContent="start"
|
||||
gap={0}
|
||||
padding={1}
|
||||
height="fit"
|
||||
className="mt-1"
|
||||
>
|
||||
<Spacer orientation="horizontal" rem={0.675} />
|
||||
<Content
|
||||
icon={CUSTOM_PROVIDER.icon}
|
||||
title={t("modelPicker.customModels.title")}
|
||||
sizePreset="secondary"
|
||||
/>
|
||||
</GeneralLayouts.Section>
|
||||
|
||||
<SelectCard
|
||||
state="filled"
|
||||
rounding={3}
|
||||
padding={2}
|
||||
onClick={onAddCustomModel}
|
||||
>
|
||||
<ContentAction
|
||||
title={t("modelPicker.customModel.title")}
|
||||
sizePreset="secondary"
|
||||
variant="body"
|
||||
color="muted"
|
||||
padding={1}
|
||||
rightChildren={
|
||||
<Button
|
||||
prominence="tertiary"
|
||||
rightIcon={SvgPlusCircle}
|
||||
onClick={onAddCustomModel}
|
||||
>
|
||||
{t("modelPicker.addCustomModel.label")}
|
||||
</Button>
|
||||
}
|
||||
center
|
||||
/>
|
||||
</SelectCard>
|
||||
</GeneralLayouts.Section>
|
||||
);
|
||||
}
|
||||
|
||||
interface IndexSettingsFormValues extends EmbeddingModelSelection {
|
||||
enable_contextual_rag: boolean;
|
||||
contextual_rag_model_configuration_id: number | null;
|
||||
@@ -783,35 +896,8 @@ export default function IndexSettingsPage() {
|
||||
null
|
||||
);
|
||||
|
||||
const allModels = useMemo(
|
||||
() => [...CLOUD_BASED_PROVIDERS, ...SELF_HOSTED_PROVIDERS],
|
||||
[]
|
||||
);
|
||||
|
||||
const {
|
||||
query,
|
||||
setQuery,
|
||||
filtered: filteredProviders,
|
||||
} = useFilter(
|
||||
allModels,
|
||||
(embeddingProvider) =>
|
||||
`${embeddingProvider.displayName} ${embeddingProvider.embeddingModels
|
||||
.map((embeddingModel) => embeddingModel.modelName)
|
||||
.join(" ")}`
|
||||
);
|
||||
|
||||
const { filteredCloudProviders, filteredSelfHostedProviders } =
|
||||
useMemo(() => {
|
||||
const matched = new Set(filteredProviders);
|
||||
return {
|
||||
filteredCloudProviders: CLOUD_BASED_PROVIDERS.filter((p) =>
|
||||
matched.has(p)
|
||||
),
|
||||
filteredSelfHostedProviders: SELF_HOSTED_PROVIDERS.filter((p) =>
|
||||
matched.has(p)
|
||||
),
|
||||
};
|
||||
}, [filteredProviders]);
|
||||
// Whether the admin opened the bring-your-own section.
|
||||
const [bringYourOwnOpen, setBringYourOwnOpen] = useState(false);
|
||||
|
||||
const { data: secondarySearchSettings } = useSecondarySearchSettings();
|
||||
// INSTANT switchover swaps immediately — no secondary settings — and backfills on the
|
||||
@@ -855,27 +941,85 @@ export default function IndexSettingsPage() {
|
||||
};
|
||||
}, [currentEmbeddingModel]);
|
||||
|
||||
const currentProviderName = currentEmbeddingModel
|
||||
? resolveProviderName(
|
||||
currentEmbeddingModel.model_name,
|
||||
currentEmbeddingModel.provider_type
|
||||
)
|
||||
: null;
|
||||
const currentModelName = currentEmbeddingModel?.model_name;
|
||||
const currentProviderType = currentEmbeddingModel?.provider_type ?? null;
|
||||
const currentModelRef: EmbeddingModelRef | null = useMemo(
|
||||
() =>
|
||||
currentModelName === undefined
|
||||
? null
|
||||
: {
|
||||
modelName: currentModelName,
|
||||
providerName: resolveProviderName(
|
||||
currentModelName,
|
||||
currentProviderType
|
||||
),
|
||||
},
|
||||
[currentModelName, currentProviderType]
|
||||
);
|
||||
const currentProviderName = currentModelRef?.providerName ?? null;
|
||||
const currentProvider = currentProviderName
|
||||
? findProvider(currentProviderName)
|
||||
: null;
|
||||
const isCurrentCloudBased = currentProviderName
|
||||
? isCloudBased(currentProviderName)
|
||||
: false;
|
||||
// Matched on provider AND name: an Azure deployment labelled like an OpenAI
|
||||
// model must not borrow that model's registry entry.
|
||||
const currentRegistryModel = currentModelRef
|
||||
? findProviderModel(currentModelRef.providerName, currentModelRef.modelName)
|
||||
: null;
|
||||
|
||||
const { data: searchSettings, isLoading: isLoadingSearchSettings } =
|
||||
useCurrentSearchSettings({ pollIntervalMs: isReindexing ? 5000 : 0 });
|
||||
const { data: configuredProvidersList } = useConfiguredEmbeddingProviders();
|
||||
const configuredProviders = useMemo(
|
||||
() =>
|
||||
new Map((configuredProvidersList ?? []).map((p) => [p.provider_type, p])),
|
||||
[configuredProvidersList]
|
||||
);
|
||||
const visibleCloudProviders = useMemo(
|
||||
() =>
|
||||
visibleEmbeddingProviders(
|
||||
CLOUD_BASED_PROVIDERS,
|
||||
currentModelRef,
|
||||
configuredProviders
|
||||
),
|
||||
[currentModelRef, configuredProviders]
|
||||
);
|
||||
const visibleSelfHostedProviders = useMemo(
|
||||
() => visibleEmbeddingProviders(SELF_HOSTED_PROVIDERS, currentModelRef),
|
||||
[currentModelRef]
|
||||
);
|
||||
const [query, setQuery] = useState("");
|
||||
const isSearching = query.trim() !== "";
|
||||
// The search runs over the visible groups, so it cannot find a hidden
|
||||
// legacy model.
|
||||
const {
|
||||
filteredCloudProviders,
|
||||
filteredBringYourOwnProviders,
|
||||
filteredSelfHostedProviders,
|
||||
customModelMatched,
|
||||
} = useMemo(() => {
|
||||
const needle = query.trim().toLowerCase();
|
||||
const matches = (provider: EmbeddingProvider) =>
|
||||
`${provider.displayName} ${provider.embeddingModels
|
||||
.map((model) => model.modelName)
|
||||
.join(" ")}`
|
||||
.toLowerCase()
|
||||
.includes(needle);
|
||||
const cloud = visibleCloudProviders.filter(matches);
|
||||
return {
|
||||
filteredCloudProviders: cloud.filter(
|
||||
(p) => !isBringYourOwnProvider(p.providerName)
|
||||
),
|
||||
filteredBringYourOwnProviders: cloud.filter((p) =>
|
||||
isBringYourOwnProvider(p.providerName)
|
||||
),
|
||||
filteredSelfHostedProviders: visibleSelfHostedProviders.filter(matches),
|
||||
customModelMatched: matches(CUSTOM_PROVIDER),
|
||||
};
|
||||
}, [query, visibleCloudProviders, visibleSelfHostedProviders]);
|
||||
|
||||
const { data: searchSettings, isLoading: isLoadingSearchSettings } =
|
||||
useCurrentSearchSettings({ pollIntervalMs: isReindexing ? 5000 : 0 });
|
||||
const cancelReindexModal = useCreateModal();
|
||||
const forwardOnlyModal = useCreateModal();
|
||||
const customModelModal = useCreateModal();
|
||||
@@ -944,9 +1088,12 @@ export default function IndexSettingsPage() {
|
||||
() =>
|
||||
savedModelSelection(
|
||||
currentEmbeddingModelSpec,
|
||||
currentEmbeddingModel?.provider_type ?? null
|
||||
// Custom models are staged as CUSTOM, so the saved one must match.
|
||||
currentProviderName === EmbeddingProviderName.CUSTOM
|
||||
? EmbeddingProviderName.CUSTOM
|
||||
: (currentEmbeddingModel?.provider_type ?? null)
|
||||
),
|
||||
[currentEmbeddingModelSpec, currentEmbeddingModel]
|
||||
[currentEmbeddingModelSpec, currentEmbeddingModel, currentProviderName]
|
||||
);
|
||||
|
||||
const initialFormValues: IndexSettingsFormValues = useMemo(
|
||||
@@ -1271,10 +1418,56 @@ export default function IndexSettingsPage() {
|
||||
void setFieldValue("model_spec", selection.model_spec);
|
||||
void setFieldValue("model_provider", selection.model_provider);
|
||||
};
|
||||
// Compares the provider and the spec too, like classifyChanges:
|
||||
// an OpenAI model with the name of the current Azure deployment
|
||||
// is a staged change.
|
||||
const isModelStaged =
|
||||
values.model_name !== initialFormValues.model_name &&
|
||||
!!values.model_name;
|
||||
const stagedModelName = isModelStaged ? values.model_name : null;
|
||||
!!values.model_name &&
|
||||
!isSameModelSelection(values, initialFormValues);
|
||||
// Registry picks carry no provider; their name resolves it.
|
||||
// Custom models carry CUSTOM, even with a registry name.
|
||||
const stagedModelRef: EmbeddingModelRef | null = isModelStaged
|
||||
? {
|
||||
modelName: values.model_name,
|
||||
providerName:
|
||||
values.model_provider ??
|
||||
resolveProviderName(values.model_name, null),
|
||||
}
|
||||
: null;
|
||||
// A search that matches a bring-your-own option shows it.
|
||||
const bringYourOwnExpanded = bringYourOwnOpen || isSearching;
|
||||
const renderCloudProviderGroup = (
|
||||
provider: EmbeddingProvider
|
||||
) => (
|
||||
<ProviderGroup
|
||||
key={provider.providerName}
|
||||
provider={provider}
|
||||
current={currentModelRef}
|
||||
staged={stagedModelRef}
|
||||
isCloud
|
||||
existingCredentials={configuredProviders?.get(
|
||||
provider.providerName
|
||||
)}
|
||||
existingModel={
|
||||
currentEmbeddingModel?.provider_type ===
|
||||
provider.providerName
|
||||
? (currentEmbeddingModelSpec ?? undefined)
|
||||
: undefined
|
||||
}
|
||||
onSelectModel={(name, customModel) =>
|
||||
applySelection({
|
||||
model_name: name,
|
||||
model_spec: customModel
|
||||
? { ...customModel, modelName: name }
|
||||
: null,
|
||||
model_provider: customModel
|
||||
? provider.providerName
|
||||
: null,
|
||||
})
|
||||
}
|
||||
onDeselectModel={() => applySelection(savedSelection)}
|
||||
/>
|
||||
);
|
||||
// Block apply when Contextual Retrieval is on but no LLM is set.
|
||||
const contextualRagModelMissing =
|
||||
values.enable_contextual_rag &&
|
||||
@@ -1511,7 +1704,7 @@ export default function IndexSettingsPage() {
|
||||
...customModel,
|
||||
modelName: customModel.modelName,
|
||||
},
|
||||
model_provider: null,
|
||||
model_provider: EmbeddingProviderName.CUSTOM,
|
||||
});
|
||||
}
|
||||
customModelModal.toggle(false);
|
||||
@@ -1765,55 +1958,29 @@ export default function IndexSettingsPage() {
|
||||
expandedContent={
|
||||
<>
|
||||
<Tabs.Content value={MODEL_TAB_CLOUD}>
|
||||
{filteredCloudProviders.length > 0 ? (
|
||||
{filteredCloudProviders.length > 0 ||
|
||||
filteredBringYourOwnProviders.length >
|
||||
0 ? (
|
||||
<GeneralLayouts.Section
|
||||
gap={2}
|
||||
padding={2}
|
||||
>
|
||||
{filteredCloudProviders.map(
|
||||
(provider) => (
|
||||
<ProviderGroup
|
||||
key={provider.providerName}
|
||||
provider={provider}
|
||||
currentModelName={
|
||||
currentEmbeddingModel?.model_name
|
||||
}
|
||||
selectedModelName={
|
||||
stagedModelName ?? undefined
|
||||
}
|
||||
isCloud
|
||||
existingCredentials={configuredProviders?.get(
|
||||
provider.providerName
|
||||
)}
|
||||
existingModel={
|
||||
currentEmbeddingModel?.provider_type ===
|
||||
provider.providerName
|
||||
? (currentEmbeddingModelSpec ??
|
||||
undefined)
|
||||
: undefined
|
||||
}
|
||||
onSelectModel={(
|
||||
name,
|
||||
customModel
|
||||
) =>
|
||||
applySelection({
|
||||
model_name: name,
|
||||
model_spec: customModel
|
||||
? {
|
||||
...customModel,
|
||||
modelName: name,
|
||||
}
|
||||
: null,
|
||||
model_provider: customModel
|
||||
? provider.providerName
|
||||
: null,
|
||||
})
|
||||
}
|
||||
onDeselectModel={() =>
|
||||
applySelection(savedSelection)
|
||||
}
|
||||
/>
|
||||
)
|
||||
renderCloudProviderGroup
|
||||
)}
|
||||
{filteredBringYourOwnProviders.length >
|
||||
0 && (
|
||||
<BringYourOwnSection
|
||||
open={bringYourOwnExpanded}
|
||||
onOpenChange={setBringYourOwnOpen}
|
||||
description={t(
|
||||
"modelPicker.bringYourOwn.cloudDescription"
|
||||
)}
|
||||
>
|
||||
{filteredBringYourOwnProviders.map(
|
||||
renderCloudProviderGroup
|
||||
)}
|
||||
</BringYourOwnSection>
|
||||
)}
|
||||
</GeneralLayouts.Section>
|
||||
) : (
|
||||
@@ -1830,23 +1997,25 @@ export default function IndexSettingsPage() {
|
||||
</Tabs.Content>
|
||||
|
||||
<Tabs.Content value={MODEL_TAB_SELF}>
|
||||
{filteredSelfHostedProviders.length >
|
||||
0 ? (
|
||||
{filteredSelfHostedProviders.length > 0 ||
|
||||
customModelMatched ? (
|
||||
<GeneralLayouts.Section
|
||||
gap={2}
|
||||
padding={2}
|
||||
>
|
||||
<Text
|
||||
font="secondary-body"
|
||||
color="text-03"
|
||||
>
|
||||
{t("modelPicker.cpuEstimateHint")}
|
||||
</Text>
|
||||
{filteredSelfHostedProviders.map(
|
||||
(shProvider) => (
|
||||
<ProviderGroup
|
||||
key={shProvider.providerName}
|
||||
provider={shProvider}
|
||||
currentModelName={
|
||||
currentEmbeddingModel?.model_name
|
||||
}
|
||||
selectedModelName={
|
||||
stagedModelName ?? undefined
|
||||
}
|
||||
current={currentModelRef}
|
||||
staged={stagedModelRef}
|
||||
onSelectModel={(name) =>
|
||||
applySelection({
|
||||
model_name: name,
|
||||
@@ -1861,63 +2030,21 @@ export default function IndexSettingsPage() {
|
||||
)
|
||||
)}
|
||||
|
||||
<GeneralLayouts.Section gap={1}>
|
||||
<div className="px-1 pt-1 w-full h-(--height-line-h1-headline)">
|
||||
<GeneralLayouts.Section
|
||||
flexDirection="row"
|
||||
gap={0}
|
||||
>
|
||||
<Spacer
|
||||
orientation="horizontal"
|
||||
rem={0.675}
|
||||
/>
|
||||
<div className="flex flex-row justify-between items-center w-full py-1">
|
||||
<Content
|
||||
icon={CUSTOM_PROVIDER.icon}
|
||||
title={t(
|
||||
"modelPicker.customModels.title"
|
||||
)}
|
||||
sizePreset="secondary"
|
||||
/>
|
||||
</div>
|
||||
</GeneralLayouts.Section>
|
||||
</div>
|
||||
|
||||
<SelectCard
|
||||
state="filled"
|
||||
rounding={3}
|
||||
padding={2}
|
||||
onClick={() =>
|
||||
customModelModal.toggle(true)
|
||||
}
|
||||
{customModelMatched && (
|
||||
<BringYourOwnSection
|
||||
open={bringYourOwnExpanded}
|
||||
onOpenChange={setBringYourOwnOpen}
|
||||
description={t(
|
||||
"modelPicker.bringYourOwn.selfHostedDescription"
|
||||
)}
|
||||
>
|
||||
<ContentAction
|
||||
title={t(
|
||||
"modelPicker.customModel.title"
|
||||
)}
|
||||
sizePreset="secondary"
|
||||
variant="body"
|
||||
color="muted"
|
||||
padding={1}
|
||||
rightChildren={
|
||||
<Button
|
||||
prominence="tertiary"
|
||||
rightIcon={SvgPlusCircle}
|
||||
onClick={() =>
|
||||
customModelModal.toggle(
|
||||
true
|
||||
)
|
||||
}
|
||||
>
|
||||
{t(
|
||||
"modelPicker.addCustomModel.label"
|
||||
)}
|
||||
</Button>
|
||||
<CustomModelGroup
|
||||
onAddCustomModel={() =>
|
||||
customModelModal.toggle(true)
|
||||
}
|
||||
center
|
||||
/>
|
||||
</SelectCard>
|
||||
</GeneralLayouts.Section>
|
||||
</BringYourOwnSection>
|
||||
)}
|
||||
</GeneralLayouts.Section>
|
||||
) : (
|
||||
<IllustrationContent
|
||||
@@ -1985,7 +2112,10 @@ export default function IndexSettingsPage() {
|
||||
</div>
|
||||
</div>
|
||||
) : (
|
||||
<div className="flex flex-row items-start w-full">
|
||||
<div
|
||||
className="flex flex-row items-start w-full"
|
||||
data-testid="current-embedding-model"
|
||||
>
|
||||
<GeneralLayouts.Section
|
||||
padding={2}
|
||||
gap={0}
|
||||
@@ -1997,12 +2127,20 @@ export default function IndexSettingsPage() {
|
||||
}
|
||||
title={currentEmbeddingModel.model_name}
|
||||
description={embeddingModelDescription(
|
||||
findRegistryModel(
|
||||
currentEmbeddingModel.model_name
|
||||
),
|
||||
currentRegistryModel,
|
||||
t,
|
||||
settings.appName
|
||||
)}
|
||||
tag={
|
||||
currentRegistryModel?.legacy
|
||||
? {
|
||||
title: t(
|
||||
"modelCard.legacy.tag"
|
||||
),
|
||||
color: "amber",
|
||||
}
|
||||
: undefined
|
||||
}
|
||||
sizePreset="main-ui"
|
||||
variant="section"
|
||||
/>
|
||||
@@ -2013,29 +2151,38 @@ export default function IndexSettingsPage() {
|
||||
/>
|
||||
)}
|
||||
</div>
|
||||
{currentRegistryModel?.legacy && (
|
||||
<GeneralLayouts.Section
|
||||
alignItems="start"
|
||||
width="auto"
|
||||
height="fit"
|
||||
className="mt-2 mx-6"
|
||||
>
|
||||
<Text
|
||||
font="secondary-body"
|
||||
color="text-03"
|
||||
as="p"
|
||||
>
|
||||
{t("currentModel.legacyHint")}
|
||||
</Text>
|
||||
</GeneralLayouts.Section>
|
||||
)}
|
||||
</GeneralLayouts.Section>
|
||||
|
||||
<div className="flex flex-col justify-start items-end shrink-0 gap-1 p-2">
|
||||
<Button
|
||||
prominence="secondary"
|
||||
onClick={() => {
|
||||
const isStagedSelfHosted =
|
||||
stagedModelName &&
|
||||
SELF_HOSTED_PROVIDERS.some((p) =>
|
||||
p.embeddingModels.some(
|
||||
(m) =>
|
||||
m.modelName ===
|
||||
stagedModelName
|
||||
)
|
||||
);
|
||||
// Open on the tab that holds the
|
||||
// staged model, else the current one.
|
||||
const focusProviderName =
|
||||
stagedModelRef?.providerName ??
|
||||
currentProviderName;
|
||||
setActiveModelTab(
|
||||
isStagedSelfHosted
|
||||
? MODEL_TAB_SELF
|
||||
: stagedModelName
|
||||
? MODEL_TAB_CLOUD
|
||||
: currentEmbeddingModel?.provider_type
|
||||
? MODEL_TAB_CLOUD
|
||||
: MODEL_TAB_SELF
|
||||
focusProviderName &&
|
||||
isCloudBased(focusProviderName)
|
||||
? MODEL_TAB_CLOUD
|
||||
: MODEL_TAB_SELF
|
||||
);
|
||||
setViewAllModelsOpen(true);
|
||||
}}
|
||||
|
||||
@@ -20,6 +20,7 @@ import {
|
||||
type EmbeddingProvider,
|
||||
type VertexEmbeddingConfig,
|
||||
} from "@/lib/searchSettings/types";
|
||||
import { defaultTestModelName } from "@/lib/searchSettings";
|
||||
import {
|
||||
connectEmbeddingProvider,
|
||||
testEmbedding,
|
||||
@@ -103,7 +104,8 @@ function ModalShell({ provider, isEditing, children }: ModalShellProps) {
|
||||
// returns `null`.
|
||||
//
|
||||
// `apiUrl`, `apiVersion`, `deploymentName` default to "" / null so simple
|
||||
// providers (OpenAI / Cohere / Voyage / Google) only have to pass `apiKey`.
|
||||
// providers (OpenAI / Cohere / Voyage / Google) only have to pass `apiKey`
|
||||
// and the `modelName` the test embeds with.
|
||||
// ---------------------------------------------------------------------------
|
||||
|
||||
interface ProviderTestResult {
|
||||
@@ -115,7 +117,7 @@ async function testAndSaveProviderCredentials({
|
||||
apiKey,
|
||||
unknownErrorMessage,
|
||||
apiUrl = "",
|
||||
modelName = "",
|
||||
modelName,
|
||||
apiVersion = null,
|
||||
deploymentName = null,
|
||||
vertexConfig,
|
||||
@@ -126,7 +128,7 @@ async function testAndSaveProviderCredentials({
|
||||
/** Fallback toast copy when the backend error carries no message. */
|
||||
unknownErrorMessage: string;
|
||||
apiUrl?: string;
|
||||
modelName?: string;
|
||||
modelName: string;
|
||||
apiVersion?: string | null;
|
||||
deploymentName?: string | null;
|
||||
vertexConfig?: VertexEmbeddingConfig | null;
|
||||
@@ -158,8 +160,10 @@ interface ProviderModalProps {
|
||||
provider: EmbeddingProvider;
|
||||
existingCredentials?: ConfiguredEmbeddingProvider;
|
||||
/**
|
||||
* Model being connected, selected, or edited for this provider. Google
|
||||
* tests this model. Custom providers also use it to preload model fields.
|
||||
* Model being connected, selected, or edited for this provider. The
|
||||
* credential test of a registry provider embeds with it, else with
|
||||
* `defaultTestModelName`. Custom providers also use it to preload model
|
||||
* fields.
|
||||
*/
|
||||
existingModel?: EmbeddingModel;
|
||||
/**
|
||||
@@ -181,6 +185,7 @@ interface StandardFormValues {
|
||||
function StandardProviderModal({
|
||||
provider,
|
||||
existingCredentials,
|
||||
existingModel,
|
||||
onSubmit,
|
||||
}: ProviderModalProps) {
|
||||
const t = useTranslations("admin.indexSettings");
|
||||
@@ -207,6 +212,9 @@ function StandardProviderModal({
|
||||
await testAndSaveProviderCredentials({
|
||||
provider,
|
||||
apiKey,
|
||||
modelName:
|
||||
existingModel?.modelName ??
|
||||
defaultTestModelName(provider.providerName),
|
||||
unknownErrorMessage: t("toasts.unknownError"),
|
||||
})
|
||||
) {
|
||||
@@ -360,8 +368,7 @@ function GoogleProviderModal({
|
||||
},
|
||||
modelName:
|
||||
existingModel?.modelName ??
|
||||
provider.embeddingModels[0]?.modelName ??
|
||||
"",
|
||||
defaultTestModelName(provider.providerName),
|
||||
unknownErrorMessage: t("toasts.unknownError"),
|
||||
})
|
||||
) {
|
||||
@@ -446,6 +453,7 @@ function AzureProviderModal({
|
||||
apiKey,
|
||||
unknownErrorMessage: t("toasts.unknownError"),
|
||||
apiUrl: values.apiUrl,
|
||||
modelName: values.modelName.trim(),
|
||||
apiVersion: values.apiVersion,
|
||||
deploymentName: values.deploymentName,
|
||||
})
|
||||
|
||||
@@ -17,6 +17,8 @@ export class IndexSettingsPage {
|
||||
readonly viewAllModelsButton: Locator;
|
||||
readonly cloudTab: Locator;
|
||||
readonly selfHostedTab: Locator;
|
||||
/** Toggle of the collapsed "bring your own" section (LiteLLM, Azure, custom). */
|
||||
readonly bringYourOwnToggle: Locator;
|
||||
readonly applyReindexButton: Locator;
|
||||
readonly applyWithoutReindexButton: Locator;
|
||||
readonly revertButton: Locator;
|
||||
@@ -40,6 +42,9 @@ export class IndexSettingsPage {
|
||||
});
|
||||
this.cloudTab = page.getByRole("tab", { name: /cloud.based/i });
|
||||
this.selfHostedTab = page.getByRole("tab", { name: /self.hosted/i });
|
||||
this.bringYourOwnToggle = page.getByRole("button", {
|
||||
name: "Advanced: bring your own model or proxy",
|
||||
});
|
||||
this.applyReindexButton = page.getByRole("button", {
|
||||
name: "Apply & Re-index",
|
||||
});
|
||||
@@ -84,9 +89,25 @@ export class IndexSettingsPage {
|
||||
await this.cloudTab.click();
|
||||
}
|
||||
|
||||
/** Open the collapsed "bring your own" section of the active tab. */
|
||||
async expandBringYourOwnSection(): Promise<void> {
|
||||
await expect(this.bringYourOwnToggle).toBeVisible({ timeout: 10000 });
|
||||
// Control flow only: the section stays open after an earlier expand.
|
||||
if (
|
||||
(await this.bringYourOwnToggle.getAttribute("aria-expanded")) !== "true"
|
||||
) {
|
||||
await this.bringYourOwnToggle.click();
|
||||
}
|
||||
await expect(this.bringYourOwnToggle).toHaveAttribute(
|
||||
"aria-expanded",
|
||||
"true"
|
||||
);
|
||||
}
|
||||
|
||||
// ---------------------------------------------------------------------------
|
||||
// Cloud-provider setup modal (LiteLLM / Azure — providers with no
|
||||
// pre-registered models render an "Add Configuration" card)
|
||||
// pre-registered models render an "Add Configuration" card inside the
|
||||
// collapsed "bring your own" section)
|
||||
// ---------------------------------------------------------------------------
|
||||
|
||||
private setupModalFor(displayName: string): Locator {
|
||||
@@ -105,6 +126,7 @@ export class IndexSettingsPage {
|
||||
}
|
||||
|
||||
async openProviderSetup(displayName: string): Promise<void> {
|
||||
await this.expandBringYourOwnSection();
|
||||
await this.page
|
||||
.getByText(
|
||||
new RegExp(
|
||||
|
||||
@@ -115,6 +115,8 @@ function modelDisplayName(model: TestModelConfiguration): string {
|
||||
// Helpers shared across both describe blocks
|
||||
// ---------------------------------------------------------------------------
|
||||
|
||||
// Legacy self-hosted models are not rendered unless current, so the first
|
||||
// "Select Model" is always one of the selectable models.
|
||||
async function stageNonCurrentSelfHostedModel(page: Page): Promise<void> {
|
||||
await expandModelPicker(page);
|
||||
await page.getByRole("tab", { name: /self.hosted/i }).click();
|
||||
|
||||
Reference in new issue
Block a user