 MyPrototypeWhat
cb0b1ab667
* feat(llm): cross-provider reasoning text fallback with opt-in (#223 Phase 2)

Phase 2 of #223 — wires the shared `<thinking>` text fallback into every
adapter's outbound path behind two new opt-in flags.

User-facing API (`AgentConfig` / `LLMChatOptions`):
- `preserveReasoningAsText?: boolean` — default `false`. When `true`,
  outbound IR-to-native conversion downgrades each `ReasoningBlock` that
  the target adapter cannot natively echo to inline `<thinking>` text and
  prepends it to the next text part (rather than dropping silently).
- `compressReasoningText?: boolean | { minChars?: number }` — defaults
  default-on when `preserveReasoningAsText` is true (per maintainer's #223
  guidance to "tie compress default-on to the preserve flag"). Mirrors the
  shape of `compressToolResults`; head+tail truncation defaults to 1200
  chars per block.

Adapter wiring:
- openai-common.ts: refactored to drop the never-wired (since #234)
  `OpenAIReasoningReplayOptions` type in favour of reading the AgentConfig
  flags. Replaced the private `reasoningBlockToThinkingText` /
  `truncateReasoningForReplay` helpers with the shared
  `reasoningBlockToInlineText` introduced in Phase 1.
- openai.ts / azure-openai.ts / copilot.ts pass the new flags through
  `buildOpenAIMessageList`. Subclasses (deepseek, grok, qiniu, minimax)
  inherit chat() so the wiring propagates automatically.
- anthropic.ts: foreign-provenance reasoning falls back to plain text when
  opt-in is set; own-provenance signed blocks still native-echo (Phase 1
  contract unchanged); own-provenance UNSIGNED blocks now also fall back
  to text rather than dropping silently (was always wasted otherwise).
- gemini.ts: same own/foreign-provenance pattern as anthropic, with the
  same outbound capability gate.
- bedrock.ts: capability is `'never'` (until the deferred signature
  follow-up restores native echo); all reasoning falls back to text when
  opt-in is set. Emits a standalone text block since Bedrock messages
  accept multiple content blocks.
- ai-sdk.ts: capability `'never'` — when opt-in is set, swaps the
  AI SDK structured `{type: 'reasoning'}` part for a text part wrapped
  in `<thinking>`. Default-off preserves pre-Phase-2 pass-through behaviour
  to avoid silently changing what existing users have today.

Tests:
- Refreshed openai-common.test.ts to use the new flag names. Added cases
  for `compressReasoningText: false` (no truncation) and the default-on
  semantics when preserve is true and compress is undefined.
- Added per-adapter `reasoning text fallback (#223 Phase 2)` describe
  blocks to anthropic, gemini, bedrock, and ai-sdk test files. Each
  covers the default-off drop, the opt-in text-fallback, the
  own-provenance native echo path, and (for anthropic) the redacted
  placeholder.
- Updated tests/reasoning-fallback.test.ts so `maxChars: Infinity` now
  asserts pass-through (no truncation) rather than clamp-to-1. The
  positive-Infinity sentinel is how callers signal
  `compressReasoningText: false`.

Docs + example:
- docs/context-management.md gains a "Preserving Reasoning Across
  Providers" section with capability table, default behaviour rules,
  and the loop-detector caveat for local OpenAI-compatible models.
- examples/patterns/cross-provider-reasoning.ts demonstrates the
  Agent.prompt() model-swap scenario and documents the loop-detector
  failure mode.

Refs #223

* test(llm): tighten reasoning-flag propagation test scope (#223 Phase 2 self-review)

Address self-review feedback before opening the Phase 2 PR:

- tests/runner-reasoning-flags.test.ts: rewrite header to honestly describe
  what is covered. `AgentRunner.stream()` internally drives turns via
  `adapter.chat()` (`runner.ts:766`) — `adapter.stream()` is on the
  `LLMAdapter` interface but unused by the runner. The previous "stream path"
  claim was therefore testing a non-existent code path. Drop the dead
  `capturedStream` instrumentation; replace it with a `runner.stream()`
  entrypoint test that exercises the same `adapter.chat()` propagation,
  pinning the contract for the stream-side flag flow.

- tests/reasoning-fallback.test.ts: add a runtime-invariant test for the
  `NO_TRUNCATION` constant. The Phase 2 commit exported the sentinel and
  documented it in JSDoc, but had no test that would CI-fail if a future
  refactor removed the `Number.POSITIVE_INFINITY` special-case branch in
  `resolveMaxChars`. The new assertion ties the constant value, the
  resolver branch, and the documented "no truncation" contract together.

Refs #223

* docs(context-management): acknowledge tool-use-only third capability state

After merging upstream/main (which added 'tool-use-only' for DeepSeek V4
via #251), update the capability table to include the new state and its
two sub-rules:
  - tool-calling conversation → native reasoning_content echo
  - non-tool conversation     → drop (DeepSeek spec)

Also clarify that 'tool-use-only' is the only capability where
same-provider native echo happens WITHOUT preserveReasoningAsText opt-in
(the DeepSeek API forces it for protocol compliance).

Refs #223, #251

* fix(llm): add missing nativeReasoningEchoProvider to ReasoningOutboundOptions

Repair an omission from merge commit 9ca9a91: the field was added to my
working tree alongside the openai-common.ts conflict resolution, but
never staged — so the merge commit landed openai-common.ts referencing
`outboundOptions?.nativeReasoningEchoProvider` while the type declaration
on the receiving end (`ReasoningOutboundOptions` in reasoning-fallback.ts)
did not carry the field.

Locally the bug was masked because vitest runs against the working tree
where the field exists; `npm test` reported 869/874 passing. The pushed
branch would compile-fail at the openai-common.ts access site for any
reviewer pulling the PR.

This commit just adds the field declaration + its JSDoc (already used
correctly throughout openai-common.ts and openai.ts). No behaviour change
relative to what the merge intended.

Refs #223, #251
Open Multi-Agent
From a goal to a task DAG, automatically.
TypeScript-native multi-agent orchestration. Three runtime dependencies.




English · 中文
open-multi-agent is a multi-agent orchestration framework for TypeScript backends. Give it a goal; a coordinator agent decomposes it into a task DAG, parallelizes independents, and synthesizes the result. Three runtime dependencies, drops into any Node.js backend.
Your engineers describe the goal, not the graph.
Quick Start
Requires Node.js >= 18.
Use it in your project
npm install @open-multi-agent/core
Migrating from @jackchen_me/open-multi-agent? That package is deprecated; install @open-multi-agent/core instead.
import { OpenMultiAgent, type AgentConfig } from '@open-multi-agent/core'

const agents: AgentConfig[] = [
  { name: 'architect', model: 'claude-sonnet-4-6', systemPrompt: 'Design clean API contracts.', tools: ['file_write'] },
  { name: 'developer', model: 'claude-sonnet-4-6', systemPrompt: 'Implement runnable TypeScript.', tools: ['bash', 'file_read', 'file_write', 'file_edit'] },
  { name: 'reviewer', model: 'claude-sonnet-4-6', systemPrompt: 'Review correctness and security.', tools: ['file_read', 'grep'] },
]

const orchestrator = new OpenMultiAgent({
  defaultModel: 'claude-sonnet-4-6',
  onProgress: (event) => console.log(event.type, event.task ?? event.agent ?? ''),
})

const team = orchestrator.createTeam('api-team', { name: 'api-team', agents, sharedMemory: true })
const result = await orchestrator.runTeam(team, 'Create a REST API for a todo list in /tmp/todo-api/')

console.log(result.success, result.totalTokenUsage.output_tokens)
Run an example locally
git clone https://github.com/open-multi-agent/open-multi-agent && cd open-multi-agent
npm install
export ANTHROPIC_API_KEY=sk-...
npx tsx examples/basics/team-collaboration.ts
Three agents collaborate on a REST API while onProgress streams the coordinator's task DAG:
agent_start coordinator
task_start design-api
task_complete design-api
task_start implement-handlers
task_start scaffold-tests         // independent tasks run in parallel
task_complete scaffold-tests
task_complete implement-handlers
task_start review-code            // unblocked after implementation
task_complete review-code
agent_complete coordinator        // synthesizes final result
Success: true
Tokens: 12847 output tokens
Local models via Ollama need no API key, see providers/ollama. For hosted providers (OPENAI_API_KEY, GEMINI_API_KEY, etc.), see Supported Providers.
Three Ways to Run
| Mode | Method | When to use | Example |
|---|---|---|---|
| Single agent | runAgent() |
One agent, one prompt | basics/single-agent |
| Auto-orchestrated team | runTeam() |
Give a goal, let the coordinator plan and execute | basics/team-collaboration |
| Explicit pipeline | runTasks() |
You define the task graph and assignments | basics/task-pipeline |
Preview the coordinator's task DAG without executing agents:
const plan = await orchestrator.runTeam(team, goal, { planOnly: true })
Inject team context (goal, roster, this worker's role) into every worker prompt. Helps workers stay aligned with the overall goal and makes multi-step runs easier to debug. Off by default; worker prompts stay byte-identical when omitted.
const result = await orchestrator.runTeam(team, goal, { revealCoordinator: true })
For MapReduce-style fan-out without task dependencies, use AgentPool.runParallel() directly. See patterns/fan-out-aggregate.
For shell and CI, use the JSON-first oma binary. See docs/cli.md.
Features
| Capability | What you get |
|---|---|
| Goal-driven coordinator | One runTeam(team, goal) call. The coordinator decomposes the goal into a task DAG, parallelizes independents, and synthesizes the result. |
| Mix providers in one team | 11 built-in: Anthropic, OpenAI, Azure, Bedrock, Gemini, Grok, DeepSeek, Doubao, MiniMax, Qiniu, Copilot. Ollama / vLLM / LM Studio / OpenRouter / Groq via OpenAI-compatible. (full setup) |
| Tools + MCP | 6 built-in (bash, file_*, grep, glob), opt-in delegate_to_agent, custom tools via defineTool() + Zod, stdio MCP servers via connectMCPTools(). (tool config) |
| Streaming + structured output | Token-by-token streaming on every adapter; Zod-validated final answer with auto-retry on parse failure. (structured-output) |
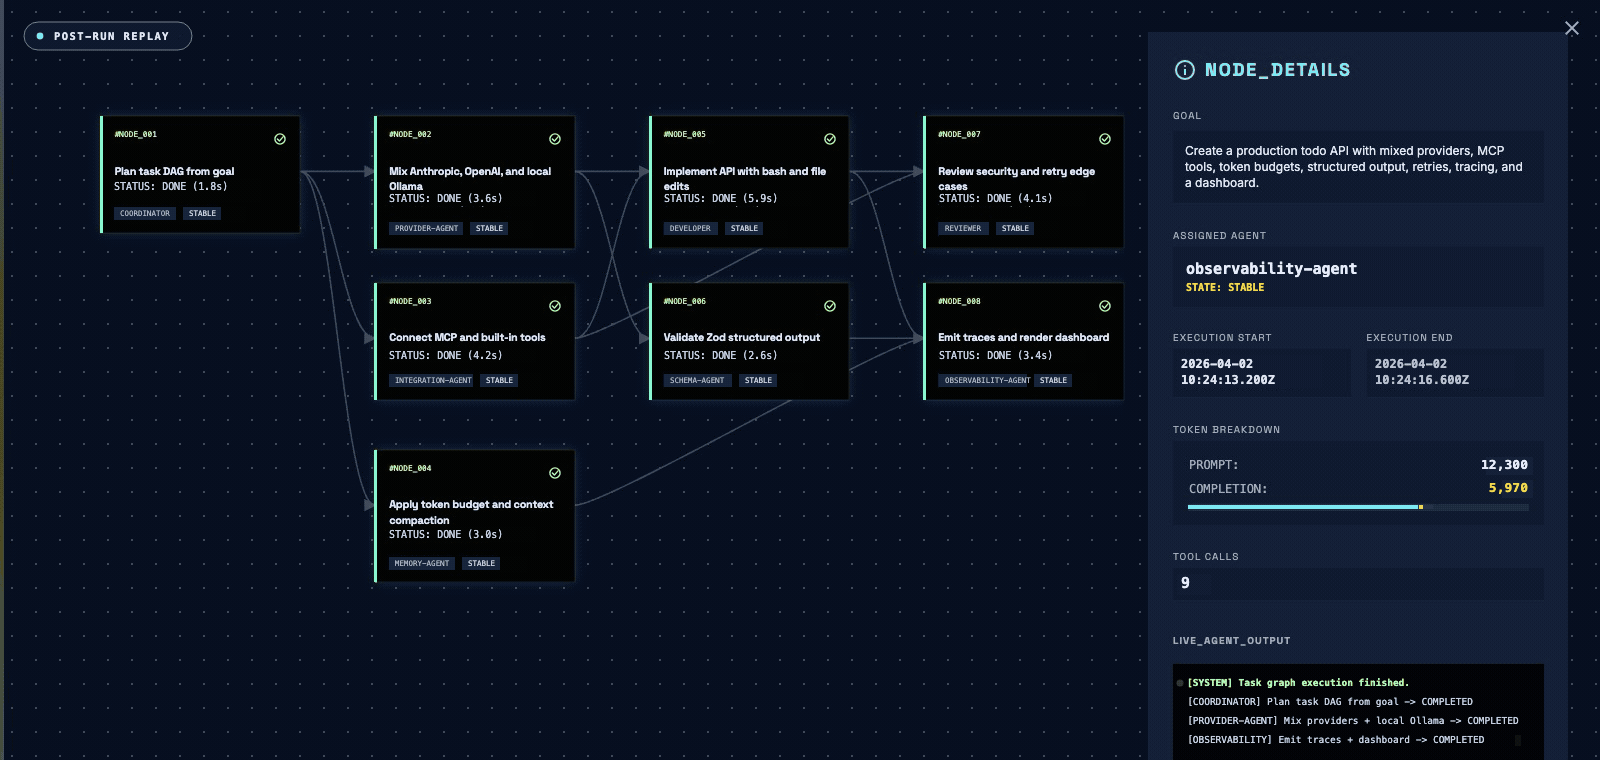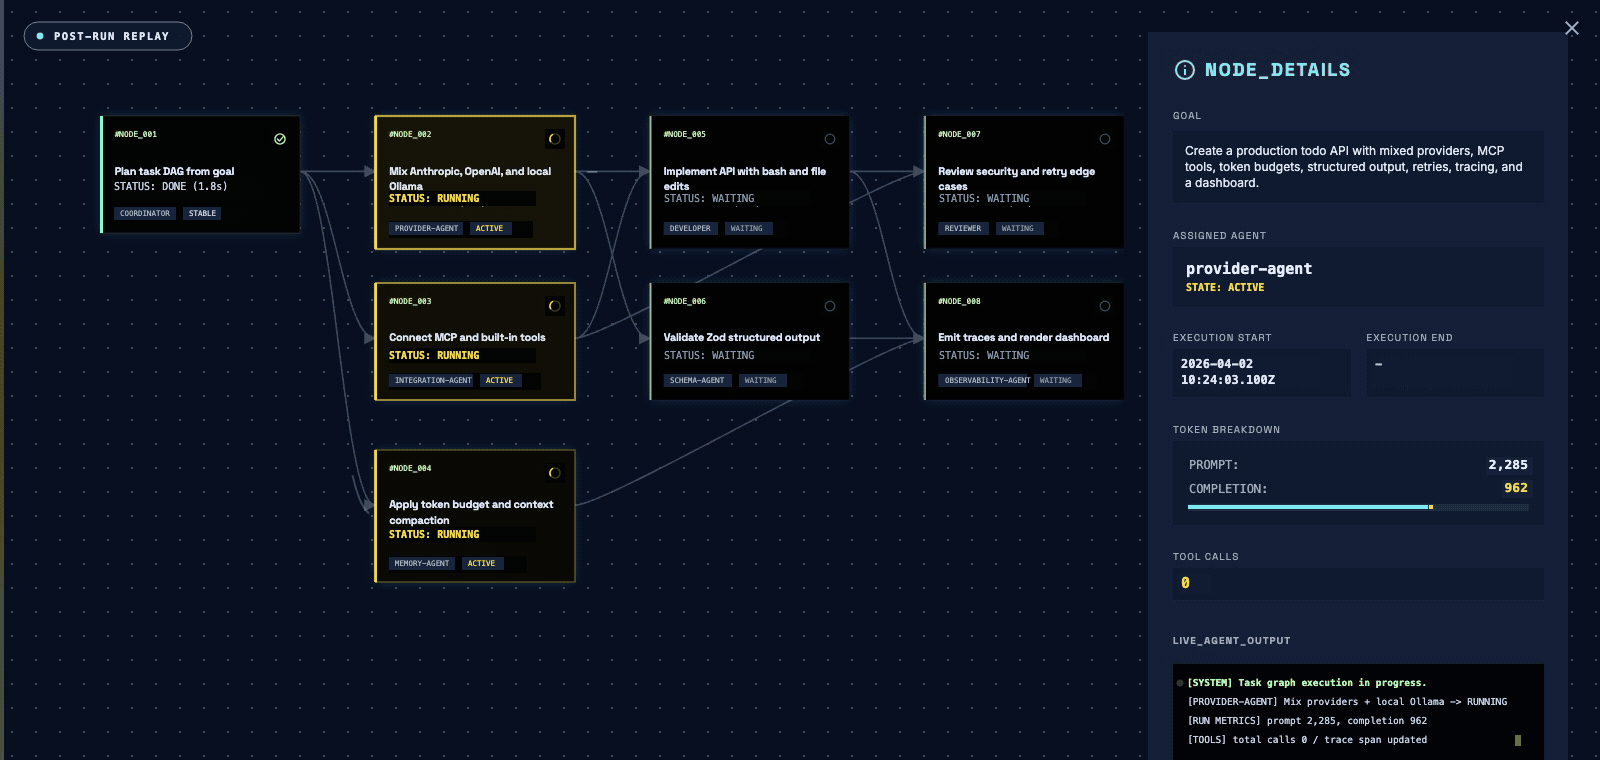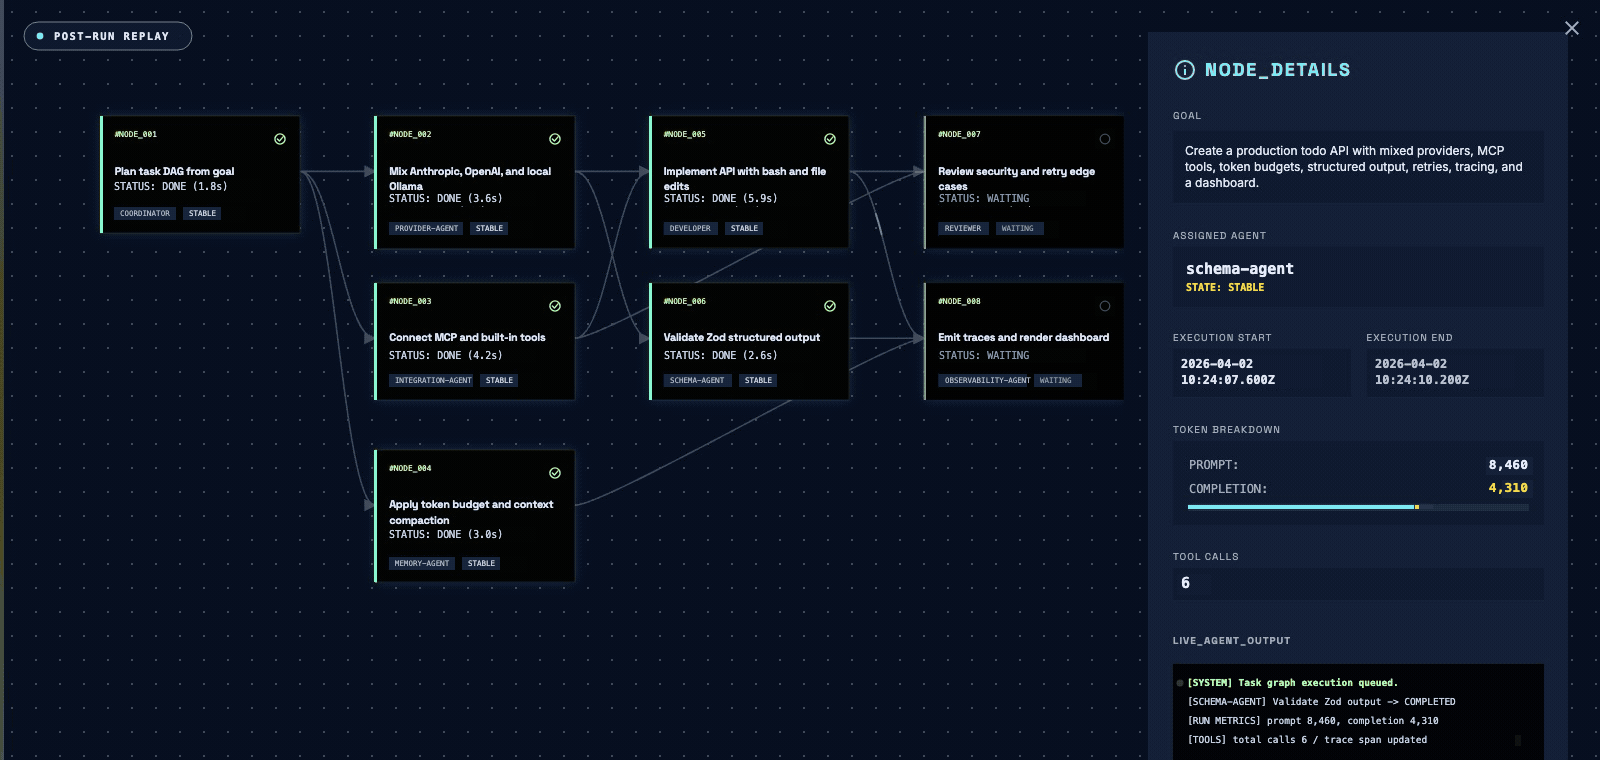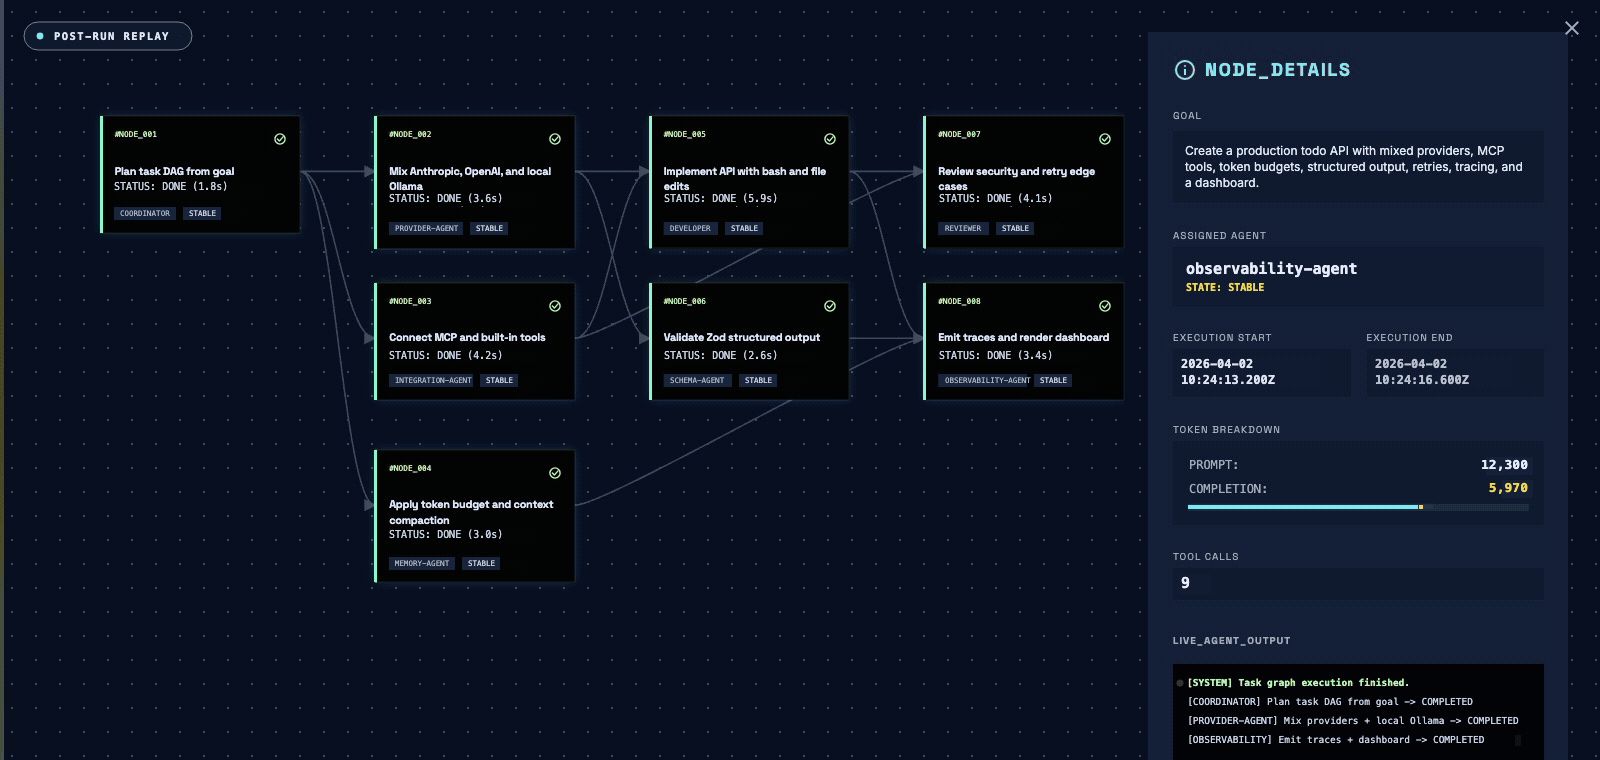
| Observability | onProgress events, onTrace spans, post-run HTML dashboard rendering the executed task DAG. (observability guide) |
| Pluggable shared memory | Default in-process KV; swap in Redis / Postgres / your own backend by implementing MemoryStore. (shared memory) |
Production controls (context strategies, task retry with backoff, loop detection, tool output truncation/compression) are covered in the Production Checklist.
Examples
examples/ is organized by category: basics, cookbook, patterns, providers, integrations, and production. See examples/README.md for the full index.
Real-world workflows (cookbook/)
End-to-end scenarios you can run today. Each one is a complete, opinionated workflow.
contract-review-dag: four-task DAG for contract review with parallel branches and step-level retry on failure.meeting-summarizer: three specialised agents fan out on a transcript, an aggregator merges them into one Markdown report with action items and sentiment.competitive-monitoring: three parallel source agents extract claims from feeds; an aggregator cross-checks them and flags contradictions.translation-backtranslation: translate EN to target with one provider, back-translate with another, flag semantic drift.
Patterns and integrations
basics/team-collaboration:runTeam()coordinator pattern.patterns/structured-output: any agent returns Zod-validated JSON.patterns/fan-out-aggregate: MapReduce-style fan-out viaAgentPool.runParallel().patterns/agent-handoff: synchronous sub-agent delegation viadelegate_to_agent.integrations/trace-observability:onTracespans for LLM calls, tools, and tasks.integrations/mcp-github: expose an MCP server's tools to an agent viaconnectMCPTools().integrations/with-vercel-ai-sdk: Next.js app combining OMArunTeam()with AI SDKuseChatstreaming.- Provider examples: scripts under
examples/providers/covering hosted providers, OpenAI-compatible endpoints, and local models.
Run any script with npx tsx examples/<path>.ts.
How is this different from X?
A quick router. Mechanism breakdown follows.
| If you need | Pick |
|---|---|
| Fixed production topology with mature checkpointing | LangGraph JS |
| Explicit Supervisor + hand-wired workflows | Mastra |
| Python stack with mature multi-agent ecosystem | CrewAI |
| AI app toolkit with broad model-provider support | Vercel AI SDK |
| TypeScript, goal to result with auto task decomposition | open-multi-agent |
vs. LangGraph JS. LangGraph compiles a declarative graph (nodes, edges, conditional routing) into an invokable. open-multi-agent runs a Coordinator that decomposes the goal into a task DAG at runtime, then auto-parallelizes independents. Same end (orchestrated execution), opposite directions: LangGraph is graph-first, OMA is goal-first.
vs. Mastra. Both are TypeScript-native. Mastra's Supervisor pattern requires you to wire agents and workflows by hand; OMA's Coordinator does the wiring at runtime from the goal string. If the workflow is known up front, Mastra's explicitness pays off. If you'd rather not enumerate every step, OMA's runTeam(team, goal) is one call.
vs. CrewAI. CrewAI is the mature multi-agent option in Python. OMA targets TypeScript backends with three runtime dependencies and direct Node.js embedding. Roughly comparable orchestration surface; the choice is the language stack.
vs. Vercel AI SDK. AI SDK provides the LLM-call layer — provider abstraction, streaming, tool calls, and structured outputs. It does not orchestrate goal-driven multi-agent teams. The two are complementary: AI SDK for app surfaces and single-agent calls, OMA when you need a team.
Ecosystem
open-multi-agent launched 2026-04-01 under MIT. Known users and integrations to date:
In production
- temodar-agent (~60 stars). WordPress security analysis platform by Ali Sünbül. Uses our built-in tools (
bash,file_*,grep) directly inside a Docker runtime. Confirmed production use.
Using open-multi-agent in production or a side project? Open a discussion and we will list it here.
Integrations
- Engram — "Git for AI memory." Syncs knowledge across agents instantly and flags conflicts. (repo)
- @agentsonar/oma — Sidecar detecting cross-run delegation cycles, repetition, and rate bursts.
Built an integration? Open a discussion to get listed.
Provider community offers
Limited-time provider offers for open-multi-agent users. Listings are not paid endorsements.
- MiniMax — Use MiniMax M2.7 in OMA's TypeScript multi-agent workflows. OMA users get 12% off the MiniMax Token Plan until 2026-06-30. See the MiniMax setup guide.
Featured partner
For products and platforms with a deep open-multi-agent integration. See the Featured partner program for terms and how to apply.
Architecture
┌─────────────────────────────────────────────────────────────────┐
│  OpenMultiAgent (Orchestrator)                                  │
│                                                                 │
│  createTeam()  runTeam()  runTasks()  runAgent()  getStatus()   │
└──────────────────────┬──────────────────────────────────────────┘
                       │
            ┌──────────▼──────────┐
            │  Team               │
            │  - AgentConfig[]    │
            │  - MessageBus       │
            │  - TaskQueue        │
            │  - SharedMemory     │
            └──────────┬──────────┘
                       │
         ┌─────────────┴─────────────┐
         │                           │
┌────────▼──────────┐    ┌───────────▼───────────┐
│  AgentPool        │    │  TaskQueue             │
│  - Semaphore      │    │  - dependency graph    │
│  - runParallel()  │    │  - auto unblock        │
└────────┬──────────┘    │  - cascade failure     │
         │               └───────────────────────┘
┌────────▼──────────┐
│  Agent            │
│  - run()          │    ┌────────────────────────┐
│  - prompt()       │───►│  LLMAdapter            │
│  - stream()       │    │  - AnthropicAdapter    │
└────────┬──────────┘    │  - OpenAIAdapter       │
         │               │  - AzureOpenAIAdapter  │
         │               │  - BedrockAdapter      │
         │               │  - CopilotAdapter      │
         │               │  - GeminiAdapter       │
         │               │  - GrokAdapter         │
         │               │  - MiniMaxAdapter      │
         │               │  - DeepSeekAdapter     │
         │               │  - DoubaoAdapter       │
         │               │  - QiniuAdapter        │
         │               └────────────────────────┘
┌────────▼──────────┐
│  AgentRunner      │    ┌──────────────────────┐
│  - conversation   │───►│  ToolRegistry        │
│    loop           │    │  - defineTool()      │
│  - tool dispatch  │    │  - 6 built-in tools  │
└───────────────────┘    │  + delegate (opt-in) │
                         └──────────────────────┘
Core Concepts
- Tools + MCP. Built-ins cover
bash,file_read,file_write,file_edit,grep, andglob; custom tools usedefineTool()+ Zod; stdio MCP servers connect throughconnectMCPTools(). See tool configuration. - Observability. Wire
onProgressfor live lifecycle events,onTracefor structured spans, andrenderTeamRunDashboard(result)for a static DAG dashboard. See observability. - Shared memory. Use the default in-process KV or bring Redis, Postgres, Engram, or any
MemoryStore. See shared memory. - Context management. Use sliding windows, summarization, rule-based compaction, or a custom compressor for long-running agents. See context management.
Supported Providers
Change provider, model, and set the env var. The agent config shape stays the same.
const agent: AgentConfig = {
  name: 'my-agent',
  provider: 'anthropic',
  model: 'claude-sonnet-4-6',
  systemPrompt: 'You are a helpful assistant.',
}
| Kind | How to configure | Services |
|---|---|---|
| Built-in shortcuts | Set provider to anthropic, gemini, openai, azure-openai, copilot, grok, deepseek, doubao, minimax, qiniu, or bedrock; the framework supplies the endpoint. |
Anthropic, Gemini, OpenAI, Azure OpenAI, GitHub Copilot, xAI Grok, DeepSeek, Doubao (Volcengine), MiniMax, Qiniu, AWS Bedrock |
| OpenAI-compatible endpoints | Set provider: 'openai' plus baseURL and, when needed, apiKey. |
Ollama, vLLM, LM Studio, llama.cpp server, OpenRouter, Groq, Mistral |
| Vercel AI SDK | Import AISdkAdapter from @open-multi-agent/core/ai-sdk; install optional peer ai plus an @ai-sdk/* provider. |
Any AI SDK provider (60+ models and hosts) |
See docs/providers.md for env vars, model examples, local tool-calling, timeouts, and troubleshooting.
Vercel AI SDK (optional)
Install the optional peer ai plus any @ai-sdk provider you need (for example @ai-sdk/openai). Pass adapter: new AISdkAdapter(model) on AgentConfig to route that agent through the AI SDK instead of the built-in provider factory. provider, apiKey, baseURL, and region are ignored when adapter is set. Mixed teams work as usual: only agents with adapter use the AI SDK.
import { openai } from '@ai-sdk/openai'
import { AISdkAdapter } from '@open-multi-agent/core/ai-sdk'
import { OpenMultiAgent } from '@open-multi-agent/core'

const oma = new OpenMultiAgent()
await oma.runAgent(
  {
    name: 'researcher',
    model: 'gpt-4o',
    adapter: new AISdkAdapter(openai('gpt-4o')),
    systemPrompt: 'You are a researcher.',
  },
  'What are the latest AI trends?',
)
The coordinator accepts the same hook via runTeam(team, goal, { coordinator: { adapter: new AISdkAdapter(...) } }).
Production Checklist
Before going live, wire up the controls that protect token spend, recover from failure, and let you debug.
| Concern | Knob | Where it lives |
|---|---|---|
| Bound the conversation | maxTurns per agent + contextStrategy (sliding-window / summarize / compact / custom) |
AgentConfig |
| Cap tool output | maxToolOutputChars (or per-tool maxOutputChars) + compressToolResults: true |
AgentConfig and defineTool() |
| Recover from failure | Per-task maxRetries, retryDelayMs, retryBackoff (exponential multiplier) |
Task config used via runTasks() |
| Hard-cap spend | maxTokenBudget on the orchestrator |
OrchestratorConfig |
| Catch stuck agents | loopDetection with onLoopDetected: 'terminate' (or a custom handler) |
AgentConfig |
| Trace and audit | onTrace to your tracing backend; persist renderTeamRunDashboard(result) |
OrchestratorConfig |
Contributing
Issues, feature requests, and PRs are welcome. Some areas where contributions would be especially valuable:
- Production examples. Real-world end-to-end workflows. See
examples/production/README.mdfor the acceptance criteria and submission format. - Documentation. Guides, tutorials, and API docs.
- Translations. Help translate this README into other languages. Open a PR.
Contributors
Contributor credits by area
Framework features
- @ibrahimkzmv (token budget, context strategy, dependency-scoped context, tool presets, glob, MCP integration, configurable coordinator, CLI, dashboard rendering, trace event types)
- @apollo-mg (context compaction fix, sampling parameters)
- @tizerluo (onPlanReady, onAgentStream)
- @CodingBangboo (planOnly mode)
- @Xin-Mai (output schema validation)
- @JasonOA888 (AbortSignal support)
- @EchoOfZion (coordinator skip for simple goals)
- @voidborne-d (OpenAI mixed content fix)
- @NamelessNATM (agent delegation base implementation)
- @MyPrototypeWhat (reasoning blocks, reasoning_effort, sampling parity, trace input/output)
- @SiMinus (streaming reasoning events)
Provider integrations
- @ibrahimkzmv (Gemini)
- @hkalex (DeepSeek, MiniMax)
- @marceloceccon (Grok)
- @Klarline (Azure OpenAI)
- @Deathwing (GitHub Copilot)
- @JackChiang233 (Qiniu)
- @CodingBangboo (AWS Bedrock)
Examples & cookbook
- @mvanhorn (research aggregation, code review, meeting summarizer, Groq example, Mistral example)
- @Kinoo0 (code review upgrade)
- @Optimisttt (research aggregation upgrade)
- @Agentscreator (Engram memory integration)
- @fault-segment (contract-review DAG)
- @HuXiangyu123 (cost-tiered example)
- @zouhh22333-beep (translation/backtranslation)
- @pei-pei45 (competitive monitoring)
- @mmjwxbc (interview simulator)
- @binghuaren96 (incident postmortem DAG)
- @DaiMao-UT (paper replication triage)
- @oooooowoooooo (rare disease information triage)
- @CodingBangboo (Express customer support pipeline)
Docs & tests
- @tmchow (llama.cpp docs)
- @kenrogers (OpenRouter docs)
- @jadegold55 (LLM adapter test coverage)
Star History
License
MIT